首页 文章 精选 留言 我的

精选列表

搜索[全基因组选择],共10000篇文章
优秀的个人博客,低调大师

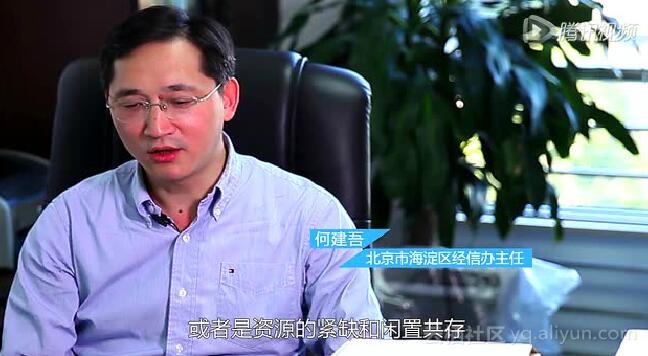
智慧海淀为什么选择与阿里云合作?

智慧海淀与阿里云的合作 2014年底,北京市海淀区建成中国首个统一的综合性政务云平台。 政务云平台上线后,海淀区逐步把所有面向企业的审批审核事项以及面向市民的服务事项的智慧政务综合服务平台迁移到云平台上,实现网上统一办理,为老百姓提供智能、高效、便捷的服务。该平台由阿里云计算提供云计算和大数据处理。 今天,特别邀请到北京市海淀区经信办主任何建吾与大家分享,智慧海淀与阿里云这段合作背后的故事。 (点击观看视频) 原文链接

优秀的个人博客,低调大师

Android项目框架之图片加载框架的选择

本文来自http://blog.csdn.net/liuxian13183/,引用必须注明出处! 从Android爆发以后,自定义的控件如EditTextWithDelete、ActionBar、PullToRresh逐步进入开发者的视野,想起11年的时候,基本项目中使用的UI还全都是Android提供的基础控件,一点的动画+布局,下载和网络请求都是用HttpClient,图片加载当然也是下载后再使用,当时的程序资源可没有现在这么丰富,看看Github上开源的项目,现在的程序员应该感到幸福。 项目开发从程序上来讲,万古不变两大事情,一是网络通信框架,二是图片加载框架,有关网络框架上一篇已经介绍了async-http和okhttp,而其他如volly同时拥有网络请求和图片加载两个框架,很多人图省事就一次性使用了,当然facebook自己的开源框架也是写的非常不错,接下来再一一介绍;先贴一张11年我们自己写的imageloader 补充一下,上面框架还支持给图片设置像素点占位大小;看到这么多功能,对于现在的项目基本满足要求,缺点是:网络请求直接使用未封装的HttpUrlConnection,以及图片选项设置麻烦一些(如可以设置磁盘和内存最大宽高),不支持webp和gif。再看看其他几种图片加载框架的异同 Fresco,facebook出品,最大的优势在于可展示加载过程,即加载进度、加载前图片、加载中图片、加载后图片、加载失败图片等,还可以设置图片的形状;并且提供加载Gif、Webp图片的方法。 Picasso,默认Config为8888,如果加载图片不成功,需要改565,原因内存不足。 Glide是升级版本的piccaso:1、支持跟fragment和activity生命周期绑定;2、同时可以直接剪切图片;3、网络请求直接使用okhttp;4、相对imageloader,API相对简单。默认加载RGB565格式图片,缺点是没有直接从fileCaceh取文件的接口、不支持webp、防止图片错乱只能设置setTag(int,String)。 volly,基于老的imageloader又做了次封装,差别不是太大,功能弱化一些,同glide支持图片动画,但它同时支持gif和webp。不适用于直播和较大图片下载,因为它解析后的缓存一般直接放在内存中。 https://developer.android.com/training/volley/index.html 而后面这几种框架,都是在imageloader兴起之后出现的,都有加载过程,在我看来也仅有fresco和glide是真正写出了跟原框架不同的东西。 public class ImageDownloader { private static ImageDownloader instance = null; private static File cacheDir; public static Map<String, SoftReference<Bitmap>> bitMapCache = new HashMap<String, SoftReference<Bitmap>>(); public static ImageDownloader getInstance() { if (instance == null) { instance = new ImageDownloader(); } return instance; } private ImageDownloader() { // Find the dir to save cached images if (android.os.Environment.getExternalStorageState().equals( android.os.Environment.MEDIA_MOUNTED)) cacheDir = new File( android.os.Environment.getExternalStorageDirectory(), "WholeMag"); else cacheDir = WholeMagApplication.getInstance().getCacheDir(); if (!cacheDir.exists()) cacheDir.mkdirs(); } public void download(String actName, String url, ImageView imageView) { BitmapDownloaderTask task = new BitmapDownloaderTask(imageView, actName); task.execute(url); // return task.doInBackground(url); } class BitmapDownloaderTask extends AsyncTask<String, Void, Bitmap> { // private String url; // private boolean flag; private final WeakReference<ImageView> imageViewReference; // 使用WeakReference解决内存问题 private String actName; public BitmapDownloaderTask(ImageView imageView, String actName) { imageViewReference = new WeakReference<ImageView>(imageView); this.actName = actName; } @Override protected Bitmap doInBackground(String... params) { // 实际的下载线程,内部其实是concurrent线程,所以不会阻塞 Bitmap rebmp = getLocalBitmap(params[0], actName); if (rebmp == null) rebmp = downloadBitmap(params[0], actName); if (rebmp == null) { doInBackground(params[0]); } return rebmp; } @Override protected void onPostExecute(Bitmap bitmap) { // 下载完后执行的 if (isCancelled()) { bitmap = null; } if (imageViewReference != null) { ImageView imageView = imageViewReference.get(); if (imageView != null) { imageView.setDrawingCacheEnabled(true); Bitmap temp = imageView.getDrawingCache(); imageView.setDrawingCacheEnabled(false); if (temp != null) { temp.recycle(); } double widthX = (float) WholeMagDatas.getDeviceWidth() / bitmap.getWidth(); // 图片宽度拉伸比例 int bitmapHight = bitmap.getHeight();// 图片高度 imageView.setImageBitmap(bitmap); // 下载完设置imageview为刚才下载的bitmap对象 if(actName.equals(AppData.NEWS_DETAIL_ACT)){ FrameLayout.LayoutParams ll = new FrameLayout.LayoutParams( android.view.ViewGroup.LayoutParams.FILL_PARENT, (int) (bitmapHight * widthX), Gravity.CENTER); imageView.setLayoutParams(ll); } AlphaAnimation alphaAnimation = new AlphaAnimation(0, 1);// 创建一个AlphaAnimation对象 alphaAnimation.setDuration(500);// 设置动画执行的时间(单位:毫秒) imageView.startAnimation(alphaAnimation); } } } } static Bitmap getLocalBitmap(String url, String actName) { if (bitMapCache.containsKey(url)) { return bitMapCache.get(url).get(); } // String tmp = url; // String first = url.substring(url.lastIndexOf("/") + 1); // tmp = tmp.substring(0, tmp.lastIndexOf("/")); // String second = tmp.substring(tmp.lastIndexOf("/") + 1); // tmp = tmp.substring(0, tmp.lastIndexOf("/")); // String third = tmp.substring(tmp.lastIndexOf("/") + 1); // String filename = third + second + first; // File f = new File(cacheDir, filename); File f = Tools.getFile(actName, url); InputStream inputStream = null; try { // decode image size BitmapFactory.Options o = new BitmapFactory.Options(); o.inPreferredConfig = Bitmap.Config.RGB_565; o.inDither = false; o.inPurgeable = true; // o.inTempStorage = new byte[12 * 1024]; inputStream = new FileInputStream(f); // Bitmap bitmap = BitmapFactory.decodeFile(f.getAbsolutePath()); Bitmap bitmap = BitmapFactory.decodeStream(inputStream, null, o); bitMapCache.put(url, new SoftReference<Bitmap>(bitmap)); return bitmap; } catch (Exception e) { } finally { if (null != inputStream) { try { inputStream.close(); } catch (Exception ex) { } } } return null; } static Bitmap downloadBitmap(String url, String actName) { final AndroidHttpClient client = AndroidHttpClient.newInstance("linux"); final HttpGet getRequest = new HttpGet(url); try { HttpResponse response = client.execute(getRequest); final int statusCode = response.getStatusLine().getStatusCode(); if (statusCode != HttpStatus.SC_OK) { // Log.e("cwjDebug", "Error " + statusCode // + " while retrieving bitmap from " + url); return null; } final HttpEntity entity = response.getEntity(); if (entity != null) { // String tmp = url; // String first = url.substring(url.lastIndexOf("/") + 1); // tmp = tmp.substring(0, tmp.lastIndexOf("/")); // String second = tmp.substring(tmp.lastIndexOf("/") + 1); // tmp = tmp.substring(0, tmp.lastIndexOf("/")); // String third = tmp.substring(tmp.lastIndexOf("/") + 1); // String filename = third + second + first; // File f = new File(cacheDir, filename); File f = Tools.getFile(actName, url); OutputStream os = new FileOutputStream(f); InputStream inputStream = null; try { inputStream = entity.getContent(); BitmapFactory.Options o = new BitmapFactory.Options(); o.inPreferredConfig = Bitmap.Config.RGB_565; o.inDither = false; o.inPurgeable = true; final Bitmap bitmap = BitmapFactory.decodeStream( inputStream, null, o); bitmap.compress(Bitmap.CompressFormat.JPEG, 100, os); bitMapCache.put(url, new SoftReference<Bitmap>(bitmap)); return bitmap; } finally { if (inputStream != null) { inputStream.close(); } if (null != os) { os.close(); } entity.consumeContent(); } } } catch (Exception e) { getRequest.abort(); } finally { if (client != null) { client.close(); } } return null; }} 当年为了防止图片爆掉出现OOM,使用了软引用,觉得还不错;图片加载的基本原理就是,把url+imageview抛过来,然后开启异步线程加载,根据获取的byte流decode成bitmap,最后在UI线程将图片加载到imageview上;也没有说做本地缓存,仅做了应用缓存;没有对图片进行压缩或者设置格式,使占用内存更小,展示也更合理;LruCache基本原理跟上面使用软引用的过程差不多,只不过多限制了图片占用内存的大小,计算图片使用的频率,对应用层、SD卡层均做了封装。上面介绍完,相信你也对图片加载有个大概的轮廓,我们拿开源的imageloader为例,来讲讲图片加载框架的一些细节 public final class ImageLoaderConfiguration { final Resources resources;//主要给图片设计宽高时,获得屏幕宽高使用 final int maxImageWidthForMemoryCache;//内存中最大的图片宽度 final int maxImageHeightForMemoryCache;//内存中最大的图片高度 final int maxImageWidthForDiskCache;//SD卡中最大的图片宽度 final int maxImageHeightForDiskCache;//SD卡中最大的图片高度 final BitmapProcessor processorForDiskCache;//从SD卡获得Bitmap的加载器 final Executor taskExecutor;//加载图片时的执行器 final Executor taskExecutorForCachedImages;//加载缓存时的执行器 final boolean customExecutor;//是否使用默认执行器 final boolean customExecutorForCachedImages;//是否使用默认缓存执行器 final int threadPoolSize;//线程数,可以用来控制展示当前界面的item图片 final int threadPriority;//线程的执行优先级 final QueueProcessingType tasksProcessingType;//是LILO还是LIFO,默认是前者,但一般喜欢后者 final MemoryCache memoryCache;//内存缓存对象,如不写可用默认 final DiskCache diskCache;//SD卡缓存对象,如不写可用默认 final ImageDownloader downloader;//图片加载器,根据网络(http/s)、file、content、drawable、asset来加载 final ImageDecoder decoder;//图片解析器,根据获取的图片参数拿到Bitmap final DisplayImageOptions defaultDisplayImageOptions;//设置图片加载状态和结果,见下面源码 //不用网络下载图片的下载器,可理解为加载SD卡图片的加载器 final ImageDownloader networkDeniedDownloader; final ImageDownloader slowNetworkDownloader;//仅网络下载图片的下载器,支持断点续传拿这些变量来讲,基本就可以说明事情 public final class DisplayImageOptions { private final int imageResOnLoading;//图片是否加载中 private final int imageResForEmptyUri;//图片是否来自于空url private final int imageResOnFail;//图片是否加载失败 private final Drawable imageOnLoading;//加载中的图片 private final Drawable imageForEmptyUri;//空数据的图片 private final Drawable imageOnFail;//加载失败的图片 private final boolean resetViewBeforeLoading;//加载完是否重置(意味着放弃之前的加载) private final boolean cacheInMemory;//是否缓存在内存中 private final boolean cacheOnDisk;//是否缓存在SD卡中 private final ImageScaleType imageScaleType;//要多大的图片,统一设置 private final Options decodingOptions;//Bitmap的options对象 private final int delayBeforeLoading;//是否延迟加载,可用于非当前页面图片 private final boolean considerExifParams;//是否支持jpeg图片的rotate和flip等方法 private final Object extraForDownloader;//额外数据 private final BitmapProcessor preProcessor;//加载不在内存中的图片 private final BitmapProcessor postProcessor;//加载在图片中的图片 private final BitmapDisplayer displayer;//展示图片 private final Handler handler;//这个就不用讲了吧,跟主线程交互必不可少的工具 private final boolean isSyncLoading;//是否同步加载 判断是否是主线程: public static boolean isOnMainThread() { return Looper.myLooper() == Looper.getMainLooper(); }

优秀的个人博客,低调大师

全栈角度看分页处理

作者:京东物流 杨攀 分页是 web application 开发最常见的功能。在使用不同的框架和工具过程中,发现初始行/页的定义不同,特意整理记录。从这个技术点去看不同层的实现。以及不同语言实现的对比。 文章会从正常的web 结构分层的角度去梳理不同层的处理。 分为数据库分页、服务端分页、前端分页 数据库分页 这里用mysql 举例整理。我们常用的数据库例如 Oracle/ SQL Server 等,对于分页语法的支持大同小异。不做具体一一举例。 先从数据库层梳理,也是从最根源去分析分页的最终目的,前端和后端的一起逻辑和适配,都是为了拼接合适的 SQL 语句。 ①MySQL LIMIT 语法:[LIMIT {[offset,]row_count}] LIMIT row_countis equivalent toLIMIT 0, row_count. The offset of the initial row is 0 (not 1) 参考:MySQL :: MySQL 5.7 Reference Manual :: 13.2.9 SELECT Statement 服务端/后端分页 后端分页,简单讲,就是数据库的分页。 对于mysql 来讲,就是上述 offset row_count 的计算过程。 这里选用了常用的框架组件来对比各自实现的细节。 pagehelper 是Java Orm 框架mybatis 常用的开源分页插件 spring-data-jdbc 是Java 框架常用的数据层组件 ①pagehelper /** * 计算起止行号 offset * @see com.github.pagehelper.Page#calculateStartAndEndRow */ private void calculateStartAndEndRow() { // pageNum 页码,从1开始。 pageNum < 1 , 忽略计算。 this.startRow = this.pageNum > 0 ? (this.pageNum - 1) * this.pageSize : 0; this.endRow = this.startRow + this.pageSize * (this.pageNum > 0 ? 1 : 0); } /** * 计算总页数 pages/ pageCount。 * 在赋值数据总条数的同时,也计算了总页数。 * 可以与 Math.ceil 实现对比看。 */ public void setTotal(long total) { if (pageSize > 0) { pages = (int) (total / pageSize + ((total % pageSize == 0) ? 0 : 1)); } else { pages = 0; } } SQL 拼接实现: com.github.pagehelper.dialect.helper.MySqlDialect ②spring-data-jdbc 关键类: org.springframework.data.domain.Pageable org.springframework.data.web.PageableDefault /** * offset 计算,不同于pagehelper, page 页码从0 开始。 default is 0 * @see org.springframework.data.domain.AbstractPageRequest#getOffset */ public long getOffset() { return (long)this.page * (long)this.size; } /* * 总页数的计算使用 Math.ceil 实现。 * @see org.springframework.data.domain.Page#getTotalPages() */ @Override public int getTotalPages() { return getSize() == 0 ? 1 : (int) Math.ceil((double) total / (double) getSize()); } /** * offset 计算,不同于pagehelper, page 页码从0 开始。 * @see org.springframework.data.jdbc.core.convert.SqlGenerator#applyPagination */ private SelectBuilder.SelectOrdered applyPagination(Pageable pageable, SelectBuilder.SelectOrdered select) { // 在spring-data-relation, Limit 抽象为 SelectLimitOffset SelectBuilder.SelectLimitOffset limitable = (SelectBuilder.SelectLimitOffset) select; // To read the first 20 rows from start use limitOffset(20, 0). to read the next 20 use limitOffset(20, 20). SelectBuilder.SelectLimitOffset limitResult = limitable.limitOffset(pageable.getPageSize(), pageable.getOffset()); return (SelectBuilder.SelectOrdered) limitResult; } spring-data-commons 提供 mvc 层的分页参数处理器 /** * Annotation to set defaults when injecting a {@link org.springframework.data.domain.Pageable} into a controller method. * * @see org.springframework.data.web.PageableDefault */ @Documented @Retention(RetentionPolicy.RUNTIME) @Target(ElementType.PARAMETER) public @interface PageableDefault { /** * The default-size the injected {@link org.springframework.data.domain.Pageable} should get if no corresponding * parameter defined in request (default is 10). */ int size() default 10; /** * The default-pagenumber the injected {@link org.springframework.data.domain.Pageable} should get if no corresponding * parameter defined in request (default is 0). */ int page() default 0; } MVC 参数处理器: org.springframework.data.web.PageableHandlerMethodArgumentResolver 前端分页 前端展示层,分别从服务端渲染方案以及纯前端脚本方案去看分页最终的页面呈现逻辑。 这里选取的分别是Java 常用的模板引擎 thymeleaf 以及热门的前端框架 element-ui。 从用法以及组件源码角度,去理清终端处理分页的常见方式。 ①thymeleaf - 模板引擎 Thymeleafis a modern server-side Java template engine for both web and standalone environments. <!-- spring-data-examples\web\example\src\main\resources\templates\users.html--> <nav> <!-- class样式 bootstrap 默认的分页用法--> <ul class="pagination" th:with="total = ${users.totalPages}"> <li th:if="${users.hasPrevious()}"> <a th:href="@{/users(page=${users.previousPageable().pageNumber},size=${users.size})}" aria-label="Previous"> <span aria-hidden="true">«</span> </a> </li> <!-- spring-data-examples 分页计算从0 开始, /users?page=0&size=10 --> <!-- 生成页码列表,呈现形式即我们常见的 ①②③④ --> <li th:each="page : ${#numbers.sequence(0, total - 1)}"><a th:href="@{/users(page=${page},size=${users.size})}" th:text="${page + 1}">1</a></li> <li th:if="${users.hasNext()}"> <!-- 下一页实现,因为是服务器端渲染生成。在最终生成的html 中,这里的href 是固定的。实现思路和纯前端技术,使用javascript 脚本对比看 --> <a th:href="@{/users(page=${users.nextPageable().pageNumber},size=${users.size})}" aria-label="Next"> <span aria-hidden="true">»</span> </a> </li> </ul> </nav> ②element-ui 前端框架 // from node_modules\element-ui\packages\pagination\src\pagination.js // page-count 总页数,total 和 page-count 设置任意一个就可以达到显示页码的功能; computed: { internalPageCount() { if (typeof this.total === 'number') { // 页数计算使用 Math.ceil return Math.max(1, Math.ceil(this.total / this.internalPageSize)); } else if (typeof this.pageCount === 'number') { return Math.max(1, this.pageCount); } return null; } }, /** * 起始页计算。 page 页码从1 开始。 */ getValidCurrentPage(value) { value = parseInt(value, 10); // 从源码的实现可以看到,一个稳定强大的开源框架,在容错、边界处理的严谨和思考。 const havePageCount = typeof this.internalPageCount === 'number'; let resetValue; if (!havePageCount) { if (isNaN(value) || value < 1) resetValue = 1; } else { // 强制赋值起始值 1 if (value < 1) { resetValue = 1; } else if (value > this.internalPageCount) { // 数据越界,强制拉回到PageCount resetValue = this.internalPageCount; } } if (resetValue === undefined && isNaN(value)) { resetValue = 1; } else if (resetValue === 0) { resetValue = 1; } return resetValue === undefined ? value : resetValue; }, 总结 技术永远是关联的,思路永远是相似的,方案永远是相通的。单独的去分析某个技术或者原理,总是有边界和困惑存在。纵向拉伸,横向对比才能对技术方案有深刻的理解。在实战应用中,能灵活自如。 分页实现的方案最终是由数据库决定的,对于众多的数据库,通过SQL 语法的规范去框定,以及我们常用的各种组件或者插件去适配。 纵向对比,我们可以看到不同技术层的职责和通用适配的实现过程,对于我们日常的业务通用开发以及不同业务的兼容有很大的借鉴意义。 横向对比,例如前端展示层的实现思路,其实差别非常大。如果使用 thymeleaf,结构简单清晰,但交互响应上都会通过服务器。如果选用element-ui,分页只依赖展示层,和服务端彻底解构。在技术选型中可以根据各自的优缺点进行适度的抉择。

优秀的个人博客,低调大师

Elasticsearch API 使用指南(全)

1. 集群支持的选项 curl -XGET "http://172.0.0.52:9200/_cat" 2. 查看节点信息 curl -XGET "http://172.0.0.52:9200/_cat/nodes?v" 3. 查看master节点信息 curl -XGET "http://172.0.0.52:9200/_cat/master?v" 4.查看所有节点上的热点线程 curl -XGET "http://172.0.0.52:9200/_nodes/hot_threads" 5.查看有问题的分片或索引 curl -XGET "http://172.0.0.52:9200/_cluster/allocation/explain?pretty" 6.查看线程池设置 curl -XGET "http://172.0.0.52:9200/_nodes/thread_pool/" 7.统计全部信息 curl -XGET "http://172.0.0.52:9200/_cluster/stats?human&pretty" 8.查看集群状态 curl -XGET "http://172.0.0.52:9200/_cluster/health?pretty" 9.查看ES信息 curl -XGET "http://172.0.0.52:9200/" 10.获取所有索引的信息 curl -XGET "http://172.0.0.52:9200/_cat/indices?v&pretty" curl -XGET "http://172.0.0.52:9200/_cat/nodes?v" curl -XGET "http://172.0.0.52:9200/_cat/segments?v&h=shard,segment,size,size.memory" 11.获取所有文档数量 curl -XGET "http://172.0.0.52:9200/_count?pretty" -H 'Content-Type: application/json' -d' { "query": { "match_all": {} } }' 12. 查看集群的健康状态 green:所有功能都是完好的; yellow:所有数据是可用的,但是一些副本还没有被分配; red代表一些数据由于某些原因已经不可用。 注意,尽管一个集群是red状态,它仍然可以提供部分服务(比如,它会继续从可用的切片数据里搜索),但是在失去部分数据后,需要尽快去修复。 curl -XGET "http://172.0.0.52:9200/_cat/health?v" 13. 创建索引 test_one 索引名 pretty 参数表示输出格式良好的JSON响应(如果存在) curl -XPUT "http://172.0.0.52:9200/test_one?pretty" 14. 查看索引列表 curl -XGET "http://172.0.0.52:9200/_cat/indices?v" curl -XGET "http://172.0.0.52:9200/test_one" 15. 删除索引 根据索引名称删除 curl -XDELETE "http://172.0.0.52:9200/test_one?pretty" 可以一次删除多个索引(以逗号间隔)删除所有索引_all或通配符 * 16. 创建文档 向es中插入文档的时候,必须要指定一个类型(type) 16.1.使用PUT来创建文档,需要指定id 索引 index:test_one 类型 type:test_type _id:1 curl -XPUT "http://172.0.0.52:9200/test_one/test_type/1?pretty" -H 'Content-Type: application/json' -d' {"name": "ghl", "age": 24, "sex": "male"}' 16.2. 使用POST来创建文档,可以不指定id(不指定时随机生成id) curl -XPOST "http://172.0.0.52:9200/test_one/test_type?pretty" -H 'Content-Type: application/json' -d' {"name": "Jack"}' 17. 查看文档 curl -XGET "http://172.0.0.52:9200/test_one/test_type/1?pretty" 18. 替换文档 使用PUT并指定id时,es会使用新的文档替换原文档 curl -XPUT "http://172.0.0.52:9200/test_one/test_type/1?pretty" -H 'Content-Type: application/json' -d' {"name": "Jack"}' 19. 更新文档 curl -XPOST "http://172.0.0.52:9200/test_one/test_type/1/_update?pretty" -H 'Content-Type: application/json' -d' {"doc":{"name": "Lucy"}}' 20. 删除文档 curl -XDELETE "http://172.0.0.52:9200/test_one/test_type/1?pretty" 21. 索引的增删改查有一个类似的格式下: curl -XGET "http://172.0.0.52:9200/<Index>/<Type>/<ID>" REST Verb:REST风格的语法谓词; Node:节点ip; port:节点端口号,默认9200; Index:索引名; Type:索引类型; ID:操作对象的ID号; 22. 判断索引是否存在 curl -XHEAD "http://172.0.0.52:9200/test_one" 23. 查看索引模板 curl -XGET "http://172.0.0.52:9200/_template/template_1" curl -XGET "http://172.0.0.52:9200/_template/temp*" curl -XGET "http://172.0.0.52:9200/_template/template_1,template_2" curl -XGET "http://172.0.0.52:9200/_template" 24. 删除模板 curl -XDELETE "http://172.0.0.52:9200/_template/template_1" 25. 打开/关闭索引 curl -XPOST "http://172.0.0.52:9200/test_one/_close" curl -XPOST "http://172.0.0.52:9200/test_one/_open" curl -XGET "http://172.0.0.52:9200/_cat/indices?v" 26.查看索引状态信息 curl -XGET "http://172.0.0.52:9200/_stats" curl -XGET "http://172.0.0.52:9200/logstash-nginx-access-2019.08.07,test_one/_stats" 27.查看索引段信息 curl -XGET "http://172.0.0.52:9200/test_one/_segments" curl -XGET "http://172.0.0.52:9200/logstash-nginx-access-2019.08.07,test_one/_segments" curl -XGET "http://172.0.0.52:9200/_segments"

优秀的个人博客,低调大师

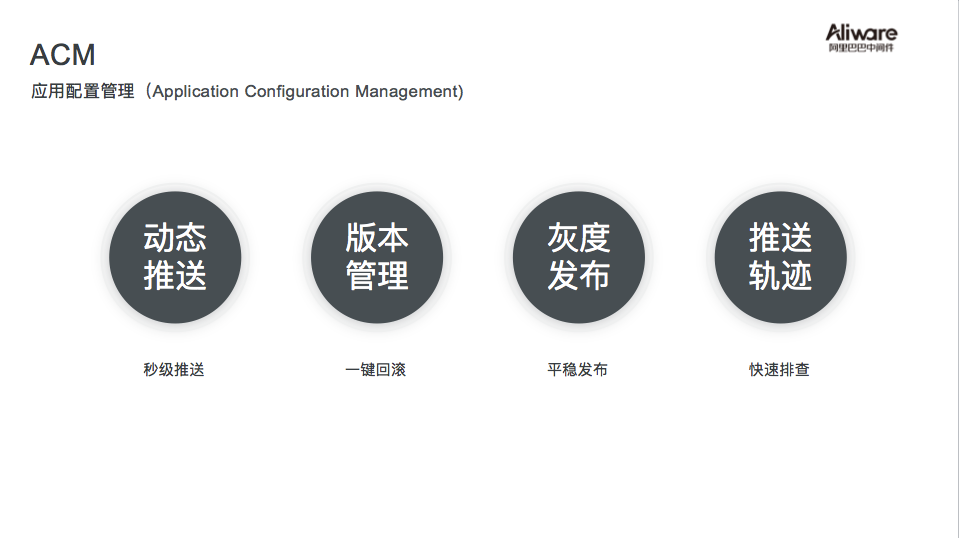
ACM 无缝支持 Spring 全栈

ACM 产品介绍 应用配置管理 ACM(Application ConfigurationManagement)前身为淘宝内部配置中心Diamond,是一款在分布式架构环境中对应用配置进行“集中管理”和“动态推送”的配置中心产品。利用ACM,您可以在微服务、DevOps、大数据等场景下极大减轻配置管理的工作量,并增强配置管理的服务能力。 核心功能 统一管控:您可以在 ACM 的控制台统一管理所有应用的配置,而不再像传统配置那样,分散在各处。 动态推送:当你在 ACM 控制台修改了配置, ACM 能够实时将修改后的配置推送到接入 ACM 服务的应用进程中。 版本管理:ACM 控制台保留配置变更各个历史版本,当前你发现误修改配置后,能够快速得回滚,降低影响面。 灰度发布:有一些配置是相对比较重要,一旦变更,可能会带来很大的影响。通过灰度发布功能,

优秀的个人博客,低调大师

全排列

说起回溯算法,渊源颇深,我上次做过一道,本应该这次能拿下但是,又没拿下,不过这次有点理解它的思想了, 每次的回溯就是一个二叉树,简单的说,就是你执行的操作需要回溯时它会返回调用它的方法哪里的状态,进行下一步的执行。 public List<List<Integer>> permute(int[] nums) { List<List<Integer>> temp = new ArrayList<>(20); zuhe(temp,0,nums); return temp; } private void zuhe(List<List<Integer>> temp, int n, int[] nums) { /* * 每次让其加一个就行了,就空了, * */ if (nums.length == n) { List<Integer> integers =new ArrayList<>(20); for (int r:nums){ integers.add(r); } temp.add(integers); } for (int i = n, length = nums.length; i <length ; i++) { change(nums,i,n); zuhe(temp,n+1,nums); change(nums,i,n); } } public void change(int[] nums, int i, int j) { int temp = nums[i]; nums[i] = nums[j]; nums[j] = temp; } 这个需要多练,具体自己体会

优秀的个人博客,低调大师

Python全栈工程师

ParisGabriel Python 入门基础 print(“hello world”)变量 : 存储信息的,日后被调用、修改操作常量: 固定不变的量,字母大写命名规则:1. 字母数字下划线组成2. 不能以数字开头,不能含有特殊字符和空格3. 不能以保留字命名4. 不能以中文命名5. 定义的变量名应该有意义6. 驼峰式命、 下划线分割单词7. 变量名区分大小写a=1b=2if a<b: print("Yes") print("Yes") print("Yes") print("Yes")else: print("No")a=1b=2 if a>b: print("Yes") elif a==b: print("第三") else: print("any") if 条件1: 自拍elif 条件2: 蹦 else: 跳舞 # 单行注释'''多行注释'''""" 多行注释 """ input() "abc" + "qwe" file.py 文件的扩展名:.py : python的程序文件.txt : 文本文件pdf chm html doc xml xls ppt jpg png gif jpeg bmpavi rmvb MP4 mkv 3gp WMV MP3 flue mid True 真 正确的False 假 错误的 a b = 100c = 1000 if b <= a <= c: print("True") num number num1 = intpu("Num1:")num2 = intpu("Num2:")num3 = intpu("Num3:") 输出三个数字中的最大值/最小值 if num1>num2>num3: #num1最大else: #num1<num2 if num1>num2>num3 #num1最大elif num1>num3>num2 #num1最大elif num2>num1>num3 #num2最大elif num2>num3>num1 #num2最大elif num3>num2>num1 #num3最大else num3>num1>num2 #num3最大 num1 num2 num3 max_num =0if num1>num2: max_num= num1 if max_num > num3: print("Max NUM is",max_num) else: print("Max NUM is",num3)else: max_num = num2 if max_num > num3: print("Max NUM is",max_num) else: print("Max NUM is",num3) num += 1 等价于 num = num + 1num -= 1 等价于 num = num - 1num *= 2 等价于 num = num * 2num /= 2 等价于 num = num / 2num //= 2 等价于 num = num // 2num %= 2 等价于 num = num % 2num **= 2 等价于 num = num ** 2 and 且,并且只有两个条件全部为True(正确)的时候, 结果才会为True(正确) 条件1 and 条件2 5>3 and 6<2 True or 或,或者只要有一个条件为True,则结果为Ture,5>3 or 6<2 真 或 假 not 不,雅蠛蝶 not 5>3 == Falsenot 5<3 == True a>b and (c>d or (not f)) (not (not True)) or (False and (not True)) 条件1 and 条件2条件1 or 条件2 短路原则对于and 如果前面的第一个条件为假,那么这个and前后两个条件组成的表达式 的计算结果就一定为假,第二个条件就不会被计算 对于or 如果前面的第一个条件为真,那么这个or前后两个条件组成的表达式 的计算结果就一定为真,第二个条件就不会被计算 True or True and False 猜年龄 age = 50 user_input_age = int(input("Age is :"))if ....while 循环 while 条件: print("any") print("any") num = 1 while num<10: # 2 print(num) # 2 num+=1 # 3 if num == 9: # 3 breaknum = 1 while num<=100: # num<=100 等价于 True # while num<=100: 等价于 while True: if num%2 == 0: print(num) num += 1num = 1 while num<=100: if num%2 == 1: print(num) num += 1 age = 50 #user_input_age = int(input("Age is :")) flag = True while flag: user_input_age = int(input("Age is :")) if user_input_age == age: print("Yes") flag =False elif user_input_age > age: print("Is bigger") else: print("Is smaller") print("End") break # 终止age = 50 #user_input_age = int(input("Age is :")) #flag = True# break while True: user_input_age = int(input("Age is :")) if user_input_age == age: print("Yes") break elif user_input_age > age: print("Is bigger") else: print("Is smaller") print("End") continue 继续 if a>b and d<f or 5>3 and d == e: ...... while 条件: ....else: .... statement 语句 num = 1while num <= 10: num += 1 if num == 5: break print(num)else: print("This is else statement") while 条件1: ..... while 条件2: .... 1*1=11*2=2 2*2=41*3=3 2*3=6 3*3=9.... #print("hello world.",end="__") # \n \r\n \r#print("hello world.",end="__")#print("hello world.",end="__") num1 = 0 while num1<=5: print(num1,end="_") num2 = 0 while num2<=7: print(num2,end="-") num2+=1 num1+=1 print() # print(end="\n") #0_0-1-2-3-4-5-6-7-#1_0-1-2-3-4-5-6-7- Height 高度width 宽度 height = int(input("Height:")) # 用户输入一个高度width = int(input("width:")) # 用户输入一个宽度 num_height = 1while num_height <=height: num_width = 1 while num_width <= width: print("#", end="") num_width += 1 print() num_height += 1 12345678223456783234567842345678 第一行的时候 8字符 8次循环第二行的时候 8字符 8次循环第三行的时候 8字符 8次循环第四行的时候 8字符 8次循环 width = int(input("width:")) num_width = 1 while num_width<=width: print("#", end="") num_width +=1print() num_width = 1while num_width<=width: print("#", end="") num_width +=1print() num_width = 1while num_width<=width: print("#", end="") num_width +=1print() num_width = 1while num_width<=width: print("#", end="") num_width +=1 #print("#",end="")#print("#",end="")#print("#",end="")#print("#",end="") print() num = 4 while num>0: print("#", end="") num -= 1 print() # @ == #### height = int(input("Height:")) # 用户输入一个高度width = int(input("width:")) # 用户输入一个宽度 #num2 = height num2 = height # 第一步: 赋值while num2 > 0: # 第二步 :num2 == 2 num1 = width # 第三步: 赋值 while num1>0: # 第四部:num1==2 # 第七步:num1 = 1 print("#", end="") # 第五步: 不换行 打印一个# 第八步: 不换行 打印一个# num1 -= 1 #第六步: num1 = 1 第九步: num1 = 0 print() # 第十步 : 只是换行 num2 -= 1 # 第十一步 : num2=1 #### print("1*1=",1) # "1*1=",1 == str(m)+"*"+str(n)+"=",1 m = 2n = 2 print( str(m)+ "*" + str(n) + "=" , m*n )line = 5 # 第一步 : 赋值while line>0: # 第二部 line=5 tmp = line # 第三部 : tmp =5 tmp=4 while tmp>0: # 第四部 : tmp =5 #第七步 tmp=4 #第十部: tmp=3 第十三步 tmp=2 print("*",end="") #第五步 #第八部 #第十一部 #第十四步 tmp = tmp-1 # 第六步 tmp = 4 # 第九步 tmp=3 # 第十二步 tmp=2 第十五步 tmp= 1 print() #print(line) line -= 1first = 1while first<=9: sec = 1 while sec <= first: print( str(sec)+"*"+ str(first) +"="+str(sec * first), end="\t") sec += 1 print() first += 1 今天太晚了明天要上课 明天晚上补图片 代码

优秀的个人博客,低调大师

mysql全表抽取到MPP

代码实例 package com.epoint.com.mysql_mpp_full; import java.io.FileNotFoundException; import java.sql.Connection; import java.sql.DriverManager; import java.sql.PreparedStatement; import java.sql.ResultSet; import java.sql.ResultSetMetaData; import java.sql.SQLException; import java.sql.Statement; import java.text.SimpleDateFormat; import java.util.ArrayList; import java.util.Date; import java.util.List; import java.util.TimeZone; public class AutoMysqltoMPP { private static String MYSQLUSERNAME = "root"; private static String MYSQLPASSWORD = "Gepoint"; private static String MYSQLDRIVER = "com.mysql.jdbc.Driver"; private static String MYSQLURL = "jdbc:mysql://100.2.5.221:3307/dep_fr_db"; private static String MYSQLDATABASE = "dep_fr_db"; private static String MPPDRIVER = "com.MPP.jdbc.Driver"; private static String MPPURL = "jdbc:MPP://100.2.5.1:5258/dep_fr_db"; private static String MPPUSERNAME = "mpp"; private static String MPPPASSWORD = "h3c"; private static Connection mysqlconn = null; private static Statement mysqlpstm = null; private static ResultSet mysqlrs = null; private static Connection mppconn = null; private static Statement mppstm = null; private static ResultSet mpprs = null; String sql1 = " "; String sql2 = " "; String sql3 = " "; String sql4 = " "; String sql5 = " "; String sql6 = " "; public static void main(String[] args) throws Exception { AutoMysqltoMPP aidth = new AutoMysqltoMPP(); aidth.getMYSQLConnection(); aidth.MYSQLReleaseResource(); aidth.getMPPConnection(); aidth.MPPReleaseResource(); aidth.CreateMPPTable(); // aidth.ImportDataToMPP(); System.out.println("表已创建完毕,赶紧去查看表吧!!"); SimpleDateFormat sdf = new SimpleDateFormat("HH:mm:ss:SS"); TimeZone t = sdf.getTimeZone(); t.setRawOffset(0); sdf.setTimeZone(t); Long startTime = System.currentTimeMillis(); // 此段为要放置测取时间的函数 mysqlconn = getMYSQLConnection(); mppconn = getMPPConnection(); mppstm = mppconn.createStatement(); mysqlpstm = mysqlconn.createStatement(); mppstm.execute("TRUNCATE table code_main"); aidth.tableInput(); Long endTime = System.currentTimeMillis(); System.out.println("用时:" + sdf.format(new Date(endTime - startTime))); } public void CreateMPPTable() { mysqlconn = getMYSQLConnection(); mppconn = getMPPConnection(); try { mppstm = mppconn.createStatement(); mysqlpstm = mysqlconn.createStatement(); int i = 0; String sql = "SELECT table_schema\r\n" + " ,table_name\r\n" + " ,(\r\n" + " CASE \r\n" + " WHEN ORDINAL_POSITION = mincol\r\n" + " AND ORDINAL_POSITION < maxcol\r\n" + " THEN CONCAT (\"create table if not exists \"\r\n" + " ,table_schema\r\n" + " ,\".\"\r\n" + " ,table_name\r\n" + " ,\"(`\"\r\n" + " ,column_name\r\n" + " ,\"` \"\r\n" + " ,COLUMN_TYPE\r\n" + " ,\",\"\r\n" + " )\r\n" + " WHEN ORDINAL_POSITION = mincol\r\n" + " AND ORDINAL_POSITION = maxcol\r\n" + " THEN CONCAT (\"create table if not exists \"\r\n" + " ,table_schema\r\n" + " ,\".\"\r\n" + " ,table_name\r\n" + " ,\"(`\"\r\n" + " ,column_name\r\n" + " ,\"` \"\r\n" + " ,COLUMN_TYPE\r\n" + " ,\");\"\r\n" + " )\r\n" + " WHEN ORDINAL_POSITION > mincol\r\n" + " AND ORDINAL_POSITION < maxcol\r\n" + " THEN CONCAT (\r\n" + " \"`\"\r\n" + " ,column_name\r\n" + " ,\"` \"\r\n" + " ,COLUMN_TYPE\r\n" + " ,\",\"\r\n" + " )\r\n" + " WHEN ORDINAL_POSITION = maxcol\r\n" + " THEN CONCAT (\r\n" + " \"`\"\r\n" + " ,column_name\r\n" + " ,\"` \"\r\n" + " ,COLUMN_TYPE\r\n" + " ,\");\"\r\n" + " )\r\n" + " END\r\n" + " ) AS statement\r\n" + " ,ORDINAL_POSITION\r\n" + " ,maxcol\r\n" + " ,mincol\r\n" + "FROM (\r\n" + " SELECT b.table_schema,b.table_name,b.ORDINAL_POSITION,b.column_name,\r\n" + " (case\r\n" + " when column_type = 'timestamp' then 'datetime'\r\n" + " when column_type = 'bit(1)' then 'int(1)'\r\n" + " else\r\n" + " column_type\r\n" + " end ) AS column_type\r\n" + " ,a.maxcol\r\n" + " ,a.mincol\r\n" + " FROM (\r\n" + " SELECT table_schema\r\n" + " ,table_name\r\n" + " ,max(ORDINAL_POSITION) maxcol\r\n" + " ,min(ORDINAL_POSITION) mincol\r\n" + " FROM information_schema.COLUMNS\r\n" + " GROUP BY table_schema\r\n" + " ,table_name\r\n" + " ) a\r\n" + " JOIN (\r\n" + " SELECT table_schema\r\n" + " ,table_name\r\n" + " ,ORDINAL_POSITION\r\n" + " ,column_name\r\n" + " ,COLUMN_TYPE\r\n" + " FROM information_schema.COLUMNS\r\n" + " ORDER BY table_schema\r\n" + " ,table_name\r\n" + " ,ORDINAL_POSITION ASC\r\n" + " ) b ON a.table_schema = b.table_schema\r\n" + " AND a.table_name = b.table_name\r\n" + " ) c\r\n" + "WHERE table_schema = '" + MYSQLDATABASE + "'"; mysqlrs = mysqlpstm.executeQuery(sql); while (mysqlrs.next()) { sql1 = mysqlrs.getString(3); sql2 = sql2 + sql1; } sql3 = "create database IF NOT EXISTS " + MYSQLDATABASE; mppstm.execute(sql3); System.out.println("-------------------建mpp表,表结构的语句为:" + sql2); String[] sqls = sql2.split(";"); for (String m : sqls) { mppstm.execute(m); } System.out.println("----------------------------------------建mpp表已结束!!!!!!!!!!!!!!!!!!!!!!!!!!!!!"); mppstm.close(); mysqlpstm.close(); } catch (SQLException e) { e.printStackTrace(); } finally { MYSQLReleaseResource(); MPPReleaseResource(); } } public void ImportDataToMPP() { mysqlconn = getMYSQLConnection(); mppconn = getMPPConnection(); String sql = "select table_name from user_tables where num_rows > 0 order by table_name asc"; int i = 0; try { mysqlpstm = mysqlconn.createStatement(); mysqlrs = mysqlpstm.executeQuery(sql); mppstm = mppconn.createStatement(); while (mysqlrs.next()) { i = i + 1; String table_name = mysqlrs.getString("table_name").replaceAll("\\$", ""); String sql7 = "insert into " + MYSQLDATABASE + "." + table_name + " select * from " + MYSQLDATABASE + "_ex." + table_name; System.out.println("现在插入第" + i + "个表:" + sql7); mppstm.execute(sql7); } } catch (SQLException e) { e.printStackTrace(); } finally { MYSQLReleaseResource(); MPPReleaseResource(); } } public static List<List<String>> tableInput() throws FileNotFoundException, SQLException { List<List<String>> FindList = new ArrayList<List<String>>(); mysqlconn = getMYSQLConnection(); mppconn = getMPPConnection(); mppstm = mppconn.createStatement(); mysqlpstm = mysqlconn.createStatement(); PreparedStatement pre = null; ResultSet resultSet = null; String sql = "SELECT CODEID,CODENAME,LEVNUM,CATEGORYNUM,description,isfromsoa FROM code_main"; try { pre = mysqlconn.prepareStatement(sql); resultSet = pre.executeQuery(); String[] columu = { "CODEID","CODENAME","LEVNUM","CATEGORYNUM","description","isfromsoa"}; int i = 0; while (resultSet.next()) { List<String> minList = new ArrayList<String>(); for (String each : columu) { minList.add(resultSet.getString(each)); } FindList.add(minList); i++; if (i % 10000 == 0) { // 设置的每次提交大小为10000 executeManySql(FindList); FindList.removeAll(FindList); System.out.println(i); } } executeManySql(FindList);// 最后别忘了提交剩余的 return FindList; } catch (SQLException e) { // TODO Auto-generated catch block e.printStackTrace(); } finally { try { pre.close();// 关闭Statement } catch (SQLException e) { e.printStackTrace(); } try { mppstm.close(); mysqlpstm.close(); } catch (SQLException e) { e.printStackTrace(); } } return null; } //executeManySql(FindList)函数如下,因为数据量比较大,所以我设置的每次提交大小为10000,这样就不会内存溢出了。 public static void executeManySql(List<List<String>> FindList) throws SQLException { mysqlconn = getMYSQLConnection(); mppconn = getMPPConnection(); mppstm = mppconn.createStatement(); mysqlpstm = mysqlconn.createStatement(); mppconn.setAutoCommit(false); Statement stat = null; PreparedStatement pst = (PreparedStatement) mppconn .prepareStatement("insert into code_main values (?,?,?,?,?,?)"); for (List<String> minList : FindList) { for (int i = 0; i < minList.size(); i++) { pst.setString(i + 1, minList.get(i)); } // 把一个SQL命令加入命令列表 pst.addBatch(); } // 执行批量更新 pst.executeBatch(); // 语句执行完毕,提交本事务 mppconn.commit(); pst.close(); mppstm.close(); mysqlpstm.close();// 一定要记住关闭连接,不然mysql回应为too many connection自我保护而断开。 }//同时我还设置了计时的函数,可以看到这个从数据抽取到完成数据迁移的时间。 public static Connection getMYSQLConnection() { try { Class.forName(MYSQLDRIVER); mysqlconn = DriverManager.getConnection(MYSQLURL, MYSQLUSERNAME, MYSQLPASSWORD); } catch (ClassNotFoundException e) { throw new RuntimeException("class not find !", e); } catch (SQLException e) { throw new RuntimeException("get connection error!", e); } return mysqlconn; } public void MYSQLReleaseResource() { if (mysqlrs != null) { try { mysqlrs.close(); } catch (SQLException e) { e.printStackTrace(); } } if (mysqlpstm != null) { try { mysqlpstm.close(); } catch (SQLException e) { e.printStackTrace(); } } if (mysqlconn != null) { try { mysqlconn.close(); } catch (SQLException e) { e.printStackTrace(); } } } public static Connection getMPPConnection() { try { Class.forName(MPPDRIVER); mppconn = DriverManager.getConnection(MPPURL, MPPUSERNAME, MPPPASSWORD); } catch (ClassNotFoundException e) { throw new RuntimeException("class not find !", e); } catch (SQLException e) { throw new RuntimeException("get connection error!", e); } return mppconn; } public void MPPReleaseResource() { if (mpprs != null) { try { mpprs.close(); } catch (SQLException e) { e.printStackTrace(); } } if (mppstm != null) { try { mppstm.close(); } catch (SQLException e) { e.printStackTrace(); } } if (mppconn != null) { try { mppconn.close(); } catch (SQLException e) { e.printStackTrace(); } } } }

资源下载

更多资源
Nacos

Nacos

Nacos /nɑ:kəʊs/ 是 Dynamic Naming and Configuration Service 的首字母简称,一个易于构建 AI Agent 应用的动态服务发现、配置管理和AI智能体管理平台。Nacos 致力于帮助您发现、配置和管理微服务及AI智能体应用。Nacos 提供了一组简单易用的特性集,帮助您快速实现动态服务发现、服务配置、服务元数据、流量管理。Nacos 帮助您更敏捷和容易地构建、交付和管理微服务平台。

Spring

Spring

Spring框架(Spring Framework)是由Rod Johnson于2002年提出的开源Java企业级应用框架,旨在通过使用JavaBean替代传统EJB实现方式降低企业级编程开发的复杂性。该框架基于简单性、可测试性和松耦合性设计理念,提供核心容器、应用上下文、数据访问集成等模块,支持整合Hibernate、Struts等第三方框架,其适用范围不仅限于服务器端开发,绝大多数Java应用均可从中受益。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

Sublime Text

Sublime Text

Sublime Text具有漂亮的用户界面和强大的功能,例如代码缩略图,Python的插件,代码段等。还可自定义键绑定,菜单和工具栏。Sublime Text 的主要功能包括:拼写检查,书签,完整的 Python API , Goto 功能,即时项目切换,多选择,多窗口等等。Sublime Text 是一个跨平台的编辑器,同时支持Windows、Linux、Mac OS X等操作系统。

用户登录
用户注册