首页 文章 精选 留言 我的

精选列表

搜索[执行机制],共10000篇文章
优秀的个人博客,低调大师

hive执行流程(2)-CommandProcessor相关类

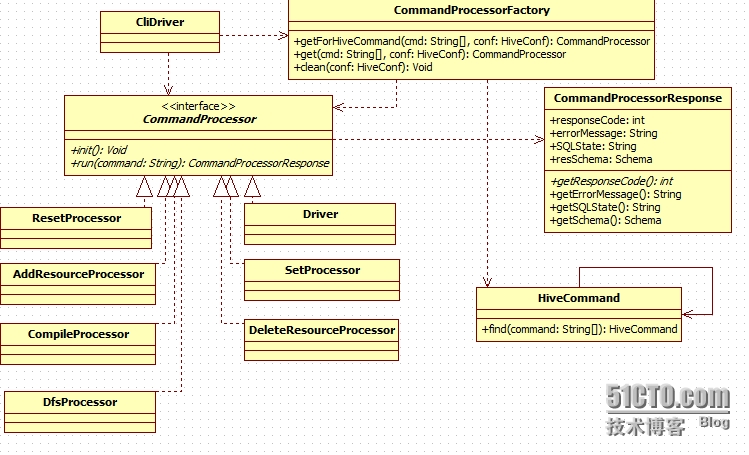
在 上一篇的CliDriver类中介绍了CliDriver类会引用到CommandProcessor相关类,主要是根据命令来判断具体实现类,比如通过本地的hive cli启动时,运行hive的命令(非list/source/shell命令等)时在processCmd方法中有如下实现: 1 2 3 4 5 6 7 8 try { CommandProcessorproc=CommandProcessorFactory.get(tokens,(HiveConf)conf); //根据命令判断具体的CommandProcessor实现类 ret=processLocalCmd(cmd,proc,ss); } catch (SQLExceptione){ console.printError( "Failedprocessingcommand" +tokens[ 0 ]+ "" +e.getLocalizedMessage(), org.apache.hadoop.util.StringUtils.stringifyException(e)); ret= 1 ; } 具体的决定什么样的命令对应什么样的具体实现类由 CommandProcessorFactory 规定:如果是set,reset,dfs,add delete,compile等命令,返回对应的CommandProcessor实现类。其余有效命令比如select,insert 都是返回Driver类。 CommandProcessor相关类在org.apache.hadoop.hive.ql.processors包中,类的具体的uml图如下: 简单看下几个类的实现: 1.HiveCommand类,是一个迭代类,定义了非sql的一些语句 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 public enum HiveCommand{ SET(), RESET(), DFS(), ADD(), DELETE(), COMPILE(); private static final Set<String>COMMANDS= new HashSet<String>(); static { for (HiveCommandcommand:HiveCommand.values()){ COMMANDS.add(command.name()); } } public static HiveCommandfind(String[]command){ if ( null ==command){ return null ; } Stringcmd=command[ 0 ]; if (cmd!= null ){ cmd=cmd.trim().toUpperCase(); if (command.length> 1 && "role" .equalsIgnoreCase(command[ 1 ])){ //specialhandlingforsetroler1statement return null ; } else if (COMMANDS.contains(cmd)){ return HiveCommand.valueOf(cmd); } } return null ; } } 2.CommandProcessorFactory 类,主要用于获取具体的命令实现类 主要定义了get和getForHiveCommand方法 方法调用get----->getForHiveCommand,其中getForHiveCommand会调HiveCommand类,HiveCommand类是一个枚举类型,定义了一些命令。 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 getForHiveCommand方法中: public static CommandProcessorgetForHiveCommand(String[]cmd,HiveConfconf) throws SQLException{ HiveCommandhiveCommand=HiveCommand.find(cmd); //sql语句返回值为null if (hiveCommand== null ||isBlank(cmd[ 0 ])){ return null ; } if (conf== null ){ conf= new HiveConf(); } Set<String>availableCommands= new HashSet<String>(); for (StringavailableCommand:conf.getVar(HiveConf.ConfVars.HIVE_SECURITY_COMMAND_WHITELIST).split( "," )){ availableCommands.add(availableCommand.toLowerCase().trim()); } if (!availableCommands.contains(cmd[ 0 ].trim().toLowerCase())){ throw new SQLException( "Insufficientprivilegestoexecute" +cmd[ 0 ], "42000" ); } switch (hiveCommand){ //每种语句对应的具体的processor类 case SET: return new SetProcessor(); case RESET: return new ResetProcessor(); case DFS: SessionStatess=SessionState.get(); return new DfsProcessor(ss.getConf()); case ADD: return new AddResourceProcessor(); case DELETE: return new DeleteResourceProcessor(); case COMPILE: return new CompileProcessor(); default : throw new AssertionError( "UnknownHiveCommand" +hiveCommand); } } get方法: public static CommandProcessorget(String[]cmd,HiveConfconf) throws SQLException{ CommandProcessorresult=getForHiveCommand(cmd,conf); if (result!= null ){ return result; //如果result不为空,即命令在HiveCommand的迭代器中定义的话,直接返回对应的结果 } if (isBlank(cmd[ 0 ])){ return null ; } else { //为空的话返回Driver类的实例 if (conf== null ){ return new Driver(); } Driverdrv=mapDrivers.get(conf); if (drv== null ){ drv= new Driver(); mapDrivers.put(conf,drv); } drv.init(); return drv; } } 3.CommandProcessorResponse类封装了processor的返回信息,比如返回码,错误信息等。 4.CommandProcessor 类是一个接口,具体的实现类由下面几个: 1 AddResourceProcessor/CompileProcessor/DeleteResourceProcessor/DfsProcessor/ResetProcessor/SetProcessor/Driver 主要实现方法在各个实现类的run方法中,run方法返回一个CommandProcessorResponse的对象。 下面简单的说下常用的几个实现类: a.AddResourceProcessor类是处理add xxx命令的。 主要有两个步骤: 1)判断命令的合法性(长度,类型是否在FILE,JAR,ARCHIVE3种之内) 2)调用SessionState的add_resource方法( 1 2 SessionState.add_resource方法---->调用SessionState.downloadResource---> 调用FileSystem的copyToLocalFile方法,把文件下载到本地 ) 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 public CommandProcessorResponserun(Stringcommand){ SessionStatess=SessionState.get(); command= new VariableSubstitution().substitute(ss.getConf(),command); String[]tokens=command.split( "\\s+" ); SessionState.ResourceTypet; if (tokens.length< 2 ||(t=SessionState.find_resource_type(tokens[ 0 ]))== null ){ console.printError( "Usage:add[" +StringUtils.join(SessionState.ResourceType.values(), "|" ) + "]<value>[<value>]*" ); return new CommandProcessorResponse( 1 ); } for ( int i= 1 ;i<tokens.length;i++){ StringresourceFile=ss.add_resource(t,tokens[i]); if (resourceFile== null ){ StringerrMsg=tokens[i]+ "doesnotexist." ; return new CommandProcessorResponse( 1 ,errMsg, null ); } } return new CommandProcessorResponse( 0 ); } b.相反的DeleteResourceProcessor是用来处理delete xxx命令的。 最终调用了SessionState的delete_resource方法,把resource从HashMap中去掉。 1 2 3 4 5 6 7 8 9 10 11 12 SessionState的delete_resource方法 public boolean delete_resource(ResourceTypet,Stringvalue){ if (resource_map.get(t)== null ){ return false ; } if (t.hook!= null ){ if (!t.hook.postHook(resource_map.get(t),value)){ return false ; } } return (resource_map.get(t).remove(value)); } c.DfsProcessor类用来处理dfs 命令,即已“!dfs”开头的命令,最终调用了FsShell的run方法 d.SetProcessor类用来处理set xxx等命令,可以用来设置参数,变量等。 设置参数时 1)以system: 开头的调用了System.getProperties().setProperty方法。 比如 1 2 3 hive>setsystem:user.name=xxxx; hive>setsystem:user.name; system:user.name=xxxx 2)以hiveconf:开头: 调用了HiveConf的verifyAndSet方法 3)以hivevar:开头: ss.getHiveVariables().put方法 Driver的实现比较复杂,放在下篇讲解。 本文转自菜菜光 51CTO博客,原文链接:http://blog.51cto.com/caiguangguang/1566936,如需转载请自行联系原作者

优秀的个人博客,低调大师

python环境下,执行系统命令方法

1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 方法 1 :os.system >>> import os >>>os.system( 'ls' ) anaconda - ks.cfgDjango - 1.2 . 7 install.log.syslogptyprocess - 0.5 . 1 server1.py公共的文档 a.pydockermysitepycharm - 2016.3 . 2 server.py模板下载 client1.pydocker - 1.7 . 1 paramiko - 2.1 . 1 pycharm - license.txtsetuptools - 2.0 视频音乐 client.pyinstall.logpexpect - 4.2 . 1 pycrypto - 2.6 . 1 spawn - 0.1 图片桌面 0 >>> 方法 2 :os.popen >>> import os >>>tmp = os.popen( 'ls' ) >>>tmp.readlines() anaconda - ks.cfgDjango - 1.2 . 7 install.log.syslogptyprocess - 0.5 . 1 server1.py公共的文档 a.pydockermysitepycharm - 2016.3 . 2 server.py模板下载 client1.pydocker - 1.7 . 1 paramiko - 2.1 . 1 pycharm - license.txtsetuptools - 2.0 视频音乐 client.pyinstall.logpexpect - 4.2 . 1 pycrypto - 2.6 . 1 spawn - 0.1 图片桌面 0 >>> 方法 3 :subprocess >>> import subprocess >>>subprocess.call(( 'ls' ),shell = True ) anaconda - ks.cfgDjango - 1.2 . 7 install.log.syslogptyprocess - 0.5 . 1 server1.py公共的文档 a.pydockermysitepycharm - 2016.3 . 2 server.py模板下载 client1.pydocker - 1.7 . 1 paramiko - 2.1 . 1 pycharm - license.txtsetuptools - 2.0 视频音乐 client.pyinstall.logpexpect - 4.2 . 1 pycrypto - 2.6 . 1 spawn - 0.1 图片桌面 0 >>> >>>p = subprocess.Popen( 'ls' ,shell = True ,stdout = subprocess.PIPE,stderr = subprocess.STDOUT) >>>p.stdout.readlines(): [ 'anaconda-ks.cfg\n' , 'a.py\n' , 'client1.py\n' , 'client.py\n' , 'Django-1.2.7\n' , 'docker\n' , 'docker-1.7.1\n' , 'install.log\n' , 'install.log.syslog\n' , 'mysite\n' , 'paramiko-2.1.1\n' , 'pexpect-4.2.1\n' , 'ptyprocess-0.5.1\n' , 'pycharm-2016.3.2\n' , 'pycharm-license.txt\n' , 'pycrypto-2.6.1\n' , 'server1.py\n' , 'server.py\n' , 'setuptools-2.0\n' , 'spawn-0.1\n' , '\xe5\x85\xac\xe5\x85\xb1\xe7\x9a\x84\n' , '\xe6\xa8\xa1\xe6\x9d\xbf\n' , '\xe8\xa7\x86\xe9\xa2\x91\n' , '\xe5\x9b\xbe\xe7\x89\x87\n' , '\xe6\x96\x87\xe6\xa1\xa3\n' , '\xe4\xb8\x8b\xe8\xbd\xbd\n' , '\xe9\x9f\xb3\xe4\xb9\x90\n' , '\xe6\xa1\x8c\xe9\x9d\xa2\n' ] 方法 4 :commands >>> import commands >>>commands.getoutput( 'date' ) >>> '2017\xe5\xb9\xb405\xe6\x9c\x8808\xe6\x97\xa5\xe6\x98\x9f\xe6\x9c\x9f\xe4\xb8\x8018:26:25CST' >>>commands.getstatusoutput( 'date' ) >>>( 0 , '2017\xe5\xb9\xb405\xe6\x9c\x8808\xe6\x97\xa5\xe6\x98\x9f\xe6\x9c\x9f\xe4\xb8\x8018:27:24CST' ) 本文转自 gswljy 51CTO博客,原文链接:http://blog.51cto.com/guoshiwei/1924267

优秀的个人博客,低调大师

MapReduce的数据流程、执行流程

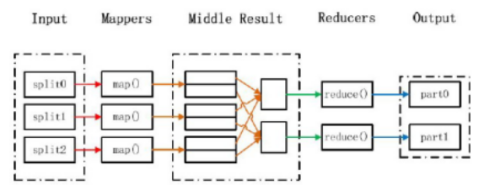
MapReduce的数据流程: 预先加载本地的输入文件 经过MAP处理产生中间结果 经过shuffle程序将相同key的中间结果分发到同一节点上处理 Recude处理产生结果输出 将结果输出保存在hdfs上 MAP 在map阶段,使用job.setInputFormatClass定义的InputFormat将输入的数据集分割成小数据块splites, 同时InputFormat提供一个RecordReder的实现。默认的是TextInputFormat, 他提供的RecordReder会将文本的一行的偏移量作为key,这一行的文本作为value。 这就是自定义Map的输入是<LongWritable, Text>的原因。 然后调用自定义Map的map方法,将一个个<LongWritable, Text>对输入给Map的map方法。 最终是按照自定义的MAP的输出key类,输出class类生成一个List<MapOutputKeyClass, MapOutputValueClass>。 Partitioner 在map阶段的最后,会先调用job.setPartitionerClass设置的类对这个List进行分区, 每个分区映射到一个reducer。每个分区内又调用job.setSortComparatorClass设置的key比较函数类排序。 可以看到,这本身就是一个二次排序。 如果没有通过job.setSortComparatorClass设置key比较函数类,则使用key的实现的compareTo方法。 Shuffle: 将每个分区根据一定的规则,分发到reducer处理 Sort 在reduce阶段,reducer接收到所有映射到这个reducer的map输出后, 也是会调用job.setSortComparatorClass设置的key比较函数类对所有数据对排序。 然后开始构造一个key对应的value迭代器。这时就要用到分组, 使用jobjob.setGroupingComparatorClass设置的分组函数类。只要这个比较器比较的两个key相同, 他们就属于同一个组,它们的value放在一个value迭代器 Reduce最后就是进入Reducer的reduce方法,reduce方法的输入是所有的(key和它的value迭代器)。 同样注意输入与输出的类型必须与自定义的Reducer中声明的一致。 一个更为详细的流程图 具体的例子: 是hadoop mapreduce example中的例子,自己改写了一下并加入的注释 import java.io.DataInput; import java.io.DataOutput; import java.io.IOException; import java.util.StringTokenizer; import org.apache.hadoop.conf.Configuration; import org.apache.hadoop.fs.Path; import org.apache.hadoop.io.IntWritable; import org.apache.hadoop.io.LongWritable; import org.apache.hadoop.io.RawComparator; import org.apache.hadoop.io.Text; import org.apache.hadoop.io.WritableComparable; import org.apache.hadoop.io.WritableComparator; import org.apache.hadoop.mapreduce.lib.input.FileInputFormat; import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat; import org.apache.hadoop.mapreduce.Job; import org.apache.hadoop.mapreduce.Mapper; import org.apache.hadoop.mapreduce.Partitioner; import org.apache.hadoop.mapreduce.Reducer; import org.apache.hadoop.util.GenericOptionsParser; import com.catt.cdh.mr.example.SecondarySort2.FirstPartitioner; import com.catt.cdh.mr.example.SecondarySort2.Reduce; /** * This is an example Hadoop Map/Reduce application. * It reads the text input files that must contain two integers per a line. * The output is sorted by the first and second number and grouped on the * first number. * * To run: bin/hadoop jar build/hadoop-examples.jar secondarysort * <i>in-dir</i> <i>out-dir</i> */ public class SecondarySort { /** * Define a pair of integers that are writable. * They are serialized in a byte comparable format. */ public static class IntPair implements WritableComparable<IntPair> { private int first = 0; private int second = 0; /** * Set the left and right values. */ public void set(int left, int right) { first = left; second = right; } public int getFirst() { return first; } public int getSecond() { return second; } /** * Read the two integers. * Encoded as: MIN_VALUE -> 0, 0 -> -MIN_VALUE, MAX_VALUE-> -1 */ @Override public void readFields(DataInput in) throws IOException { first = in.readInt() + Integer.MIN_VALUE; second = in.readInt() + Integer.MIN_VALUE; } @Override public void write(DataOutput out) throws IOException { out.writeInt(first - Integer.MIN_VALUE); out.writeInt(second - Integer.MIN_VALUE); } @Override // The hashCode() method is used by the HashPartitioner (the default // partitioner in MapReduce) public int hashCode() { return first * 157 + second; } @Override public boolean equals(Object right) { if (right instanceof IntPair) { IntPair r = (IntPair) right; return r.first == first && r.second == second; } else { return false; } } /** A Comparator that compares serialized IntPair. */ public static class Comparator extends WritableComparator { public Comparator() { super(IntPair.class); } // 针对key进行比较,调用多次 public int compare(byte[] b1, int s1, int l1, byte[] b2, int s2, int l2) { return compareBytes(b1, s1, l1, b2, s2, l2); } } static { // 注意:如果不进行注册,则使用key.compareTo方法进行key的比较 // register this comparator WritableComparator.define(IntPair.class, new Comparator()); } // 如果不注册WritableComparator,则使用此方法进行key的比较 @Override public int compareTo(IntPair o) { if (first != o.first) { return first < o.first ? -1 : 1; } else if (second != o.second) { return second < o.second ? -1 : 1; } else { return 0; } } } /** * Partition based on the first part of the pair. */ public static class FirstPartitioner extends Partitioner<IntPair, IntWritable> { @Override public int getPartition(IntPair key, IntWritable value, int numPartitions) { return Math.abs(key.getFirst() * 127) % numPartitions; } } /** * Compare only the first part of the pair, so that reduce is called once * for each value of the first part. */ public static class FirstGroupingComparator implements RawComparator<IntPair> { // 针对key调用,调用多次 @Override public int compare(byte[] b1, int s1, int l1, byte[] b2, int s2, int l2) { return WritableComparator.compareBytes(b1, s1, Integer.SIZE / 8, b2, s2, Integer.SIZE / 8); } // 没有监控到被调用,不知道有什么用 @Override public int compare(IntPair o1, IntPair o2) { int l = o1.getFirst(); int r = o2.getFirst(); return l == r ? 0 : (l < r ? -1 : 1); } } /** * Read two integers from each line and generate a key, value pair * as ((left, right), right). */ public static class MapClass extends Mapper<LongWritable, Text, IntPair, IntWritable> { private final IntPair key = new IntPair(); private final IntWritable value = new IntWritable(); @Override public void map(LongWritable inKey, Text inValue, Context context) throws IOException, InterruptedException { StringTokenizer itr = new StringTokenizer(inValue.toString()); int left = 0; int right = 0; if (itr.hasMoreTokens()) { left = Integer.parseInt(itr.nextToken()); if (itr.hasMoreTokens()) { right = Integer.parseInt(itr.nextToken()); } key.set(left, right); value.set(right); context.write(key, value); } } } /** * A reducer class that just emits the sum of the input values. */ public static class Reduce extends Reducer<IntPair, IntWritable, Text, IntWritable> { private static final Text SEPARATOR = new Text( "------------------------------------------------"); private final Text first = new Text(); @Override public void reduce(IntPair key, Iterable<IntWritable> values, Context context) throws IOException, InterruptedException { context.write(SEPARATOR, null); first.set(Integer.toString(key.getFirst())); for (IntWritable value : values) { context.write(first, value); } } } public static void main(String[] args) throws Exception { Configuration conf = new Configuration(); String[] ars = new String[] { "hdfs://data2.kt:8020/test/input", "hdfs://data2.kt:8020/test/output" }; conf.set("fs.default.name", "hdfs://data2.kt:8020/"); String[] otherArgs = new GenericOptionsParser(conf, ars) .getRemainingArgs(); if (otherArgs.length != 2) { System.err.println("Usage: secondarysort <in> <out>"); System.exit(2); } Job job = new Job(conf, "secondary sort"); job.setJarByClass(SecondarySort.class); job.setMapperClass(MapClass.class); // 不再需要Combiner类型,因为Combiner的输出类型<Text, // IntWritable>对Reduce的输入类型<IntPair, IntWritable>不适用 // job.setCombinerClass(Reduce.class); // Reducer类型 job.setReducerClass(Reduce.class); // 分区函数 job.setPartitionerClass(FirstPartitioner.class); // 设置setSortComparatorClass,在partition后, // 每个分区内又调用job.setSortComparatorClass设置的key比较函数类排序 // 另外,在reducer接收到所有映射到这个reducer的map输出后, // 也是会调用job.setSortComparatorClass设置的key比较函数类对所有数据对排序 // job.setSortComparatorClass(GroupingComparator2.class); // 分组函数 job.setGroupingComparatorClass(FirstGroupingComparator.class); // the map output is IntPair, IntWritable // 针对自定义的类型,需要指定MapOutputKeyClass job.setMapOutputKeyClass(IntPair.class); // job.setMapOutputValueClass(IntWritable.class); // the reduce output is Text, IntWritable job.setOutputKeyClass(Text.class); job.setOutputValueClass(IntWritable.class); FileInputFormat.addInputPath(job, new Path(otherArgs[0])); FileOutputFormat.setOutputPath(job, new Path(otherArgs[1])); System.exit(job.waitForCompletion(true) ? 0 : 1); } }

资源下载

更多资源
腾讯云软件源

腾讯云软件源

为解决软件依赖安装时官方源访问速度慢的问题,腾讯云为一些软件搭建了缓存服务。您可以通过使用腾讯云软件源站来提升依赖包的安装速度。为了方便用户自由搭建服务架构,目前腾讯云软件源站支持公网访问和内网访问。

Nacos

Nacos

Nacos /nɑ:kəʊs/ 是 Dynamic Naming and Configuration Service 的首字母简称,一个易于构建 AI Agent 应用的动态服务发现、配置管理和AI智能体管理平台。Nacos 致力于帮助您发现、配置和管理微服务及AI智能体应用。Nacos 提供了一组简单易用的特性集,帮助您快速实现动态服务发现、服务配置、服务元数据、流量管理。Nacos 帮助您更敏捷和容易地构建、交付和管理微服务平台。

Sublime Text

Sublime Text

Sublime Text具有漂亮的用户界面和强大的功能,例如代码缩略图,Python的插件,代码段等。还可自定义键绑定,菜单和工具栏。Sublime Text 的主要功能包括:拼写检查,书签,完整的 Python API , Goto 功能,即时项目切换,多选择,多窗口等等。Sublime Text 是一个跨平台的编辑器,同时支持Windows、Linux、Mac OS X等操作系统。

WebStorm

WebStorm

WebStorm 是jetbrains公司旗下一款JavaScript 开发工具。目前已经被广大中国JS开发者誉为“Web前端开发神器”、“最强大的HTML5编辑器”、“最智能的JavaScript IDE”等。与IntelliJ IDEA同源,继承了IntelliJ IDEA强大的JS部分的功能。

用户登录
用户注册