首页 文章 精选 留言 我的

精选列表

搜索[个人博客],共10000篇文章
优秀的个人博客,低调大师

[python作业AI毕业设计博客]人工智能医疗新书下载: Machine Learning and AI for Healthcare ...

下载地址:https://itbooks.pipipan.com/fs/18113597-335448646 探索人工智能(AI)和医疗机器学习的理论和实际应用。本书提供了机器学习算法,架构设计以及医疗保健和大数据挑战中学习应用的导览。 您将发现医疗保健数据分析的道德含义以及AI在人口和患者健康优化方面的未来。您还将创建机器学习模型,评估绩效并在组织内实施结果。 机器学习和医疗保健人工智能提供了如何在组织内应用机器学习并评估AI应用程序的功效,适用性和效率的技术。通过主要案例研究说明了这些,包括如何通过患者主导的数据学习和物联网重新定义慢性病。 你将学到什么 深入了解关键机器学习算法及其在更广泛的医疗保健中的使用和实施 实施机器学习系统,例如语音识别和增强的深度学习/ AI 选择学习方法/算法和调整以用于医疗保健 通过最佳实践,反馈循环和智能代理

优秀的个人博客,低调大师

[雪峰磁针石博客]python网络作业:使用python的socket库实现ICMP协议的ping

ICMP ping是您遇到过的最常见的网络扫描类型。 打开命令行提示符或终端并输入ping www.google.com非常容易。 为什么要在python中实现? 很多名牌大学喜欢考试用python的socket库实现ICMP协议的ping 个别环境没有ping 直接上代码: #!/usr/bin/python3 # -*- coding: utf-8 -*- # 技术支持:https://www.jianshu.com/u/69f40328d4f0 # 技术支持 https://china-testing.github.io/ # https://github.com/china-testing/python-api-tesing/blob/master/practices/ping.py # 讨论钉钉免费群21745728 qq群144081101 567351477 # CreateDate: 2018-11-22 import os import argparse import socket import struct import select import time ICMP_ECHO_REQUEST = 8 # Platform specific DEFAULT_TIMEOUT = 2 DEFAULT_COUNT = 4 class Pinger(object): """ Pings to a host -- the Pythonic way""" def __init__(self, target_host, count=DEFAULT_COUNT, timeout=DEFAULT_TIMEOUT): self.target_host = target_host self.count = count self.timeout = timeout def do_checksum(self, source_string): """ Verify the packet integritity """ sum = 0 max_count = (len(source_string)/2)*2 count = 0 while count < max_count: val = source_string[count + 1]*256 + source_string[count] sum = sum + val sum = sum & 0xffffffff count = count + 2 if max_count<len(source_string): sum = sum + ord(source_string[len(source_string) - 1]) sum = sum & 0xffffffff sum = (sum >> 16) + (sum & 0xffff) sum = sum + (sum >> 16) answer = ~sum answer = answer & 0xffff answer = answer >> 8 | (answer << 8 & 0xff00) return answer def receive_pong(self, sock, ID, timeout): """ Receive ping from the socket. """ time_remaining = timeout while True: start_time = time.time() readable = select.select([sock], [], [], time_remaining) time_spent = (time.time() - start_time) if readable[0] == []: # Timeout return time_received = time.time() recv_packet, addr = sock.recvfrom(1024) icmp_header = recv_packet[20:28] type, code, checksum, packet_ID, sequence = struct.unpack( "bbHHh", icmp_header ) if packet_ID == ID: bytes_In_double = struct.calcsize("d") time_sent = struct.unpack("d", recv_packet[28:28 + bytes_In_double])[0] return time_received - time_sent time_remaining = time_remaining - time_spent if time_remaining <= 0: return def send_ping(self, sock, ID): """ Send ping to the target host """ target_addr = socket.gethostbyname(self.target_host) my_checksum = 0 # Create a dummy heder with a 0 checksum. header = struct.pack("bbHHh", ICMP_ECHO_REQUEST, 0, my_checksum, ID, 1) bytes_In_double = struct.calcsize("d") data = (192 - bytes_In_double) * "Q" data = struct.pack("d", time.time()) + bytes(data.encode('utf-8')) # Get the checksum on the data and the dummy header. my_checksum = self.do_checksum(header + data) header = struct.pack( "bbHHh", ICMP_ECHO_REQUEST, 0, socket.htons(my_checksum), ID, 1 ) packet = header + data sock.sendto(packet, (target_addr, 1)) def ping_once(self): """ Returns the delay (in seconds) or none on timeout. """ icmp = socket.getprotobyname("icmp") try: sock = socket.socket(socket.AF_INET, socket.SOCK_RAW, icmp) except socket.error as e: if e.errno == 1: # Not superuser, so operation not permitted e.msg += "ICMP messages can only be sent from root user processes" raise socket.error(e.msg) except Exception as e: print ("Exception: %s" %(e)) my_ID = os.getpid() & 0xFFFF self.send_ping(sock, my_ID) delay = self.receive_pong(sock, my_ID, self.timeout) sock.close() return delay def ping(self): """ Run the ping process """ for i in range(self.count): print ("Ping to %s..." % self.target_host,) try: delay = self.ping_once() except socket.gaierror as e: print ("Ping failed. (socket error: '%s')" % e[1]) break if delay == None: print ("Ping failed. (timeout within %ssec.)" % self.timeout) else: delay = delay * 1000 print ("Get pong in %0.4fms" % delay) if __name__ == '__main__': parser = argparse.ArgumentParser(description='Python ping') parser.add_argument('host', action="store", help=u'主机名') given_args = parser.parse_args() target_host = given_args.host pinger = Pinger(target_host=target_host) pinger.ping() 参考资料 本文最新版本地址 讨论 钉钉群21745728 qq群144081101 567351477 本文涉及的python测试开发库 谢谢点赞! 本文相关海量书籍下载 python 3.7极速入门教程9最佳python中文工具书籍下载 最新代码地址 执行 注意要有root或管理员权限: # python3 ping.py china-testing.github.io Ping to china-testing.github.io... Get pong in 160.7175ms Ping to china-testing.github.io... Get pong in 160.8465ms Ping to china-testing.github.io... Get pong in 12.0983ms Ping to china-testing.github.io... Get pong in 161.3324ms # python3 ping.py www.so.com Ping to www.so.com... Get pong in 29.0303ms Ping to www.so.com... Get pong in 28.8599ms Ping to www.so.com... Get pong in 28.9860ms Ping to www.so.com... Get pong in 29.0167ms

优秀的个人博客,低调大师

[雪峰磁针石博客]web开发工具flask中文英文书籍下载-持续更新

Flask Web Development 2nd - 2018.pdf 中文版: Flask Web开发 基于Python的Web应用开发实战 第2版 强烈推荐: https://github.com/miguelgrinberg/flasky 星级 5000多 这本书比较基础,入门是可以的,但是难以成大器,配合下面这本书就完美了。另外Flask Building Python Web Services - 2017.pdf也是不错的参考。 The New And Improved Flask - 2018.pdf 推荐 https://github.com/miguelgrinberg/microblog 星级 2000 左右 深入理解Flask - 2016.pdf Flask 是在Python 用户中最为流行的Web 开发框架。《深入理解 Flask》从一个简单的Flask 项目入手,由浅入深地探讨了一系列实战问题,包括如何使用SQLAlchemy 和Jinja 等工具进行Web 开发;如何正确地设计扩展性强的Flask 应用架构和搭建MVC 环境;对于各种NoSQL 数据库的特性,何时应该、何时不应该及如何使用它们;通过使用Flask 扩展快速实现用户的身份系统、RESTful API、NoSQL查询、后台管理等功能;如何创建自己的扩展;使用Celery 编写异步任务,使用pytest 进行单元测试等;最后介绍了如何部署上线,包括使用自己搭建的服务器或使用各种云服务,以及如何权衡和选择这些不同的解决方案。 英文版本:Mastering Flask - 2015.pdf Python高效开发实战Django、Tornado、Flask、Twisted - 2016.pdf Learning Flask Framework - 2015.pdf Instant Flask Web Development - 2013.pdf head first flask - 2016.pdf Flask Building Python Web Services - 2017.pdf Flask Blueprints - 2015.pdf Building Web Applications with Flask - 2015.pdf Flask Web开发实战:入门、进阶与原理解析 https://github.com/greyli/helloflask 更多flask及python web开发新书:https://itbooks.pipipan.com/dir/18113597-29505146-756dbb/ 参考资料 讨论qq群144081101 591302926 567351477 钉钉免费群21745728 本文最新版本地址 本文涉及的python测试开发库 谢谢点赞! 本文相关海量书籍下载

优秀的个人博客,低调大师

[雪峰磁针石博客]2018最佳人工智能图像处理工具OpenCV书籍下载

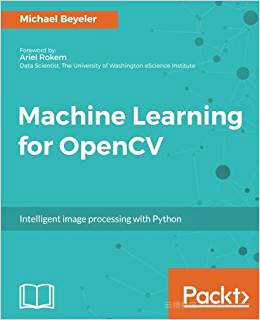
@Machine Learning for OpenCV - 2017.pdf A practical introduction to the world of machine learning and image processing usingOpenCV and Python 使用OpenCV和Python对机器学习和图像处理世界的实用介绍 机器学习不再仅仅是一个流行语,它就在我们身边:从保护您的电子邮件到自动标记图片中的朋友,到预测您喜欢的电影。计算机视觉是当今最令人兴奋的机器学习应用领域之一,深度学习驱动创新系统,如自动驾驶汽车和谷歌的DeepMind。 OpenCV位于这些主题的交叉点,为经典以及最先进的计算机视觉和机器学习算法提供了一个全面的开源库。结合Python Anaconda,您可以访问您可能要求的所有开源计算库。 OpenCV的机器学习首先向您介绍统计学习的基本概念,例如分类和回归。一旦涵盖了所有基础知识,您将开始探索各种算法,如决策树,支持向量机和贝叶斯网络,并学习如何将它们与其他OpenCV功能相结合。随着本书的进展,您的机器学习技能也将如此,直到您准备好接受当今最热门的话题:深度学习。 在本书的最后,您将准备好通过构建现有的源代码或从头开发自己的算法来解决您自己的机器学习问题! https://github.com/mbeyeler/opencv-machine-learning 400左右 讨论钉钉免费群21745728 qq群144081101567351477 Learning OpenCV 3 - 2017.pdf 计算机视觉是在图像处理的基础上发展起来的新兴学科。OpenCV是一个开源的计算机视觉库,是英特尔公司资助的两大图像处理利器之一。它为图像处理、模式识别、三维重建、物体跟踪、机器学习和线性代数提供了各种各样的算法。 《学习OpenCV 3(中文版)》由OpenCV发起人所写,站在一线开发人员的角度用通俗易懂的语言解释了OpenCV的缘起和计算机视觉基础结构,演示了如何用OpenCV和现有的自由代码为各种各样的机器进行编程,这些都有助于读者迅速入门并渐入佳境,兴趣盎然地深入探索计算机视觉领域。 《学习OpenCV 3(中文版)》可作为信息处理、计算机、机器人、人工智能、遥感图像处理、认知神经科学等有关专业的高年级学生或研究生的教学用书,也可供相关领域的研究工作者参考。 https://github.com/oreillymedia/Learning-OpenCV-3_examples 500左右 @OpenCV 3.x with Python By Example 2nd 2018.pdf Make the most of OpenCV and Python to build applications for object recognition and augmented reality 充分利用OpenCV和Python来构建对象识别和增强现实的应用程序 计算机视觉在现代技术中随处可见。 OpenCV for Python使我们能够实时运行计算机视觉算法。随着强大机器的出现,我们拥有更多处理能力。使用这项技术,我们可以将计算机视觉应用程序无缝集成到云中。本书着重于OpenCV 3.x和Python 3.6,将指导您轻松构建出色的计算机视觉应用程序。 我们首先使用简单的过滤和几何变换来操纵图像。然后我们讨论仿射和投影转换,看看我们如何使用它们对照片应用很酷的高级操作,例如调整它们的大小,同时保持内容完整或平滑地删除不需要的元素。然后,我们将使用先进的机器学习技术(如人工神经网络)来介绍对象跟踪,身体部位识别和对象识别等技术。还包括3D重建和增强现实技术。本书借助示例介绍了流行的OpenCV库。 本书是一本实用的教程,涵盖了不同层面的各种示例,教您OpenCV的不同功能及其实际实现。到本书结束时,您将掌握使用OpenCV和Python开发真实计算机视觉应用程序的技能。 https://github.com/PacktPublishing/OpenCV-3-x-with-Python-By-Example 50左右 中文版 OpenCV 3 Computer Vision with Python Cookbook - 2018.pdf OpenCV 3是一个用于计算机视觉,机器学习和图像处理的本地跨平台库。 OpenCV方便的高级API隐藏了非常强大的内部设计,旨在提高计算效率,可以利用多核和GPU处理。本书将通过提供一些可用于改进应用程序的配方,帮助您解决日益严峻的计算机视觉问题。 在本书中,您将学习如何通过操纵像素和使用直方图分析图像来处理图像。然后,我们将向您展示如何应用图像过滤器来增强图像内容并利用图像几何图形来传递图像场景的不同视图。我们将探索实现相机校准和执行多视图分析的技术。 稍后,您将致力于从图像重建3D场景,将低级像素信息转换为高级概念,以用于对象检测和识别等应用。您还将了解如何处理文件或摄像机中的视频以及如何检测和跟踪移动的对象。最后,您将了解深度学习和神经网络的最新方法。 在本书的最后,您将能够在OpenCV中应用您的技能,在各个领域创建计算机视觉应用程序。 https://github.com/PacktPublishing/OpenCV-3-Computer-Vision-with-Python-Cookbook 50左右 中文版 Computer Vision with OpenCV 3 and Qt5 - 2018.pdf Build visually appealing, multithreaded, cross-platform computer vision applications 构建视觉上吸引人的,多线程,跨平台的计算机视觉应用程序 开发人员长期以来一直使用OpenCV库来开发计算机视觉应用程序。但是,他们现在需要一种更有效的工具来完成工作并以更好,更现代的方式完成工作。 Qt是目前可用于此任务的主要框架之一。 本书将教您如何使用OpenCV 3和Qt5的组合开发应用程序,以及如何创建跨平台的计算机视觉应用程序。我们将首先介绍Qt,它的IDE和它的SDK。接下来,您将学习如何使用OpenCV API集成这两个工具,并了解如何配置Qt以使用OpenCV。您将在本书中继续构建完整的计算机视觉应用程序。 稍后,您将使用Qt小部件技术创建令人惊叹的UI应用程序,在这些技术中,您将以有效的方式处理图像。在本书的最后,您将学习如何将OpenCV Mat转换为Qt QImage。您还将了解如何有效地处理图像以过滤图像,转换图像,检测或跟踪对象以及分析视频。您将更好地开发OpenCV应用程序。 https://github.com/PacktPublishing/Computer-Vision-with-OpenCV-3-and-Qt5 100左右 Mastering OpenCV 3 2nd - 2017.pdf 随着我们越来越有能力处理各种数据,我们越来越依赖视觉输入,以及我们可以用自动驾驶汽车,人脸识别,甚至增强现实应用和游戏做些什么。 这完全由计算机视觉提供支持。 本书将帮助您直接创建功能强大且独特的计算机视觉应用程序。 每章都围绕一个中心项目构建,深入探讨OpenCV的一个重要方面,如面部识别,图像目标跟踪,制作增强现实应用,3D可视化框架和机器学习。 您将学习如何使AI能够记住并使用神经网络来帮助您的应用程序学习。 在本书的最后,您将使用本书中的项目创建各种工作原型,并将精通OpenCV3的新功能。 https://github.com/PacktPublishing/Mastering-OpenCV3-Second-Edition 50左右 Packt.OpenCV.3.Computer.Vision.Application.Programming.Cookbook.3rd.Edition.2017.pdf https://github.com/PacktPublishing/OpenCV3-Computer-Vision-Application-Programming-Cookbook-Third-Edition 50左右 Java Image Processing Recipes With OpenCV and JVM - 2018.pdf 快速获取常见Java图像处理问题的解决方案,学习最佳实践,并了解OpenCV为图像处理提供的所有功能。 您将使用JVM图像包装器,以便通过管道运行图像转换并获得即时视觉反馈非常容易。 本书大量使用Gorilla环境,可以在浏览器中直接执行代码,图像转换结果也可以直接在浏览器中显示。 Java图像处理配方包括更先进的图像处理技术的配方,例如图像平滑,卡通,草图绘制和母版蒙版,以仅将更改应用于图像的某些部分。 您将看到OpenCV功能如何为边缘检测和形状查找等问题提供即时解决方案。 最后,本书包含处理网络摄像头和各种视频流的实用方法,为您提供现成的代码,用于进行实时视频分析。 https://github.com/Apress/java-image-processing-recipes <10 Pro Processing for Images and Computer Vision with OpenCV - 2017.pdf Solutions for Media Artists and Creative Coders 媒体艺术家和创意编码器的解决方案 华人写得书。 将处理语言应用于计算机视觉中涉及的任务 - 诸如边缘和角落检测,视频中帧之间的运动识别,对象的识别,特征点的匹配以及用于跟踪目的的不同帧中的形状等任务等。您将通过创意效果,几何变换,多个图像的混合等操纵图像。提供了示例。 使用OpenCV进行图像和计算机视觉的专业处理是一个循序渐进的培训工具,它以线性顺序指导您完成一系列工作示例。每章都以基本演示开始,包括在您自己的系统上重新创建它的代码。然后是一个创造性的挑战,通过它来吸引和发展对章节主题的掌握。该书还包括有关视觉艺术,交互设计和行业最佳实践的提示和技巧。 本书适用于任何艺术和其他视觉应用的开发人员,例如增强现实和数字效果,需要操纵图像,以及识别和操纵这些图像中的对象。本书专门针对那些使用艺术领域常见的Processing语言的人,以及Java程序员,因为Processing易于集成到Java编程环境中。 https://github.com/Apress/pro-processing-images-and-computer-vision-opencv <10 参考资料 讨论qq群144081101 591302926 567351477 钉钉群21745728 本文最新版本地址 本文涉及的python测试开发库 谢谢点赞! 本文相关海量书籍下载

优秀的个人博客,低调大师

[雪峰磁针石博客]2018最佳人工智能数据采集(爬虫)工具书下载

Python网络数据采集 Python网络数据采集 - 2016.pdf 本书采用简洁强大的Python语言,介绍了网络数据采集,并为采集新式网络中的各种数据类型提供了全面的指导。第 1部分重点介绍网络数据采集的基本原理:如何用Python从网络服务器请求信息,如何对服务器的响应进行基本处理,以及如何以自动化手段与网站进行交互。第 二部分介绍如何用网络爬虫测试网站,自动化处理,以及如何通过更多的方式接入网络。 Web Scraping with Python 2nd - 2018.pdf https://github.com/REMitchell/python-scraping 2000左右星 精通Python爬虫框架Scrapy Scrapy是使用Python开发的一个快速、高层次的屏幕抓取和Web抓取框架,用于抓Web站点并从页面中提取结构化的数据。《精通Python爬虫框架Scrapy》以Scrapy 1.0版本为基础,讲解了Scrapy的基础知识,以及如何使用Python和三方API提取、整理数据,以满足自己的需求。 本书共11章,其内容涵盖了Scrapy基础知识,理解HTML和XPath,安装Scrapy并爬取一个网站,使用爬虫填充数据库并输出到移动应用中,爬虫的强大功能,将爬虫部署到Scrapinghub云服务器,Scrapy的配置与管理,Scrapy编程,管道秘诀,理解Scrapy性能,使用Scrapyd与实时分析进行分布式爬取。本书附录还提供了各种软件的安装与故障排除等内容。本书适合软件开发人员、数据科学家,以及对自然语言处理和机器学习感兴趣的人阅读。 源码 github星级 300左右 Learning Scrapy -2016.pdf 另有中文电子版本 因为版权已经在CSDN等网站下架,可以在qq群144081101等找到。 python3爬虫基础 在线教程 https://github.com/MorvanZhou/easy-scraping-tutorial 200 左右星 First web scraper 教程:https://first-web-scraper.readthedocs.io/en/latest/ https://github.com/ireapps/first-web-scraper/blob/master/docs/index.rst 200 左右星 Practical Web Scraping for Data Science -Best Practices and Examples with Python - 2018.pdf https://github.com/Apress/practical-web-scraping-for-data-science 星级 低于100 This book provides a complete and modern guide to web scraping, using Python as the programming language, without glossing over important details or best practices. Written with a data science audience in mind, the book explores both scraping and the larger context of web technologies in which it operates, to ensure full understanding. The authors recommend web scraping as a powerful tool for any data scientist’s arsenal, as many data science projects start by obtaining an appropriate data set. Starting with a brief overview on scraping and real-life use cases, the authors explore the core concepts of HTTP, HTML, and CSS to provide a solid foundation. Along with a quick Python primer, they cover Selenium for JavaScript-heavy sites, and web crawling in detail. The book finishes with a recap of best practices and a collection of examples that bring together everything you've learned and illustrate various data science use cases. 用Python写网络爬虫 第2版 《用Python写网络爬虫(第 2版》讲解了如何使用Python来编写网络爬虫程序,内容包括网络爬虫简介,从页面中抓取数据的3种方法,提取缓存中的数据,使用多个线程和进程进行并发抓取,抓取动态页面中的内容,与表单进行交互,处理页面中的验证码问题,以及使用Scarpy和Portia进行数据抓取,并在最后介绍了使用本书讲解的数据抓取技术对几个真实的网站进行抓取的实例,旨在帮助读者活学活用书中介绍的技术。 《用Python写网络爬虫(第 2版》适合有一定Python编程经验而且对爬虫技术感兴趣的读者阅读。 Python Web Scraping 2nd Edition - 2017.pdf 第一版中文 用Python写网络爬虫.pdf https://github.com/kjam/wswp < 100星 Python Web Scraping Cookbook - 2018.pdf 下载 Python Web Scraping Cookbook is a solution-focused book that will teach you techniques to develop high-performance Scrapers, and deal with cookies, hidden form fields, Ajax-based sites and proxies. You'll explore a number of real-world scenarios where every part of the development or product life cycle will be fully covered. You will not only develop the skills to design reliable, high-performing data flows, but also deploy your codebase to Amazon Web Services (AWS). If you are involved in software engineering, product development, or data mining or in building data-driven products, you will find this book useful as each recipe has a clear purpose and objective. Right from extracting data from websites to writing a sophisticated web crawler, the book's independent recipes will be extremely helpful while on the job. This book covers Python libraries, requests, and BeautifulSoup. You will learn about crawling, web spidering, working with AJAX websites, and paginated items. You will also understand to tackle problems such as 403 errors, working with proxy, scraping images, and LXML. By the end of this book, you will be able to scrape websites more efficiently and deploy and operate your scraper in the cloud. https://github.com/PacktPublishing/Python-Web-Scraping-Cookbook < 100星 参考资料 https://github.com/lorien/awesome-web-scraping/blob/master/python.md 最好用的Python爬虫推荐 https://www.jianshu.com/p/7da43c16dd87 https://www.zhihu.com/question/41277528

优秀的个人博客,低调大师

[雪峰磁针石博客]数据分析工具pandas快速入门教程4-数据汇聚

我们需要的所有信息可能记录在单独的文件和数据帧中。例如,可能有一个公司信息单独表和股票价格表,数据被分成独立的表格以减少冗余信息。 连接 添加行 4-1.py import pandas as pd df1 = pd.read_csv('data/concat_1.csv') df2 = pd.read_csv('data/concat_2.csv') df3 = pd.read_csv('data/concat_3.csv') print(df1) print(df2) print(df3) row_concat = pd.concat([df1, df2, df3]) print(row_concat) print(row_concat.iloc[3, ]) new_row_series = pd.Series(['n1', 'n2', 'n3', 'n4']) print(pd.concat([df1, new_row_series])) new_row_df = pd.DataFrame([['n1', 'n2', 'n3', 'n4']], columns=['A', 'B', 'C', 'D']) print(new_row_df) print(pd.concat([df1, new_row_df])) print(df1.append(df2)) print(df1.append(new_row_df)) data_dict = {'A': 'n1', 'B': 'n2', 'C': 'n3', 'D': 'n4'} print(df1.append(data_dict, ignore_index=True)) row_concat_i = pd.concat([df1, df2, df3], ignore_index=True) print(row_concat_i) 执行结果 $ python3 4-1.py A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 A B C D 0 a4 b4 c4 d4 1 a5 b5 c5 d5 2 a6 b6 c6 d6 3 a7 b7 c7 d7 A B C D 0 a8 b8 c8 d8 1 a9 b9 c9 d9 2 a10 b10 c10 d10 3 a11 b11 c11 d11 A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 0 a4 b4 c4 d4 1 a5 b5 c5 d5 2 a6 b6 c6 d6 3 a7 b7 c7 d7 0 a8 b8 c8 d8 1 a9 b9 c9 d9 2 a10 b10 c10 d10 3 a11 b11 c11 d11 A a3 B b3 C c3 D d3 Name: 3, dtype: object A B C D 0 0 a0 b0 c0 d0 NaN 1 a1 b1 c1 d1 NaN 2 a2 b2 c2 d2 NaN 3 a3 b3 c3 d3 NaN 0 NaN NaN NaN NaN n1 1 NaN NaN NaN NaN n2 2 NaN NaN NaN NaN n3 3 NaN NaN NaN NaN n4 A B C D 0 n1 n2 n3 n4 A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 0 n1 n2 n3 n4 A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 0 a4 b4 c4 d4 1 a5 b5 c5 d5 2 a6 b6 c6 d6 3 a7 b7 c7 d7 A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 0 n1 n2 n3 n4 A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 4 n1 n2 n3 n4 A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 4 a4 b4 c4 d4 5 a5 b5 c5 d5 6 a6 b6 c6 d6 7 a7 b7 c7 d7 8 a8 b8 c8 d8 9 a9 b9 c9 d9 10 a10 b10 c10 d10 11 a11 b11 c11 d11 添加列 4-2.py In [1]: from numpy import NaN, NAN, nan In [2]: print(NaN == True, NaN == False, NaN == 0, NaN == '', sep='|') False|False|False|False In [3]: print(NaN == NaN, NaN == nan, NaN == NAN, nan == NAN, sep='|') False|False|False|False In [4]: import pandas as pd In [5]: print(pd.isnull(NaN), pd.isnull(nan), pd.isnull(NAN), sep='|') True|True|True In [6]: print(pd.notnull(NaN), pd.notnull(99), pd.notnull("https://china-testing.github.io"), sep='|') False|True|True 执行结果 $ python3 4-2.py A B C D A B C D A B C D 0 a0 b0 c0 d0 a4 b4 c4 d4 a8 b8 c8 d8 1 a1 b1 c1 d1 a5 b5 c5 d5 a9 b9 c9 d9 2 a2 b2 c2 d2 a6 b6 c6 d6 a10 b10 c10 d10 3 a3 b3 c3 d3 a7 b7 c7 d7 a11 b11 c11 d11 A A A 0 a0 a4 a8 1 a1 a5 a9 2 a2 a6 a10 3 a3 a7 a11 A B C D A B C D A B C D new_col_list 0 a0 b0 c0 d0 a4 b4 c4 d4 a8 b8 c8 d8 n1 1 a1 b1 c1 d1 a5 b5 c5 d5 a9 b9 c9 d9 n2 2 a2 b2 c2 d2 a6 b6 c6 d6 a10 b10 c10 d10 n3 3 a3 b3 c3 d3 a7 b7 c7 d7 a11 b11 c11 d11 n4 A B C D A B C D A B C D new_col_list \ 0 a0 b0 c0 d0 a4 b4 c4 d4 a8 b8 c8 d8 n1 1 a1 b1 c1 d1 a5 b5 c5 d5 a9 b9 c9 d9 n2 2 a2 b2 c2 d2 a6 b6 c6 d6 a10 b10 c10 d10 n3 3 a3 b3 c3 d3 a7 b7 c7 d7 a11 b11 c11 d11 n4 new_col_series 0 n1 1 n2 2 n3 3 n4 0 1 2 3 4 5 6 7 8 9 10 11 0 a0 b0 c0 d0 a4 b4 c4 d4 a8 b8 c8 d8 1 a1 b1 c1 d1 a5 b5 c5 d5 a9 b9 c9 d9 2 a2 b2 c2 d2 a6 b6 c6 d6 a10 b10 c10 d10 3 a3 b3 c3 d3 a7 b7 c7 d7 a11 b11 c11 d11 合并不同区间 4-3.py import pandas as pd df1 = pd.read_csv('data/concat_1.csv') df2 = pd.read_csv('data/concat_2.csv') df3 = pd.read_csv('data/concat_3.csv') df1.columns = ['A', 'B', 'C', 'D'] df2.columns = ['E', 'F', 'G', 'H'] df3.columns = ['A', 'C', 'F', 'H'] print(df1) print(df2) print(df3) row_concat = pd.concat([df1, df2, df3]) print(row_concat) print(pd.concat([df1, df2, df3], join='inner')) print(pd.concat([df1,df3], ignore_index=False, join='inner')) df1.index = [0, 1, 2, 3] df2.index = [4, 5, 6, 7] df3.index = [0, 2, 5, 7] print(df1) print(df2) print(df3) col_concat = pd.concat([df1, df2, df3], axis=1) print(col_concat) print(pd.concat([df1, df3], axis=1, join='inner')) 执行结果 $ python3 4-3.py A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 E F G H 0 a4 b4 c4 d4 1 a5 b5 c5 d5 2 a6 b6 c6 d6 3 a7 b7 c7 d7 A C F H 0 a8 b8 c8 d8 1 a9 b9 c9 d9 2 a10 b10 c10 d10 3 a11 b11 c11 d11 A B C D E F G H 0 a0 b0 c0 d0 NaN NaN NaN NaN 1 a1 b1 c1 d1 NaN NaN NaN NaN 2 a2 b2 c2 d2 NaN NaN NaN NaN 3 a3 b3 c3 d3 NaN NaN NaN NaN 0 NaN NaN NaN NaN a4 b4 c4 d4 1 NaN NaN NaN NaN a5 b5 c5 d5 2 NaN NaN NaN NaN a6 b6 c6 d6 3 NaN NaN NaN NaN a7 b7 c7 d7 0 a8 NaN b8 NaN NaN c8 NaN d8 1 a9 NaN b9 NaN NaN c9 NaN d9 2 a10 NaN b10 NaN NaN c10 NaN d10 3 a11 NaN b11 NaN NaN c11 NaN d11 Empty DataFrame Columns: [] Index: [0, 1, 2, 3, 0, 1, 2, 3, 0, 1, 2, 3] A C 0 a0 c0 1 a1 c1 2 a2 c2 3 a3 c3 0 a8 b8 1 a9 b9 2 a10 b10 3 a11 b11 A B C D 0 a0 b0 c0 d0 1 a1 b1 c1 d1 2 a2 b2 c2 d2 3 a3 b3 c3 d3 E F G H 4 a4 b4 c4 d4 5 a5 b5 c5 d5 6 a6 b6 c6 d6 7 a7 b7 c7 d7 A C F H 0 a8 b8 c8 d8 2 a9 b9 c9 d9 5 a10 b10 c10 d10 7 a11 b11 c11 d11 A B C D E F G H A C F H 0 a0 b0 c0 d0 NaN NaN NaN NaN a8 b8 c8 d8 1 a1 b1 c1 d1 NaN NaN NaN NaN NaN NaN NaN NaN 2 a2 b2 c2 d2 NaN NaN NaN NaN a9 b9 c9 d9 3 a3 b3 c3 d3 NaN NaN NaN NaN NaN NaN NaN NaN 4 NaN NaN NaN NaN a4 b4 c4 d4 NaN NaN NaN NaN 5 NaN NaN NaN NaN a5 b5 c5 d5 a10 b10 c10 d10 6 NaN NaN NaN NaN a6 b6 c6 d6 NaN NaN NaN NaN 7 NaN NaN NaN NaN a7 b7 c7 d7 a11 b11 c11 d11 A B C D A C F H 0 a0 b0 c0 d0 a8 b8 c8 d8 2 a2 b2 c2 d2 a9 b9 c9 d9 合并多个数据集 4-4.py import pandas as pd person = pd.read_csv('data/survey_person.csv') site = pd.read_csv('data/survey_site.csv') survey = pd.read_csv('data/survey_survey.csv') visited = pd.read_csv('data/survey_visited.csv') print(person) print(site) print(survey) print(visited) visited_subset = visited.iloc[[0, 2, 6], ] o2o_merge = site.merge(visited_subset, left_on='name', right_on='site') print(o2o_merge) m2o_merge = site.merge(visited, left_on='name', right_on='site') print(m2o_merge) ps = person.merge(survey, left_on='ident', right_on='person') vs = visited.merge(survey, left_on='ident', right_on='taken') print(ps) print(vs) 执行结果 $ python3 4-4.py ident personal family 0 dyer William Dyer 1 pb Frank Pabodie 2 lake Anderson Lake 3 roe Valentina Roerich 4 danforth Frank Danforth name lat long 0 DR-1 -49.85 -128.57 1 DR-3 -47.15 -126.72 2 MSK-4 -48.87 -123.40 taken person quant reading 0 619 dyer rad 9.82 1 619 dyer sal 0.13 2 622 dyer rad 7.80 3 622 dyer sal 0.09 4 734 pb rad 8.41 5 734 lake sal 0.05 6 734 pb temp -21.50 7 735 pb rad 7.22 8 735 NaN sal 0.06 9 735 NaN temp -26.00 10 751 pb rad 4.35 11 751 pb temp -18.50 12 751 lake sal 0.10 13 752 lake rad 2.19 14 752 lake sal 0.09 15 752 lake temp -16.00 16 752 roe sal 41.60 17 837 lake rad 1.46 18 837 lake sal 0.21 19 837 roe sal 22.50 20 844 roe rad 11.25 ident site dated 0 619 DR-1 1927-02-08 1 622 DR-1 1927-02-10 2 734 DR-3 1939-01-07 3 735 DR-3 1930-01-12 4 751 DR-3 1930-02-26 5 752 DR-3 NaN 6 837 MSK-4 1932-01-14 7 844 DR-1 1932-03-22 name lat long ident site dated 0 DR-1 -49.85 -128.57 619 DR-1 1927-02-08 1 DR-3 -47.15 -126.72 734 DR-3 1939-01-07 2 MSK-4 -48.87 -123.40 837 MSK-4 1932-01-14 name lat long ident site dated 0 DR-1 -49.85 -128.57 619 DR-1 1927-02-08 1 DR-1 -49.85 -128.57 622 DR-1 1927-02-10 2 DR-1 -49.85 -128.57 844 DR-1 1932-03-22 3 DR-3 -47.15 -126.72 734 DR-3 1939-01-07 4 DR-3 -47.15 -126.72 735 DR-3 1930-01-12 5 DR-3 -47.15 -126.72 751 DR-3 1930-02-26 6 DR-3 -47.15 -126.72 752 DR-3 NaN 7 MSK-4 -48.87 -123.40 837 MSK-4 1932-01-14 ident personal family taken person quant reading 0 dyer William Dyer 619 dyer rad 9.82 1 dyer William Dyer 619 dyer sal 0.13 2 dyer William Dyer 622 dyer rad 7.80 3 dyer William Dyer 622 dyer sal 0.09 4 pb Frank Pabodie 734 pb rad 8.41 5 pb Frank Pabodie 734 pb temp -21.50 6 pb Frank Pabodie 735 pb rad 7.22 7 pb Frank Pabodie 751 pb rad 4.35 8 pb Frank Pabodie 751 pb temp -18.50 9 lake Anderson Lake 734 lake sal 0.05 10 lake Anderson Lake 751 lake sal 0.10 11 lake Anderson Lake 752 lake rad 2.19 12 lake Anderson Lake 752 lake sal 0.09 13 lake Anderson Lake 752 lake temp -16.00 14 lake Anderson Lake 837 lake rad 1.46 15 lake Anderson Lake 837 lake sal 0.21 16 roe Valentina Roerich 752 roe sal 41.60 17 roe Valentina Roerich 837 roe sal 22.50 18 roe Valentina Roerich 844 roe rad 11.25 ident site dated taken person quant reading 0 619 DR-1 1927-02-08 619 dyer rad 9.82 1 619 DR-1 1927-02-08 619 dyer sal 0.13 2 622 DR-1 1927-02-10 622 dyer rad 7.80 3 622 DR-1 1927-02-10 622 dyer sal 0.09 4 734 DR-3 1939-01-07 734 pb rad 8.41 5 734 DR-3 1939-01-07 734 lake sal 0.05 6 734 DR-3 1939-01-07 734 pb temp -21.50 7 735 DR-3 1930-01-12 735 pb rad 7.22 8 735 DR-3 1930-01-12 735 NaN sal 0.06 9 735 DR-3 1930-01-12 735 NaN temp -26.00 10 751 DR-3 1930-02-26 751 pb rad 4.35 11 751 DR-3 1930-02-26 751 pb temp -18.50 12 751 DR-3 1930-02-26 751 lake sal 0.10 13 752 DR-3 NaN 752 lake rad 2.19 14 752 DR-3 NaN 752 lake sal 0.09 15 752 DR-3 NaN 752 lake temp -16.00 16 752 DR-3 NaN 752 roe sal 41.60 17 837 MSK-4 1932-01-14 837 lake rad 1.46 18 837 MSK-4 1932-01-14 837 lake sal 0.21 19 837 MSK-4 1932-01-14 837 roe sal 22.50 20 844 DR-1 1932-03-22 844 roe rad 11.25 参考资料 技术支持qq群144081101 591302926 567351477 钉钉免费群21745728 本文最新版本地址 本文涉及的python测试开发库 谢谢点赞! 本文相关海量书籍下载 源码下载 本文英文版书籍下载

优秀的个人博客,低调大师

[雪峰磁针石博客]flask构建自动化测试平台2-开始头条项目

2-开始头条项目 代码地址 我们将创建一个头条应用程序,显示最新的新闻标题,天气信息,和货币汇率。 在本章中,我们将介绍RSS源并展示如何自动使用它们从特定出版物中检索最近的新闻报道。在下一章中,我们会讨论如何使用模板来显示检索到的标题和摘要文章给我们的用户。第4章,我们头条页面项目的用户输入,将显示你如何从用户那里获得输入,以便他们可以定制他们的体验,也看看如何将天气和货币数据添加到我们的应用程序。我们会完成在第5章“改善我们头条项目的用户体验”一文中关注项目添加一些CSS样式并查看如何记住用户的偏好。 到本章结束时,您将学会如何创建更复杂的Flask应用。我们将从真实世界的新闻故事中提取原始数据并构建HTML格式化将其显示给我们的用户。您还将学习更多关于路由的知识 - 也就是说不同的URL会触发我们应用程序代码的不同部分。 在本章中,我们将介绍以下主题: RSS和RSS源简介 技术支持QQ群: 144081101 591302926 567351477本文最新版本 RSS和RSS源简介 我们需要安装feedparser:feedparser。 问题,如何寻找python库? python测试开发库, PYPI pip3 install --user feedparser 主要的RSS有WordPress和Blogger,通常会有如下图标。 BBC news的rss为: http://feeds.bbci.co.uk/news/rss.xml 下面的代码需要对HTML有一定的了解,初学者可以参考:http://www.w3school.com.cn/html/index.asp import feedparser from flask import Flask app = Flask(__name__) RSS_FEEDS = {'bbc': 'http://feeds.bbci.co.uk/news/rss.xml', 'cnn': 'http://rss.cnn.com/rss/edition.rss', 'fox': 'http://feeds.foxnews.com/foxnews/latest', 'iol': 'http://www.iol.co.za/cmlink/1.640'} @app.route("/") @app.route("/<publication>") def get_news(publication="bbc"): feed = feedparser.parse(RSS_FEEDS[publication]) first_article = feed['entries'][0] return """<html> <body> <h1>Headlines </h1> <b>{0}</b> <i>{1}</i> <p>{2}</p> </body> </html>""".format(first_article.get("title"), first_article.get("published"), first_article.get("summary")) if __name__ == "__main__": app.run(host='0.0.0.0',port=8000, debug=True) 执行: $ curl http://172.20.15.200:8000/iol <html> <body> <h1>Headlines </h1> <b>IEC still unable to confirm addresses of 2.8 million citizens</b> <i>Wed, 07 Mar 2018 17:26:00 GMT</i> <p>The Independent Electoral Commission still does not have addresses for 2.8 million South Africans ahead of the 2019 general elections.</p> </body> </html>andrew@andrew-PowerEdge-T630:~/code/Flask-Building-Python-Web-Services/Module 1$ curl http://172.20.15.200:8000/cnn <html> <body> <h1>Headlines </h1> <b>In Lesotho, women say they're finding their abortions on Facebook</b> <i>None</i> <p>None</p> </body> </html>andrew@andrew-PowerEdge-T630:~/code/Flask-Building-Python-Web-Services/Module 1$ curl http://172.20.15.200:8000/test <!DOCTYPE HTML PUBLIC "-//W3C//DTD HTML 4.01 Transitional//EN" "http://www.w3.org/TR/html4/loose.dtd"> <html> <head> <title>KeyError: 'test' // Werkzeug Debugger</title> <link rel="stylesheet" href="?__debugger__=yes&amp;cmd=resource&amp;f=style.css" type="text/css"> <!-- We need to make sure this has a favicon so that the debugger does ... 参考资料 本文相关书籍下载 讨论 钉钉免费群21745728 qq群144081101 567351477 本文涉及的python测试开发库 谢谢点赞! 本文代码地址

资源下载

更多资源
腾讯云软件源

腾讯云软件源

为解决软件依赖安装时官方源访问速度慢的问题,腾讯云为一些软件搭建了缓存服务。您可以通过使用腾讯云软件源站来提升依赖包的安装速度。为了方便用户自由搭建服务架构,目前腾讯云软件源站支持公网访问和内网访问。

Nacos

Nacos

Nacos /nɑ:kəʊs/ 是 Dynamic Naming and Configuration Service 的首字母简称,一个易于构建 AI Agent 应用的动态服务发现、配置管理和AI智能体管理平台。Nacos 致力于帮助您发现、配置和管理微服务及AI智能体应用。Nacos 提供了一组简单易用的特性集,帮助您快速实现动态服务发现、服务配置、服务元数据、流量管理。Nacos 帮助您更敏捷和容易地构建、交付和管理微服务平台。

Spring

Spring

Spring框架(Spring Framework)是由Rod Johnson于2002年提出的开源Java企业级应用框架,旨在通过使用JavaBean替代传统EJB实现方式降低企业级编程开发的复杂性。该框架基于简单性、可测试性和松耦合性设计理念,提供核心容器、应用上下文、数据访问集成等模块,支持整合Hibernate、Struts等第三方框架,其适用范围不仅限于服务器端开发,绝大多数Java应用均可从中受益。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

用户登录
用户注册