首页 文章 精选 留言 我的

精选列表

搜索[监督学习],共10000篇文章
优秀的个人博客,低调大师

CUDA学习(二十五)

硬件实施(HARDWARE IMPLEMENTATION):NVIDIA GPU架构是围绕可扩展的多线程流处理器(SM)阵列构建的。 当主机CPU上的CUDA程序调用内核网格时,网格块被枚举并分配给具有可用执行能力的多处理器。 一个线程块的线程在一个多处理器上同时执行,多个线程块可以在一个多处理器上同时执行。 当线程块终止时,在空闲的多处理器上启动新的块。多处理器被设计为同时执行数百个线程。 为了管理如此大量的线程,它采用了SIMT架构中描述的称为SIMT(单指令,多线程)的独特架构。 这些指令被流水线化以利用单个线程内的指令级并行性,以及通过硬件多线程中详细描述的同时硬件多线程广泛地实现线程级并行性。 与CPU内核不同,它们是按顺序发布的,没有分支预测,也没有推测性执行。SIMT体系结构和硬件多线程描述了所有设备共有的流式多处理器的体系结构特征。 计算能力3.x,计算能力5.x,计算能力6.x和计算能力7.x分别为计算能力3.x,5.x,6.x和7.x的设备提供具体信息。SIMT架构:多处理器创建,管理,调度和执行32个并行线程组的线程,称为warps。 单独的线程在同一个程序地址上组成一个warp起始点,但是它们有自己的指令地址计数器和寄存器状态,因此可以自由地分支和独立执行。 术语warp起源于编织,第一个平行螺纹技术。 半经线是经线的前半部分或后半部分。 四分之一翘曲是经线的第一,二,三或四分之一。当一个多处理器被赋予一个或多个线程块执行时,它将它们分成warp,每个warp被warp调度器调度执行。 块被划分成扭曲的方式总是相同的; 每个warp包含连续的,增加线程ID的线程,第一个warp包含线程0. ThreadHierarchy描述线程ID如何与块中的线程索引相关。一个warp一次执行一个共同的指令,所以当一个warp的所有32个线程都同意它们的执行路径时,就可以实现完全的效率。 如果warp的线程通过依赖于数据的条件分支发散,则warp执行每个分支路径,禁用不在该路径上的线程。 分支发散只发生在经线内; 不同的warps独立执行,不管它们是执行共同的还是不相交的代码路径。SIMT体系结构类似于SIMD(单指令多数据)矢量组织,因为单指令控制多个处理单元。一个关键的区别是SIMD向量组织将SIMD宽度暴露给软件,而SIMT指令指定单个线程的执行和分支行为。与SIMD向量机相反,SIMT使程序员能够为独立标量线程编写线程级并行代码,并为协调线程编写数据并行代码。为了正确,程序员可以基本上忽略SIMT行为;然而,通过注意代码很少要求变形中的线程发散,可以实现显着的性能改进。实际上,这与传统代码中缓存行的作用类似:在设计正确性时,可以安全地忽略缓存行大小,但在设计峰值性能时必须考虑代码结构。另一方面,矢量架构需要软件将负载合并到矢量中,并手动管理差异。

优秀的个人博客,低调大师

python标准库学习7

使用 os.path 模块处理文件名 import os filename = "my/little/pony" print "using", os.name, "..." print "split", "=>", os.path.split(filename) print "splitext", "=>", os.path.splitext(filename) print "dirname", "=>", os.path.dirname(filename) print "basename", "=>", os.path.basename(filename) print "join", "=>", os.path.join(os.path.dirname(filename), os.path.basename(filename)) using nt ... split => ('my/little', 'pony') splitext => ('my/little/pony', '') dirname => my/little basename => pony join => my/little\pony 当前目录和上一级目录 >>> os.pardir '..' >>> os.curdir '.' 使用 os.path 模块检查文件名的特征 import os FILES = ( os.curdir, "/", "file", "/file", "samples", "samples/sample.jpg", "directory/file", "../directory/file", "/directory/file" ) for file in FILES: print file, "=>", if os.path.exists(file): print "EXISTS", if os.path.isabs(file): print "ISABS", if os.path.isdir(file): print "ISDIR", if os.path.isfile(file): print "ISFILE", if os.path.islink(file): print "ISLINK", if os.path.ismount(file): print "ISMOUNT", print . => EXISTS ISDIR / => EXISTS ISABS ISDIR ISMOUNT file => /file => ISABS samples => EXISTS ISDIR samples/sample.jpg => EXISTS ISFILE directory/file => ../directory/file => /directory/file => ISABS expanduser函数以与大部分Unix shell相同的方式处理用户名快捷符号(~, 不过在 Windows 下工作不正常), 使用 os.path 模块将用户名插入到文件名 import os print os.path.expanduser("~/.pythonrc") # /home/effbot/.pythonrc expandvars函数将文件名中的环境变量替换为对应值 使用 os.path 替换文件名中的环境变量 import os os.environ["USER"] = "user" print os.path.expandvars("/home/$USER/config") print os.path.expandvars("$USER/folders") /home/user/config user/folders 列出目录下所有的文件和目录 >>> a=[file for file in os.listdir("d:\\new")] >>> for i in a: print i walk函数会帮你找出一个目录树下的所有文件. 它的参数依次是目录名, 回调函数, 以及传递给回调函数的数据对象. 使用 os.path 搜索文件系统 import os def callback(arg, directory, files): for file in files: print os.path.join(directory, file), repr(arg) os.path.walk(".", callback, "secret message") ./aifc-example-1.py 'secret message' ./anydbm-example-1.py 'secret message' ./array-example-1.py 'secret message' ... ./samples 'secret message' ./samples/sample.jpg 'secret message' ./samples/sample.txt 'secret message' ./samples/sample.zip 'secret message' ./samples/articles 'secret message' ./samples/articles/article-1.txt 'secret message' ./samples/articles/article-2.txt 'secret message' ... index函数会返回一个文件名列表, 你可以直接使用for-in循环处理文件. 使用 os.listdir 搜索文件系统 import os def index(directory): # like os.listdir, but traverses directory trees stack = [directory] files = [] while stack: directory = stack.pop() for file in os.listdir(directory): fullname = os.path.join(directory, file) files.append(fullname) if os.path.isdir(fullname) and not os.path.islink(fullname): stack.append(fullname) return files for file in index("."): print file .\aifc-example-1.py .\anydbm-example-1.py .\array-example-1.py ... 一次返回一个文件 import os class DirectoryWalker: # a forward iterator that traverses a directory tree def _ _init_ _(self, directory): self.stack = [directory] self.files = [] self.index = 0 def _ _getitem_ _(self, index): while 1: try: file = self.files[self.index] self.index = self.index + 1 except IndexError: # pop next directory from stack self.directory = self.stack.pop() self.files = os.listdir(self.directory) self.index = 0 else: # got a filename fullname = os.path.join(self.directory, file) if os.path.isdir(fullname) and not os.path.islink(fullname): self.stack.append(fullname) return fullname for file in DirectoryWalker("."): print file .\aifc-example-1.py .\anydbm-example-1.py .\array-example-1.py ... 注意DirectoryWalker类并不检查传递给_ _getitem_ _方法的索引值. 这意味着如果你越界访问序列成员(索引数字过大)的话, 这个类将不能正常工作. 下面这个例子它返回文件名和它的os.stat属性(一个元组). 这个版本在每个文件上都能节省一次或两次stat调用(os.path.isdir和os.path.islink内部都使用了stat), 并且在一些平台上运行很快. 使用 DirectoryStatWalker 搜索文件系统 import os, stat class DirectoryStatWalker: # a forward iterator that traverses a directory tree, and # returns the filename and additional file information def _ _init_ _(self, directory): self.stack = [directory] self.files = [] self.index = 0 def _ _getitem_ _(self, index): while 1: try: file = self.files[self.index] self.index = self.index + 1 except IndexError: # pop next directory from stack self.directory = self.stack.pop() self.files = os.listdir(self.directory) self.index = 0 else: # got a filename fullname = os.path.join(self.directory, file) st = os.stat(fullname) mode = st[stat.ST_MODE] if stat.S_ISDIR(mode) and not stat.S_ISLNK(mode): self.stack.append(fullname) return fullname, st for file, st in DirectoryStatWalker("."): print file, st[stat.ST_SIZE] .\aifc-example-1.py 336 .\anydbm-example-1.py 244 .\array-example-1.py 526 Using the stat Module import stat import os, time st = os.stat("samples/sample.txt") print "mode", "=>", oct(stat.S_IMODE(st[stat.ST_MODE])) print "type", "=>", if stat.S_ISDIR(st[stat.ST_MODE]): print "DIRECTORY", if stat.S_ISREG(st[stat.ST_MODE]): print "REGULAR", if stat.S_ISLNK(st[stat.ST_MODE]): print "LINK", print print "size", "=>", st[stat.ST_SIZE] print "last accessed", "=>", time.ctime(st[stat.ST_ATIME]) print "last modified", "=>", time.ctime(st[stat.ST_MTIME]) print "inode changed", "=>", time.ctime(st[stat.ST_CTIME]) mode => 0664 type => REGULAR size => 305 last accessed => Sun Oct 10 22:12:30 1999 last modified => Sun Oct 10 18:39:37 1999 inode changed => Sun Oct 10 15:26:38 1999 使用 string 模块 import string text = "Monty Python's Flying Circus" print "upper", "=>", string.upper(text) print "lower", "=>", string.lower(text) print "split", "=>", string.split(text) print "join", "=>", string.join(string.split(text), "+") print "replace", "=>", string.replace(text, "Python", "Java") print "find", "=>", string.find(text, "Python"), string.find(text, "Java") print "count", "=>", string.count(text, "n") upper => MONTY PYTHON'S FLYING CIRCUS lower => monty python's flying circus split => ['Monty', "Python's", 'Flying', 'Circus'] join => Monty+Python's+Flying+Circus replace => Monty Java's Flying Circus find => 6 -1 count => 3 使用字符串方法替代 string 模块函数 text = "Monty Python's Flying Circus" print "upper", "=>", text.upper() print "lower", "=>", text.lower() print "split", "=>", text.split() print "join", "=>", "+".join(text.split()) print "replace", "=>", text.replace("Python", "Perl") print "find", "=>", text.find("Python"), text.find("Perl") print "count", "=>", text.count("n") upper => MONTY PYTHON'S FLYING CIRCUS lower => monty python's flying circus split => ['Monty', "Python's", 'Flying', 'Circus'] join => Monty+Python's+Flying+Circus replace => Monty Perl's Flying Circus find => 6 -1 count => 3 使用 string 模块将字符串转为数字 import string print int("4711"), print string.atoi("4711"), print string.atoi("11147", 8), # octal 八进制 print string.atoi("1267", 16), # hexadecimal 十六进制 print string.atoi("3mv", 36) # whatever... print string.atoi("4711", 0), print string.atoi("04711", 0), print string.atoi("0x4711", 0) print float("4711"), print string.atof("1"), print string.atof("1.23e5") 4711 4711 4711 4711 4711 4711 2505 18193 4711.0 1.0 123000.0 operator模块为 Python 提供了一个 "功能性" 的标准操作符接口. 当使用map以及filter一类的函数的时候,operator模块中的函数可以替换一些lambda函式. 而且这些函数在一些喜欢写晦涩代码的程序员中很流行. 使用 operator 模块 print "add", "=>", reduce(operator.add, sequence) print "sub", "=>", reduce(operator.sub, sequence) print "mul", "=>", reduce(operator.mul, sequence) print "concat", "=>", operator.concat("spam", "egg") print "repeat", "=>", operator.repeat("spam", 5) print "getitem", "=>", operator.getitem(sequence, 2) print "indexOf", "=>", operator.indexOf(sequence, 2) print "sequenceIncludes", "=>", operator.sequenceIncludes(sequence, 3) add => 7 sub => -5 mul => 8 concat => spamegg repeat => spamspamspamspamspam getitem => 4 indexOf => 1 sequenceIncludes => 0 使用 operator 模块检查类型 import operator import UserList def dump(data): print type(data), "=>", if operator.isCallable(data): print "CALLABLE", if operator.isMappingType(data): print "MAPPING", if operator.isNumberType(data): print "NUMBER", if operator.isSequenceType(data): print "SEQUENCE", print dump(0) dump("string") dump("string"[0]) dump([1, 2, 3]) dump((1, 2, 3)) dump({"a": 1}) dump(len) # function 函数 dump(UserList) # module 模块 dump(UserList.UserList) # class 类 dump(UserList.UserList()) # instance 实例 <type 'int'> => NUMBER <type 'string'> => SEQUENCE <type 'string'> => SEQUENCE <type 'list'> => SEQUENCE <type 'tuple'> => SEQUENCE <type 'dictionary'> => MAPPING <type 'builtin_function_or_method'> => CALLABLE <type 'module'> => <type 'class'> => CALLABLE <type 'instance'> => MAPPING NUMBER SEQUENCE copy模块包含两个函数, 用来拷贝对象 使用 copy 模块复制对象 import copy a = [[1],[2],[3]] b = copy.copy(a) print "before", "=>" print a print b # modify original a[0][0] = 0 a[1] = None print "after", "=>" print a print b before => [[1], [2], [3]] [[1], [2], [3]] after => [[0], None, [3]] [[0], [2], [3]] 使用 copy 模块复制集合(Collections) import copy a = [[1],[2],[3]] b = copy.deepcopy(a) print "before", "=>" print a print b # modify original a[0][0] = 0 a[1] = None print "after", "=>" print a print b before => [[1], [2], [3]] [[1], [2], [3]] after => [[0], None, [3]] [[1], [2], [3]] 使用sys模块获得脚本的参数 import sys print "script name is", sys.argv[0] if len(sys.argv) > 1: print "there are", len(sys.argv)-1, "arguments:" for arg in sys.argv[1:]: print arg else: print "there are no arguments!" script name is sys-argv-example-1.py there are no arguments! 使用sys模块操作模块搜索路径 import sys print "path has", len(sys.path), "members" # add the sample directory to the path sys.path.insert(0, "samples") import sample # nuke the path sys.path = [] import random # oops! path has 7 members this is the sample module! Traceback (innermost last): File "sys-path-example-1.py", line 11, in ? import random # oops! ImportError: No module named random 使用sys模块查找内建模块 import sys def dump(module): print module, "=>", if module in sys.builtin_module_names: print "<BUILTIN>" else: module = _ _import_ _(module) print module._ _file_ _ dump("os") dump("sys") dump("string") dump("strop") dump("zlib") os => C:\python\lib\os.pyc sys => <BUILTIN> string => C:\python\lib\string.pyc strop => <BUILTIN> zlib => C:\python\zlib.pyd 使用sys模块查找已导入的模块 modules字典包含所有加载的模块.import语句在从磁盘导入内容之前会先检查这个字典. import sys print sys.modules.keys() ['os.path', 'os', 'exceptions', '_ _main_ _', 'ntpath', 'strop', 'nt', 'sys', '_ _builtin_ _', 'site', 'signal', 'UserDict', 'string', 'stat'] getrefcount函数返回给定对象的引用记数 - 也就是这个对象使用次数. Python 会跟踪这个值, 当它减少为0的时候, 就销毁这个对象. 使用sys模块获得引用记数 import sys variable = 1234 print sys.getrefcount(0) print sys.getrefcount(variable) print sys.getrefcount(None) 50 3 192 注意这个值总是比实际的数量大, 因为该函数本身在确定这个值的时候依赖这个对象 使用sys模块获得当前平台 import sys # # emulate "import os.path" (sort of)... if sys.platform == "win32": import ntpath pathmodule = ntpath elif sys.platform == "mac": import macpath pathmodule = macpath else: # assume it's a posix platform import posixpath pathmodule = posixpath print pathmodule setprofiler函数允许你配置一个分析函数(profiling function). 这个函数会在每次调用某个函数或方法时被调用(明确或隐含的), 或是遇到异常的时候被调用. 使用sys模块配置分析函数 import sys def test(n): j = 0 for i in range(n): j = j + i return n def profiler(frame, event, arg): print event, frame.f_code.co_name, frame.f_lineno, "->", arg # profiler is activated on the next call, return, or exception # 分析函数将在下次函数调用, 返回, 或异常时激活 sys.setprofile(profiler) # profile this function call # 分析这次函数调用 test(1) # disable profiler # 禁用分析函数 sys.setprofile(None) # don't profile this call # 不会分析这次函数调用 test(2) call test 3 -> None return test 7 -> 1 使用sys模块配置单步跟踪函数 import sys def test(n): j = 0 for i in range(n): j = j + i return n def tracer(frame, event, arg): print event, frame.f_code.co_name, frame.f_lineno, "->", arg return tracer # tracer is activated on the next call, return, or exception # 跟踪器将在下次函数调用, 返回, 或异常时激活 sys.settrace(tracer) # trace this function call # 跟踪这次函数调用 test(1) # disable tracing # 禁用跟踪器 sys.settrace(None) # don't trace this call # 不会跟踪这次函数调用 test(2) call test 3 -> None line test 3 -> None line test 4 -> None line test 5 -> None line test 5 -> None line test 6 -> None line test 5 -> None line test 7 -> None return test 7 -> 1 ============================================================================== 本文转自被遗忘的博客园博客,原文链接:http://www.cnblogs.com/rollenholt/archive/2011/11/26/2264682.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

python标准库学习8

使用sys重定向输出 import sys import string class Redirect: def _ _init_ _( self , stdout): self .stdout = stdout def write( self , s): self .stdout.write(string.lower(s)) # redirect standard output (including the print statement) # 重定向标准输出(包括print语句) old_stdout = sys.stdout sys.stdout = Redirect(sys.stdout) print "HEJA SVERIGE" , print "FRISKT HUM\303\226R" # restore standard output # 恢复标准输出 sys.stdout = old_stdout print "M\303\205\303\205\303\205\303\205L!" heja sverige friskt hum\ 303 \ 266r M\ 303 \ 205 \ 303 \ 205 \ 303 \ 205 \ 303 \ 205L ! 使用sys模块退出程序 import sys print "hello" sys.exit( 1 ) print "there" hello 注意sys.exit并不是立即退出. 而是引发一个SystemExit异常. 这意味着你可以在主程序中捕获对sys.exit的调用 捕获sys.exit调用 import sys print "hello" try : sys.exit( 1 ) except SystemExit: pass print "there" hello there 如果准备在退出前自己清理一些东西(比如删除临时文件), 你可以配置一个 "退出处理函数"(exit handler), 它将在程序退出的时候自动被调用 另一种捕获sys.exit调用的方法 import sys def exitfunc(): print "world" sys.exitfunc = exitfunc print "hello" sys.exit( 1 ) print "there" # never printed # 不会被 print hello world 在 Python 2.0 以后, 你可以使用atexit模块来注册多个退出处理函数. atexit模块允许你注册一个或多个终止函数(暂且这么叫), 这些函数将在解释器终止前被自动调用. 调用register函数, 便可以将函数注册为终止函数,你也可以添加更多的参数, 这些将作为exit函数的参数传递. 使用 atexit 模块 import atexit def exit( * args): print "exit" , args # register two exit handler atexit.register(exit) atexit.register(exit, 1 ) atexit.register(exit, "hello" , "world" ) exit ( 'hello' , 'world' ) exit ( 1 ,) exit () time模块提供了一些处理日期和一天内时间的函数. 它是建立在 C 运行时库的简单封装. 给定的日期和时间可以被表示为浮点型(从参考时间, 通常是 1970.1.1 到现在经过的秒数. 即 Unix 格式), 或者一个表示时间的 struct (类元组). 使用 time 模块获取当前时间 import time now = time.time() print now, "seconds since" , time.gmtime( 0 )[: 6 ] print print "or in other words:" print "- local time:" , time.localtime(now) print "- utc:" , time.gmtime(now) 937758359.77 seconds since ( 1970 , 1 , 1 , 0 , 0 , 0 ) or in other words: - local time: ( 1999 , 9 , 19 , 18 , 25 , 59 , 6 , 262 , 1 ) - utc: ( 1999 , 9 , 19 , 16 , 25 , 59 , 6 , 262 , 0 ) 使用 time 模块格式化时间输出 import time now = time.localtime(time.time()) print time.asctime(now) print time.strftime( "%y/%m/%d %H:%M" , now) print time.strftime( "%a %b %d" , now) print time.strftime( "%c" , now) print time.strftime( "%I %p" , now) print time.strftime( "%Y-%m-%d %H:%M:%S %Z" , now) # do it by hand... year, month, day, hour, minute, second, weekday, yearday, daylight = now print "%04d-%02d-%02d" % (year, month, day) print "%02d:%02d:%02d" % (hour, minute, second) print ( "MON" , "TUE" , "WED" , "THU" , "FRI" , "SAT" , "SUN" )[weekday], yearday Sun Oct 10 21 : 39 : 24 1999 99 / 10 / 10 21 : 39 Sun Oct 10 Sun Oct 10 21 : 39 : 24 1999 09 PM 1999 - 10 - 10 21 : 39 : 24 CEST 1999 - 10 - 10 21 : 39 : 24 SUN 283 在一些平台上,time模块包含了strptime函数, 它的作用与strftime相反. 给定一个字符串和模式, 它返回相应的时间对象 使用 time.strptime 函数解析时间 import time # make sure we have a strptime function! # 确认有函数 strptime try : strptime = time.strptime except AttributeError: from strptime import strptime print strptime( "31 Nov 00" , "%d %b %y" ) print strptime( "1 Jan 70 1:30pm" , "%d %b %y %I:%M%p" ) strptime 不完全实现 import re import string MONTHS = [ "Jan" , "Feb" , "Mar" , "Apr" , "May" , "Jun" , "Jul" , "Aug" , "Sep" , "Oct" , "Nov" , "Dec" ] SPEC = { # map formatting code to a regular expression fragment "%a" : "(?P<weekday>[a-z]+)" , "%A" : "(?P<weekday>[a-z]+)" , "%b" : "(?P<month>[a-z]+)" , "%B" : "(?P<month>[a-z]+)" , "%C" : "(?P<century>\d\d?)" , "%d" : "(?P<day>\d\d?)" , "%D" : "(?P<month>\d\d?)/(?P<day>\d\d?)/(?P<year>\d\d)" , "%e" : "(?P<day>\d\d?)" , "%h" : "(?P<month>[a-z]+)" , "%H" : "(?P<hour>\d\d?)" , "%I" : "(?P<hour12>\d\d?)" , "%j" : "(?P<yearday>\d\d?\d?)" , "%m" : "(?P<month>\d\d?)" , "%M" : "(?P<minute>\d\d?)" , "%p" : "(?P<ampm12>am|pm)" , "%R" : "(?P<hour>\d\d?):(?P<minute>\d\d?)" , "%S" : "(?P<second>\d\d?)" , "%T" : "(?P<hour>\d\d?):(?P<minute>\d\d?):(?P<second>\d\d?)" , "%U" : "(?P<week>\d\d)" , "%w" : "(?P<weekday>\d)" , "%W" : "(?P<weekday>\d\d)" , "%y" : "(?P<year>\d\d)" , "%Y" : "(?P<year>\d\d\d\d)" , "%%" : "%" } class TimeParser: def _ _init_ _( self , format ): # convert strptime format string to regular expression format = string.join(re.split( "(?:\s|%t|%n)+" , format )) pattern = [] try : for spec in re.findall( "%\w|%%|." , format ): if spec[ 0 ] = = "%" : spec = SPEC[spec] pattern.append(spec) except KeyError: raise ValueError, "unknown specificer: %s" % spec self .pattern = re. compile ( "(?i)" + string.join(pattern, "")) def match( self , daytime): # match time string match = self .pattern.match(daytime) if not match: raise ValueError, "format mismatch" get = match.groupdict().get tm = [ 0 ] * 9 # extract date elements y = get( "year" ) if y: y = int (y) if y < 68 : y = 2000 + y elif y < 100 : y = 1900 + y tm[ 0 ] = y m = get( "month" ) if m: if m in MONTHS: m = MONTHS.index(m) + 1 tm[ 1 ] = int (m) d = get( "day" ) if d: tm[ 2 ] = int (d) # extract time elements h = get( "hour" ) if h: tm[ 3 ] = int (h) else : h = get( "hour12" ) if h: h = int (h) if string.lower(get( "ampm12" , " ")) == " pm": h = h + 12 tm[ 3 ] = h m = get( "minute" ) if m: tm[ 4 ] = int (m) s = get( "second" ) if s: tm[ 5 ] = int (s) # ignore weekday/yearday for now return tuple (tm) def strptime(string, format = "%a %b %d %H:%M:%S %Y" ): return TimeParser( format ).match(string) if _ _name_ _ = = "_ _main_ _" : # try it out import time print strptime( "2000-12-20 01:02:03" , "%Y-%m-%d %H:%M:%S" ) print strptime(time.ctime(time.time())) ( 2000 , 12 , 20 , 1 , 2 , 3 , 0 , 0 , 0 ) ( 2000 , 11 , 15 , 12 , 30 , 45 , 0 , 0 , 0 ) 使用 time 模块将本地时间元组转换为时间值(整数) import time t0 = time.time() tm = time.localtime(t0) print tm print t0 print time.mktime(tm) ( 1999 , 9 , 9 , 0 , 11 , 8 , 3 , 252 , 1 ) 936828668.16 936828668.0 将 UTC 时间元组转换为时间值(整数) import time def _d(y, m, d, days = ( 0 , 31 , 59 , 90 , 120 , 151 , 181 , 212 , 243 , 273 , 304 , 334 , 365 )): # map a date to the number of days from a reference point return (((y - 1901 ) * 1461 ) / 4 + days[m - 1 ] + d + ((m > 2 and not y % 4 and (y % 100 or not y % 400 )) and 1 )) def timegm(tm, epoch = _d( 1970 , 1 , 1 )): year, month, day, h, m, s = tm[: 6 ] assert year > = 1970 assert 1 < = month < = 12 return (_d(year, month, day) - epoch) * 86400 + h * 3600 + m * 60 + s t0 = time.time() tm = time.gmtime(t0) print tm print t0 print timegm(tm) ( 1999 , 9 , 8 , 22 , 12 , 12 , 2 , 251 , 0 ) 936828732.48 936828732 使用 time 模块评价算法 import time def procedure(): time.sleep( 2.5 ) # measure process time t0 = time.clock() procedure() print time.clock() - t0, "seconds process time" # measure wall time t0 = time.time() procedure() print time.time() - t0, "seconds wall time" 0.0 seconds process time 2.50903499126 seconds wall time 使用 types 模块 import types def check( object ): print object , if type ( object ) is types.IntType: print "INTEGER" , if type ( object ) is types.FloatType: print "FLOAT" , if type ( object ) is types.StringType: print "STRING" , if type ( object ) is types.ClassType: print "CLASS" , if type ( object ) is types.InstanceType: print "INSTANCE" , print check( 0 ) check( 0.0 ) check( "0" ) class A: pass class B: pass check(A) check(B) a = A() b = B() check(a) check(b) 0 INTEGER 0.0 FLOAT 0 STRING A CLASS B CLASS <A instance at 796960 > INSTANCE <B instance at 796990 > INSTANCE 使用 gc 模块收集循环引用垃圾 import gc # create a simple object that links to itself class Node: def _ _init_ _( self , name): self .name = name self .parent = None self .children = [] def addchild( self , node): node.parent = self self .children.append(node) def _ _repr_ _( self ): return "<Node %s at %x>" % ( repr ( self .name), id ( self )) # set up a self-referencing structure root = Node( "monty" ) root.addchild(Node( "eric" )) root.addchild(Node( "john" )) root.addchild(Node( "michael" )) # remove our only reference del root print gc.collect(), "unreachable objects" print gc.collect(), "unreachable objects" 12 unreachable objects 0 unreachable objects ============================================================================== 本文转自被遗忘的博客园博客,原文链接:http://www.cnblogs.com/rollenholt/archive/2011/11/27/2264909.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

python标准库学习9

fileinput模块允许你循环一个或多个文本文件的内容 使用 fileinput 模块循环一个文本文件 import fileinput import sys for line in fileinput. input ( "samples/sample.txt" ): sys.stdout.write( "-> " ) sys.stdout.write(line) - > We will perhaps eventually be writing only small - > modules which are identified by name as they are - > used to build larger ones, so that devices like - > indentation, rather than delimiters, might become - > feasible for expressing local structure in the - > source language. - > - - Donald E. Knuth, December 1974 你也可以使用fileinput模块获得当前行的元信息 (meta information). 其中包括isfirstline,filename,lineno 使用 fileinput 模块处理多个文本文件 import fileinput import glob import string, sys for line in fileinput. input (glob.glob( "samples/*.txt" )): if fileinput.isfirstline(): # first in a file? sys.stderr.write( "-- reading %s --\n" % fileinput.filename()) sys.stdout.write( str (fileinput.lineno()) + " " + string.upper(line)) - - reading samples\sample.txt - - 1 WE WILL PERHAPS EVENTUALLY BE WRITING ONLY SMALL 2 MODULES WHICH ARE IDENTIFIED BY NAME AS THEY ARE 3 USED TO BUILD LARGER ONES, SO THAT DEVICES LIKE 4 INDENTATION, RATHER THAN DELIMITERS, MIGHT BECOME 5 FEASIBLE FOR EXPRESSING LOCAL STRUCTURE IN THE 6 SOURCE LANGUAGE. 7 - - DONALD E. KNUTH, DECEMBER 1974 文本文件的替换操作很简单. 只需要把inplace关键字参数设置为 1 , 传递给input函数, 该模块会帮你做好一切. 使用 fileinput 模块将 CRLF 改为 LF import fileinput, sys for line in fileinput. input (inplace = 1 ): # convert Windows/DOS text files to Unix files if line[ - 2 :] = = "\r\n" : line = line[: - 2 ] + "\n" sys.stdout.write(line) shutil实用模块包含了一些用于复制文件和文件夹的函数. 使用 shutil 复制文件 import shutil import os for file in os.listdir( "." ): if os.path.splitext( file )[ 1 ] = = ".py" : print file shutil.copy( file , os.path.join( "backup" , file )) aifc - example - 1.py anydbm - example - 1.py array - example - 1.py ... copytree函数用于复制整个目录树 (与cp -r相同), 而rmtree函数用于删除整个目录树 (与rm -r) 使用 shutil 模块复制/删除目录树 import shutil import os SOURCE = "samples" BACKUP = "samples-bak" # create a backup directory shutil.copytree(SOURCE, BACKUP) print os.listdir(BACKUP) # remove it shutil.rmtree(BACKUP) print os.listdir(BACKUP) [ 'sample.wav' , 'sample.jpg' , 'sample.au' , 'sample.msg' , 'sample.tgz' , ... Traceback (most recent call last): File "shutil-example-2.py" , line 17 , in ? print os.listdir(BACKUP) os.error: No such file or directory tempfile模块允许你快速地创建名称唯一的临时文件供使用. 使用 tempfile 模块创建临时文件 import tempfile import os tempfile = tempfile.mktemp() print "tempfile" , "=>" , tempfile file = open (tempfile, "w+b" ) file .write( "*" * 1000 ) file .seek( 0 ) print len ( file .read()), "bytes" file .close() try : # must remove file when done os.remove(tempfile) except OSError: pass tempfile = > C:\TEMP\~ 160 - 1 1000 bytes TemporaryFile函数会自动挑选合适的文件名, 并打开文件而且它会确保该文件在关闭的时候会被删除. (在 Unix 下, 你可以删除一个已打开的文件, 这 时文件关闭时它会被自动删除. 在其他平台上, 这通过一个特殊的封装类实现.) 使用 tempfile 模块打开临时文件 import tempfile file = tempfile.TemporaryFile() for i in range ( 100 ): file .write( "*" * 100 ) file .close() # removes the file! StringIO模块的使用. 它实现了一个工作在内存的文件对象 (内存文件). 在大多需要标准文件对象的地方都可以使用它来替换. 使用 StringIO 模块从内存文件读入内容 import StringIO MESSAGE = "That man is depriving a village somewhere of a computer scientist." file = StringIO.StringIO(MESSAGE) print file .read() That man is depriving a village somewhere of a computer scientist. StringIO类实现了内建文件对象的所有方法, 此外还有getvalue方法用来返回它内部的字符串值 使用 StringIO 模块向内存文件写入内容 import StringIO file = StringIO.StringIO() file .write( "This man is no ordinary man. " ) file .write( "This is Mr. F. G. Superman." ) print file .getvalue() This man is no ordinary man. This is Mr. F. G. Superman. 使用 StringIO 模块捕获输出 import StringIO import string, sys stdout = sys.stdout sys.stdout = file = StringIO.StringIO() print """ According to Gbaya folktales, trickery and guile are the best ways to defeat the python, king of snakes, which was hatched from a dragon at the world's start. -- National Geographic, May 1997 """ sys.stdout = stdout print string.upper( file .getvalue()) ACCORDING TO GBAYA FOLKTALES, TRICKERY AND GUILE ARE THE BEST WAYS TO DEFEAT THE PYTHON, KING OF SNAKES, WHICH WAS HATCHED FROM A DRAGON AT THE WORLD'S START. - - NATIONAL GEOGRAPHIC, MAY 1997 cStringIO是一个可选的模块, 是StringIO的更快速实现. 它的工作方式和StringIO基本相同, 但是它不可以被继承 使用 cStringIO 模块 import cStringIO MESSAGE = "That man is depriving a village somewhere of a computer scientist." file = cStringIO.StringIO(MESSAGE) print file .read() That man is depriving a village somewhere of a computer scientist. 为了让你的代码尽可能快, 但同时保证兼容低版本的 Python ,你可以使用一个小技巧在cStringIO不可用时启用StringIO模块, 后退至 StringIO try : import cStringIO StringIO = cStringIO except ImportError: import StringIO print StringIO <module 'StringIO' (built - in )> mmap模块提供了操作系统内存映射函数的接口,映射区域的行为和字符串对象类似, 但数据是直接从文件读取的. 使用 mmap 模块 import mmap import os filename = "samples/sample.txt" file = open (filename, "r+" ) size = os.path.getsize(filename) data = mmap.mmap( file .fileno(), size) # basics print data print len (data), size # use slicing to read from the file # 使用切片操作读取文件 print repr (data[: 10 ]), repr (data[: 10 ]) # or use the standard file interface # 或使用标准的文件接口 print repr (data.read( 10 )), repr (data.read( 10 )) <mmap object at 008A2A10 > 302 302 'We will pe' 'We will pe' 'We will pe' 'rhaps even' 在 Windows 下, 这个文件必须以既可读又可写的模式打开( `r+` , `w+` , 或 `a+` ), 否则mmap调用会失败. 对映射区域使用字符串方法和正则表达式 mport mmap import os, string, re def mapfile(filename): file = open (filename, "r+" ) size = os.path.getsize(filename) return mmap.mmap( file .fileno(), size) data = mapfile( "samples/sample.txt" ) # search index = data.find( "small" ) print index, repr (data[index - 5 :index + 15 ]) # regular expressions work too! m = re.search( "small" , data) print m.start(), m.group() 43 'only small\015\012modules ' 43 small ============================================================================== 本文转自被遗忘的博客园博客,原文链接:http://www.cnblogs.com/rollenholt/archive/2011/11/27/2264946.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

python标准库学习4

>>> os.environ["HOME"] 'C:\\Users\\Administrator' >>> os.getcwd() #获得当前的目录 'D:\\new' >>> os.getenv("QTDIR") #获取环境变量的值 'D:\\vs2010-qt-src-4.7.4\\qt-src-4.7.4' os.putenv(varname, value) #设置环境变量的值 os.mkdir(path[, mode]) >>> os.mkdir("aa") >>> os.rmdir("aa") >>>os.makedirs("aa\\bb\\cc") 多级目录 os.removedirs(path)¶ os.remove("d:\\new\\hello.txt") #删除文件,如果是目录的话,出错 os.rename("test.txt","a.txt") random.randint(a, b) Return a random integer N such that a <= N <= b. random.choice(seq) Return a random element from the non-empty sequence seq. If seq is empty, raises IndexError. random.random() Return the next random floating point number in the range [0.0, 1.0). random.shuffle(x[, random]) 随机排序序列 random.uniform(a, b)¶返回a<=N<=b之间的浮点数 random.randrange([start], stop[, step])想当于choice(range(start, stop, step)) >>> random.random() # Random float x, 0.0 <= x < 1.0 0.37444887175646646 >>> random.uniform(1, 10) # Random float x, 1.0 <= x < 10.0 1.1800146073117523 >>> random.randint(1, 10) # Integer from 1 to 10, endpoints included 7 >>> random.randrange(0, 101, 2) # Even integer from 0 to 100 26 >>> random.choice('abcdefghij') # Choose a random element 'c' >>> items = [1, 2, 3, 4, 5, 6, 7] >>> random.shuffle(items) >>> items [7, 3, 2, 5, 6, 4, 1] >>> random.sample([1, 2, 3, 4, 5], 3) # Choose 3 elements [4, 1, 5] >>> datetime.MAXYEAR 9999 >>> datetime.MINYEAR 1 >>> a=datetime.date(2011,2,1) >>> a.today() datetime.date(2011, 11, 26) >>> a.year 2011 >>> a.month 2 >>> a.day 1 >>> import time >>> from datetime import date >>> today = date.today() >>> today datetime.date(2007, 12, 5) >>> my_birthday = date(today.year, 6, 24) >>> if my_birthday < today: ... my_birthday = my_birthday.replace(year=today.year + 1) >>> my_birthday datetime.date(2008, 6, 24) >>> time_to_birthday = abs(my_birthday - today) #计算日期之差 >>> time_to_birthday.days 202 >>> datetime.now() #当前时间 datetime.datetime(2011, 11, 26, 10, 40, 10, 283000) >>> datetime.utcnow() datetime.datetime(2011, 11, 26, 2, 40, 34, 809000) >>> a=date(2005,7,14) #日期和时间进行合并 >>> t=time(12,30,12) >>> datetime.combine(a,t) datetime.datetime(2005, 7, 14, 12, 30, 12) >>> dt = datetime.strptime("21/11/06 16:30", "%d/%m/%y %H:%M") >>> dt datetime.datetime(2006, 11, 21, 16, 30) >>> from datetime import timedelta, datetime, tzinfo >>> class GMT1(tzinfo): ... def __init__(self): # DST starts last Sunday in March ... d = datetime(dt.year, 4, 1) # ends last Sunday in October ... self.dston = d - timedelta(days=d.weekday() + 1) ... d = datetime(dt.year, 11, 1) ... self.dstoff = d - timedelta(days=d.weekday() + 1) ... def utcoffset(self, dt): ... return timedelta(hours=1) + self.dst(dt) ... def dst(self, dt): ... if self.dston <= dt.replace(tzinfo=None) < self.dstoff: ... return timedelta(hours=1) ... else: ... return timedelta(0) ... def tzname(self,dt): ... return "GMT +1" ... >>> class GMT2(tzinfo): ... def __init__(self): ... d = datetime(dt.year, 4, 1) ... self.dston = d - timedelta(days=d.weekday() + 1) ... d = datetime(dt.year, 11, 1) ... self.dstoff = d - timedelta(days=d.weekday() + 1) ... def utcoffset(self, dt): ... return timedelta(hours=1) + self.dst(dt) ... def dst(self, dt): ... if self.dston <= dt.replace(tzinfo=None) < self.dstoff: ... return timedelta(hours=2) ... else: ... return timedelta(0) ... def tzname(self,dt): ... return "GMT +2" ... >>> gmt1 = GMT1() >>> # Daylight Saving Time >>> dt1 = datetime(2006, 11, 21, 16, 30, tzinfo=gmt1) >>> dt1.dst() datetime.timedelta(0) >>> dt1.utcoffset() datetime.timedelta(0, 3600) >>> dt2 = datetime(2006, 6, 14, 13, 0, tzinfo=gmt1) >>> dt2.dst() datetime.timedelta(0, 3600) >>> dt2.utcoffset() datetime.timedelta(0, 7200) >>> # Convert datetime to another time zone >>> dt3 = dt2.astimezone(GMT2()) >>> dt3 # doctest: +ELLIPSIS datetime.datetime(2006, 6, 14, 14, 0, tzinfo=<GMT2 object at 0x...>) >>> dt2 # doctest: +ELLIPSIS datetime.datetime(2006, 6, 14, 13, 0, tzinfo=<GMT1 object at 0x...>) >>> dt2.utctimetuple() == dt3.utctimetuple() True class datetime.time(hour[, minute[, second[, microsecond[, tzinfo]]]]) >>> a=time(10,46,12) >>> a.min datetime.time(0, 0) >>> a.max datetime.time(23, 59, 59, 999999) >>> a.hour 10 >>> a.minute 46 >>> a.second 12 >>> a.microsecond 0 class collections.Counter([iterable-or-mapping]) A Counter is a dict subclass for counting hashable objects. >>> # Tally occurrences of words in a list >>> cnt = Counter() >>> for word in ['red', 'blue', 'red', 'green', 'blue', 'blue']: ... cnt[word] += 1 >>> cnt Counter({'blue': 3, 'red': 2, 'green': 1}) >>> # Find the ten most common words in Hamlet >>> import re >>> words = re.findall('\w+', open('hamlet.txt').read().lower()) >>> Counter(words).most_common(10) [('the', 1143), ('and', 966), ('to', 762), ('of', 669), ('i', 631), ('you', 554), ('a', 546), ('my', 514), ('hamlet', 471), ('in', 451)] >>> c = Counter(['eggs', 'ham']) >>> c['bacon'] # count of a missing element is zero 0 >>> c['sausage'] = 0 # counter entry with a zero count >>> del c['sausage'] # del actually removes the entry >>> c = Counter(a=4, b=2, c=0, d=-2) >>> list(c.elements()) ['a', 'a', 'a', 'a', 'b', 'b'] most_common([n]) #出现次数最多的n个 >>> Counter('abracadabra').most_common(3) [('a', 5), ('r', 2), ('b', 2)] >>> c = Counter(a=4, b=2, c=0, d=-2) >>> d = Counter(a=1, b=2, c=3, d=4) >>> c.subtract(d) Counter({'a': 3, 'b': 0, 'c': -3, 'd': -6}) >>> c = Counter(a=4, b=2, c=0, d=-2) >>> sum(c.values()) # total of all counts 4 >>> list(c) ['a', 'c', 'b', 'd'] >>> set(c) set(['a', 'c', 'b', 'd']) >>> dict(c) {'a': 4, 'c': 0, 'b': 2, 'd': -2} >>> c.items() [('a', 4), ('c', 0), ('b', 2), ('d', -2)] >>> c.most_common()[:-2:-1] # c.most_common()[:-n:-1] n least #common elements [('d', -2)] >>> c+=Counter() >>> c Counter({'a': 4, 'b': 2}) >>> c.clear() >>> c Counter() >>> c = Counter(a=3, b=1) >>> d = Counter(a=1, b=2) >>> c + d # add two counters together: c[x] + d[x] Counter({'a': 4, 'b': 3}) >>> c - d # subtract (keeping only positive counts) Counter({'a': 2}) >>> c & d # intersection: min(c[x], d[x]) Counter({'a': 1, 'b': 1}) >>> c | d # union: max(c[x], d[x]) Counter({'a': 3, 'b': 2}) >>> from collections import deque >>> d = deque('ghi') # make a new deque with three items >>> for elem in d: # iterate over the deque's elements ... print elem.upper() G H I >>> d.append('j') # add a new entry to the right side >>> d.appendleft('f') # add a new entry to the left side >>> d # show the representation of the deque deque(['f', 'g', 'h', 'i', 'j']) >>> d.pop() # return and remove the rightmost item 'j' >>> d.popleft() # return and remove the leftmost item 'f' >>> list(d) # list the contents of the deque ['g', 'h', 'i'] >>> d[0] # peek at leftmost item 'g' >>> d[-1] # peek at rightmost item 'i' >>> list(reversed(d)) # list the contents of a deque in reverse ['i', 'h', 'g'] >>> 'h' in d # search the deque True >>> d.extend('jkl') # add multiple elements at once >>> d deque(['g', 'h', 'i', 'j', 'k', 'l']) >>> d.rotate(1) # right rotation >>> d deque(['l', 'g', 'h', 'i', 'j', 'k']) >>> d.rotate(-1) # left rotation >>> d deque(['g', 'h', 'i', 'j', 'k', 'l']) >>> deque(reversed(d)) # make a new deque in reverse order deque(['l', 'k', 'j', 'i', 'h', 'g']) >>> d.clear() # empty the deque >>> d.pop() # cannot pop from an empty deque Traceback (most recent call last): File "<pyshell#6>", line 1, in -toplevel- d.pop() IndexError: pop from an empty deque >>> d.extendleft('abc') # extendleft() reverses the input order >>> d deque(['c', 'b', 'a']) def tail(filename, n=10): 'Return the last n lines of a file' return deque(open(filename), n) def moving_average(iterable, n=3): # moving_average([40, 30, 50, 46, 39, 44]) --> 40.0 42.0 45.0 43.0 # http://en.wikipedia.org/wiki/Moving_average it = iter(iterable) d = deque(itertools.islice(it, n-1)) d.appendleft(0) s = sum(d) for elem in it: s += elem - d.popleft() d.append(elem) yield s / float(n) def delete_nth(d, n): d.rotate(-n) d.popleft() d.rotate(n) class collections.defaultdict([default_factory[, ...]]) >>> s = [('yellow', 1), ('blue', 2), ('yellow', 3), ('blue', 4), ('red', 1)] >>> d = defaultdict(list) >>> for k, v in s: ... d[k].append(v) ... >>> d.items() [('blue', [2, 4]), ('red', [1]), ('yellow', [1, 3])] >>> d = {} >>> for k, v in s: ... d.setdefault(k, []).append(v) ... >>> d.items() [('blue', [2, 4]), ('red', [1]), ('yellow', [1, 3])] >>> s = 'mississippi' >>> d = defaultdict(int) >>> for k in s: ... d[k] += 1 ... >>> d.items() [('i', 4), ('p', 2), ('s', 4), ('m', 1)] >>> s = [('red', 1), ('blue', 2), ('red', 3), ('blue', 4), ('red', 1), ('blue', 4)] >>> d = defaultdict(set) >>> for k, v in s: ... d[k].add(v) ... >>> d.items() [('blue', set([2, 4])), ('red', set([1, 3]))] >>> def heapsort(iterable): ... 'Equivalent to sorted(iterable)' ... h = [] ... for value in iterable: ... heappush(h, value) ... return [heappop(h) for i in range(len(h))] ... >>> heapsort([1, 3, 5, 7, 9, 2, 4, 6, 8, 0]) [0, 1, 2, 3, 4, 5, 6, 7, 8, 9] >>> h = [] >>> heappush(h, (5, 'write code')) >>> heappush(h, (7, 'release product')) >>> heappush(h, (1, 'write spec')) >>> heappush(h, (3, 'create tests')) >>> heappop(h) (1, 'write spec') #coding=utf-8 #堆的实例 from heapq import heappush, heappop, heappushpop, heapify, heapreplace, nlargest,\ nsmallest heap=[] heappush(heap,"A"); heappush(heap,"C"); heappush(heap,"B"); print heap heappop(heap) #弹出堆中最小的元素 print heap var=heappushpop(heap,"D") #返回并弹出堆中最小的元素,并且将D压入堆 print var print heap var=heapreplace(heap,"E") #返回并弹出堆中最小的元素,并且将D压入堆, print var print heap list=[1,2,3,4,5,6,7,8,9,0] heapify(list); print list print nlargest(3,list) #返回堆中最大的3个 print nsmallest(3,list) #返回堆中最小的3个 ============================================================================== 本文转自被遗忘的博客园博客,原文链接:http://www.cnblogs.com/rollenholt/archive/2011/11/26/2264225.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

python标准库学习6

使用 apply 函数 def function(a, b): print a, b apply (function, ( "whither" , "canada?" )) apply (function, ( 1 , 2 + 3 )) whither canada? 1 5 使用 apply 函数传递关键字参数 def function(a, b): print a, b apply (function, ( "crunchy" , "frog" )) apply (function, ( "crunchy" ,), { "b" : "frog" }) apply (function, (), { "a" : "crunchy" , "b" : "frog" }) crunchy frog crunchy frog crunchy frog 使用 apply 函数调用基类的构造函数 class Rectangle: def _ _init_ _( self , color = "white" , width = 10 , height = 10 ): print "create a" , color, self , "sized" , width, "x" , height class RoundedRectangle(Rectangle): def _ _init_ _( self , * * kw): apply (Rectangle._ _init_ _, ( self ,), kw) rect = Rectangle(color = "green" , height = 100 , width = 100 ) rect = RoundedRectangle(color = "blue" , height = 20 ) create a green <Rectangle instance at 8c8260 > sized 100 x 100 create a blue <RoundedRectangle instance at 8c84c0 > sized 10 x 20 使用 _ _import_ _ 函数获得特定函数 def getfunctionbyname(module_name, function_name): module = _ _import_ _(module_name) return getattr (module, function_name) print repr (getfunctionbyname( "dumbdbm" , "open" )) <function open at 794fa0 > 使用 _ _import_ _ 函数实现 延迟导入 class LazyImport: def _ _init_ _( self , module_name): self .module_name = module_name self .module = None def _ _getattr_ _( self , name): if self .module is None : self .module = _ _import_ _( self .module_name) return getattr ( self .module, name) string = LazyImport( "string" ) print string.lowercase abcdefghijklmnopqrstuvwxyz 使用 dir 函数 def dump(value): print value, "=>" , dir (value) import sys dump( 0 ) dump( 1.0 ) dump( 0.0j ) # complex number dump([]) # list dump({}) # dictionary dump( "string" ) dump( len ) # function dump(sys) # module 0 = > [] 1.0 = > [] 0j = > [ 'conjugate' , 'imag' , 'real' ] [] = > [ 'append' , 'count' , 'extend' , 'index' , 'insert' , 'pop' , 'remove' , 'reverse' , 'sort' ] {} = > [ 'clear' , 'copy' , 'get' , 'has_key' , 'items' , 'keys' , 'update' , 'values' ] string = > [] <built - in function len > = > [ '_ _doc_ _' , '_ _name_ _' , '_ _self_ _' ] <module 'sys' (built - in )> = > [ '_ _doc_ _' , '_ _name_ _' , '_ _stderr_ _' , '_ _stdin_ _' , '_ _stdout_ _' , 'argv' , 'builtin_module_names' , 'copyright' , 'dllhandle' , 'exc_info' , 'exc_type' , 'exec_prefix' , 'executable' , ... 使用 dir 函数查找类的所有成员 class A: def a( self ): pass def b( self ): pass class B(A): def c( self ): pass def d( self ): pass def getmembers(klass, members = None ): # get a list of all class members, ordered by class if members is None : members = [] for k in klass._ _bases_ _: getmembers(k, members) for m in dir (klass): if m not in members: members.append(m) return members print getmembers(A) print getmembers(B) print getmembers(IOError) [ '_ _doc_ _' , '_ _module_ _' , 'a' , 'b' ] [ '_ _doc_ _' , '_ _module_ _' , 'a' , 'b' , 'c' , 'd' ] [ '_ _doc_ _' , '_ _getitem_ _' , '_ _init_ _' , '_ _module_ _' , '_ _str_ _' ] 使用 callable 函数 def dump(function): if callable (function): print function, "is callable" else : print function, "is *not* callable" class A: def method( self , value): return value class B(A): def _ _call_ _( self , value): return value a = A() b = B() dump( 0 ) # simple objects dump( "string" ) dump( callable ) dump(dump) # function dump(A) # classes dump(B) dump(B.method) dump(a) # instances dump(b) dump(b.method) 0 is * not * callable string is * not * callable <built - in function callable > is callable <function dump at 8ca320 > is callable A is callable B is callable <unbound method A.method> is callable <A instance at 8caa10 > is * not * callable <B instance at 8cab00 > is callable <method A.method of B instance at 8cab00 > is callable 使用 eval 函数 def dump(expression): result = eval (expression) print expression, "=>" , result, type (result) dump( "1" ) dump( "1.0" ) dump( "'string'" ) dump( "1.0 + 2.0" ) dump( "'*' * 10" ) dump( "len('world')" ) 1 = > 1 < type 'int' > 1.0 = > 1.0 < type 'float' > 'string' = > string < type 'string' > 1.0 + 2.0 = > 3.0 < type 'float' > '*' * 10 = > * * * * * * * * * * < type 'string' > len ( 'world' ) = > 5 < type 'int' > 使用 eval 函数执行任意命令 print eval ( "_ _import_ _('os').getcwd()" ) print eval ( "_ _import_ _('os').remove('file')" ) / home / fredrik / librarybook Traceback (innermost last): File "builtin-eval-example-2" , line 2 , in ? File "<string>" , line 0 , in ? os.error: ( 2 , 'No such file or directory' ) 使用 compile 函数检查语法 NAME = "script.py" BODY = """ prnt 'owl-stretching time' """ try : compile (BODY, NAME, "exec" ) except SyntaxError, v: print "syntax error:" , v, "in" , NAME # syntax error: invalid syntax in script.py 执行已编译的代码 BODY = """ print 'the ant, an introduction' """ code = compile (BODY, "<script>" , "exec" ) print code exec code <code object ? at 8c6be0 , file "<script>" , line 0 > the ant, an introduction Python 还提供了execfile函数, 一个从文件加载代码, 编译代码, 执行代码的快捷方式. 使用 execfile 函数 execfile ( "hello.py" ) def EXECFILE (filename, locals = None , globals = None ): exec compile ( open (filename).read(), filename, "exec" ) in locals , globals EXECFILE ( "hello.py" ) hello again, and welcome to the show hello again, and welcome to the show 显式地访问 _ _builtin_ _ 模块中的函数 def open (filename, mode = "rb" ): import _ _builtin_ _ file = _ _builtin_ _. open (filename, mode) if file .read( 5 ) not in ( "GIF87" , "GIF89" ): raise IOError, "not a GIF file" file .seek( 0 ) return file fp = open ( "samples/sample.gif" ) print len (fp.read()), "bytes" fp = open ( "samples/sample.jpg" ) print len (fp.read()), "bytes" 3565 bytes Traceback (innermost last): File "builtin-open-example-1.py" , line 12 , in ? File "builtin-open-example-1.py" , line 5 , in open IOError: not a GIF file 使用 exceptions 模块 # python imports this module by itself, so the following # line isn't really needed # python 会自动导入该模块, 所以以下这行是不必要的 # import exceptions class HTTPError(Exception): # indicates an HTTP protocol error def _ _init_ _( self , url, errcode, errmsg): self .url = url self .errcode = errcode self .errmsg = errmsg def _ _str_ _( self ): return ( "<HTTPError for %s: %s %s>" % ( self .url, self .errcode, self .errmsg) ) try : raise HTTPError( "http://www.python.org/foo" , 200 , "Not Found" ) except HTTPError, error: print "url" , "=>" , error.url print "errcode" , "=>" , error.errcode print "errmsg" , "=>" , error.errmsg raise # reraise exception url = > http: / / www.python.org / foo errcode = > 200 errmsg = > Not Found Traceback (innermost last): File "exceptions-example-1" , line 16 , in ? HTTPError: <HTTPError for http: / / www.python.org / foo: 200 Not Found> 使用 os 模块重命名和删除文件 import os import string def replace( file , search_for, replace_with): # replace strings in a text file back = os.path.splitext( file )[ 0 ] + ".bak" temp = os.path.splitext( file )[ 0 ] + ".tmp" try : # remove old temp file, if any os.remove(temp) except os.error: pass fi = open ( file ) fo = open (temp, "w" ) for s in fi.readlines(): fo.write(string.replace(s, search_for, replace_with)) fi.close() fo.close() try : # remove old backup file, if any os.remove(back) except os.error: pass # rename original to backup... os.rename( file , back) # ...and temporary to original os.rename(temp, file ) # # try it out! file = "samples/sample.txt" replace( file , "hello" , "tjena" ) replace( file , "tjena" , "hello" ) 使用 os 列出目录下的文件 import os for file in os.listdir( "samples" ): print file sample.au sample.jpg sample.wav ... getcwd和chdir函数分别用于获得和改变当前工作目录 使用 os 模块改变当前工作目录 import os # where are we? cwd = os.getcwd() print "1" , cwd # go down os.chdir( "samples" ) print "2" , os.getcwd() # go back up os.chdir(os.pardir) print "3" , os.getcwd() 1 / ematter / librarybook 2 / ematter / librarybook / samples 3 / ematter / librarybook makedirs和removedirs函数用于创建或删除目录层 使用 os 模块创建/删除多个目录级 import os os.makedirs( "test/multiple/levels" ) fp = open ( "test/multiple/levels/file" , "w" ) fp.write( "inspector praline" ) fp.close() # remove the file os.remove( "test/multiple/levels/file" ) # and all empty directories above it os.removedirs( "test/multiple/levels" ) removedirs函数会删除所给路径中最后一个目录下所有的空目录. 而mkdir和rmdir函数只能处理单个目录级 使用 os 模块创建/删除目录 import os os.mkdir( "test" ) os.rmdir( "test" ) os.rmdir( "samples" ) # this will fail Traceback (innermost last): File "os-example-7" , line 6 , in ? OSError: [Errno 41 ] Directory not empty: 'samples' 如果需要删除非空目录, 你可以使用shutil模块中的rmtree函数 >>> import shutil shutil.rmtree( "d:\\a" ) 复制文件目录(包括内部文件) >>> shutil.copytree( "d:\\new" , "d:\\a" ) 复制文件操作: shutil.copyfile( "d:\\new\\a.txt" , "d:\\a.txt" ) 目录或文件的移动操作 shutil.move( "d:\\new\\a.txt" , "d:\\" ) 使用 os 模块获取文件属性 import os import time file = "samples/sample.jpg" def dump(st): mode, ino, dev, nlink, uid, gid, size, atime, mtime, ctime = st print "- size:" , size, "bytes" print "- owner:" , uid, gid print "- created:" , time.ctime(ctime) print "- last accessed:" , time.ctime(atime) print "- last modified:" , time.ctime(mtime) print "- mode:" , oct (mode) print "- inode/dev:" , ino, dev # # get stats for a filename st = os.stat( file ) print "stat" , file dump(st) print # # get stats for an open file fp = open ( file ) st = os.fstat(fp.fileno()) print "fstat" , file dump(st) stat samples / sample.jpg - size: 4762 bytes - owner: 0 0 - created: Tue Sep 07 22 : 45 : 58 1999 - last accessed: Sun Sep 19 00 : 00 : 00 1999 - last modified: Sun May 19 01 : 42 : 16 1996 - mode: 0100666 - inode / dev: 0 2 fstat samples / sample.jpg - size: 4762 bytes - owner: 0 0 - created: Tue Sep 07 22 : 45 : 58 1999 - last accessed: Sun Sep 19 00 : 00 : 00 1999 - last modified: Sun May 19 01 : 42 : 16 1996 - mode: 0100666 - inode / dev: 0 0 可以使用chmod和utime函数修改文件的权限模式和时间属性 使用 os 模块修改文件的权限和时间戳 import os import stat, time infile = "samples/sample.jpg" outfile = "out.jpg" # copy contents fi = open (infile, "rb" ) fo = open (outfile, "wb" ) while 1 : s = fi.read( 10000 ) if not s: break fo.write(s) fi.close() fo.close() # copy mode and timestamp st = os.stat(infile) os.chmod(outfile, stat.S_IMODE(st[stat.ST_MODE])) os.utime(outfile, (st[stat.ST_ATIME], st[stat.ST_MTIME])) print "original" , "=>" print "mode" , oct (stat.S_IMODE(st[stat.ST_MODE])) print "atime" , time.ctime(st[stat.ST_ATIME]) print "mtime" , time.ctime(st[stat.ST_MTIME]) print "copy" , "=>" st = os.stat(outfile) print "mode" , oct (stat.S_IMODE(st[stat.ST_MODE])) print "atime" , time.ctime(st[stat.ST_ATIME]) print "mtime" , time.ctime(st[stat.ST_MTIME]) original = > mode 0666 atime Thu Oct 14 15 : 15 : 50 1999 mtime Mon Nov 13 15 : 42 : 36 1995 copy = > mode 0666 atime Thu Oct 14 15 : 15 : 50 1999 mtime Mon Nov 13 15 : 42 : 36 1995 system函数在当前进程下执行一个新命令, 并等待它完成 使用 os 执行操作系统命令 import os if os.name = = "nt" : command = "dir" else : command = "ls -l" os.system(command) - rwxrw - r - - 1 effbot effbot 76 Oct 9 14 : 17 README - rwxrw - r - - 1 effbot effbot 1727 Oct 7 19 : 00 SimpleAsyncHTTP.py - rwxrw - r - - 1 effbot effbot 314 Oct 7 20 : 29 aifc - example - 1.py - rwxrw - r - - 1 effbot effbot 259 Oct 7 20 : 38 anydbm - example - 1.py ... 命令通过操作系统的标准 shell 执行, 并返回 shell 的退出状态. 需要注意的是在 Windows 下, shell 通常是command.com, 它的推出状态总是 0. exec函数会使用新进程替换当前进程(或者说是"转到进程"). 使用 os 模块启动新进程 import os import sys program = "python" arguments = [ "hello.py" ] print os.execvp(program, (program,) + tuple (arguments)) print "goodbye" hello again, and welcome to the show execvp函数, 它会从标准路径搜索执行程序, 把第二个参数(元组)作为单独的参数传递给程序, 并使用当前的环境变量来运行程序. 其他七个同类型函数请参阅Python Library Reference. 在 Unix 环境下, 你可以通过组合使用exec,fork以及wait函数来从当前程序调用另一个程序,fork函数复制当前进程,wait函数会等待一个子进程执行结束. 使用 os 模块调用其他程序 (Unix) import os import sys def run(program, * args): pid = os.fork() if not pid: os.execvp(program, (program,) + args) return os.wait()[ 0 ] run( "python" , "hello.py" ) print "goodbye" hello again, and welcome to the show goodbye fork函数在子进程返回中返回 0 (这个进程首先从fork返回值), 在父进程中返回一个非 0 的进程标识符(子进程的 PID ). 也就是说, 只有当我们处于子进程的时候 "not pid" 才为真. fork和wait函数在 Windows 上是不可用的, 但是你可以使用spawn函数不过,spawn不会沿着路径搜索可执行文件, 你必须自己处理好这些. 或许系统当前的“PATH”变量的值 >>> import string >>> import os >>> for path in string.split(os.environ[ "PATH" ],os.pathsep): print path C:\Program Files\NVIDIA Corporation\PhysX\Common d:\program files\Python27\Lib\site - packages\PyQt4 C:\windows\system32 C:\windows C:\windows\System32\Wbem C:\windows\System32\WindowsPowerShell\v1. 0 \ C:\Program Files\Common Files\Thunder Network\KanKan\Codecs D:\Program Files\python D:\Program Files\Java\jdk1. 6.0_23 / bin D:\Program Files\Java\jdk1. 6.0_23 / jre / bin C:\Program Files\Microsoft SQL Server\ 90 \Tools\binn\ D:\vs2010 - qt - src - 4.7 . 4 \qt - src - 4.7 . 4 \ bin C:\Program Files\Intel\WiFi\ bin \ C:\Program Files\Common Files\Intel\WirelessCommon\ C:\Program Files\Lenovo\Bluetooth Software\ D:\vs2010 - qt - src - 4.7 . 4 \qt - src - 4.7 . 4 \ bin D:\vs2010 - qt - src - 4.7 . 4 \qt - src - 4.7 . 4 \lib D:\vs2010 - qt - src - 4.7 . 4 \qt - src - 4.7 . 4 \include D:\Qt\ 4.7 . 4 \ bin >>> 使用 os 模块调用其他程序 (Windows) import os import string def run(program, * args): # find executable for path in string.split(os.environ[ "PATH" ], os.pathsep): file = os.path.join(path, program) + ".exe" try : return os.spawnv(os.P_WAIT, file , ( file ,) + args) except os.error: pass raise os.error, "cannot find executable" run( "python" , "hello.py" ) print "goodbye" hello again, and welcome to the show goodbye spawn函数还可用于在后台运行一个程序.下面这个例子给run函数添加了一个可选的mode参数; 当设置为os.P_NOWAIT时, 这个脚本不会等待子程序结束, 默认值os.P_WAIT时spawn会等待子进程结束. 其它的标志常量还有os.P_OVERLAY,它使得spawn的行为和exec类似, 以及os.P_DETACH, 它在后台运行子进程, 与当前控制台和键盘焦点隔离. import os import string def run(program, * args, * * kw): # find executable mode = kw.get( "mode" , os.P_WAIT) for path in string.split(os.environ[ "PATH" ], os.pathsep): file = os.path.join(path, program) + ".exe" try : return os.spawnv(mode, file , ( file ,) + args) except os.error: pass raise os.error, "cannot find executable" run( "python" , "hello.py" , mode = os.P_NOWAIT) print "goodbye" goodbye hello again, and welcome to the show 下面这个例子提供了一个在 Unix 和 Windows 平台上通用的spawn方法 使用 spawn 或 fork/exec 调用其他程序 import os import string if os.name in ( "nt" , "dos" ): exefile = ".exe" else : exefile = "" def spawn(program, * args): try : # possible 2.0 shortcut! return os.spawnvp(program, (program,) + args) except AttributeError: pass try : spawnv = os.spawnv except AttributeError: # assume it's unix pid = os.fork() if not pid: os.execvp(program, (program,) + args) return os.wait()[ 0 ] else : # got spawnv but no spawnp: go look for an executable for path in string.split(os.environ[ "PATH" ], os.pathsep): file = os.path.join(path, program) + exefile try : return spawnv(os.P_WAIT, file , ( file ,) + args) except os.error: pass raise IOError, "cannot find executable" # # try it out! spawn( "python" , "hello.py" ) print "goodbye" hello again, and welcome to the show goodbye 处理守护进程 Unix 系统中, 你可以使用fork函数把当前进程转入后台(一个"守护者/daemon"). 一般来说, 你需要派生(fork off)一个当前进程的副本, 然后终止原进程 使用 os 模块使脚本作为守护执行 (Unix) import os import time pid = os.fork() if pid: os._exit( 0 ) # kill original print "daemon started" time.sleep( 10 ) print "daemon terminated" 使用 os 模块终止当前进程 importos importsys try: sys.exit(1) exceptSystemExit, value: print"caught exit(%s)"%value try: os._exit(2) exceptSystemExit, value: print"caught exit(%s)"%value print"bye!" caught exit(1) 本文转自被遗忘的博客园博客,原文链接:http://www.cnblogs.com/rollenholt/archive/2011/11/26/2264597.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

数据分析学习笔记

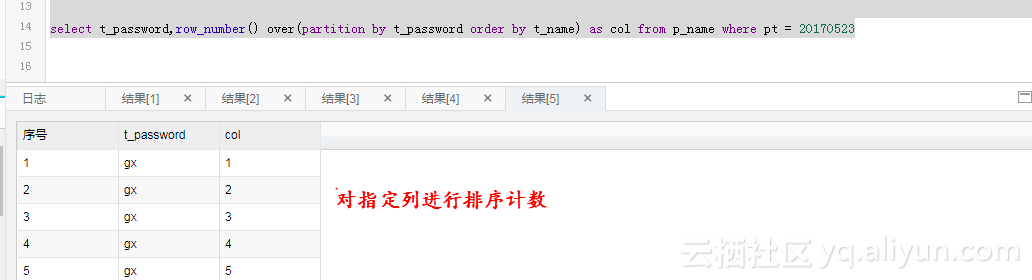
row_number() row_number() over(partition by col1[, col2…] order by col1 [asc|desc][, col2[asc|desc]…]) 函数说明: 可以用于开窗,排序,计数,返回当前窗口的排序值。 参数说明:partition by col1[, col2..]:指定开窗口的列。 order by col1 [asc|desc], col2[asc|desc]:指定结果返回时的排序的值。 WM_CONCAT 函数声明:string wm_concat(string separator, string str) 函数说明:该函数用指定的 spearator 做分隔符,链接 str 中的值。可以用于多行变一行。 参数说明:separator:String 类型常量,分隔符。其他类型或非常量将引发异常。str:String 类型,若输入为 Bigint,Double 或者 Datetime 类型,会隐式转换为 String 后参与运算,其它类型报异常。返回值:返回 String 类型。

优秀的个人博客,低调大师

iOS开发学习笔记(一)

一、必要条件 1、一台运行Snow Leopard(os x 10.6.5或者更高版本)的基于Intel的Macintosh计算机。 2、注册成为iOS开发人员,下载iOS SDK。 3、下载XCode集成开发环境。 二、开发者选择: 1、免费的SDK包含一个模拟器,它支持在mac上创建和运行iPhone和iPad程序。但是模拟器不支持依赖硬件的某些特性,如iPhone的加速计或者摄像头,也不支持将应用程序安装到实际的iPhone或其他设备上。开发的应用也不能发布到appstore上。如果要实现这些功能,需要注册另外两个收费的选项。 2、标准方案是99美元一年。提供了大量的开发工具、资源和技术支持,支持在appstore上发布应用。最重要的是支持在iOS上而不是模拟器上调试和测试代码。 3、企业方案是299美元一年。面向开发专用的、内部的iOS应用程序的企业。 三、编写iOS程序用何不同: 1、只有一个应用程序正在运行 在iOS上,特定时间段内仅激活一个应用程序并在屏幕上显示。从iOS 4开始,当用户按下home按钮后应用程序有时可能继续在后台运行,但是这种情况也只限于特定的场合。 当应用程序未激活或未运行于后台时,它不会引起CPU任何形式的注意,这将导致网络连接断开以及其他问题。iOS 4在后台处理能力方面已经有了大幅提升,但要使你的应用程序在这种情况下仍运行良好,还需要你自身的努力。 2、只有一个窗口 在桌面及笔记本电脑操作系统中,多个程序可以同时运行,并且可以分别创建和控制多个窗口。而iOS则有所不同,它只允许应用程序操作一个“窗口”。应用程序与用户的所有交互都在这个窗口中完成,而且这个窗口的大小就是iOS屏幕的大小,是固定的。 3、受限访问 计算机上的程序可以访问其用户能够访问的任何内容,而iOS则严格限制了应用程序的访问权限。 你只能在iOS为应用程序创建的文件系统中读写文件。此区域称为应用程序的沙盒,应用程序在其中存储文档、首选项等需要存储的各种数据。 应用程序还存在其他方面的限制。举例来说,你不能访问iOS上端口号较小的网络端口,也不能执行台式计算机中需要有根用户或管理员权限才能执行的操作。 4、有限的响应时间 由于使用方式特殊,iOS及其应用程序需要具备较快的响应时间。启动应用程序时,需要先打开它,载入首选项和数据,并尽快在屏幕上显示主视图,这一切要在几秒之内完成。 只要应用程序在运行,就可以从其下方拖出一个菜单条。如果用户按home按钮,iOS就会返回主页,用户需要快速保存一切内容并退出。如果未在5秒之内保存并放弃控制,则应用程序进程将终止,无论用户是否已经完成保存。 请注意,在iOS 4中,这种情况因为一种新API的存在而有所改善。这种API允许你的应用程序在终止前申请多一些的时间来处理。 5、有限的屏幕大小 iPhone的屏幕显示效果非常出色,从推出到现在,它一直是消费设备中分辨率最高的屏幕。 但是,iPhone的显示屏幕并不大,你施展的空间要比现代计算机小很多,最新的Retina显示器(iPhone 4和第4代iPod touch)仅有640×960像素,更老的仅有320×480像素。 而且,现在的尺寸与以前相同,只不过Retina显示屏为640×960像素,所以不要以为可以放更多的控件或什么了——仅仅是分辨率比以前高了。 iPad稍大一些,是1024×768像素,但也不算很大。与此形成鲜明对比的是,在撰写本书时,苹果公司最便宜的iMac支持1920×1080像素,最便宜的笔记本电脑MacBook支持1280×800像素。而苹果公司最大的显示器,27英寸的LED Cinema Display,支持超大的2560×1440像素。 6、有限的系统资源 阅读本书的任何资深程序员可能都会对256 MB内存、8 GB存储空间的机器嗤之以鼻,因为其资源实在是非常有限,但这种机器却是真实存在的。或许,开发iOS应用程序与在内存为48 KB的机器上编写复杂的电子表格应用程序不属于同一级别,二者之间没有可比性,但由于iOS的图形属性和它的功能,其内存不足是非常容易出现的。 目前上市的iOS的物理内存要么是256 MB,要么是512 MB,当然今后内存还会不断增长。内存的一部分用于屏幕缓冲和其他一些系统进程。通常,不到一半(也可能更少)的内存将留给应用程序使用。 虽然这些内存对于这样的小型计算机可能已经足够了,但谈到iOS的内存时还有另一个因素需要考虑:现代计算机操作系统,如Mac OS X,会将一部分未使用的内存块写到磁盘的交换文件中。这样,当应用程序请求的内存超过计算机实际可用的内存时,它仍然可以运行。但是,iOS并不会将易失性内存(如应用程序数据)写到交换文件中。因此,应用程序可用的内存量将受到手机中未使用的物理内存量的限制。 Cocoa Touch提供了一种内置机制,可以将内存不足的情况通知给应用程序。出现这种情况时,应用程序必须释放不需要的内存,甚至可能被强制退出。 7、不支持垃圾收集 之前已经说过,Cocoa Touch使用的是Objective-C 2.0,但该语言中的一个关键特性在iOS中并不可用:Cocoa Touch不支持垃圾收集。 8、新功能 前面提过,Cocoa Touch缺少Cocoa的一些功能,但iOS SDK中也有一些新功能是Cocoa所没有的,或者至少不是在任何Mac上都可用的。 iPhone SDK为应用程序提供了一种定位方法,即用Core Location确定手机的当前地理坐标。 大部分iOS还提供了一个内置的照相机和照片库,并且SDK允许应用程序访问这两者。 iOS还提供了一个内置的加速计(在最新的iPhone、iPod touch中有陀螺仪),用于检测机子的握持和移动方式。 9、与众不同的方法 iOS没有键盘和鼠标,这意味着在编程时它与用户的交互方式和通用的计算机截然不同。所幸的是,大多数交互都不需要你来处理。例如,如果在应用程序中添加一个文本字段,则iOS知道在用户单击该字段时调用键盘,你不需要编写任何额外的代码。 说明目前的设备支持通过蓝牙连接外部键盘,这提供了一种不错的键盘体验并节省了一定的屏幕空间,但这种使用情形仍然非常少。连接鼠标仍然完全行不通。 本文转自麒麟博客园博客,原文链接:http://www.cnblogs.com/zhuqil/archive/2012/05/24/2517176.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

Android被逼学习例子2

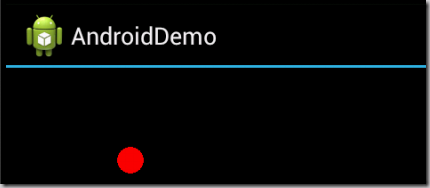
接下来的这个小例子演示当手指在触摸屏上拖动的时候,一个红色的小球更随手指进行移动。不过这个例子大致演示了一下自定义UI组件。 先来看看效果吧: 代码大致如下: AndroidDemoActivity.java package Android.Demo; import android.app.Activity; import android.os.Bundle; import android.provider.ContactsContract.CommonDataKinds.Event; import android.view.MotionEvent; import android.view.View; import android.view.View.OnTouchListener; import android.widget.LinearLayout; public class AndroidDemoActivity extends Activity { /** Called when the activity is first created. */ @Override public void onCreate(Bundle savedInstanceState) { super.onCreate(savedInstanceState); setContentView(R.layout.main); LinearLayout layout = (LinearLayout) findViewById(R.id.root); final DrawView draw = new DrawView(this); draw.setMinimumHeight(300); draw.setMinimumWidth(300); draw.setOnTouchListener(new OnTouchListener() { @Override public boolean onTouch(View arg0, MotionEvent evnet) { // TODO Auto-generated method stub draw.currentX = evnet.getX(); draw.currentY = evnet.getY(); draw.invalidate(); return false; } }); layout.addView(draw); } } DrawView.java代码如下: package Android.Demo; import android.content.Context; import android.graphics.Canvas; import android.graphics.Color; import android.graphics.Paint; import android.view.View; public class DrawView extends View { public DrawView(Context context) { super(context); } @Override protected void onDraw(Canvas canvas) { super.onDraw(canvas); Paint p = new Paint(); p.setColor(Color.RED); canvas.drawCircle(currentX, currentY, 15, p); } public float currentX = 40; public float currentY = 40; } main.xml代码如下: <?xml version="1.0" encoding="utf-8"?> <LinearLayout xmlns:android="http://schemas.android.com/apk/res/android" android:id="@+id/root" android:layout_width="fill_parent" android:layout_height="fill_parent" android:orientation="vertical" > </LinearLayout> ============================================================================== 本文转自被遗忘的博客园博客,原文链接:http://www.cnblogs.com/rollenholt/archive/2012/05/16/2505374.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

Docker Swarm学习教程【转载】

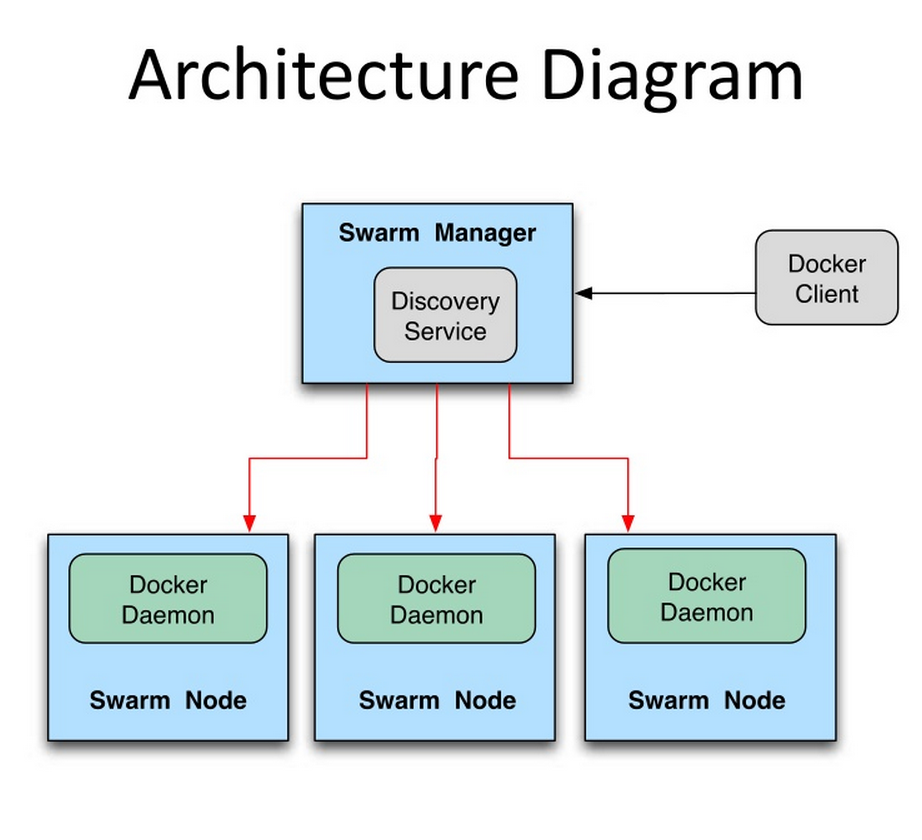
Swarm介绍 Swarm是Docker公司在2014年12月初发布的一套较为简单的工具,用来管理Docker集群,它将一群Docker宿主机变成一个单一的,虚拟的主机。Swarm使用标准的Docker API接口作为其前端访问入口,换言之,各种形式的Docker Client(dockerclient in go, docker_py, docker等)均可以直接与Swarm通信。Swarm几乎全部用Go语言来完成开发,上周五,4月17号,Swarm0.2发布,相比0.1版本,0.2版本增加了一个新的策略来调度集群中的容器,使得在可用的节点上传播它们,以及支持更多的Docker命令以及集群驱动。 Swarm deamon只是一个调度器(Scheduler)和路由器(router),Swarm自己不运行容器,它只是接受docker客户端发送过来的请求,调度适合的节点来运行容器,这意味着,即使Swarm由于某些原因挂掉了,集群中的节点也会照常运行,当Swarm重新恢复运行之后,它会收集重建集群信息。下面是Swarm的结构图: 如何使用Swarm 有3台机器,sclu083,IP地址是10.13.181.83,sclu084,IP地址是10.13.181.84,atsg124 ,IP地址是10.32.105.124,利用这三台机器创建一个Docker集群,其中sclu083同时充当swarm manager管理集群. Swarm安装 最简单的安装Swarm的方式就是用Docker官方提供的Swarm镜像: sudo docker pull swarm Docker集群管理需要服务发现(Discovery service backend)功能.Swarm支持以下几种discovery service backend:Docker Hub上面内置的服务发现功能,本地的静态文件描述集群(static file describing the cluster),etcd(顺带说一句,etcd这玩意貌似很火很有前途,有时间研究下),consul,zookeeper和一些静态的ip列表(a static list of ips).本文会详细介绍前面两种方法backend的使用。 在使用Swarm进行集群管理之前,需要先把准备加入集群的所有的节点的docker deamon的监听端口修改为0.0.0.0:2375,可以直接使用 sudo docker –H tcp://0.0.0.0:2375 &命令,也可以在配置文件中修改 sudo vim /etc/default/docker 在文件的最后面添加下面这句 D0OCKER_OPTS=”-H 0.0.0.0:2375 –H unix:///var/run/docker.sock” 注意:一定是要在所有的节点上进行修改,修改之后要重启docker deamon sudo service docker restart 第一种方法:使用Docker Hub上面内置的服务发现功能 第一步:在任何一台节点上面执行swarm create命令来创建一个集群标志。这条命令执行完毕之后,swarm会前往Docker Hub上内建的发现服务中获取一个全球唯一的token,用以唯一的标识swarm管理的Docker集群。 sudo docker run –-rm swarm create 我们在sclu084 这台机器上执行上面的命令,效果如下: 返回的token是d947b55aa8fb9198b5d13ad81f61ac4d,这个token一定要记住,因为接下来的操作都会用到这一个token。 第二步:在所有的要加入集群的机器上面执行swarm join命令,把机器加入集群 本次试验就是要在所有的三台机器上执行命令: sudo docker run –-rm swarm join –addr=ip_address:2375 token://d947b55aa8fb9198b5d13ad81f61ac4d 在IP地址为10.13.181.84机器上面执行的效果如下图: 执行这条命令后不会立即返回 ,我们手动通过Ctrl+C返回。 第三步:启动swarm manager 因为我们是要让sclu083充当Swarm管理节点,所以我们要在这条机器上面执行swarm manage这条命令: sudo docker run –d –p 2376:2375 swarm manage token:// d947b55aa8fb9198b5d13ad81f61ac4d 需要注意的是:在这条命令中,第一:要以daemon的形式运行swarm。第二:端口映射:2376可以更换成任何一个本机没有占用的端口,一定不能是2375。否则就会出问题。 执行结果如下如所示: 执行完这个命令之后,整个集群已经启动起来了。 现在可以在任何一台节点上查看集群上的所有节点了。 之后可以在任何一台安装了docker的机器上面通过命令(命令中要指明swarm maneger 机器的IP地址和端口)在这个集群上面运行Dcoker容器操作。 现在在10.13.181.85这台机器上面查看集群的节点的信息。info命令可以换成任何一个Swarm支持的docker命令,这些命令可以查看官方文档 sudo docker –H 10.13.181.83:2376 info 由上图的结果,我们可以发现一个问题:明明这个小集群中是有3个节点的,但是info命令只显示了2个节点。还缺少节点10.32.105.124。为什么会出现这个情况呢? 因为10.32.105.124这台机器没有设置上面的docker daemon监听0.0.0.0:2375这个端口,所以Swarm没办法吧这个节点加入集群中来。 在使用Docker Hub内置的发现服务时,会出现一个问题,就是使用swarm create时会出现 time="2015-04-21T08:56:25Z" level=fatal msg="Get https://discovery-stage.hub.docker.com/v1/clusters/d947b55aa8fb9198b5d13ad81f61ac4d: dial tcp: i/o timeout" 类似于这样的错误,不知道是什么原因,有待解决。 当使用Docker Hub内置的服务发现功能出现问题时,可以使用下面的第二种方法。 第二种方法:使用文件 第二种方法相对而言比第一种方法要简单,也更不容易出现timeout的问题。 第一步:在sclu083这台机器上新建一个文件,把要加入集群的机器的IP地址写进去 第二步:在sclu083这台机器上面执行swarm manage命令: sudo docker run –d –p 2376:2375 –v $(pwd)/cluster:/tmp/cluster swarm manage file:///tmp/cluster 注意:这里一定要使用-v命令,因为cluster文件是在本机上面,启动的容器默认是访问不到的,所以要通过-v命令共享。还有,file:///千万不能忘记了 可以看到,swarm已经运行起来了。现在可以查看下集群节点信息了,使用命令: sudo docker run –rm –v $(pwd)/cluster:/tmp/cluster swarm list file:///tmp/cluster (在使用文件作为服务发现的时候,貌似manage list命令只能在swarm manage节点上使用,在其他节点上好像是用不了) 好了,现在集群也已经运行起来了,可以跟第一种方法一样在其他机器上使用集群了。同样在sclu085 机器上做测试: 可以看到,成功访问并且节点信息是正确的。接下来可以把上面的info命令替换成其他docker可执行命令来使用这个晓得Docker集群了。 Swarm调度策略 Swarm在schedule节点运行容器的时候,会根据指定的策略来计算最适合运行容器的节点,目前支持的策略有:spread,binpack,random. Random顾名思义,就是随机选择一个Node来运行容器,一般用作调试用,spread和binpack策略会根据各个节点的可用的CPU,RAM以及正在运行的容器的数量来计算应该运行容器的节点。 在同等条件下,Spread策略会选择运行容器最少的那台节点来运行新的容器,binpack策略会选择运行容器最集中的那台机器来运行新的节点(The binpack strategy causes Swarm to optimize for the container which is most packed.)。 使用Spread策略会使得容器会均衡的分布在集群中的各个节点上运行,一旦一个节点挂掉了只会损失少部分的容器。 Binpack策略最大化的避免容器碎片化,就是说binpack策略尽可能的把还未使用的节点留给需要更大空间的容器运行,尽可能的把容器运行在一个节点上面。 Constraint Filter 通过label来在指定的节点上面运行容器。这些label是在地洞docker daemon时指定的,也可以卸载/etc/default/docker这个配置文件里面。 sudo docker run –H 10.13.181.83:2376 run –name redis_083 –d –e constraint:label==083 redis Affinity Filter 使用-e affinity:container==container_name / container_id –-name container_1可以让容器container_1紧挨着容器container_name / container_id执行,也就是说两个容器在一个node上面执行(You can schedule 2 containers and make the container #2 next to the container #1.) 先在一台机器上启动一个容器 sudo docker -H 10.13.181.83:2376 run --name redis_085 -d -e constraint:label==085 redis 接下来启动容器redis_085_1,让redis_085_1紧挨着redis_085容器运行,也就是在一个节点上运行 sudo docker –H 10.13.181.83:2376 run –d –name redis_085_1 –e affinity:container==redis_085 redis 通过-e affinity:image=image_name命令可以指定只有已经下载了image_name的机器才运行容器(You can schedule a container only on nodes where the images are already pulled) 下面命令在只有redis镜像的节点上面启动redis容器: sudo docker –H 100.13.181.83:2376 run –name redis1 –d –e affinity:image==redis redis 下面这条命令达到的效果是:在有redis镜像的节点上面启动一个r名字叫做redis的容器,如果每个节点上面都没有redis容器,就按照默认的策略启动redis容器。 sudo docker -H 10.13.181.83:2376 run -d --name redis -e affinity:image==~redis redis Port filterPort也会被认为是一个唯一的资源 sudo docker -H 10.13.181.83:2376 run -d -p 80:80 nginx 执行完这条命令,任何使用80端口的容器都是启动失败。 结束语: 本文详细介绍了两种方法来使用Swarm管理Docker集群。但是Swarm是一个比较新的项目,目前还处于研发阶段,Swarm的发展十分快速,功能和特性的变更迭代还非常频繁。因此,可以说Swarm还不推荐被用于生产环境中,但可以肯定的是Swarm是一项很有前途的技术。 最近在学Go,准备抽时间好好研究下Swarm源码。Go是一门很有前途的语言。

优秀的个人博客,低调大师

Docker Toolbox 学习教程【转载】

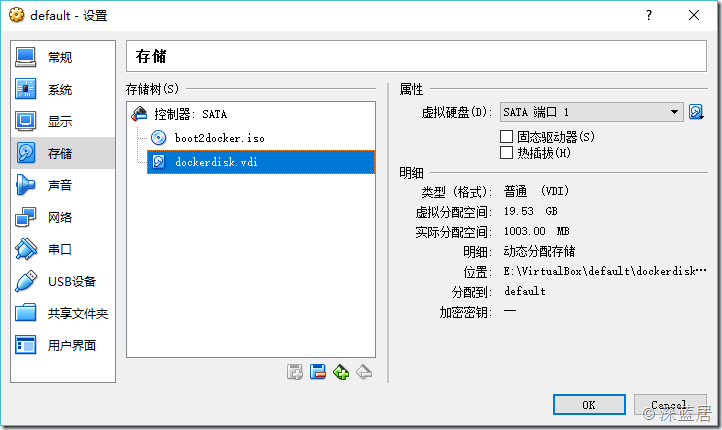
最近在研究虚拟化,容器和大数据,所以从Docker入手,下面介绍一下在Windows下怎么玩转Docker。Docker本身在Windows下有两个软件,一个就是Docker,另一个是Docker Toolbox。这里我选择的是Docker Toolbox,为什么呢?参见官方文档:https://blog.docker.com/2015/08/docker-toolbox/首先我们从官网下载最新版的Windows Docker Toolbox。安装后会安装一个VirtualBox虚拟机,一个Kitematic,这是GUI管理Docker的工具,没有发布正式版,不推荐使用,另外还有就是我们在命令行下用到的docker-machine和docker命令了。 基本使用 安装完成Toolbox后会有一个Docker Quickstart Terminal的快捷方式,双击运行如果报错,那可能是因为你已经安装了Hyper-v,所以VirtualBox无法用64位的虚拟机。需要卸载Hyper-v。 运行后会在Virtualbox中创建一个叫做default的虚拟机,然后很有可能会卡在waiting for an IP的命令下,然后就死活不动了。我的做法是彻底放弃Docker Quickstart Terminal,根本不用这玩意儿,关掉,我们用PowerShell进行虚拟机的管理。 打开PowerShell,输入: docker-machine ls 我们可以看到我们当前的Docker虚拟机的状态。如果什么都没有的话,那么我们可以使用以下命令创建一个Docker虚拟机。 docker-machine create --driver=virtualbox default 创建完毕后,我们在用docker-machine ls确认我们的Docker虚拟机在运行中。 然后使用以下命令获得虚拟机的环境变量: docker-machine env default 然后再输入: docker-machine env default | Invoke-Expression 这样我们就把当前的PowerShell和虚拟机里面的Docker Linux建立的连接,接下来就可以在PowerShell中使用docker命令了。 比如我们要查看当前有哪些镜像: docker images 当前有哪些容器: docker ps –a 其他各种docker命令我就不在这里累述了。 Docker虚拟机文件地址修改 默认情况下,docker-machine创建的虚拟机文件,是保存在C盘的C:\Users\用户名\.docker\machine\machines\default 目录下的,如果下载和使用的镜像过多,那么必然导致该文件夹膨胀过大,如果C盘比较吃紧,那么我们就得考虑把该虚拟机移到另一个盘上。具体操作如下: 1.使用docker-machine stop default停掉Docker的虚拟机。 2.打开VirtualBox,选择“管理”菜单下的“虚拟介质管理”,我们可以看到Docker虚拟机用的虚拟硬盘的文件disk。 3.选中“disk”,然后点击菜单中的“复制”命令,根据向导,把当前的disk复制到另一个盘上面去。 4.回到VirtualBox主界面,右键“default”这个虚拟机,选择“设置”命令,在弹出的窗口中选择“存储”选项。 5.把disk从“控制器SATA”中删除,然后重新添加我们刚才复制到另外一个磁盘上的那个文件。 这是我设置好后的界面,可以看到我在步骤3复制的时候,复制到E:\VirtualBox\default\dockerdisk.vdi文件去了。 6.确定,回到PowerShell,我们使用docker-machine start default就可以启动新地址的Docker虚拟机了。确保新磁盘的虚拟机没有问题。就可以把C盘那个disk文件删除了。 【注意:不要在Window中直接去复制粘贴disk文件,这样会在步骤5的时候报错的,报错的内容如下,所以一定要在VirtualBox中去复制!】 Failed to open the hard disk file D:\Docker\boot2docker-vm\boot2docker-vm.vmdk. Cannot register the hard disk 'D:\Docker\boot2docker-vm\boot2docker-vm.vmdk' {9a4ed2ae-40f7-4445-8615-a59dccb2905c} because a hard disk C:\Users\用户名\.docker\machine\machines\default\disk.vmdk' with UUID {9a4ed2ae-40f7-4445-8615-a59dccb2905c} already exists. Result Code: E_INVALIDARG (0x80070057) Component: VirtualBox Interface: IVirtualBox {fafa4e17-1ee2-4905-a10e-fe7c18bf5554} Callee RC: VBOX_E_OBJECT_NOT_FOUND (0x80BB0001) 镜像加速 在国内使用Docker Hub的话就特别慢,为此,我们可以给Docker配置国内的加速地址。我看了一下,DaoCloud和阿里云的镜像加速还不错,另外还有网易的蜂巢。选一个就行了。以DaoClound为例,注册账号,然后在https://www.daocloud.io/mirror就可以看到DaoClound提供给您的镜像加速的URL。然后到PowerShell中去依次执行: docker-machine ssh default sudo sed -i "s|EXTRA_ARGS='|EXTRA_ARGS='--registry-mirror=加速地址 |g" /var/lib/boot2docker/profile exit docker-machine restart default 这样重启Docker后就可以用国内的镜像来加速下载了。 试一下下载一个mysql看看快不快: docker pull mysql 下载完镜像,我们运行一个容器: docker run -d -p 3306:3306 --name mysql -e MYSQL_ROOT_PASSWORD=123 mysql:latest 接下来我们打开windows下的mysql客户端,服务器地址填docker虚拟机的IP地址,通过docker-machine env可以看到,我这里是192.168.99.100,然后用户名root,密码123,这样我们就可以连接到docker容器里面的mysql了。 【注意,Docker容器是在VirtualBox的虚拟机里面,不是在Windows里面,所以不能用127.0.0.1访问】

资源下载

更多资源
Mario

Mario

马里奥是站在游戏界顶峰的超人气多面角色。马里奥靠吃蘑菇成长,特征是大鼻子、头戴帽子、身穿背带裤,还留着胡子。与他的双胞胎兄弟路易基一起,长年担任任天堂的招牌角色。

Nacos

Nacos

Nacos /nɑ:kəʊs/ 是 Dynamic Naming and Configuration Service 的首字母简称,一个易于构建 AI Agent 应用的动态服务发现、配置管理和AI智能体管理平台。Nacos 致力于帮助您发现、配置和管理微服务及AI智能体应用。Nacos 提供了一组简单易用的特性集,帮助您快速实现动态服务发现、服务配置、服务元数据、流量管理。Nacos 帮助您更敏捷和容易地构建、交付和管理微服务平台。

Spring

Spring

Spring框架(Spring Framework)是由Rod Johnson于2002年提出的开源Java企业级应用框架,旨在通过使用JavaBean替代传统EJB实现方式降低企业级编程开发的复杂性。该框架基于简单性、可测试性和松耦合性设计理念,提供核心容器、应用上下文、数据访问集成等模块,支持整合Hibernate、Struts等第三方框架,其适用范围不仅限于服务器端开发,绝大多数Java应用均可从中受益。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

用户登录
用户注册