首页 文章 精选 留言 我的

精选列表

搜索[python解释器],共10000篇文章
优秀的个人博客,低调大师

python插入排序

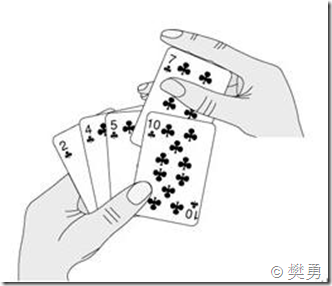
插入排序(Insertion Sort)的基本思想是:将列表分为2部分,左边为排序好的部分,右边为未排序的部分,循环整个列表,每次将一个待排序的记录,按其关键字大小插入到前面已经排好序的子序列中的适当位置,直到全部记录插入完成为止。 插入排序非常类似于整扑克牌。 在开始摸牌时,左手是空的,牌面朝下放在桌上。接着,一次从桌上摸起一张牌,并将它插入到左手一把牌中的正确位置上。为了找到这张牌的正确位置,要将它与手中已有的牌从右到左地进行比较。无论什么时候,左手中的牌都是排好序的。 也许你没有意识到,但其实你的思考过程是这样的:现在抓到一张7,把它和手里的牌从右到左依次比较,7比10小,应该再往左插,7比5大,好,就插这里。为什么比较了10和5就可以确定7的位置?为什么不用再比较左边的4和2呢?因为这里有一个重要的前提:手里的牌已经是排好序的。现在我插了7之后,手里的牌仍然是排好序的,下次再抓到的牌还可以用这个方法插入。编程对一个数组进行插入排序也是同样道理,但和插入扑克牌有一点不同,不可能在两个相邻的存储单元之间再插入一个单元,因此要将插入点之后的数据依次往后移动一个单元。 source = [92, 77, 67, 8, 6, 84, 55, 85, 43, 67] for index in range(1,len(source)): current_val = source[index] #先记下来每次大循环走到的第几个元素的值 position = index while position > 0 and source[position-1] > current_val: #当前元素的左边的紧靠的元素比它大,要把左边的元素一个一个的往右移一位,给当前这个值插入到左边挪一个位置出来 source[position] = source[position-1] #把左边的一个元素往右移一位 position -= 1 #只一次左移只能把当前元素一个位置 ,还得继续左移只到此元素放到排序好的列表的适当位置 为止 source[position] = current_val #已经找到了左边排序好的列表里不小于current_val的元素的位置,把current_val放在这里 print(source) 结果: [77, 92, 67, 8, 6, 84, 55, 85, 43, 67] [67, 77, 92, 8, 6, 84, 55, 85, 43, 67] [8, 67, 77, 92, 6, 84, 55, 85, 43, 67] [6, 8, 67, 77, 92, 84, 55, 85, 43, 67] [6, 8, 67, 77, 84, 92, 55, 85, 43, 67] [6, 8, 55, 67, 77, 84, 92, 85, 43, 67] [6, 8, 55, 67, 77, 84, 85, 92, 43, 67] [6, 8, 43, 55, 67, 77, 84, 85, 92, 67] [6, 8, 43, 55, 67, 67, 77, 84, 85, 92] #更容易理解的版本 data_set = [ 9,1,22,9,31,-5,45,3,6,2,11 ] for i in range(len(data_set)): #position = i while i > 0 and data_set[i] < data_set[i-1]:# 右边小于左边相邻的值 tmp = data_set[i] data_set[i] = data_set[i-1] data_set[i-1] = tmp i -= 1 # position = i # while position > 0 and data_set[position] < data_set[position-1]:# 右边小于左边相邻的值 # tmp = data_set[position] # data_set[position] = data_set[position-1] # data_set[position-1] = tmp # position -= 1
优秀的个人博客,低调大师

python构造IP报文

import socket import sys import time import struct HOST, PORT = "10.60.66.66", 10086 def make_forward_iphdr(source_ip = '1.0.0.1', dest_ip = '2.0.0.2', proto = socket.IPPROTO_UDP) : # ip header fields ip_ihl = 5 ip_ver = 4 ip_tos = 0 ip_tot_len = 0 # kernel will fill the correct total length ip_id = 54321 #Id of this packet ip_frag_off = 0 ip_ttl = 255 ip_proto = proto ip_check = 0 # kernel will fill the correct checksum ip_saddr = socket.inet_aton ( source_ip ) #Spoof the source ip address if you want to ip_daddr = socket.inet_aton ( dest_ip ) ip_ihl_ver = (ip_ver << 4) + ip_ihl # the ! in the pack format string means network order ip_header = struct.pack('!BBHHHBBH4s4s', ip_ihl_ver, ip_tos, ip_tot_len, ip_id, ip_frag_off, ip_ttl, ip_proto, ip_check, ip_saddr, ip_daddr) return ip_header def make_forward_udphdr(src_port = 1024, dst_port = 10086) : udp_header = struct.pack('!HHHH', src_port, dst_port, 0, 0) return udp_header # checksum functions needed for calculation checksum def checksum(msg): s = 0 # loop taking 2 characters at a time for i in range(0, len(msg), 2): w = ord(msg[i]) + (ord(msg[i+1]) << 8 ) s = s + w s = (s>>16) + (s & 0xffff); s = s + (s >> 16); #complement and mask to 4 byte short s = ~s & 0xffff return s def make_tcp_data(ip_header, src_port = 1024, dst_port = 10086, source_ip='1.0.0.1', dest_ip='2.0.0.2', user_data = 'test') : tcp_source = src_port # source port tcp_dest = dst_port # destination port tcp_seq = 454 tcp_ack_seq = 0 tcp_doff = 5 #4 bit field, size of tcp header, 5 * 4 = 20 bytes #tcp flags tcp_fin = 0 tcp_syn = 1 tcp_rst = 0 tcp_psh = 0 tcp_ack = 0 tcp_urg = 0 tcp_window = socket.htons (5840) # maximum allowed window size tcp_check = 0 tcp_urg_ptr = 0 tcp_offset_res = (tcp_doff << 4) + 0 tcp_flags = tcp_fin + (tcp_syn << 1) + (tcp_rst << 2) + (tcp_psh <<3) + (tcp_ack << 4) + (tcp_urg << 5) # the ! in the pack format string means network order tcp_header = struct.pack('!HHLLBBHHH' , tcp_source, tcp_dest, tcp_seq, tcp_ack_seq, tcp_offset_res, tcp_flags, tcp_window, tcp_check, tcp_urg_ptr) source_address = socket.inet_aton(source_ip) dest_address = socket.inet_aton(dest_ip) placeholder = 0 protocol = socket.IPPROTO_TCP tcp_length = len(tcp_header) + len(user_data) psh = struct.pack('!4s4sBBH' , source_address , dest_address , placeholder , protocol , tcp_length); psh = psh + tcp_header + user_data; tcp_check = checksum(psh) #print tcp_checksum # make the tcp header again and fill the correct checksum - remember checksum is NOT in network byte order tcp_header = struct.pack('!HHLLBBH' , tcp_source, tcp_dest, tcp_seq, tcp_ack_seq, tcp_offset_res, tcp_flags, tcp_window) + struct.pack('H' , tcp_check) + struct.pack('!H' ,tcp_urg_ptr) # final full packet - syn packets dont have any data packet = ip_header + tcp_header + user_data return packet

优秀的个人博客,低调大师

[Spark][Python]PageRank 程序

PageRank 程序: file contents: page1 page3 page2 page1 page4 page1 page3 page1 page4 page2 page3 page4 def computeContribs(neighbors,rank): for neighbor in neighbors: yield( neighbor, rank/len(neighbors) ) links = sc.textFile("tst001.txt").map(lambda line: line.split()).map(lambda pages: (pages[0],pages[1]))\ .distinct().groupByKey().persist() ranks=links.map(lambda (page,neighbors): (page,1.0) ) In [4]: for x in range(1): ...: print "links count:"+links.count() ...: print "ranks count:" ranks.count() In [11]: for x in range(3): ....: contribs=links.join(ranks).flatMap( lambda (page,(neighbors,rank)): computeContribs(neighbors,rank) ) ....: ranks=contribs.reduceByKey(lambda v1,v2: v1+v2).map(lambda (page,contrib): (page,contrib*0.85+0.15)) ....: for rank in ranks.collect(): print rank (u'page2', 0.394375) (u'page3', 1.2619062499999998) (u'page4', 0.8820624999999999) (u'page1', 1.4616562499999997) 本文转自健哥的数据花园博客园博客,原文链接:http://www.cnblogs.com/gaojian/p/7614711.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

python异常继承树

BaseException + - - SystemExit + - - KeyboardInterrupt + - - GeneratorExit + - - Exception + - - StopIteration + - - StandardError | + - - BufferError | + - - ArithmeticError | | + - - FloatingPointError | | + - - OverflowError | | + - - ZeroDivisionError | + - - AssertionError | + - - AttributeError | + - - EnvironmentError | | + - - IOError | | + - - OSError | | + - - WindowsError (Windows) | | + - - VMSError (VMS) | + - - EOFError | + - - ImportError | + - - LookupError | | + - - IndexError | | + - - KeyError | + - - MemoryError | + - - NameError | | + - - UnboundLocalError | + - - ReferenceError | + - - RuntimeError | | + - - NotImplementedError | + - - SyntaxError | | + - - IndentationError | | + - - TabError | + - - SystemError | + - - TypeError | + - - ValueError | + - - UnicodeError | + - - UnicodeDecodeError | + - - UnicodeEncodeError | + - - UnicodeTranslateError + - - Warning + - - DeprecationWarning + - - PendingDeprecationWarning + - - RuntimeWarning + - - SyntaxWarning + - - UserWarning + - - FutureWarning + - - ImportWarning + - - UnicodeWarning + - - BytesWarning ============================================================================== 本文转自被遗忘的博客园博客,原文链接:http://www.cnblogs.com/rollenholt/archive/2011/11/25/2263724.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

Python-字典遍历

遇到个小问题: 我将十本书的[书名列表]赋值给字典的title键值,将[作者列表]赋值给‘author’键值。现在想一个书名,一个作者的输出。使用嵌套循环遍历一共得到了10*10=100次书名和作者(笑)。 for ti,au in dic[‘title’],dic[‘author’]: 这是我下意识写出的一行代码,然而不能这样遍历。又改成dic[‘title’,’author’]也不可以,有没有会的兄台可以指点我一下。尝试了如下: f.open(‘f:\book.txt’,’a’) for i in f.readlines: #报错,不可遍历 for ti in dic[‘title’]: 看来只能在Excel中输出了。 2018.1.9 更新: 或者直接再将字典单个键的 value 赋值给一个新list,再通过list遍历。 2018.1.15更新: list1 = [ 1, 2, 3] list2 = ['a','b','c',] d = zip(list1,list2) dic1 = dict(d) for i,j in dic1.items(): print (i,j) 结果图: ​

资源下载

更多资源
腾讯云软件源

腾讯云软件源

为解决软件依赖安装时官方源访问速度慢的问题,腾讯云为一些软件搭建了缓存服务。您可以通过使用腾讯云软件源站来提升依赖包的安装速度。为了方便用户自由搭建服务架构,目前腾讯云软件源站支持公网访问和内网访问。

Spring

Spring

Spring框架(Spring Framework)是由Rod Johnson于2002年提出的开源Java企业级应用框架,旨在通过使用JavaBean替代传统EJB实现方式降低企业级编程开发的复杂性。该框架基于简单性、可测试性和松耦合性设计理念,提供核心容器、应用上下文、数据访问集成等模块,支持整合Hibernate、Struts等第三方框架,其适用范围不仅限于服务器端开发,绝大多数Java应用均可从中受益。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

WebStorm

WebStorm

WebStorm 是jetbrains公司旗下一款JavaScript 开发工具。目前已经被广大中国JS开发者誉为“Web前端开发神器”、“最强大的HTML5编辑器”、“最智能的JavaScript IDE”等。与IntelliJ IDEA同源,继承了IntelliJ IDEA强大的JS部分的功能。

用户登录
用户注册