ES BM25 TF-IDF相似度算法设置——
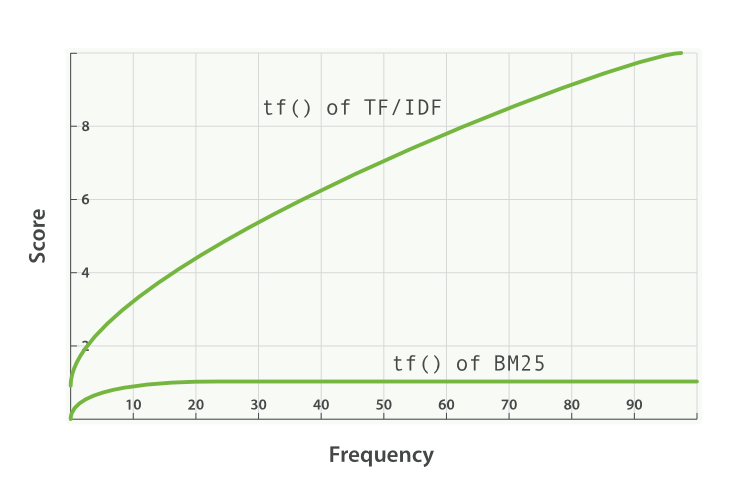
Pluggable Similarity Algorithms Before we move on from relevance and scoring, we will finish this chapter with a more advanced subject: pluggable similarity algorithms.While Elasticsearch uses theLucene’s Practical Scoring Functionas its default similarity algorithm, it supports other algorithms out of the box, which are listed in theSimilarity Modulesdocumentation. Okapi BM25 The most interesting competitor to TF/IDF and the vector space model is calledOkapi BM25, which is considered to be astate-of-the-artranking function.BM25 originates from theprobabilistic relevance model, rather than the vector space model, yetthe algorithm has a lot in common with Lucene’s practical scoring function. Both use term frequency, inverse document frequency, and field-length normalization, but the definition of each of these factors is a little different. Rather than explaining the BM25 formula in detail, we will focus on the practical advantages that BM25 offers. Term-frequency saturation Both TF/IDF and BM25 useinverse document frequencyto distinguish between common (low value) words and uncommon (high value) words.Both also recognize (seeTerm frequency) that the more often a word appears in a document, the more likely is it that the document is relevant for that word. However, common words occur commonly.The fact that a common word appears many times in one document is offset by the fact that the word appears many times inalldocuments. However, TF/IDF was designed in an era when it was standard practice to remove themostcommon words (orstopwords, seeStopwords: Performance Versus Precision) from the index altogether.The algorithm didn’t need to worry about an upper limit for term frequency because the most frequent terms had already been removed. In Elasticsearch, thestandardanalyzer—the default forstringfields—doesn’t remove stopwordsbecause, even though they are words of little value, they do still have some value. The result is that, for very long documents, the sheer number of occurrences of words liketheandandcan artificially boost their weight. BM25, on the other hand, does have an upper limit. Terms that appear 5 to 10 times in a document have a significantly larger impact on relevance than terms that appear just once or twice. However, as can be seen inFigure34, “Term frequency saturation for TF/IDF and BM25”, terms that appear 20 times in a document have almost the same impact as terms that appear a thousand times or more. This is known asnonlinear term-frequency saturation. Figure34.Term frequency saturation for TF/IDF and BM25 Field-length normalization InField-length norm, we said that Lucene considers shorter fields to have more weight than longer fields: the frequency of a term in a field is offset by the length of the field. However, the practical scoring function treats all fields in the same way.It will treat alltitlefields (because they are short) as more important than allbodyfields (because they are long). BM25 also considers shorter fields to have more weight than longer fields, but it considers each field separately by taking the average length of the field into account. It can distinguish between a shorttitlefield and alongtitle field. InQuery-Time Boosting, we said that thetitlefield has anaturalboost over thebodyfield because of its length. This natural boost disappears with BM25 as differences in field length apply only within a single field. 摘自:https://www.elastic.co/guide/en/elasticsearch/guide/current/pluggable-similarites.html 本文转自张昺华-sky博客园博客,原文链接:http://www.cnblogs.com/bonelee/p/6472820.html ,如需转载请自行联系原作者