首页 文章 精选 留言 我的

精选列表

搜索[匹配算法],共10000篇文章
优秀的个人博客,低调大师

leetcode算法题解(Java版)-14-第k小数问题

一、第k小数问题 题目描述 There are two sorted arrays A and B of size m and n respectively. Find the median of the two sorted arrays. The overall run time complexity should be O(log (m+n)). 思路 题目要求在O(log(m+n))时间内完成,可以转换为找到假设两个数组合并后的第(m+n)/2小的数。 这里先忽略奇偶问题,具体实现代码中会有不同。先假设A和B中的数都大于k/2,比较A[k/2-1]和B[k/2-1](减1是因为数组下标从零开始)如果A[k/2-1] 代码 public class Solution { public double findMedianSortedArrays(int A[], int B[]) { //奇偶数不会有影响,最后中位数就是平均值 int m = A.length,n = B.length; int l = (m+n+1)/2; int r = (m+n+2)/2; return (findKthNum(A,B,0,0,l)+findKthNum(A,B,0,0,r))/2.0; } private double findKthNum(int [] A,int [] B,int Astart,int Bstart,int k){ int lenA = A.length; int lenB = B.length; if(Astart>=lenA){ return B[Bstart+k-1]; } if(Bstart>=lenB){ return A[Astart+k-1]; } if(k==1){ return Math.min(A[Astart],B[Bstart]); } int minA = Integer.MAX_VALUE; int minB = Integer.MAX_VALUE; if(Astart+k/2-1<A.length){ //如果这里超过了A数组的范围,那就说明A中有将A、B合并后一半以上的 //数,也就是说中位数肯定在A中。那后面的minB<minA(MAX_VALUE),就会成立,从而舍弃B中的前一些无关的数 minA = A[Astart+k/2-1]; } if(Bstart+k/2-1<B.length){ minB = B[Bstart+k/2-1]; } if(minA<minB){ return findKthNum(A,B,Astart+k/2,Bstart,k-k/2); } else{ return findKthNum(A,B,Astart,Bstart+k/2,k-k/2); } } } 二、map映射 题目描述 Given an array of integers, find two numbers such that they add up to a specific target number. The function twoSum should return indices of the two numbers such that they add up to the target, where index1 must be less than index2. Please note that your returned answers (both index1 and index2) are not zero-based. You may assume that each input would have exactly one solution. Input: numbers={2, 7, 11, 15}, target=9Output: index1=1, index2=2 思路 给一列数,给一个目标值,找出数列中两个数和为这个值的下标。因为数没有排序,可以考虑用map来构建数值和下标的映射,更狠一点,在遍历数组的同时,用map构建目标值减去当前这个数的值与当前下标的映射,然后对每一个遍历到的数判断是否已存在在map中。 代码 import java.util.HashMap; public class Solution { public int[] twoSum(int[] numbers, int target) { int n = numbers.length; int [] res = new int [2]; HashMap<Integer,Integer> map = new HashMap<Integer,Integer>(); for(int i=0 ;i<n;i++){ if(map.containsKey(numbers[i])){ res[0]=map.get(numbers[i])+1; res[1]=i+1; break; } else{ map.put(target-numbers[i],i); } } return res; } } 三、动态规划 题目描述 You are climbing a stair case. It takes n steps to reach to the top. Each time you can either climb 1 or 2 steps. In how many distinct ways can you climb to the top? 思路 题目提示了用动态规划来解,那自然想到从step 1,2,3,.。于是慢慢推了看看,看是否能得到状态转移方程。写了几个,发现:dp[i]=dp[i-1]+dp[i-2]; 代码 public class Solution { public int climbStairs(int n) { int [] dp = new int[n+2]; dp[1]=1; dp[2]=2; for(int i=3;i<=n;i++){ dp[i]=dp[i-1]+dp[i-2]; } return dp[n]; } } //优化一下空间复杂度 public class Solution { public int climbStairs(int n) { if(n<=2){ return n; } int one_step_before=2; int two_step_before=1; for(int i=3;i<=n;i++){ int cur = one_step_before+two_step_before; two_step_before = one_step_before; one_step_before = cur; } return one_step_before; } }

优秀的个人博客,低调大师

leetcode算法题解(Java版)-8-动态规划+状态压缩

一、树 题目描述 Given a binary tree struct TreeLinkNode { TreeLinkNode *left; TreeLinkNode *right; TreeLinkNode *next; } Populate each next pointer to point to its next right node. If there is no next right node, the next pointer should be set toNULL. Initially, all next pointers are set toNULL. Note: You may only use constant extra space. You may assume that it is a perfect binary tree (ie, all leaves are at the same level, and every parent has two children). For example,Given the following perfect binary tree, 1 / \ 2 3 / \ / \ 4 5 6 7 After calling your function, the tree should look like: 1 -> NULL / \ 2 -> 3 -> NULL / \ / \ 4->5->6->7 -> NULL 思路 题目的意思可能看文字有点不明白,没关系!看明白它给的两个图就行了,就是图上描绘的意思。 这道题有点像链表,二叉树中多了个链表,其实解法也应该往链表上去想,一般考虑用两个指针一个当前的,控制外部循环,一个是移动的,控制内部小循环。二叉树不断往下走,一边走一边从左向右实现同一层节点之间链表的链接 代码 /** * Definition for binary tree with next pointer. * public class TreeLinkNode { * int val; * TreeLinkNode left, right, next; * TreeLinkNode(int x) { val = x; } * } */ public class Solution { public void connect(TreeLinkNode root) { if(root==null){ return; } TreeLinkNode p=root; TreeLinkNode q=root; while(p.left!=null){ q=p; while(q!=null){ q.left.next=q.right; if(q.next!=null){ q.right.next=q.next.left; } q=q.next; } p=p.left; } return; } } 二、动态规划 题目描述 Given a string S and a string T, count the number of distinct subsequences of T in S. A subsequence of a string is a new string which is formed from the original string by deleting some (can be none) of the characters without disturbing the relative positions of the remaining characters. (ie,"ACE"is a subsequence of"ABCDE"while"AEC"is not). Here is an example:S ="rabbbit", T ="rabbit" Return3. 思路 又是典型的动态规划~~重新的复习了一下: 动态规划: 参考:CSDN 动态规划解题的一般思路: 将原问题分解为子问题:子问题和原问题类似 确定状态:即是dp数组,存储了子问题的状态 确定初始状态(边界)的值:这个需要想一下,但其实一般都是由套路的,比如都是0或者都是1。实在不知道,可以用几个值试一试 写出状态转移方程 动态规划解题的特点: 问题具有最优子结构:如果原问题的最优解也是子问题的最优解。 无后效性:当前的状态之和它之前的某些特定位置的状态有关,和路径等无关,即后来产生的值不会影响前面已经确定的值。 回到题目中来 好了,那么来看这一道题:首先可以分解为子问题,而且子问题的最优解也是原问题的最优解。 dpi就是所谓的子问题,也是状态空间,表示S[0~i-1]中包含的T[0~j-1]的subsequences(这个定义看题目)数目。然后具体分析请看代码 推荐在草稿画出dp数组,一边看代码一边填dp。 代码 public class Solution { public int numDistinct(String S, String T) { int lenS=S.length(); int lenT=T.length(); if(lenS==0||lenT==0){ return 0; } int row=lenS+1; int col=lenT+1; int [][] dp=new int [row][col]; for(int i=1;i<col;i++){ dp[0][i]=0; } for(int j=0;j<row;j++){ dp[j][0]=1; } for(int i=1;i<row;i++){ //这里在纸上画字符串数组分析的时候,把字符串的下表可以从“1”开始,便于思维理解 for(int j=1;j<col;j++){ if(S.charAt(i-1)==T.charAt(j-1)){ dp[i][j]=dp[i-1][j-1]+dp[i-1][j];//这里可能稍微难理解, //要记住这一步的目的是解决字符串可以是不连续的,只要满足在原来串中顺序不变即可称为subsequence //结合这个区想这一步为啥这么相加,就能理解了,我是用这个笨方法想的。。。 } else{ dp[i][j]=dp[i-1][j];//既然S[i-1]和T[j-1]不一样,那么不妨不要S[i], //可不能也不要T[j]噢,因为我们的目标是找到S中包含T的所有subsequences } } } return dp[row-1][col-1]; } } 状态压缩+细节优化过的代码详细见代码注释,动态规划一般都是可以压缩一下状态的。 public class Solution { public int numDistinct(String S, String T) { int lenS=S.length(); int lenT=T.length(); if(lenS==0||lenT==0){ return 0; } int col=lenT+1; int row=lenS+1; int dp[]=new int[col]; for(int i=0;i<col;i++){ if(i==0){ dp[i]=1; continue; } dp[i]=0; } for(int i=1;i<row;i++){ for(int j=j=Math.min(i,col-1);j>0;j--){ //其实这里还能再优化,写成 "j=Math.min(i,col-1)" //因为S[0~i]不可能包含长度比他大的T[0~j] if(S.charAt(i-1)==T.charAt(j-1)){ dp[j]=dp[j-1]+dp[j]; } else{ dp[j]=dp[j]; } } } return dp[col-1]; } }

优秀的个人博客,低调大师

leetcode算法题解(Java版)-6-链表,字符串

一、字符串处理 题目描述 Given an integer, convert it to a roman numeral. Input is guaranteed to be within the range from 1 to 3999. 思路 把数字转化为罗马符号,根据罗马符号的规律,可以先用map来存储一下。之后把每一位添加到所求中去。 语法点:StringBuffer是字符缓冲区,是可以修改字符长度的,最后要用sb.toString()去返回缓冲区的字符串 代码 //!COPY public class Solution { public String intToRoman(int num) { String[][] map={ {"","I","II","III","IV","V","VI","VII","VIII","IX"}, {"","X","XX","XXX","XL","L","LX","LXX","LXXX","XC"}, {"","C","CC","CCC","CD","D","DC","DCC","DCCC","CM"}, {"","M","MM","MMM"} }; StringBuffer sb=new StringBuffer(); sb.append(map[3][num/1000%10]); sb.append(map[2][num/100%10]); sb.append(map[1][num/10%10]); sb.append(map[0][num%10]); return sb.toString(); } } 二、链表 题目描述 You are given two linked lists representing two non-negative numbers. The digits are stored in reverse order and each of their nodes contain a single digit. Add the two numbers and return it as a linked list. Input: (2 -> 4 -> 3) + (5 -> 6 -> 4) Output: 7 -> 0 -> 8 思路 链表的题,虽然题目说存放的数字是反过来的,但是完全可以把加法也”反过来“,也就是说从”左到右“相加。 链表的题,一般都应该设置一个头指针head(里面什么也不存放,只是用来记住链表的头) 代码 /** * Definition for singly-linked list. * public class ListNode { * int val; * ListNode next; * ListNode(int x) { * val = x; * next = null; * } * } */ public class Solution { public ListNode addTwoNumbers(ListNode l1, ListNode l2) { if(l1==null){ return l2; } if(l2==null){ return l1; } ListNode head=new ListNode(0); ListNode p=head; int tem=0; while(l1!=null||l2!=null||tem!=0){ if(l1!=null){ tem+=l1.val; l1=l1.next; } if(l2!=null){ tem+=l2.val; l2=l2.next; } p.next=new ListNode(tem%10); p=p.next; tem/=10; } return head.next; } } 三、最长无重复字符子串 题目描述 Given a string, find the length of the longest substring without repeating characters. For example, the longest substring without repeating letters for "abcabcbb" is "abc", which the length is 3. For "bbbbb" the longest substring is "b", with the length of 1. 思路 水题渐渐做完了,开始碰到的题有难度了。这题用到了所谓的滑动窗口法:从左到右滑动,如果碰到了在左边界内且出现过的字符,那就将左边界移动到之前的那个字符的下一位,刷新求最大即可。 还看到一位大神的神解法,代码很简洁,思想其实也是一样的:从左到右滑动,记录每一个字符上一次出现的位置,在第i位时比较当前字符的上一次出现的位置和左边界,刷新当前左边界。 代码1 import java.util.HashMap; public class Solution { public int lengthOfLongestSubstring(String s) { HashMap <Character,Integer> map=new HashMap<>(); int len=s.length(); if(s==null||len==0){ return 0; } int res=0; int l=0; for(int i=0;i<len;i++){ char c=s.charAt(i); if(map.containsKey(c)){ l=Math.max(l,map.get(c)+1); } res=Math.max(res,i-l+1); map.put(c,i); } return res; } } 代码2 import java.util.HashMap; public class Solution { public int lengthOfLongestSubstring(String s) { HashMap<Character,Integer> map=new HashMap<>(); int len = s.length(); if(s==null||len==0){ return 0; } for(int i=0;i<len;i++){ map.put(s.charAt(i),-1); } int l=-1; int res=0; for(int i=0;i<len;i++){ char c=s.charAt(i); l=Math.max(l,map.get(c)); res=Math.max(res,i-l); map.put(c,i); } return res; } }

优秀的个人博客,低调大师

leetcode算法题解(Java版)-2-最长回文子串

一、int数字反转 题目描述Reverse digits of an integer. Example1: x = 123, return 321Example2: x = -123, return -321 思路: 题目很简单,需要注意的是:int型是32位的。1000000003 反转后就超了!所以需要包装类Integer中的最大值和最小值 小技巧:为了实现反转,可以先把符号保存到flag中。 代码: public class Solution { public int reverse(int x) { int res=0; int flag=x>0?1:-1; x=x*flag; while(x>0){ res=10*res+x%10; x/=10; } res=res*flag; if(res>Integer.MAX_VALUE){ res=Integer.MAX_VALUE; } if(res<Integer.MIN_VALUE){ res=Integer.MIN_VALUE; } return (int)res; } } 二、简单模拟、StringBuffer类 题目描述 The string"PAYPALISHIRING"is written in a zigzag pattern on a given number of rows like this: (you may want to display this pattern in a fixed font for better legibility) P A H N A P L S I I G Y I R And then read line by line:"PAHNAPLSIIGYIR" Write the code that will take a string and make this conversion given a number of rows: string convert(string text, int nRows); convert("PAYPALISHIRING", 3)should return"PAHNAPLSIIGYIR". 思路: 这题考到了StringBuffer类,虽然是将原字符“Z“字型排开,然后按每行输出得到结果。观察发现:从上到下(0~nRows),然后再从下到上(nRows-2~0),依次把字符添加到每行对应的sb后面。最后再按行输出就行。 语法点:sb.append(char c);sb.toString();sb.length;s.charAt(int index);s.length(); 代码: public class Solution { public String convert(String s, int nRows) { if(s==null||s.length()<=0||nRows<=1){ return s; } StringBuffer [] sb=new StringBuffer[nRows]; for(int i=0;i<nRows;i++){ sb[i]=new StringBuffer(); } int len=s.length(); int tot=0; while(tot<len){ for(int i=0;i<nRows&&tot<len;i++){ sb[i].append(s.charAt(tot++)); } for(int j=nRows-2;j>0&&tot<len;j--){ sb[j].append(s.charAt(tot++)); } } for(int i=1;i<nRows;i++){ sb[0].append(sb[i]); } return sb[0].toString(); } } 三、最长回文子串 题目描述 Given a string S, find the longest palindromic substring in S. You may assume that the maximum length of S is 1000, and there exists one unique longest palindromic substring. 思路 中间扩散法:因为回文串是中心对称的。不妨找到回文串的中心,往两边扩散来看是否符合回文串定义。奇数:一个中心字符;偶数:两个中心字符 dp大法:设置一个dp状态数组,dp(i,j)=true如果子串i~j是回文串,那么子串i-1~j+1是不是回文串跟i~j有关,所以可以用dp。状态转移方程:dp(i,j)=(s[i]==s[j]&&dp(i+1,j-1)) 代码:中间扩散: public class Solution { public String longestPalindrome(String s) { if(s==null||s.length()<=1){ return s; } int len=s.length(); int beg=0; int ans=0; //odd for(int i=1;i<len;i++){ int m=i-1; int n=i+1; while(m>=0&&n<len&&s.charAt(m)==s.charAt(n)){ if(n-m+1>ans){ ans=n-m+1; beg=m; } m--; n++; } } //even for(int i=0;i<len;i++){ int m=i; int n=i+1; while(m>=0&&n<len&&s.charAt(m)==s.charAt(n)){ if(n-m+1>ans){ ans=n-m+1; beg=m; } m--; n++; } } if(beg==0&&ans==1){ return s.charAt(0)+""; } return s.substring(beg,beg+ans); } } dp大法: public class Solution { public String longestPalindrome(String s) { int len=s.length(); if(len<2||s==null){ return s; } boolean [][] dp=new boolean [len][len]; int maxlen=0; int beg=0; for(int i=0;i<len;i++){//dp解题,初始化dp状态数组 dp[i][i]=true; } for(int i=0;i<len;i++){ for(int j=0;j<i;j++){ if(s.charAt(i)==s.charAt(j)){ if(j+1<len&&i-1>=0&&(dp[j+1][i-1]==true||i-j==1)){//注意!i-j==1小细节,一开始不过就是因为没有考虑它 dp[j][i]=true; if(maxlen<i-j+1){ maxlen=i-j+1; beg=j; } } } } } if(maxlen==0&&beg==0){ return s.charAt(0)+""; } return s.substring(beg,beg+maxlen); } }

优秀的个人博客,低调大师

ES BM25 TF-IDF相似度算法设置——

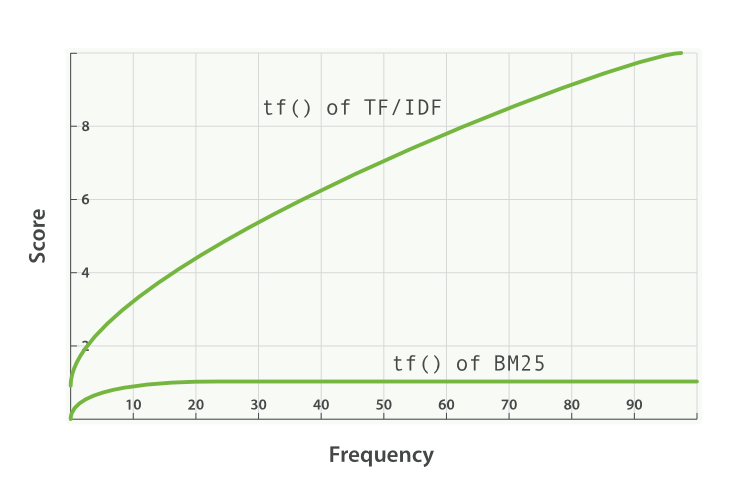
Pluggable Similarity Algorithms Before we move on from relevance and scoring, we will finish this chapter with a more advanced subject: pluggable similarity algorithms.While Elasticsearch uses theLucene’s Practical Scoring Functionas its default similarity algorithm, it supports other algorithms out of the box, which are listed in theSimilarity Modulesdocumentation. Okapi BM25 The most interesting competitor to TF/IDF and the vector space model is calledOkapi BM25, which is considered to be astate-of-the-artranking function.BM25 originates from theprobabilistic relevance model, rather than the vector space model, yetthe algorithm has a lot in common with Lucene’s practical scoring function. Both use term frequency, inverse document frequency, and field-length normalization, but the definition of each of these factors is a little different. Rather than explaining the BM25 formula in detail, we will focus on the practical advantages that BM25 offers. Term-frequency saturation Both TF/IDF and BM25 useinverse document frequencyto distinguish between common (low value) words and uncommon (high value) words.Both also recognize (seeTerm frequency) that the more often a word appears in a document, the more likely is it that the document is relevant for that word. However, common words occur commonly.The fact that a common word appears many times in one document is offset by the fact that the word appears many times inalldocuments. However, TF/IDF was designed in an era when it was standard practice to remove themostcommon words (orstopwords, seeStopwords: Performance Versus Precision) from the index altogether.The algorithm didn’t need to worry about an upper limit for term frequency because the most frequent terms had already been removed. In Elasticsearch, thestandardanalyzer—the default forstringfields—doesn’t remove stopwordsbecause, even though they are words of little value, they do still have some value. The result is that, for very long documents, the sheer number of occurrences of words liketheandandcan artificially boost their weight. BM25, on the other hand, does have an upper limit. Terms that appear 5 to 10 times in a document have a significantly larger impact on relevance than terms that appear just once or twice. However, as can be seen inFigure34, “Term frequency saturation for TF/IDF and BM25”, terms that appear 20 times in a document have almost the same impact as terms that appear a thousand times or more. This is known asnonlinear term-frequency saturation. Figure34.Term frequency saturation for TF/IDF and BM25 Field-length normalization InField-length norm, we said that Lucene considers shorter fields to have more weight than longer fields: the frequency of a term in a field is offset by the length of the field. However, the practical scoring function treats all fields in the same way.It will treat alltitlefields (because they are short) as more important than allbodyfields (because they are long). BM25 also considers shorter fields to have more weight than longer fields, but it considers each field separately by taking the average length of the field into account. It can distinguish between a shorttitlefield and alongtitle field. InQuery-Time Boosting, we said that thetitlefield has anaturalboost over thebodyfield because of its length. This natural boost disappears with BM25 as differences in field length apply only within a single field. 摘自:https://www.elastic.co/guide/en/elasticsearch/guide/current/pluggable-similarites.html 本文转自张昺华-sky博客园博客,原文链接:http://www.cnblogs.com/bonelee/p/6472820.html ,如需转载请自行联系原作者

资源下载

更多资源
腾讯云软件源

腾讯云软件源

为解决软件依赖安装时官方源访问速度慢的问题,腾讯云为一些软件搭建了缓存服务。您可以通过使用腾讯云软件源站来提升依赖包的安装速度。为了方便用户自由搭建服务架构,目前腾讯云软件源站支持公网访问和内网访问。

Spring

Spring

Spring框架(Spring Framework)是由Rod Johnson于2002年提出的开源Java企业级应用框架,旨在通过使用JavaBean替代传统EJB实现方式降低企业级编程开发的复杂性。该框架基于简单性、可测试性和松耦合性设计理念,提供核心容器、应用上下文、数据访问集成等模块,支持整合Hibernate、Struts等第三方框架,其适用范围不仅限于服务器端开发,绝大多数Java应用均可从中受益。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

WebStorm

WebStorm

WebStorm 是jetbrains公司旗下一款JavaScript 开发工具。目前已经被广大中国JS开发者誉为“Web前端开发神器”、“最强大的HTML5编辑器”、“最智能的JavaScript IDE”等。与IntelliJ IDEA同源,继承了IntelliJ IDEA强大的JS部分的功能。

用户登录
用户注册