首页 文章 精选 留言 我的

精选列表

搜索[客户分析],共10000篇文章
优秀的个人博客,低调大师

LevelDB源码分析-Compact

Compaction compact由背景线程完成,代码中触发背景线程的函数为: void DBImpl::MaybeScheduleCompaction() { mutex_.AssertHeld(); if (background_compaction_scheduled_) { // Already scheduled } else if (shutting_down_.Acquire_Load()) { // DB is being deleted; no more background compactions } else if (!bg_error_.ok()) { // Already got an error; no more changes } else if (imm_ == nullptr && manual_compaction_ == nullptr && !versions_->NeedsCompaction()) { // No work to be done } else { background_compaction_scheduled_ = true; env_->Schedule(&DBImpl::BGWork, this); } } 背景线程调用的函数为: void DBImpl::BGWork(void *db) { reinterpret_cast<DBImpl *>(db)->BackgroundCall(); } 这个函数是调用BackgroundCall函数实现的: void DBImpl::BackgroundCall() { MutexLock l(&mutex_); assert(background_compaction_scheduled_); if (shutting_down_.Acquire_Load()) { // No more background work when shutting down. } else if (!bg_error_.ok()) { // No more background work after a background error. } else { BackgroundCompaction(); } background_compaction_scheduled_ = false; // Previous compaction may have produced too many files in a level, // so reschedule another compaction if needed. MaybeScheduleCompaction(); background_work_finished_signal_.SignalAll(); } 这个函数主要调用BackgroundCompaction实现相应逻辑: void DBImpl::BackgroundCompaction() 如果immutable table存在则先调用CompactMemTable函数: mutex_.AssertHeld(); if (imm_ != nullptr) { CompactMemTable(); return; } 然后调用PickCompaction函数,PickCompaction函数选取合适的level中需要compact的文件,然后封装一个Compact对象: else { c = versions_->PickCompaction(); } 通过IsTrivialMove判断选出的sstable是否只有一个且在较低的level,并且该sstable与下下一level不会有太多的overlap,如果是的话,简单的将这个sstable移动到下一level。 Status status; if (c == nullptr) { // Nothing to do } else if (!is_manual && c->IsTrivialMove()) { // Move file to next level assert(c->num_input_files(0) == 1); FileMetaData *f = c->input(0, 0); c->edit()->DeleteFile(c->level(), f->number); c->edit()->AddFile(c->level() + 1, f->number, f->file_size, f->smallest, f->largest); status = versions_->LogAndApply(c->edit(), &mutex_); if (!status.ok()) { RecordBackgroundError(status); } VersionSet::LevelSummaryStorage tmp; Log(options_.info_log, "Moved #%lld to level-%d %lld bytes %s: %s\n", static_cast<unsigned long long>(f->number), c->level() + 1, static_cast<unsigned long long>(f->file_size), status.ToString().c_str(), versions_->LevelSummary(&tmp)); } 如果当前level中需要compact的sstable和level+2中的overlap没有超过阈值时,调用DoCompactionWork进行compact,然后调用CleanupCompaction清除compactstate对象,调用DeleteObsoleteFiles删除旧文件,回收内存和磁盘空间: else { CompactionState *compact = new CompactionState(c); status = DoCompactionWork(compact); if (!status.ok()) { RecordBackgroundError(status); } CleanupCompaction(compact); c->ReleaseInputs(); DeleteObsoleteFiles(); } delete c; 其中调用的PickCompaction函数为: Compaction *VersionSet::PickCompaction() 如果有level达到compact的阈值,优先将这个level进行compact。将最大的key大于上一次compact的最大的key的sstable加入inputs_[0]的数组中作为compact的sstable,如果compact_pointer_[level]中没有记录,则从头开始取sstable,如果不存在最大的key大于上一次compact的最大的key的sstable,则将key最小的sstable作为需要compact的sstable: Compaction *c; int level; // We prefer compactions triggered by too much data in a level over // the compactions triggered by seeks. const bool size_compaction = (current_->compaction_score_ >= 1); const bool seek_compaction = (current_->file_to_compact_ != nullptr); if (size_compaction) { level = current_->compaction_level_; assert(level >= 0); assert(level + 1 < config::kNumLevels); c = new Compaction(options_, level); // Pick the first file that comes after compact_pointer_[level] for (size_t i = 0; i < current_->files_[level].size(); i++) { FileMetaData *f = current_->files_[level][i]; if (compact_pointer_[level].empty() || icmp_.Compare(f->largest.Encode(), compact_pointer_[level]) > 0) { c->inputs_[0].push_back(f); break; } } if (c->inputs_[0].empty()) { // Wrap-around to the beginning of the key space c->inputs_[0].push_back(current_->files_[level][0]); } } 如果没有level达到需要compact的阈值,但是有文件因为seek的命中率不够而达到了compact的阈值,则将这个文件compact: else if (seek_compaction) { level = current_->file_to_compact_level_; c = new Compaction(options_, level); c->inputs_[0].push_back(current_->file_to_compact_); } 如果compact的是level0,则还需要调用GetOverlappingInputs函数求出有overlap的文件,然后再调用SetupOtherInputs函数完成compact对象的构建: c->input_version_ = current_; c->input_version_->Ref(); // Files in level 0 may overlap each other, so pick up all overlapping ones if (level == 0) { InternalKey smallest, largest; GetRange(c->inputs_[0], &smallest, &largest); // Note that the next call will discard the file we placed in // c->inputs_[0] earlier and replace it with an overlapping set // which will include the picked file. current_->GetOverlappingInputs(0, &smallest, &largest, &c->inputs_[0]); assert(!c->inputs_[0].empty()); } SetupOtherInputs(c); return c; CompactMemTable函数 void DBImpl::CompactMemTable() 调用WriteLevel0Table将immutable mmtable写入sstable: mutex_.AssertHeld(); assert(imm_ != nullptr); // Save the contents of the memtable as a new Table VersionEdit edit; Version *base = versions_->current(); base->Ref(); Status s = WriteLevel0Table(imm_, &edit, base); base->Unref(); if (s.ok() && shutting_down_.Acquire_Load()) { s = Status::IOError("Deleting DB during memtable compaction"); } 更新当前lognumber,旧日志不再需要,生效新的version: // Replace immutable memtable with the generated Table if (s.ok()) { edit.SetPrevLogNumber(0); edit.SetLogNumber(logfile_number_); // Earlier logs no longer needed s = versions_->LogAndApply(&edit, &mutex_); } 删除旧文件: if (s.ok()) { // Commit to the new state imm_->Unref(); imm_ = nullptr; has_imm_.Release_Store(nullptr); DeleteObsoleteFiles(); } else { RecordBackgroundError(s); } WriteLevel0Table函数为: Status DBImpl::WriteLevel0Table(MemTable *mem, VersionEdit *edit, Version *base) 调用BuildTable接口将immutable memtable写入sstable: mutex_.AssertHeld(); const uint64_t start_micros = env_->NowMicros(); FileMetaData meta; meta.number = versions_->NewFileNumber(); pending_outputs_.insert(meta.number); Iterator *iter = mem->NewIterator(); Log(options_.info_log, "Level-0 table #%llu: started", (unsigned long long)meta.number); Status s; { mutex_.Unlock(); s = BuildTable(dbname_, env_, options_, table_cache_, iter, &meta); mutex_.Lock(); } Log(options_.info_log, "Level-0 table #%llu: %lld bytes %s", (unsigned long long)meta.number, (unsigned long long)meta.file_size, s.ToString().c_str()); delete iter; pending_outputs_.erase(meta.number); 调用PickLevelForMemTableOutput函数选择合适的level将新的sstable加入: // Note that if file_size is zero, the file has been deleted and // should not be added to the manifest. int level = 0; if (s.ok() && meta.file_size > 0) { const Slice min_user_key = meta.smallest.user_key(); const Slice max_user_key = meta.largest.user_key(); if (base != nullptr) { level = base->PickLevelForMemTableOutput(min_user_key, max_user_key); } edit->AddFile(level, meta.number, meta.file_size, meta.smallest, meta.largest); } CompactionStats stats; stats.micros = env_->NowMicros() - start_micros; stats.bytes_written = meta.file_size; stats_[level].Add(stats); return s; PickLevelForMemTableOutput函数: int Version::PickLevelForMemTableOutput( const Slice &smallest_user_key, const Slice &largest_user_key) { int level = 0; if (!OverlapInLevel(0, &smallest_user_key, &largest_user_key)) { // Push to next level if there is no overlap in next level, // and the #bytes overlapping in the level after that are limited. InternalKey start(smallest_user_key, kMaxSequenceNumber, kValueTypeForSeek); InternalKey limit(largest_user_key, 0, static_cast<ValueType>(0)); std::vector<FileMetaData *> overlaps; while (level < config::kMaxMemCompactLevel) { if (OverlapInLevel(level + 1, &smallest_user_key, &largest_user_key)) { break; } if (level + 2 < config::kNumLevels) { // Check that file does not overlap too many grandparent bytes. GetOverlappingInputs(level + 2, &start, &limit, &overlaps); const int64_t sum = TotalFileSize(overlaps); if (sum > MaxGrandParentOverlapBytes(vset_->options_)) { break; } } level++; } } return level; } 选择level的策略为:如果level0和sstable的key有重合,则插入level0,否则循环搜索之后的level,如果下一level和sstable的key有重合,则直接返回,如果没有重合,考虑下下个level和sstable的重合的key的量,如果超过了设定的阈值,则返回(为了保证之后选取该sstable与下一level进行compact的时候,涉及下一level的文件不会太多,减小开销)。 DoCompactionWork函数 Status DBImpl::DoCompactionWork(CompactionState *compact) 将smallest_snapshot赋值为最老的snapshots的sequencenumber,如果不存在snapshots则赋值为当前数据库的sequencenumber: const uint64_t start_micros = env_->NowMicros(); int64_t imm_micros = 0; // Micros spent doing imm_ compactions Log(options_.info_log, "Compacting %d@%d + %d@%d files", compact->compaction->num_input_files(0), compact->compaction->level(), compact->compaction->num_input_files(1), compact->compaction->level() + 1); assert(versions_->NumLevelFiles(compact->compaction->level()) > 0); assert(compact->builder == nullptr); assert(compact->outfile == nullptr); if (snapshots_.empty()) { compact->smallest_snapshot = versions_->LastSequence(); } else { compact->smallest_snapshot = snapshots_.oldest()->sequence_number(); } 调用MakeInputIterator获取需要compact的文件上的迭代器,可以通过这个迭代器直接遍历所有需要compact的文件。 // Release mutex while we're actually doing the compaction work mutex_.Unlock(); Iterator *input = versions_->MakeInputIterator(compact->compaction); input->SeekToFirst(); Status status; ParsedInternalKey ikey; std::string current_user_key; bool has_current_user_key = false; SequenceNumber last_sequence_for_key = kMaxSequenceNumber; 开始通过迭代器遍历需要compact的文件。首先,如果有immutable memtable存在,首先调用CompactMemTable函数进行compact。 for (; input->Valid() && !shutting_down_.Acquire_Load();) { // Prioritize immutable compaction work if (has_imm_.NoBarrier_Load() != nullptr) { const uint64_t imm_start = env_->NowMicros(); mutex_.Lock(); if (imm_ != nullptr) { CompactMemTable(); // Wake up MakeRoomForWrite() if necessary. background_work_finished_signal_.SignalAll(); } mutex_.Unlock(); imm_micros += (env_->NowMicros() - imm_start); } 获取迭代器当前指向的entry的key值,调用ShouldStopBefore函数判断是否需要停止当前sstable的构建,如果需要,则调用FinishCompactionOutputFile函数将包含当前sstable的文件输出。ShouldStopBefore函数主要是判断当前的sstable中的key是否与下下一level中的key的overlap过大,如果过大则停止当前sstable的构建: Slice key = input->key(); if (compact->compaction->ShouldStopBefore(key) && compact->builder != nullptr) { status = FinishCompactionOutputFile(compact, input); if (!status.ok()) { break; } } 将key解码,key和之前的key重复且之前的key的sequencenumber比smallest_snapshot要小则丢弃这个key,因为既然之前重复的key的sequencenumber都比smallest_snapshot要小,当前key也肯定小,key标记为删除且之后的level中不存在这个key(也就是说这个key的删除不会影响到之后)也丢弃这个key。 // Handle key/value, add to state, etc. bool drop = false; if (!ParseInternalKey(key, &ikey)) { // Do not hide error keys current_user_key.clear(); has_current_user_key = false; last_sequence_for_key = kMaxSequenceNumber; } else { if (!has_current_user_key || user_comparator()->Compare(ikey.user_key, Slice(current_user_key)) != 0) { // First occurrence of this user key current_user_key.assign(ikey.user_key.data(), ikey.user_key.size()); has_current_user_key = true; last_sequence_for_key = kMaxSequenceNumber; } if (last_sequence_for_key <= compact->smallest_snapshot) { // Hidden by an newer entry for same user key drop = true; // (A) } else if (ikey.type == kTypeDeletion && ikey.sequence <= compact->smallest_snapshot && compact->compaction->IsBaseLevelForKey(ikey.user_key)) { // For this user key: // (1) there is no data in higher levels // (2) data in lower levels will have larger sequence numbers // (3) data in layers that are being compacted here and have // smaller sequence numbers will be dropped in the next // few iterations of this loop (by rule (A) above). // Therefore this deletion marker is obsolete and can be dropped. drop = true; } last_sequence_for_key = ikey.sequence; } 如果不丢弃key的话,当前的写入sstable的文件不存在则调用OpenCompactionOutputFile函数创建一个文件,然后将KV写入,如果写入后sstable大小达到阈值则调用FinishCompactionOutputFile函数写出这个文件。 if (!drop) { // Open output file if necessary if (compact->builder == nullptr) { status = OpenCompactionOutputFile(compact); if (!status.ok()) { break; } } if (compact->builder->NumEntries() == 0) { compact->current_output()->smallest.DecodeFrom(key); } compact->current_output()->largest.DecodeFrom(key); compact->builder->Add(key, input->value()); // Close output file if it is big enough if (compact->builder->FileSize() >= compact->compaction->MaxOutputFileSize()) { status = FinishCompactionOutputFile(compact, input); if (!status.ok()) { break; } } } 循环以上过程: input->Next(); } 结束遍历之后,将没有写出的文件写出: if (status.ok() && shutting_down_.Acquire_Load()) { status = Status::IOError("Deleting DB during compaction"); } if (status.ok() && compact->builder != nullptr) { status = FinishCompactionOutputFile(compact, input); } if (status.ok()) { status = input->status(); } delete input; input = nullptr; 记录统计信息: CompactionStats stats; stats.micros = env_->NowMicros() - start_micros - imm_micros; for (int which = 0; which < 2; which++) { for (int i = 0; i < compact->compaction->num_input_files(which); i++) { stats.bytes_read += compact->compaction->input(which, i)->file_size; } } for (size_t i = 0; i < compact->outputs.size(); i++) { stats.bytes_written += compact->outputs[i].file_size; } mutex_.Lock(); stats_[compact->compaction->level() + 1].Add(stats); 将此次compaction生效: if (status.ok()) { status = InstallCompactionResults(compact); } if (!status.ok()) { RecordBackgroundError(status); } VersionSet::LevelSummaryStorage tmp; Log(options_.info_log, "compacted to: %s", versions_->LevelSummary(&tmp)); return status; 230 Love u

优秀的个人博客,低调大师

LevelDB源码分析-编码

编码(util/coding.h util/coding.cc) LevelDB将整型编码为二进制字符串的形式,同时又能够和ASCII字符区分。 首先是定长编码: void EncodeFixed32(char *buf, uint32_t value) { if (port::kLittleEndian) { memcpy(buf, &value, sizeof(value)); } else { buf[0] = value & 0xff; buf[1] = (value >> 8) & 0xff; buf[2] = (value >> 16) & 0xff; buf[3] = (value >> 24) & 0xff; } } void EncodeFixed64(char *buf, uint64_t value) { if (port::kLittleEndian) { memcpy(buf, &value, sizeof(value)); } else { buf[0] = value & 0xff; buf[1] = (value >> 8) & 0xff; buf[2] = (value >> 16) & 0xff; buf[3] = (value >> 24) & 0xff; buf[4] = (value >> 32) & 0xff; buf[5] = (value >> 40) & 0xff; buf[6] = (value >> 48) & 0xff; buf[7] = (value >> 56) & 0xff; } } 这里根据机器区分大端和小端,LevelDB编码后的字符串为小端存储。在编码时,只是简单的将8位二进制码存储在一个char字符的位置上。因为定长,所以可以和ASCII字符区分。 接下来是定长编码的一些接口函数: void PutFixed32(std::string *dst, uint32_t value) // 将一个32位整型值定长编码后存入dst void PutFixed64(std::string *dst, uint64_t value) // 将一个64位整型值定长编码后存入dst 然后是变长编码: char *EncodeVarint32(char *dst, uint32_t v) { // Operate on characters as unsigneds unsigned char *ptr = reinterpret_cast<unsigned char *>(dst); static const int B = 128; if (v < (1 << 7)) { *(ptr++) = v; } else if (v < (1 << 14)) { *(ptr++) = v | B; *(ptr++) = v >> 7; } else if (v < (1 << 21)) { *(ptr++) = v | B; *(ptr++) = (v >> 7) | B; *(ptr++) = v >> 14; } else if (v < (1 << 28)) { *(ptr++) = v | B; *(ptr++) = (v >> 7) | B; *(ptr++) = (v >> 14) | B; *(ptr++) = v >> 21; } else { *(ptr++) = v | B; *(ptr++) = (v >> 7) | B; *(ptr++) = (v >> 14) | B; *(ptr++) = (v >> 21) | B; *(ptr++) = v >> 28; } return reinterpret_cast<char *>(ptr); } char *EncodeVarint64(char *dst, uint64_t v) { static const int B = 128; unsigned char *ptr = reinterpret_cast<unsigned char *>(dst); while (v >= B) { *(ptr++) = (v & (B - 1)) | B; v >>= 7; } *(ptr++) = static_cast<unsigned char>(v); return reinterpret_cast<char *>(ptr); } LevelDB的变长编码设计的十分巧妙,它以7个二进制bit为一个单位,存入一个char中,同时为了和ASCII码进行区分,将char的最高位设为1(ASCII码为0-127),同样采用小端存储的形式。但是变长编码的最后一个char的最高位是0,以此作为变长编码后的字符串的结束标志。 例如,11001011101111001会被编码为11111001 10101110 00000110。 接下来是一些变长编码的接口函数: void PutVarint32(std::string *dst, uint32_t v) // 将一个32位整型值变长编码后存入dst void PutVarint64(std::string *dst, uint64_t v) // 将一个64位整型值变长编码后存入dst int VarintLength(uint64_t v) // 获取变长编码后的字符串长度(以字节计数) const char *GetVarint32PtrFallback(const char *p, const char *limit, uint32_t *value) // 将以p到limit之间的变长编码字符串解码为32位整型值 bool GetVarint32(Slice *input, uint32_t *value) // 将以p到limit之间的变长编码字符串解码为32位整型值并封装入Slice中 const char *GetVarint64Ptr(const char *p, const char *limit, uint64_t *value) // 将以p到limit之间的变长编码字符串解码为64位整型值 bool GetVarint64(Slice *input, uint64_t *value) // 将以p到limit之间的变长编码字符串解码为64位整型值并封装入Slice中 227 Love u

优秀的个人博客,低调大师

Erlang PoolBoy 源码分析

问题存疑: 1.如何释放使用过的进程,被再次利用 答:通过try after 的方式,try checkout锁定一个进程,after 用完之后释放被锁定的进程 2.如果出现初始进程不够了,如果处理 答:如果不够用,判定max_overflow参数,确定是否需要重新创建进程,或者将此使用者放入等待列表中,一旦有新释放的,就马上给他使用,受超时器的影响 3.创建新的进程,是如何释放的 答:如果此进程是弹性创建的,则直接释放此进程,如果是work中的进程,则释放使用权 4.如果达到最大的创建进程数,又是如何处理的 答:根据block参数确定,是否忽略或者加入等待列表中 5.如果创建的进程 答:poolboy_sup 通过sample_one_by_one参数形式,动态调用supervisor:start_child创建进程池中的进程 6.为什么需要将初始创建的进程和poolboy进程link起来,有何用意 答:这样就可以将所有的逻辑全部集中在poolboy进程,只是将poolboy_sup当作一个中间件来使用创建进程池中的进程 queue 队列 支持先进先出或者后进先出模式 基本思路 1.通过一个外部sup启动一个poolboy进程,poolboy进程再启动一个poolboy_sup进程 2.poolboy_sup 就是这个进程池,然后启动若干个进程,但是poolboy进程操纵poolboy_sup进程创建很多个进程,然后将这些进程全部保存在poolboy进程 poolboy进程并且与poolboy_sup进程创建的进程进行link 当外部进程需要进程时直接从poolboy进程入口,然后使用,并且poolboy进程还监控所有使用的外部进程 当外部进程down掉后,poolboy进行善后操作,每一个外部进程独享poolboy进程中的一个进程 通过try after 方法,先独享进程,用完后,再释放进程 link的还有一个操作,就是处理poolboy进程池中进程挂掉的情况,先关闭此进程,并进行善后操作,然后,重新启用一个新的进程,带起挂掉的进程 主要的接口就是checkout和checkin的两个接口创建 数据结构采用queue,有两种方式可选,fifo(先进先出),fofi(后进先出)的方式,遍历整个进程池 还采用了一种动态创建进程的机制,就是说,如果发现现有创建的进程不够用了,那就需要创建一个临时的进程,满足使用,当使用完之后,再释放此进程 如果在释放的时候,发现还有等待的进程,则继续使用释放的进程,进行执行 启动 1.创建两个数据结构,wait:queue:new 保存等待的进程吃中分配的进程,monitors=ets:new()创建一个监控使用进程池中进程的数据 2.创建poolboy_sup 监督进程,采用sample_one_by_one 启动,后面采用supervisor:start_child(Sup,Args)启动进程 3.设置启动参数: worker_module:启动进程池的进程模块名 size:进程池中常见size个进程 max_overflow:最多可以弹性创建进程的数量 starategy:lifo|fifo 后进先出|先进先出模式 (一版来说,进程池中的进程没有区别的) Block:true 允许进程获取等待 false 不允许进程获取等待,在checkout接口中设置 4.启动进程池进程 supervisor:start_child(Sup,Args)启动子进程,填充进程池 使用 调用poolboy:transaction(PoolName,Query) 工作机制: 1.首先调用checkout获取进程池中的一个进程,调用的是call同步的方法执行,并设置超时时间 2.使用完毕之后,调用checkin释放进程使用 3.如果出现进程池没有进程,就可以通过max_overflow参数配置,确认是否可以生成新的进程以供使用 4.如果没有,则可以通过Block参数,确认是否可以将当前请求放入waiting中,只要有进程释放,就将此进程返回 5.进程使用完毕,则释放此进程的使用权,清理监控数据列表,然后判定是否弹性创建,决定是否释放,如果有等待进程,则将此进程使用权转移使用 异常处理 1.使用进程挂掉:调用down的handle_info,清理监控列表和工作列表,以及等待列表 2.进程池中进程挂掉:删除监控,重新生成一个进程 执行函数 checkout 获取一个可用进程 checkin 释放一个使用进程 transaction 一个完整的获取和释放进程过程 可能的不足之处 短暂 I/O 任务(比如数据库访问)的大型 worker 池会因为太多迁入和迁出活动而拖垮单个 poolboy 管理器。 参考: Erlang 池管理 maestro Erlang:https://www.oschina.net/p/maestro-erlang

优秀的个人博客,低调大师

Spark 通信原理分析

Spark通信原理(发件箱和收件箱) 更多资源 github: https://github.com/opensourceteams/spark-scala-maven csdn(汇总视频在线看): https://blog.csdn.net/thinktothings/article/details/84726769 Youtube视频分享 youtube:https://youtu.be/3vUVwbEGf1E​ BiliBili视频分享 bilibili : https://www.bilibili.com/video/av37442199/ Spark通信说明图 发件箱Outbox 发送消息在LinkList中存储 private val messages = new java.util.LinkedList[OutboxMessage] /** * Send a message. If there is no active connection, cache it and launch a new connection. If * [[Outbox]] is stopped, the sender will be notified with a [[SparkException]]. */ def send(message: OutboxMessage): Unit = { val dropped = synchronized { if (stopped) { true } else { messages.add(message) false } } if (dropped) { message.onFailure(new SparkException("Message is dropped because Outbox is stopped")) } else { drainOutbox() } } 消息发送 取出列表中的第一个元素 message = messages.poll() 调用消息发送 message.sendWith(_client) /** * Drain the message queue. If there is other draining thread, just exit. If the connection has * not been established, launch a task in the `nettyEnv.clientConnectionExecutor` to setup the * connection. */ private def drainOutbox(): Unit = { var message: OutboxMessage = null synchronized { if (stopped) { return } if (connectFuture != null) { // We are connecting to the remote address, so just exit return } if (client == null) { // There is no connect task but client is null, so we need to launch the connect task. launchConnectTask() return } if (draining) { // There is some thread draining, so just exit return } message = messages.poll() if (message == null) { return } draining = true } while (true) { try { val _client = synchronized { client } if (_client != null) { message.sendWith(_client) } else { assert(stopped == true) } } catch { case NonFatal(e) => handleNetworkFailure(e) return } synchronized { if (stopped) { return } message = messages.poll() if (message == null) { draining = false return } } } } 收件箱Inbox 对RpcMessage类型消息进行端点的 receiveAndReply 方法调用 对OneWayMessage类型消息进行端点的 receive方法调用 /** * Process stored messages. */ def process(dispatcher: Dispatcher): Unit = { var message: InboxMessage = null inbox.synchronized { if (!enableConcurrent && numActiveThreads != 0) { return } message = messages.poll() if (message != null) { numActiveThreads += 1 } else { return } } while (true) { safelyCall(endpoint) { message match { case RpcMessage(_sender, content, context) => try { endpoint.receiveAndReply(context).applyOrElse[Any, Unit](content, { msg => throw new SparkException(s"Unsupported message $message from ${_sender}") }) } catch { case NonFatal(e) => context.sendFailure(e) // Throw the exception -- this exception will be caught by the safelyCall function. // The endpoint's onError function will be called. throw e } case OneWayMessage(_sender, content) => endpoint.receive.applyOrElse[Any, Unit](content, { msg => throw new SparkException(s"Unsupported message $message from ${_sender}") }) case OnStart => endpoint.onStart() if (!endpoint.isInstanceOf[ThreadSafeRpcEndpoint]) { inbox.synchronized { if (!stopped) { enableConcurrent = true } } } case OnStop => val activeThreads = inbox.synchronized { inbox.numActiveThreads } assert(activeThreads == 1, s"There should be only a single active thread but found $activeThreads threads.") dispatcher.removeRpcEndpointRef(endpoint) endpoint.onStop() assert(isEmpty, "OnStop should be the last message") case RemoteProcessConnected(remoteAddress) => endpoint.onConnected(remoteAddress) case RemoteProcessDisconnected(remoteAddress) => endpoint.onDisconnected(remoteAddress) case RemoteProcessConnectionError(cause, remoteAddress) => endpoint.onNetworkError(cause, remoteAddress) } } inbox.synchronized { // "enableConcurrent" will be set to false after `onStop` is called, so we should check it // every time. if (!enableConcurrent && numActiveThreads != 1) { // If we are not the only one worker, exit numActiveThreads -= 1 return } message = messages.poll() if (message == null) { numActiveThreads -= 1 return } } } }

优秀的个人博客,低调大师

Etcd源码分析: 存储

存储数据结构 Etcd存储在集群搭建和使用篇有简介,总结起来有如下特点: 采用kv型数据存储,一般情况下比关系型数据库快。 支持动态存储(内存)以及静态存储(磁盘)。 分布式存储,可集成为多节点集群。 存储方式,采用类似目录结构。 1、只有叶子节点才能真正存储数据,相当于文件。 2、叶子节点的父节点一定是目录,目录不能存储数据。 叶子节点数据结构位于 /store/store.go type store struct { Root *node WatcherHub *watcherHub CurrentIndex uint64 Stats *Stats CurrentVersion int ttlKeyHeap *ttlKeyHeap // need to recovery manually worldLock sync.RWMutex // stop the world lock clock clockwork.Clock readonlySet types.Set } 其父节点数据结构位于/store/node.go type node struct { Path string CreatedIndex uint64 ModifiedIndex uint64 Parent *node `json:"-"` // should not encode this field! avoid circular dependency. ExpireTime time.Time Value string // for key-value pair Children map[string]*node // for directory // A reference to the store this node is attached to. store *store } 其中Path即为key WAL 内存中的数据格式 +-------------------------------+ | F | Pad | | +-----------+ Length | | | +-------------------------------+ | type | +-------------------------------+ | CRC | +-------------------------------+ | Data | +-------------------------------+ 字段名称 含义 占用大小 文本1 文本2 文本3 F 是否存在补齐数据 0:表示没有补齐字段 1:表示存在补齐字段 1bit Pad 表示补齐长度。在F为1时有效 7bit Length 表示数据有效负载长度,不包括F、Pad自身长度、补齐字段。 56bit Type 类型 int64,8字节,有符号 CRC 校验 uint32,4字节,无符号 Data 私有数据 WAL文件数据格式 当我们持久化到文件系统中,数据格式并不是上面介绍,而是grpc格式。 WAL文件以小端序方式存储 启动一个全新etcd,默认会在目录:/var/lib/etcd/default.etcd/member/wal/中生成一个.wal文件。 WAL的定义和创建 定义在wal.go中, WAL日志文件遵循一定的命名规则,由walName()实现,格式为"序号--raft日志索引.wal"。 // 根据seq和index产生wal文件名 func walName(seq, index uint64) string { return fmt.Sprintf("%016x-%016x.wal", seq, index) } WAL对外暴露的创建接口就是Create()函数 // Create creates a WAL ready for appending records. The given metadata is // recorded at the head of each WAL file, and can be retrieved(检索) with ReadAll. func Create(dirpath string, metadata []byte) (*WAL, error) { if Exist(dirpath) { return nil, os.ErrExist } // 先在.tmp临时文件上做修改,修改完之后可以直接执行rename,这样起到了原子修改文件的效果 tmpdirpath := filepath.Clean(dirpath) + ".tmp" if fileutil.Exist(tmpdirpath) { if err := os.RemoveAll(tmpdirpath); err != nil { return nil, err } } if err := fileutil.CreateDirAll(tmpdirpath); err != nil { return nil, err } // dir/filename ,filename从walName获取 seq-index.wal p := filepath.Join(tmpdirpath, walName(0, 0)) // 对文件上互斥锁 f, err := fileutil.LockFile(p, os.O_WRONLY|os.O_CREATE, fileutil.PrivateFileMode) if err != nil { return nil, err } // 定位到文件末尾 if _, err = f.Seek(0, io.SeekEnd); err != nil { return nil, err } // 预分配文件,大小为SegmentSizeBytes(64MB) if err = fileutil.Preallocate(f.File, SegmentSizeBytes, true); err != nil { return nil, err } // 新建WAL结构 w := &WAL{ dir: dirpath, metadata: metadata,// metadata 可为nil } // 在这个wal文件上创建一个encoder w.encoder, err = newFileEncoder(f.File, 0) if err != nil { return nil, err } // 把这个上了互斥锁的文件加入到locks数组中 w.locks = append(w.locks, f) if err = w.saveCrc(0); err != nil { return nil, err } // 将metadataType类型的record记录在wal的header处 if err = w.encoder.encode(&walpb.Record{Type: metadataType, Data: metadata}); err != nil { return nil, err } // 保存空的snapshot if err = w.SaveSnapshot(walpb.Snapshot{}); err != nil { return nil, err } // 重命名,之前以.tmp结尾的文件,初始化完成之后重命名,类似原子操作 if w, err = w.renameWal(tmpdirpath); err != nil { return nil, err } // directory was renamed; sync parent dir to persist rename pdir, perr := fileutil.OpenDir(filepath.Dir(w.dir)) if perr != nil { return nil, perr } // 将上述的所有文件操作进行同步 if perr = fileutil.Fsync(pdir); perr != nil { return nil, perr } // 关闭目录 if perr = pdir.Close(); err != nil { return nil, perr } return w, nil } 其中, SaveSnapshot()是做walpb.Snapshot持久化的, 里面的内容略过, 不过里面有一行代码if err := w.encoder.encode(rec)表示一条Record需要先把序列化后才能持久化,这个是通过encode()函数完成的(encoder.go) 一个Record被序列化之后(这里为JOSN格式),会以一个Frame的格式持久化。Frame首先是一个长度字段(encodeFrameSize()完成,在encoder.go文件),64bit,其中MSB表示这个Frame是否有padding字节,接下来才是真正的序列化后的数据 WAL存储 当raft模块收到一个proposal时就会调用Save方法完成(定义在wal.go)持久化 func (w *WAL) Save(st raftpb.HardState, ents []raftpb.Entry) error { w.mu.Lock() // 上锁 defer w.mu.Unlock() // short cut(捷径), do not call sync // IsEmptyHardState returns true if the given HardState is empty. if raft.IsEmptyHardState(st) && len(ents) == 0 { return nil } // 是否需要同步刷新磁盘 mustSync := raft.MustSync(st, w.state, len(ents)) // TODO(xiangli): no more reference operator // 保存所有日志项 for i := range ents { if err := w.saveEntry(&ents[i]); err != nil { return err } } // 持久化HardState, HardState表示服务器当前状态,定义在raft.pb.go,主要包含Term、Vote、Commit if err := w.saveState(&st); err != nil { return err } // 获取最后一个LockedFile的大小(已经使用的) curOff, err := w.tail().Seek(0, io.SeekCurrent) if err != nil { return err } // 如果小于64MB if curOff < SegmentSizeBytes { if mustSync { // 如果需要sync,就执行sync return w.sync() } return nil } // 否则执行切割(也就是说明,WAL文件是可以超过64MB的) return w.cut() } snapshot snapshot比wal大小要小5倍左右,只有CRC和Data两个字段 etcd中对raft snapshot的定义如下(在文件raft.pb.go): type Snapshot struct { Data []byte `protobuf:"bytes,1,opt,name=data" json:"data,omitempty"` Metadata SnapshotMetadata `protobuf:"bytes,2,opt,name=metadata" json:"metadata"` XXX_unrecognized []byte `json:"-"` } Metadata则是snaoshot的元信息 // snapshot的元数据 type SnapshotMetadata struct { // 最后一次的配置状态 ConfState ConfState `protobuf:"bytes,1,opt,name=conf_state,json=confState" json:"conf_state"` // 被快照取代的最后的条目在日志中的索引值(appliedIndex) Index uint64 `protobuf:"varint,2,opt,name=index" json:"index"` // 该条目的任期号 Term uint64 `protobuf:"varint,3,opt,name=term" json:"term"` XXX_unrecognized []byte `json:"-"` } snapshot持久化使用func (s *Snapshotter) SaveSnap(snapshot raftpb.Snapshot) 过程比较简单, 略去, 里面可以看到snapshot文件的命名规则 // 将raft snapshot序列化后持久化到磁盘 func (s *Snapshotter) save(snapshot *raftpb.Snapshot) error { // 产生snapshot的时间 start := time.Now() // snapshot的文件名Term-Index.snap fname := fmt.Sprintf("%016x-%016x%s", snapshot.Metadata.Term, snapshot.Metadata.Index, snapSuffix) 动态存储 +--------------------+ +--------------------+ | etcdserver/raft.go | | raft/storge.go | | +<-------->+ | | startNode() | | NewMemoryStorge() | +---------^----------+ +--------------------+ | | | +---------v----------+ +--------------------+ | rafe/node.go | | rafe/node.go | | +<-------->+ | | StartNode() | | newRaft() | +---------^----------+ +--------------------+ | | | +---------v----------+ | raft/node.go | | | | run() | +--------------------+ 首先调用NewMemoryStorage进行初始化,然后在newRaft()中生成raftLog对象并且调用InitialState()进行状态初始化,最后在node中run方法接收数据。

优秀的个人博客,低调大师

BroadcastReceiver的源码分析

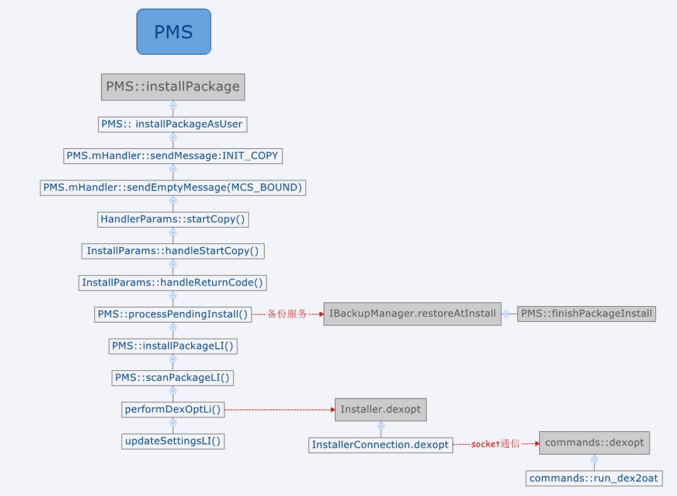
android提供了广播机制,通过BroadcastReceiver可以在不同的进程间传递消息。类似于观察者模式,A应用通过注册广播表示A对消息subject感兴趣,当B应用发出subject类型的消息的时候,A应用就能收到对应的消息。 android提供静态和动态两种方式进行消息注册,静态注册指的是在AndroidManifest.xml中进行注册,动态注册指的是在Activity通过registerReceiver的方式进行广播注册。 静态广播注册流程 静态广播注册指的是在AndroidManifest.xml注册Receiver,当Apk安装时会将静态注册的Receiver信息注册到PMS中,APK的安装流程(https://www.jianshu.com/p/953475cea991)如下: APK安装流程 其中installPackageLI完成了Apk的解析,生成了Package对象,scanPackageLi包括四大组件注册之类的操作。 PMS.scanPackageDirtyLI注册静态广播 解析到APK里的静态广播会注册到PMS的mReceivers对象中,mReceivers类型为ActivityIntentResolver。 动态广播注册流程 Activity通过registerReceiver方式进行广播注册,注册流程如下: registerReceiver流程 ContextImpl.registerReceiverInternal ContextImpl.registerReceiverInternal 该函数根据BroadcastReceiver对象生成IIntentReceiver对象,该对象和ApplicationThread的功能一样,试想一下,APP进程向AMS进程注册广播,当AMS收到广播向APP进程分发时需要用到Binder调用,IIntentReceiver就是进行跨进程调用的。 AMS.registerReceiver AMS将IIntentReceiver保存到mReisterdReceivers中,最终保存到mReceiverResolver.addFilter(bf);中。 sendBroadcast发送广播 sendBroascast流程 发送广播最终走到了AMS.broadcastIntentLocked,其中核心的代码如下所示: AMS.broadcastIntentLocked broadcastIntentLocked中receivers表示静态注册的广播,通过collectReceiverComponents从PMS那里获取;registerdReceivers表示动态注册的广播,从mReceiverResolver那里获取。在获取到要接受所有广播后,就调用如下函数进行广播分发。 广播分发 scheduleBroadcastsLocked开始进行广播发送 BroadcastQueue.scheduleBroadcastsLocked Handler消息最终调用了BroadcastQueue.processNextBroadcast,然后调用了performReceiveLocked, processNextBroadcast processNextBroadcast调用了performReceiverLocked performReceiverLocked performReceiverLocked继续调用IItentReceiver.performReceiver,该调用的Binder方式, IItentReceiver.performReceiver 最终调用了Args.run Args.run Args.run通过类加载器加载Receiver对象,并最终调用onReceive函数,至此,广播发送完成。

优秀的个人博客,低调大师

Kotlin集合框架分析

一、Kotlin中集合框架和Java集合框架特别相似 掌握以下例子就Ok了 package cn.kotliner.kotlin.collections /** * Created by wangdong * 集合框架 * kotlin中集合的映射,最终都映射到Java中的list * kotlin中所有的list和map都是不可变的接口,如下不可以.add或者.remove * 但是kotlin的mutableList和mutablemap是可变的 * public interface MutableList<E> : List<E>, MutableCollection<E> { * Modification Operations *override fun add(element: E): Boolean *override fun remove(element: E): Boolean * Bulk Modification Operations *override fun addAll(elements: Collection<E>): Boolean * * kotlin的mutablemap * public interface MutableMap<K, V> : Map<K, V> { *public fun put(key: K, value: V): V? *public fun remove(key: K): V? *@SinceKotlin("1.1") *@PlatformDependent *public fun remove(key: K, value: V): Boolean { * See default implementation in JDK sources *return true *} *public fun putAll(from: Map<out K, V>): Unit */ fun main(args: Array<String>) { //List集合 val list = listOf("Hello", "World") //list.add() //map集合 val map = mapOf("key" to "value", "2" to "whatever") //map.put() } object Test{ val list = listOf(1, 2,4) }

资源下载

更多资源
腾讯云软件源

腾讯云软件源

为解决软件依赖安装时官方源访问速度慢的问题,腾讯云为一些软件搭建了缓存服务。您可以通过使用腾讯云软件源站来提升依赖包的安装速度。为了方便用户自由搭建服务架构,目前腾讯云软件源站支持公网访问和内网访问。

Spring

Spring

Spring框架(Spring Framework)是由Rod Johnson于2002年提出的开源Java企业级应用框架,旨在通过使用JavaBean替代传统EJB实现方式降低企业级编程开发的复杂性。该框架基于简单性、可测试性和松耦合性设计理念,提供核心容器、应用上下文、数据访问集成等模块,支持整合Hibernate、Struts等第三方框架,其适用范围不仅限于服务器端开发,绝大多数Java应用均可从中受益。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

Sublime Text

Sublime Text

Sublime Text具有漂亮的用户界面和强大的功能,例如代码缩略图,Python的插件,代码段等。还可自定义键绑定,菜单和工具栏。Sublime Text 的主要功能包括:拼写检查,书签,完整的 Python API , Goto 功能,即时项目切换,多选择,多窗口等等。Sublime Text 是一个跨平台的编辑器,同时支持Windows、Linux、Mac OS X等操作系统。

用户登录
用户注册