首页 文章 精选 留言 我的

精选列表

搜索[认知分析],共10000篇文章
优秀的个人博客,低调大师

hbase snapshot源码分析

snapshot操作在硬盘上形式: /hbase/.snapshots /.tmp &lt;---- working directory /[snapshot name] &lt;----- completed snapshot 当snapshot完成时的形式展示: /hbase/.snapshots/[snapshot name] .snapshotinfo &lt;--- Description of the snapshot .tableinfo &lt;--- Copy of the tableinfo /.logs /[server_name] /... [log files] ... /[region name] &lt;---- All the region's information .regioninfo &lt;---- Copy of the HRegionInfo /[column family name] /[hfile name] &lt;--- name of the hfile in the real region ... ... snapshot基本步骤: 1.执行前会枷锁操作,不允许删除添加操作; 2.在hdfs在创建指定目录,写入相关的信息进去; 3.刷新memstore中的数据到hfile, 4.为hfile文件创建引用指针. 以下是大体的代码流程。 hbaseAdmin执行发起的snapshot: public void snapshot(final String snapshotName, final TableName tableName, SnapshotDescription.Type type) throws IOException, SnapshotCreationException, IllegalArgumentException { SnapshotDescription.Builder builder = SnapshotDescription.newBuilder(); builder.setTable(tableName.getNameAsString()); builder.setName(snapshotName); builder.setType(type); snapshot(builder.build()); } 执行快照并等待服务器完成该快照(阻止)。HBase实例一次只能有一个快照,或者结果可能是未定义(你可以告诉多个HBase集群同时快照,但只有一个在单个群集同时)。 public void snapshot(SnapshotDescription snapshot) throws IOException, SnapshotCreationException, IllegalArgumentException { // actually take the snapshot SnapshotResponse response = takeSnapshotAsync(snapshot); MasterRpcService:异步触发并完成一次snapshot: `master.snapshotManager.takeSnapshot(snapshot);` SnapshotManager类:完成一次snapshot需要根据表的状态:disabled或者enabled if (assignmentMgr.getTableStateManager().isTableState(snapshotTable, ZooKeeperProtos.Table.State.ENABLED)) { LOG.debug("Table enabled, starting distributed snapshot."); snapshotEnabledTable(snapshot); LOG.debug("Started snapshot: " + ClientSnapshotDescriptionUtils.toString(snapshot)); } // For disabled table, snapshot is created by the master else if (assignmentMgr.getTableStateManager().isTableState(snapshotTable, ZooKeeperProtos.Table.State.DISABLED)) { LOG.debug("Table is disabled, running snapshot entirely on master."); snapshotDisabledTable(snapshot); LOG.debug("Started snapshot: " + ClientSnapshotDescriptionUtils.toString(snapshot)); } private synchronized void snapshotEnabledTable(SnapshotDescription snapshot) throws HBaseSnapshotException { // setup the snapshot prepareToTakeSnapshot(snapshot); // Take the snapshot of the enabled table EnabledTableSnapshotHandler handler = new EnabledTableSnapshotHandler(snapshot, master, this); snapshotTable(snapshot, handler); } enabled状态下执行表的snapshot: // setup the snapshot 准备工作 prepareToTakeSnapshot(snapshot); // Take the snapshot of the enabled table EnabledTableSnapshotHandler handler = new EnabledTableSnapshotHandler(snapshot, master, this); 开始执行snapshot snapshotTable(snapshot, handler); } snapshot开始之前的设置准备:检查是否有一个在运行的snapshot工作以及还原snapshot工作的请求存在。# // make sure we aren't already running a snapshot if (isTakingSnapshot(snapshot)) { SnapshotSentinel handler = this.snapshotHandlers.get(snapshotTable); throw new SnapshotCreationException("Rejected taking " + ClientSnapshotDescriptionUtils.toString(snapshot) + " because we are already running another snapshot " + (handler != null ? ("on the same table " + ClientSnapshotDescriptionUtils.toString(handler.getSnapshot())) : "with the same name"), snapshot); } // make sure we aren't running a restore on the same table if (isRestoringTable(snapshotTable)) { SnapshotSentinel handler = restoreHandlers.get(snapshotTable); throw new SnapshotCreationException("Rejected taking " + ClientSnapshotDescriptionUtils.toString(snapshot) + " because we are already have a restore in progress on the same snapshot " + ClientSnapshotDescriptionUtils.toString(handler.getSnapshot()), snapshot); } try { // delete the working directory, since we aren't running the snapshot. Likely leftovers // from a failed attempt. fs.delete(workingDir, true); // recreate the working directory for the snapshot if (!fs.mkdirs(workingDir)) { throw new SnapshotCreationException("Couldn't create working directory (" + workingDir + ") for snapshot", snapshot); } 设置准备工作完成就开始进行snapshot用指定的handler进行snapshot工作: handler.prepare(); this.executorService.submit(handler); this.snapshotHandlers.put(TableName.valueOf(snapshot.getTable()), handler); ... TakeSnapshotHandler真正开始处理snapshot操作: 1.将snapshot描述信息写入.snapshotinfo目录 FsPermission perms = FSUtils.getFilePermissions(fs, fs.getConf(), HConstants.DATA_FILE_UMASK_KEY); Path snapshotInfo = new Path(workingDir, SnapshotDescriptionUtils.SNAPSHOTINFO_FILE); try { FSDataOutputStream out = FSUtils.create(fs, snapshotInfo, perms, true); try { snapshot.writeTo(out); } finally { out.close(); } } 2.复制表的信息: snapshotManifest.addTableDescriptor(this.htd); 3.获取hregionserver上的regions以及位置信息 ##: List<Pair<HRegionInfo, ServerName>> regionsAndLocations; if (TableName.META_TABLE_NAME.equals(snapshotTable)) { regionsAndLocations = new MetaTableLocator().getMetaRegionsAndLocations(server.getZooKeeper()); } else { regionsAndLocations = MetaTableAccessor.getTableRegionsAndLocations(server.getZooKeeper(), server.getConnection(), snapshotTable, false); } 4.开始执行snapshot操作,上面获取到的region信息及位置信息 // run the snapshot snapshotRegions(regionsAndLocations); 启动snapshot程序::: 在regionserver上开始snapshot // start the snapshot on the RS所有的snapshot操作的具体细节 Procedure proc = coordinator.startProcedure(this.monitor, this.snapshot.getName(), this.snapshot.toByteArray(), Lists.newArrayList(regionServers)); if (proc == null) { String msg = "Failed to submit distributed procedure for snapshot '" + snapshot.getName() + "'"; LOG.error(msg); throw new HBaseSnapshotException(msg); } 等待snapshot完成: proc.waitForCompleted(); 将下线的region作为disabled处理 // Take the offline regions as disabled for (Pair<HRegionInfo, ServerName> region : regions) { HRegionInfo regionInfo = region.getFirst(); if (regionInfo.isOffline() && (regionInfo.isSplit() || regionInfo.isSplitParent())) { LOG.info("Take disabled snapshot of offline region=" + regionInfo); snapshotDisabledRegion(regionInfo); } } 5.相关region信息以及servername,用来验证snapshot的有效性 // extract each pair to separate lists Set<String> serverNames = new HashSet<String>(); for (Pair<HRegionInfo, ServerName> p : regionsAndLocations) { if (p != null && p.getFirst() != null && p.getSecond() != null) { HRegionInfo hri = p.getFirst(); if (hri.isOffline() && (hri.isSplit() || hri.isSplitParent())) continue; serverNames.add(p.getSecond().toString()); } } 6.刷新内存状态,写snapshot-mnifest信息到目录 // flush the in-memory state, and write the single manifest status.setStatus("Consolidate snapshot: " + snapshot.getName()); snapshotManifest.consolidate(); 7.开始验证snapshot的有效性 // verify the snapshot is valid status.setStatus("Verifying snapshot: " + snapshot.getName()); verifier.verifySnapshot(this.workingDir, serverNames); 8.完成snapshot,转移目录等 // complete the snapshot, atomically moving from tmp to .snapshot dir. completeSnapshot(this.snapshotDir, this.workingDir, this.fs); msg = "Snapshot " + snapshot.getName() + " of table " + snapshotTable + " completed"; status.markComplete(msg); LOG.info(msg); metricsSnapshot.addSnapshot(status.getCompletionTimestamp() - status.getStartTime());

优秀的个人博客,低调大师

Android消息循环分析

我们的经常使用的系统中,程序的工作一般是有事件驱动和消息驱动两种方式,在Android系统中,Java应用程序是靠消息驱动来工作的。 消息驱动的原理就是: 1. 有一个消息队列。能够往这个队列中投递消息; 2. 有一个消息循环。不断从消息队列中取出消息。然后进行处理。 在Android中通过Looper来封装消息循环。同一时候在当中封装了一个消息队列MessageQueue。 另外Android给我们提供了一个封装类。来运行消息的投递,消息的处理,即Handler。 <!--more--> 在我们的线程中实现消息循环时,须要创建Looper,如: class LooperThread extends Thread { public Handler mHandler; public void run() { Looper.prepare(); //1.调用prepare ...... Looper.loop(); //2.进入消息循环 } } 看上面的代码。事实上就是先准备Looper,然后进入消息循环。 1. 在prepare的时候。创建一个Looper。同一时候在Looper的构造方法中创建一个消息队列MessageQueue,同一时候将Looper保存到TLV中(这个是关于ThreadLocal的。不太懂。以后研究了再说) 2. 调用loop进入消息循环。此处事实上就是不断到MessageQueue中取消息Message。进行处理。 然后再看我们怎样借助Handler来发消息到队列和处理消息 Handler的成员(非所有): final MessageQueue mQueue; final Looper mLooper; final Callback mCallback; Message的成员(非所有): Handler target; Runnable callback; 能够看到Handler的成员包括Looper,通过查看源码,我们能够发现这个Looper是有两种方式获得的,1是在构造函数传进来。2是使用当前线程的Looper(假设当前线程无Looper,则会报错。我们在Activity中创建Handler不须要传Handler是由于Activity本身已经有一个Looper了),MessageQueue也就是Looper中的消息队列。 然后我们看怎么向消息队列发送消息。Handler有非常多方法发送队列(这个自己能够去查),比方我们看sendMessageDelayed(Message msg, long delayMillis) public final boolean sendMessageDelayed(Message msg, long delayMillis) { if (delayMillis < 0) { delayMillis = 0; } return sendMessageAtTime(msg, SystemClock.uptimeMillis() + delayMillis); // SystemClock.uptimeMillis() 获取开机到如今的时间 } //终于全部的消息是通过这个发。uptimeMillis是绝对时间(从开机那一秒算起) public boolean sendMessageAtTime(Message msg, long uptimeMillis) { boolean sent = false; MessageQueue queue = mQueue; if (queue != null) { msg.target = this; sent = queue.enqueueMessage(msg, uptimeMillis); } return sent; } 看上面的的代码。能够看到Handler将自己设为Message的target。然后然后将msg放到队列中,而且指定运行时间。 消息处理 处理消息,即Looper从MessageQueue中取出队列后,调用msg.target的dispatchMessage方法进行处理。此时会依照消息处理的优先级来处理: 1. 若msg本身有callback,则交其处理; 2. 若Handler有全局callback,则交由其处理; 3. 以上两种都没有,则交给Handler子类实现的handleMessage处理。此时须要重载handleMessage。 我们通常採用第三种方式进行处理。 注意! ! !!我们通常是採用多线程,当创建Handler时,LooperThread中可能还未完毕Looper的创建,此时,Handler中无Looper,操作会报错。 我们能够採用Android为我们提供的HandlerThread来解决,该类已经创建了Looper,而且通过wait/notifyAll来避免错误的发生,降低我们反复造车的事情。我们创建该对象后。调用getLooper()就可以获得Looper(Looper未创建时会等待)。 补充 本文所属为Android中java层的消息循环机制,其在Native层还有消息循环。有单独的Looper。而且2.3以后MessageQueue的核心向Native层下移,native层java层均能够使用。这个我没有过多的研究了!哈哈 本文转自mfrbuaa博客园博客,原文链接:http://www.cnblogs.com/mfrbuaa/p/5119113.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

Drawable以及资源分析

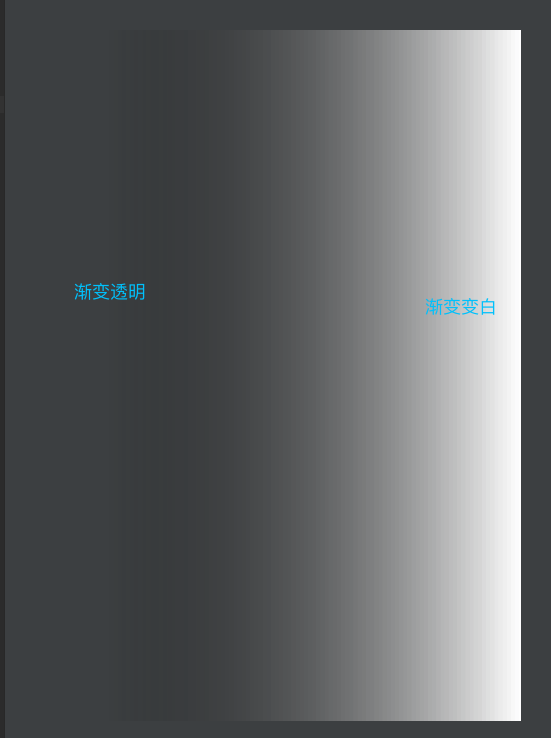
drawable是一个抽象类,他把资源文件夹下的Drawable用其子类进行实例化,然后绘制.so,我们只是在drawble资源中进行了配置,其绘制过程在对应的实现类中. 本文举例几种不常见的drawable...... 1.BitmapDrawble Bitmap-->位图 Bitmap是存储图片的一个类,构造成的是一个位图.构造过程在native方法中. Drawable-->绘制 A Drawable is a general abstraction for "something that can be drawn." Most * often you will deal with Drawable as the type of resource retrieved for * drawing things to the screen. *drawable是一个抽象类,可以对资源进行绘制的工具类. 说一下Bitmap和Drawable的关系 Drawable的子类BitmapDrawble是对bitmap的包装类,在他的BitmapState中有一个bitmap对象引用.也就是说可以通过转型得到bitmap BitmapDrawable bd = (BitmapDrawable) drawable; Bitmap bm= bd.getBitmap(); 下是他注释的翻译. A Drawable that wraps a bitmap and can be tiled, stretched, or aligned. You can create a BitmapDrawable from a file path, an input stream, through XML inflation, or from a {@link android.graphics.Bitmap} object. BitmapDrawble是一个bitmap的包装类,可以对bitmap进行平铺,拉伸和对齐等.可以通过IO,文件,xml或者bitmap构建对象 2.ShapeDrawable ShapeDrawable是最常见的,他通过xml的drawable构建shape得到. 它对应的类不是ShapeDrawable,而是android.graphics.drawable.GradientDrawable.....害我找了好久shape中的ring等方法,好坑. 我们可以通过这个绘制我们想要的效果 比如,我们绘制一层蒙层效果,效果不错. <?xml version="1.0" encoding="utf-8"?> <shape xmlns:android="http://schemas.android.com/apk/res/android"> <gradient android:angle="180" android:endColor="@android:color/transparent" android:startColor="@android:color/white" /> </shape> image.png 3.LayerDrawable LayerDrawable对应的是XML的<layer-list>,他是一种层次化的Drawable,类似于层叠效果. 这种我们可以做这种需求,比如需要对一个自定义控件进行底部画线,或者用线半包含底边,我们可以用.9图,或者用layer_list实现,作为background.比如 <?xml version="1.0" encoding="utf-8"?> <layer-list xmlns:android="http://schemas.android.com/apk/res/android"> <item > <shape android:shape="rectangle"> <solid android:color="#0ac39e"></solid> </shape> </item> <item android:bottom="10dp"> <shape android:shape="rectangle"> <solid android:color="#ffffff"></solid> </shape> </item> <item android:right="3dp" android:bottom="3dp" android:left="3dp"> <shape android:shape="rectangle"> <solid android:color="#ffffff"></solid> </shape> </item> </layer-list> image.png 4.StateListDrawable 对应着<Selector> 根据状态进行不同的操作.不做赘述. LevelListDrawable 对应着<level-list>标签,它可以根据level不同,改变相应的drawable.额....感觉和直接setImageVIew差不多.... <?xml version="1.0" encoding="utf-8"?> <level-list xmlns:android="http://schemas.android.com/apk/res/android"> <item android:minLevel="0" android:maxLevel="3" android:drawable="@color/colorAccent"></item> <item android:minLevel="4" android:maxLevel="6" android:drawable="@color/colorPrimary"></item> <item android:minLevel="7" android:maxLevel="9" android:drawable="@color/colorPrimaryDark"></item> </level-list> //两种调用方式 drawable.setLevel(0); imageView.setImageLevel(0);

优秀的个人博客,低调大师

Spark 源码分析 -- RDD

关于RDD, 详细可以参考Spark的论文, 下面看下源码 A Resilient Distributed Dataset (RDD), the basic abstraction in Spark. Represents an immutable, partitioned collection of elements that can be operated on in parallel. * Internally, each RDD is characterized by five main properties: * - A list of partitions * - A function for computing each split * - A list of dependencies on other RDDs * - Optionally, a Partitioner for key-value RDDs (e.g. to say that the RDD is hash-partitioned) * - Optionally, a list of preferred locations to compute each split on (e.g. block locations for an HDFS file) RDD分为一下几类, basic(org.apache.spark.rdd.RDD): This class contains the basic operations available on all RDDs, such as `map`, `filter`, and `persist`. org.apache.spark.rdd.PairRDDFunctions: contains operations available only on RDDs ofkey-value pairs, such as `groupByKey` and `join` org.apache.spark.rdd.DoubleRDDFunctions: contains operations available only on RDDs ofDoubles org.apache.spark.rdd.SequenceFileRDDFunctions: contains operations available on RDDs that can be saved asSequenceFiles RDD首先是泛型类, T表示存放数据的类型, 在处理数据是都是基于Iterator[T] 以SparkContext和依赖关系Seq deps为初始化参数 从RDD提供的这些接口大致就可以知道, 什么是RDD 1. RDD是一块数据, 可能比较大的数据, 所以不能保证可以放在一个机器的memory中, 所以需要分成partitions, 分布在集群的机器的memory 所以自然需要getPartitions, partitioner如果分区, getPreferredLocations分区如何考虑locality Partition的定义很简单, 只有id, 不包含data trait Partition extends Serializable { /** * Get the split's index within its parent RDD */ def index: Int // A better default implementation of HashCode override def hashCode(): Int = index } 2. RDD之间是有关联的, 一个RDD可以通过compute逻辑把父RDD的数据转化成当前RDD的数据, 所以RDD之间有因果关系 并且通过getDependencies, 可以取到所有的dependencies 3. RDD是可以被persisit的, 常用的是cache, 即StorageLevel.MEMORY_ONLY 4. RDD是可以被checkpoint的, 以提高failover的效率, 当有很长的RDD链时, 单纯的依赖replay会比较低效 5. RDD.iterator可以产生用于迭代真正数据的Iterator[T] 6. 在RDD上可以做各种transforms和actions abstract class RDD[T: ClassManifest]( @transient private var sc: SparkContext, //@transient, 不需要序列化 @transient private var deps: Seq[Dependency[_]] ) extends Serializable with Logging { /**辅助构造函数, 专门用于初始化1对1依赖关系的RDD,这种还是很多的, filter, map... Construct an RDD with just a one-to-one dependency on one parent */ def this(@transient oneParent: RDD[_]) = this(oneParent.context , List(new OneToOneDependency(oneParent))) // 不同于一般的RDD, 这种情况因为只有一个parent, 所以直接传入parent RDD对象即可 // ======================================================================= // Methods that should be implemented by subclasses of RDD // ======================================================================= /** Implemented by subclasses to compute a given partition. */ def compute(split: Partition, context: TaskContext): Iterator[T] /** * Implemented by subclasses to return the set of partitions in this RDD. This method will only * be called once, so it is safe to implement a time-consuming computation in it. */ protected def getPartitions: Array[Partition] /** * Implemented by subclasses to return how this RDD depends on parent RDDs. This method will only * be called once, so it is safe to implement a time-consuming computation in it. */ protected def getDependencies: Seq[Dependency[_]] = deps /** Optionally overridden by subclasses to specify placement preferences. */ protected def getPreferredLocations(split: Partition): Seq[String] = Nil /** Optionally overridden by subclasses to specify how they are partitioned. */ val partitioner: Option[Partitioner] = None // ======================================================================= // Methods and fields available on all RDDs // ======================================================================= /** The SparkContext that created this RDD. */ def sparkContext: SparkContext = sc /** A unique ID for this RDD (within its SparkContext). */ val id: Int = sc.newRddId() /** A friendly name for this RDD */ var name: String = null /** * Set this RDD's storage level to persist its values across operations after the first time * it is computed. This can only be used to assign a new storage level if the RDD does not * have a storage level set yet.. */ def persist(newLevel: StorageLevel): RDD[T] = { // TODO: Handle changes of StorageLevel if (storageLevel != StorageLevel.NONE && newLevel != storageLevel) { throw new UnsupportedOperationException( "Cannot change storage level of an RDD after it was already assigned a level") } storageLevel = newLevel // Register the RDD with the SparkContext sc.persistentRdds(id) = this this } /** Persist this RDD with the default storage level (`MEMORY_ONLY`). */ def persist(): RDD[T] = persist(StorageLevel.MEMORY_ONLY) /** Persist this RDD with the default storage level (`MEMORY_ONLY`). */ def cache(): RDD[T] = persist() /** Get the RDD's current storage level, or StorageLevel.NONE if none is set. */ def getStorageLevel = storageLevel // Our dependencies and partitions will be gotten by calling subclass's methods below, and will // be overwritten when we're checkpointed private var dependencies_ : Seq[Dependency[_]] = null @transient private var partitions_ : Array[Partition] = null /** An Option holding our checkpoint RDD, if we are checkpointed * checkpoint就是把RDD存到磁盘文件中, 以提高failover的效率, 虽然也可以选择replay * 并且在RDD的实现中, 如果存在checkpointRDD, 则可以直接从中读到RDD数据, 而不需要compute */ private def checkpointRDD: Option[RDD[T]] = checkpointData.flatMap(_.checkpointRDD) /** * Internal method to this RDD; will read from cache if applicable, or otherwise compute it. * This should ''not'' be called by users directly, but is available for implementors of custom * subclasses of RDD. */ /** 这是RDD访问数据的核心, 在RDD中的Partition中只包含id而没有真正数据 * 那么如果获取RDD的数据? 参考storage模块 * 在cacheManager.getOrCompute中, 会将RDD和Partition id对应到相应的block, 并从中读出数据*/ final def iterator(split: Partition, context: TaskContext): Iterator[T] = { if (storageLevel != StorageLevel.NONE) {//StorageLevel不为None,说明这个RDD persist过, 可以直接读出来 SparkEnv.get.cacheManager.getOrCompute(this, split, context, storageLevel) } else { computeOrReadCheckpoint(split, context) //如果没有persisit过, 只有从新计算出, 或从checkpoint中读出 } } // Transformations (return a new RDD) //...... 各种transformations的接口,map, union... /** * Return a new RDD by applying a function to all elements of this RDD. */ def map[U: ClassManifest](f: T => U): RDD[U] = new MappedRDD(this, sc.clean(f)) // Actions (launch a job to return a value to the user program) //......各种actions的接口,count, collect... /** * Return the number of elements in the RDD. */ def count(): Long = {// 只有在action中才会真正调用runJob, 所以transform都是lazy的 sc.runJob(this, (iter: Iterator[T]) => { var result = 0L while (iter.hasNext) { result += 1L iter.next() } result }).sum } // ======================================================================= // Other internal methods and fields // ======================================================================= /** Returns the first parent RDD 返回第一个parent RDD*/ protected[spark] def firstParent[U: ClassManifest] = { dependencies.head.rdd.asInstanceOf[RDD[U]] } //................ } 这里先只讨论一些basic的RDD, pairRDD会单独讨论 FilteredRDD One-to-one Dependency, FilteredRDD 使用FilteredRDD, 将当前RDD作为第一个参数, f函数作为第二个参数, 返回值是filter过后的RDD /** * Return a new RDD containing only the elements that satisfy a predicate. */ def filter(f: T => Boolean): RDD[T] = new FilteredRDD(this, sc.clean(f)) 在compute中, 对parent RDD的Iterator[T]进行filter操作 private[spark] class FilteredRDD[T: ClassManifest]( //filter是典型的one-to-one dependency, 使用辅助构造函数 prev: RDD[T], //parent RDD f: T => Boolean) //f,过滤函数 extends RDD[T](prev) { //firstParent会从deps中取出第一个RDD对象, 就是传入的prev RDD, 在One-to-one Dependency中,parent和child的partition信息相同 override def getPartitions: Array[Partition] = firstParent[T].partitions override val partitioner = prev.partitioner // Since filter cannot change a partition's keys override def compute(split: Partition, context: TaskContext) = firstParent[T].iterator(split, context).filter(f) //compute就是真正产生RDD的逻辑 } UnionRDD Range Dependency, 仍然是narrow的 先看看如果使用union的, 第二个参数是, 两个RDD的array, 返回值就是把这两个RDD union后产生的新的RDD /** * Return the union of this RDD and another one. Any identical elements will appear multiple * times (use `.distinct()` to eliminate them). */ def union(other: RDD[T]): RDD[T] = new UnionRDD(sc, Array(this, other)) 先定义UnionPartition, Union操作的特点是, 只是把多个RDD的partition合并到一个RDD中, 而partition本身没有变化, 所以可以直接重用parent partition 3个参数 idx, partition id, 在当前UnionRDD中的序号 rdd, parent RDD splitIndex, parent partition的id private[spark] class UnionPartition[T: ClassManifest](idx: Int, rdd: RDD[T], splitIndex: Int) extends Partition { var split: Partition = rdd.partitions(splitIndex)//从parent RDD中取出相应的partition, 重用 def iterator(context: TaskContext) = rdd.iterator(split, context)//Iterator也可以重用 def preferredLocations() = rdd.preferredLocations(split) override val index: Int = idx//partition id是新的, 因为多个合并后, 序号肯定会发生变化 } 定义UnionRDD class UnionRDD[T: ClassManifest]( sc: SparkContext, @transient var rdds: Seq[RDD[T]]) //parent RDD Seq extends RDD[T](sc, Nil) { // Nil since we implement getDependencies override def getPartitions: Array[Partition] = { val array = new Array[Partition](rdds.map(_.partitions.size).sum) //UnionRDD的partition数,是所有parent RDD中的partition数目的和 var pos = 0 for (rdd <- rdds; split <- rdd.partitions) { array(pos) = new UnionPartition(pos, rdd, split.index) //创建所有的UnionPartition pos += 1 } array } override def getDependencies: Seq[Dependency[_]] = { val deps = new ArrayBuffer[Dependency[_]] var pos = 0 for (rdd <- rdds) { deps += new RangeDependency(rdd, 0, pos, rdd.partitions.size)//创建RangeDependency pos += rdd.partitions.size)//由于是RangeDependency, 所以pos的递增是加上整个区间size } deps } override def compute(s: Partition, context: TaskContext): Iterator[T] = s.asInstanceOf[UnionPartition[T]].iterator(context)//Union的compute非常简单,什么都不需要做 override def getPreferredLocations(s: Partition): Seq[String] = s.asInstanceOf[UnionPartition[T]].preferredLocations() } 本文章摘自博客园,原文发布日期:2013-12-24

资源下载

更多资源
Mario

Mario

马里奥是站在游戏界顶峰的超人气多面角色。马里奥靠吃蘑菇成长,特征是大鼻子、头戴帽子、身穿背带裤,还留着胡子。与他的双胞胎兄弟路易基一起,长年担任任天堂的招牌角色。

Nacos

Nacos

Nacos /nɑ:kəʊs/ 是 Dynamic Naming and Configuration Service 的首字母简称,一个易于构建 AI Agent 应用的动态服务发现、配置管理和AI智能体管理平台。Nacos 致力于帮助您发现、配置和管理微服务及AI智能体应用。Nacos 提供了一组简单易用的特性集,帮助您快速实现动态服务发现、服务配置、服务元数据、流量管理。Nacos 帮助您更敏捷和容易地构建、交付和管理微服务平台。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

WebStorm

WebStorm

WebStorm 是jetbrains公司旗下一款JavaScript 开发工具。目前已经被广大中国JS开发者誉为“Web前端开发神器”、“最强大的HTML5编辑器”、“最智能的JavaScript IDE”等。与IntelliJ IDEA同源,继承了IntelliJ IDEA强大的JS部分的功能。

用户登录
用户注册