首页 文章 精选 留言 我的

精选列表

搜索[自适应爬虫],共4656篇文章
优秀的个人博客,低调大师

Python爬虫——你们要的王者荣耀高清图

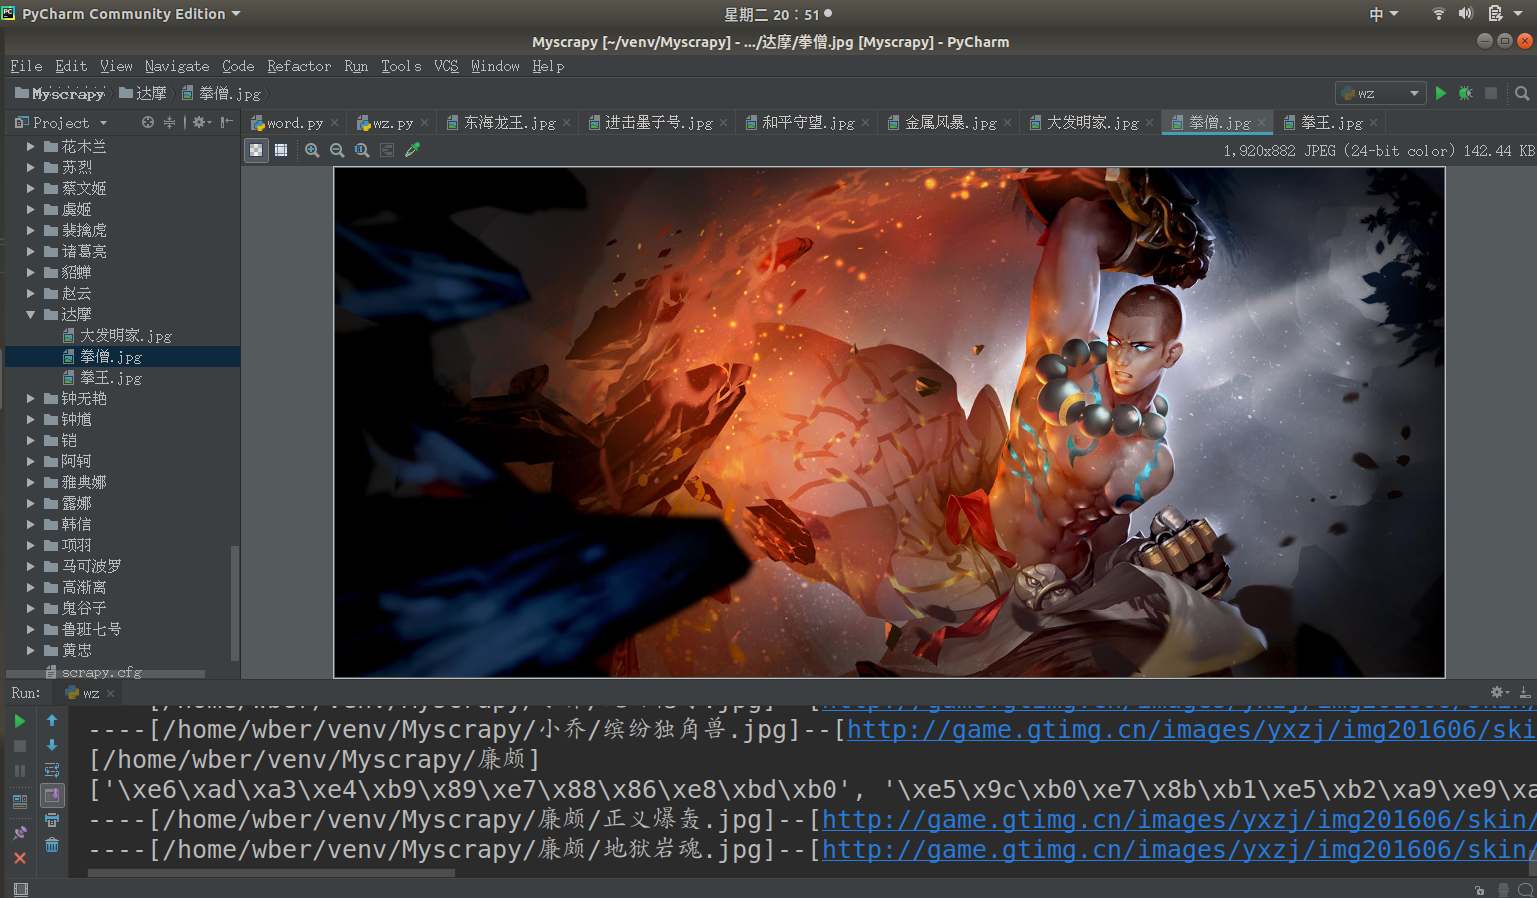
曾经144区的王者 学了计算机后 头发逐渐从李白变成了达摩 秀发有何用,变秃亦变强 (emmm徒弟说李白比达摩强,变秃不一定变强) 前言 前几天开了农药的安装包,发现农药是.Net实现的游戏 虽然游戏用的语言和排位一样让人恼火 但感觉图片美工还是可以的 比如: 不知...不知道你们是不是和我一样喜欢 玩阴阳师呢,我可是Ssr只有两只狗子的非酋呢 正文 在http://pvp.qq.com/web201605/herolist.shtml可以看到全英雄列表。 按F12查看元素 看到下面这一堆<li></li>标签了吗 里面的href就是每个英雄的详情地址 图片就在这个链接中 拿到selector body > div.wrapper > div > div > div.herolist-box > div.herolist-content > ul > li > a 英雄列表获取源码: 1 def getHeroList(): 2 '''取所以英雄存入list中''' 3 hero = {} 4 res = requests.get(mainurl) 5 sp = BeautifulSoup(res.content, "html.parser") 6 lists = sp.select('body > div.wrapper > div > div > div.herolist-box > div.herolist-content > ul > li') 7 for li in lists: 8 oj = li.select('a')[0]; 9 hero['url'] = oj['href'] 10 hero['name'] = oj.text 11 # 正则表达式取ename编号 12 ename = re.findall('herodetail/(\d+)\.shtml', oj['href'])[0] 13 hero['ename'] = ename 14 herolist.append(hero) 15 hero = {} 16 return herolist 进入英雄详情之后 可以发现,要保存图片的地址也在<li></li>中 他的selector是: body > div.wrapper > div.zk-con1.zk-con > div > div > div.pic-pf > ul > li > i > img 只需要将这个图片保存下来就可以了 代码: 1 def saveImg(filepath, imgUrl): 2 '''下载图片并保存''' 3 r = requests.get(imgUrl, stream=True) 4 with open(filepath, 'wb') as f: 5 for chunk in r.iter_content(chunk_size=1024): 6 if chunk: 7 f.write(chunk) 8 f.flush() 9 f.close() 全部代码: 1 # -*- coding: utf-8 -*- 2 3 import os 4 import re 5 import requests 6 from bs4 import BeautifulSoup 7 8 import sys 9 reload(sys) 10 sys.setdefaultencoding('utf-8') 11 12 baseurl = 'http://pvp.qq.com/web201605' 13 mainurl = 'http://pvp.qq.com/web201605/herolist.shtml' 14 herolist = [] 15 16 17 def getHeroList(): 18 '''取所以英雄存入list中''' 19 hero = {} 20 res = requests.get(mainurl) 21 sp = BeautifulSoup(res.content, "html.parser") 22 lists = sp.select('body > div.wrapper > div > div > div.herolist-box > div.herolist-content > ul > li') 23 for li in lists: 24 oj = li.select('a')[0]; 25 hero['url'] = oj['href'] 26 hero['name'] = oj.text 27 # 正则表达式取ename编号 28 ename = re.findall('herodetail/(\d+)\.shtml', oj['href'])[0] 29 hero['ename'] = ename 30 herolist.append(hero) 31 hero = {} 32 return herolist 33 34 35 def saveImg(filepath, imgUrl): 36 '''下载图片并保存''' 37 r = requests.get(imgUrl, stream=True) 38 with open(filepath, 'wb') as f: 39 for chunk in r.iter_content(chunk_size=1024): 40 if chunk: 41 f.write(chunk) 42 f.flush() 43 f.close() 44 45 46 if __name__ == '__main__': 47 hlist = getHeroList() 48 for hero in herolist: 49 herodir = os.path.join(os.getcwd(), hero['name']) 50 heropage = baseurl + '/' + hero['url'] 51 print('[%s]' % (herodir)) 52 res = requests.get(heropage) 53 sop = BeautifulSoup(res.content, "html.parser") 54 li = sop.select('body > div.wrapper > div.zk-con1.zk-con > div > div > div.pic-pf > ul ')[0]['data-imgname'] 55 li = str(li).split('|') 56 print(li) 57 # 遍历所有皮肤 58 for i in range(len(li)): 59 imgurl = 'http://game.gtimg.cn/images/yxzj/img201606/skin/hero-info/' \ 60 + hero['ename'] + '/' + hero['ename'] + '-bigskin-' + str(i + 1) + '.jpg' 61 imgname = os.path.join(herodir, li[i] + ".jpg") 62 print('----[%s]--[%s]---' % (imgname, imgurl)) 63 # 创建英雄目录 64 if os.path.exists(herodir) == False: 65 os.mkdir(herodir) 66 saveImg(imgname, imgurl) 图片生成在同级目录
优秀的个人博客,低调大师

Python爬虫(二)——豆瓣图书决策树构建

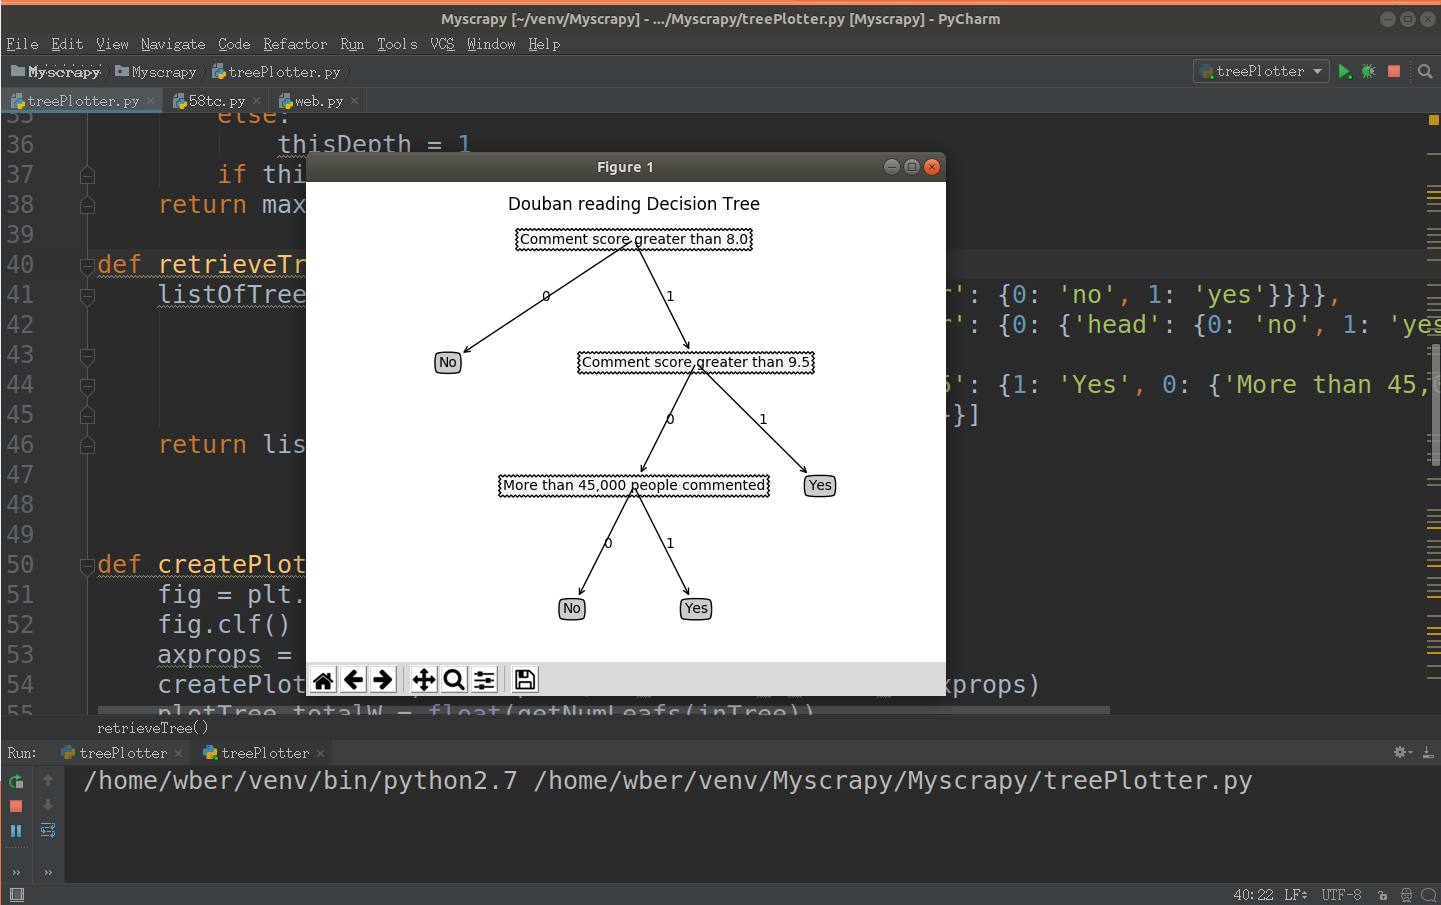
前文参考:https://www.cnblogs.com/LexMoon/p/douban1.html Matplotlib绘制决策树代码: 1 # coding=utf-8 2 import matplotlib.pyplot as plt 3 4 decisionNode = dict(boxstyle='sawtooth', fc='10') 5 leafNode = dict(boxstyle='round4',fc='0.8') 6 arrow_args = dict(arrowstyle='<-') 7 8 9 10 def plotNode(nodeTxt, centerPt, parentPt, nodeType): 11 createPlot.ax1.annotate(nodeTxt, xy=parentPt, xycoords='axes fraction',\ 12 xytext=centerPt,textcoords='axes fraction',\ 13 va='center', ha='center',bbox=nodeType,arrowprops\ 14 =arrow_args) 15 16 17 def getNumLeafs(myTree): 18 numLeafs = 0 19 firstStr = list(myTree.keys())[0] 20 secondDict = myTree[firstStr] 21 for key in secondDict: 22 if(type(secondDict[key]).__name__ == 'dict'): 23 numLeafs += getNumLeafs(secondDict[key]) 24 else: 25 numLeafs += 1 26 return numLeafs 27 28 def getTreeDepth(myTree): 29 maxDepth = 0 30 firstStr = list(myTree.keys())[0] 31 secondDict = myTree[firstStr] 32 for key in secondDict: 33 if(type(secondDict[key]).__name__ == 'dict'): 34 thisDepth = 1+getTreeDepth((secondDict[key])) 35 else: 36 thisDepth = 1 37 if thisDepth > maxDepth: maxDepth = thisDepth 38 return maxDepth 39 40 def retrieveTree(i): 41 #预先设置树的信息 42 listOfTree = [{'no surfacing':{0:'no',1:{'flipper':{0:'no',1:'yes'}}}}, 43 {'no surfacing':{0:'no',1:{'flipper':{0:{'head':{0:'no',1:'yes'}},1:'no'}}}}, 44 {'Comment score greater than 8.0':{0:{'Comment score greater than 9.5':{0:'Yes',1:{'More than 45,000 people commented': { 45 0: 'Yes',1: 'No'}}}},1:'No'}}] 46 return listOfTree[i] 47 48 def createPlot(inTree): 49 fig = plt.figure(1,facecolor='white') 50 fig.clf() 51 axprops = dict(xticks = [], yticks=[]) 52 createPlot.ax1 = plt.subplot(111,frameon = False,**axprops) 53 plotTree.totalW = float(getNumLeafs(inTree)) 54 plotTree.totalD = float(getTreeDepth(inTree)) 55 plotTree.xOff = -0.5/plotTree.totalW;plotTree.yOff = 1.0 56 plotTree(inTree,(0.5,1.0), '') 57 plt.title('Douban reading Decision Tree\n') 58 plt.show() 59 60 def plotMidText(cntrPt, parentPt,txtString): 61 xMid = (parentPt[0]-cntrPt[0])/2.0 + cntrPt[0] 62 yMid = (parentPt[1] - cntrPt[1])/2.0 + cntrPt[1] 63 createPlot.ax1.text(xMid, yMid, txtString) 64 65 def plotTree(myTree, parentPt, nodeTxt): 66 numLeafs = getNumLeafs(myTree) 67 depth = getTreeDepth(myTree) 68 firstStr = list(myTree.keys())[0] 69 cntrPt = (plotTree.xOff+(1.0+float(numLeafs))/2.0/plotTree.totalW,\ 70 plotTree.yOff) 71 plotMidText(cntrPt,parentPt,nodeTxt) 72 plotNode(firstStr,cntrPt,parentPt,decisionNode) 73 secondDict = myTree[firstStr] 74 plotTree.yOff = plotTree.yOff - 1.0/plotTree.totalD 75 for key in secondDict: 76 if type(secondDict[key]).__name__ == 'dict': 77 plotTree(secondDict[key],cntrPt,str(key)) 78 else: 79 plotTree.xOff = plotTree.xOff + 1.0/plotTree.totalW 80 plotNode(secondDict[key],(plotTree.xOff,plotTree.yOff),\ 81 cntrPt,leafNode) 82 plotMidText((plotTree.xOff,plotTree.yOff),cntrPt,str(key)) 83 plotTree.yOff = plotTree.yOff + 1.0/plotTree.totalD 84 85 if __name__ == '__main__': 86 myTree = retrieveTree(2) 87 createPlot(myTree) 运行结果:

优秀的个人博客,低调大师

Python爬虫爬取网易云音乐全部评论

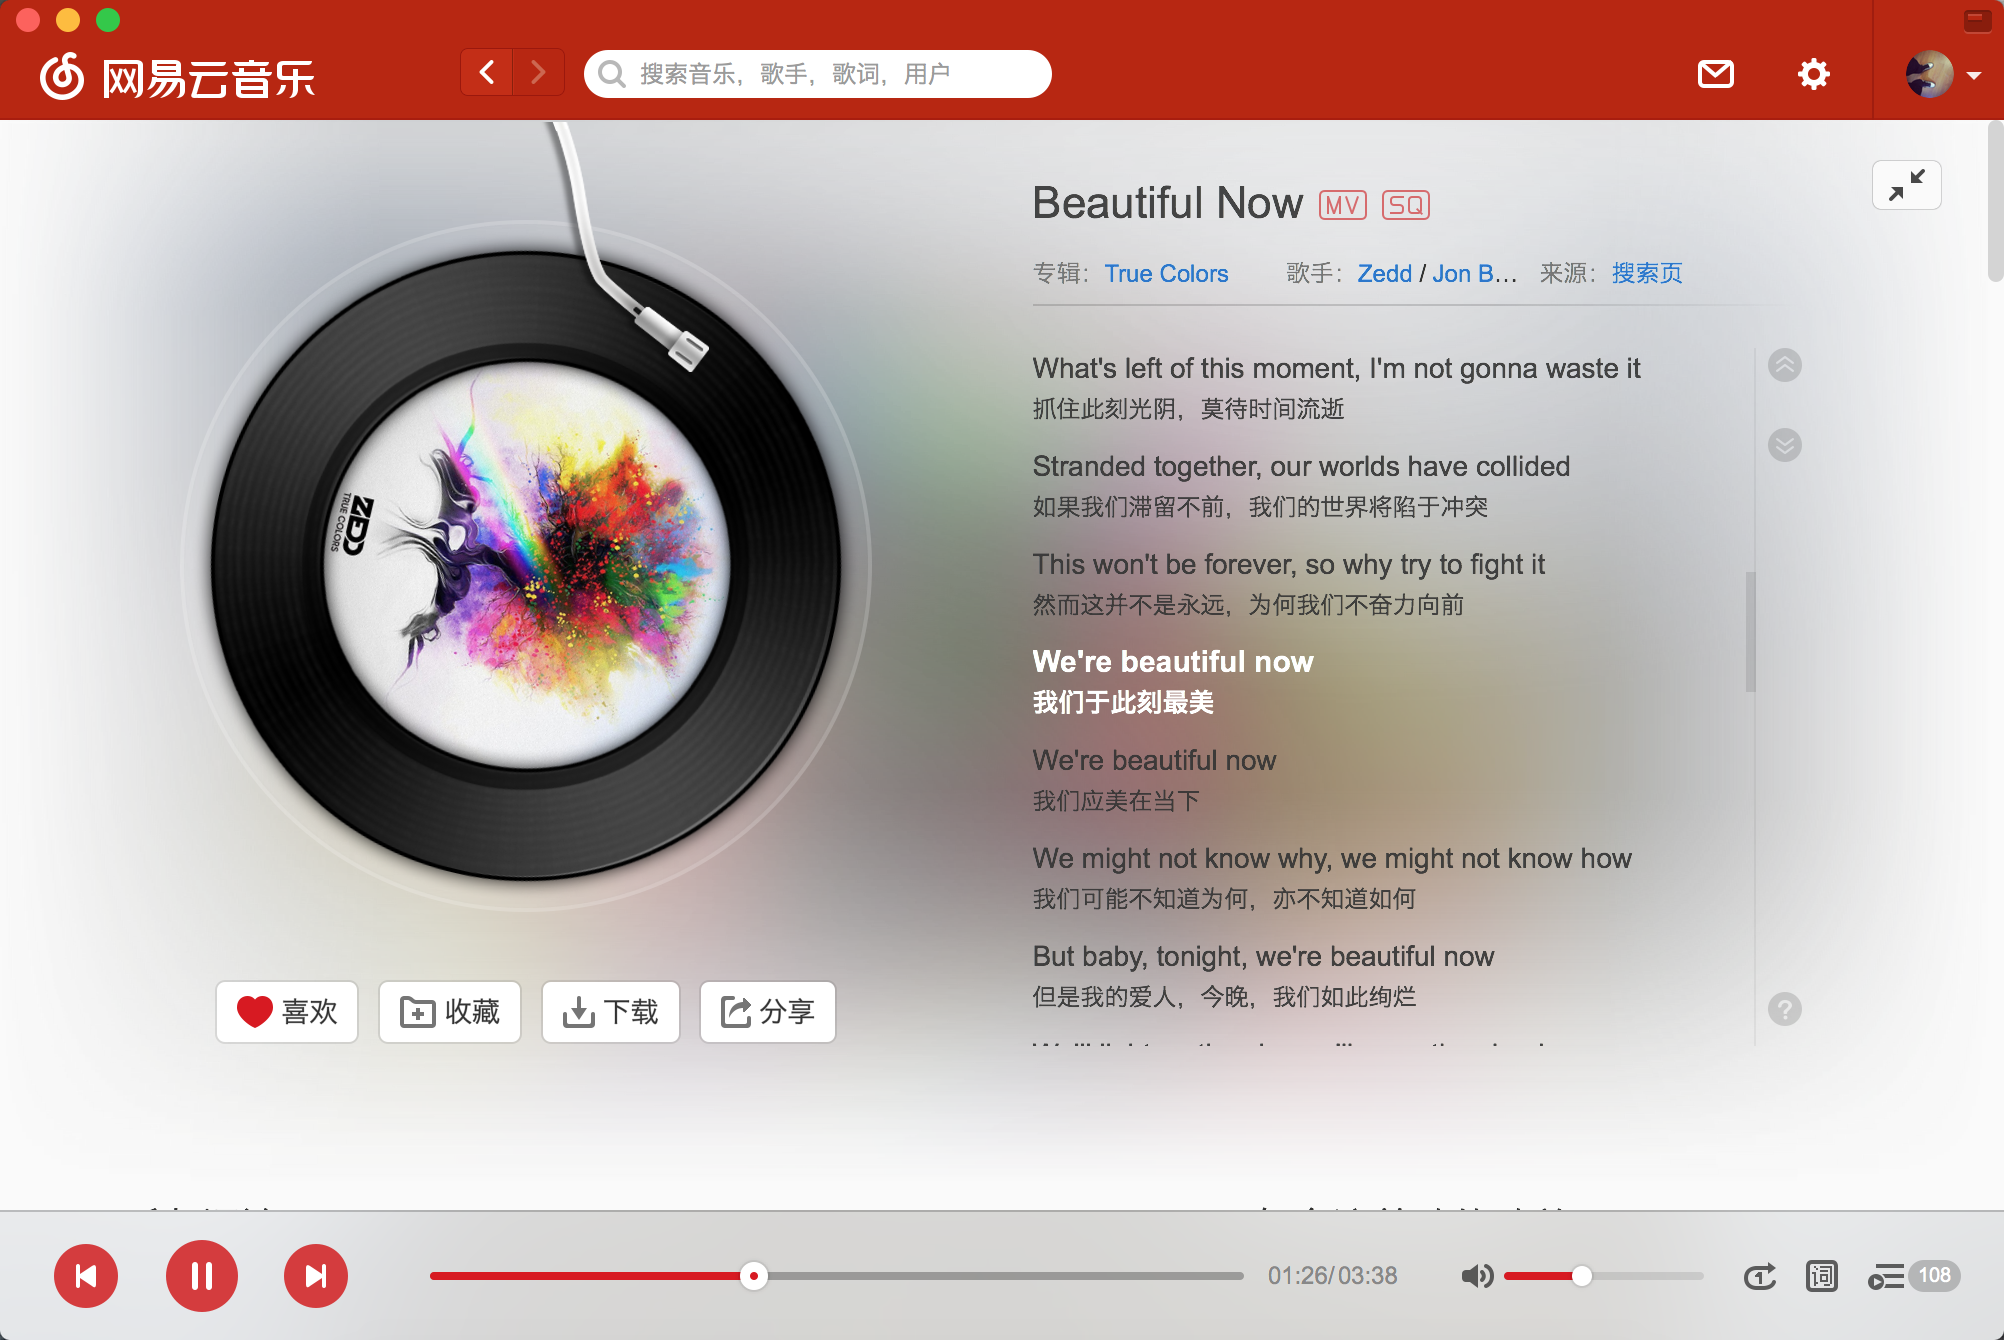
beautiful now.png 思路整理 访问网易云音乐单曲播放界面,我们可以看到当我们翻页的时候网址是没有变化的,这时候我们大致可以确定评论是通过post形式加载的; . 2.接下来就打开控制台找我们要的评论藏在哪里就好了。 我们在http://music.163.com/weapi/v1/resource/comments/R_SO_4_32019002?csrf_token=发现了我们要的评论,包括热门评论,我们注意看下R_SO_4_后面的数字,其实就是每首歌的id,如果我们想一次性爬取多首歌曲的评论的话,可以通过每次传入歌曲id来实现; image.png 我们接下来看下需要post的数据,有两个值params和encSecKey,本以为就是页码之类的,看到这两个值我其实是懵逼的,很显然是加密过了的,不过我不知道他是怎么加密的,后面在知乎上找到了解决方法,各位可以去知乎看看,我就不赘述了,因为我也没看明白……; image.png 代码部分 加密 前文说了,这部分参考了知乎的一位答主,各位可以去知乎看看,我这边只是稍微改了下就拿来用了,点这里跳转; first_param = '{rid:"", offset:"0", total:"true", limit:"20", csrf_token:""}' second_param = "010001" third_param = "00e0b509f6259df8642dbc35662901477df22677ec152b5ff68ace615bb7b725152b3ab17a876aea8a5aa76d2e417629ec4ee341f56135fccf695280104e0312ecbda92557c93870114af6c9d05c4f7f0c3685b7a46bee255932575cce10b424d813cfe4875d3e82047b97ddef52741d546b8e289dc6935b3ece0462db0a22b8e7" forth_param = "0CoJUm6Qyw8W8jud" def get_params(i): if i == 0: first_param = '{rid:"", offset:"0", total:"true", limit:"20", csrf_token:""}' else: offset =str(i*20) first_param = '{rid:"", offset:"%s", total:"%s", limit:"20", csrf_token:""}'%(offset,'flase') iv = "0102030405060708" first_key = forth_param second_key = 16 * 'F' h_encText = AES_encrypt(first_param, first_key, iv) h_encText = AES_encrypt(h_encText, second_key, iv) return h_encText def get_encSecKey(): encSecKey = "257348aecb5e556c066de214e531faadd1c55d814f9be95fd06d6bff9f4c7a41f831f6394d5a3fd2e3881736d94a02ca919d952872e7d0a50ebfa1769a7a62d512f5f1ca21aec60bc3819a9c3ffca5eca9a0dba6d6f7249b06f5965ecfff3695b54e1c28f3f624750ed39e7de08fc8493242e26dbc4484a01c76f739e135637c" return encSecKey def AES_encrypt(text, key, iv): pad = 16 - len(text) % 16 text = text + pad * chr(pad) encryptor = AES.new(key, AES.MODE_CBC, iv) encrypt_text = encryptor.encrypt(text) encrypt_text = base64.b64encode(encrypt_text) return encrypt_text 获取页码以及评论 获取页码数是为了加入循环获取每页的评论,代码如下; def get_json(url, params, encSecKey): data = { "params": params, "encSecKey": encSecKey } response = requests.post(url, headers=headers, data=data,proxies = proxies) return response.content def get_page(url): params = get_params(0); encSecKey = get_encSecKey(); json_text = get_json(url, params, encSecKey) json_dict = json.loads(json_text) total_comment = json_dict['total'] page=(total_comment/20)+1 print '***查询到评论共计%d条,%d页***'%(total_comment,page) return page 最后就是把json数据按照你想要的保存下来就好了,如果只想要热门评论的话,把comments改成hotcomments就好了。 完整代码如下: #coding = utf-8 from Crypto.Cipher import AES import base64 import requests import json import time import pandas as pd import random headers = { 'Referer': 'http://music.163.com/song?id=531051217', 'User-Agent':'Mozilla/5.0 (Windows NT 6.1; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/58.0.3029.110 Safari/537.36', 'Cookie': 'JSESSIONID-WYYY=%5CuiUi%5C%2FYs%2FcJcoQ5xd3cBhaHw0rEfHkss1s%2FCfr92IKyg2hJOrJquv3fiG2%2Fn9GZS%2FuDH8PY81zGquF4GIAVB9eYSdKJM1W6E2i1KFg9%5CuZ4xU6VdPCGwp4KOUZQQiWSlRT%2F1r07OmIBn7yYVYN%2BM2MAalUQnoYcyskaXN%5CPo1AOyVVV%3A1516866368046; _iuqxldmzr_=32; _ntes_nnid=7e2e27f69781e78f2c610fa92434946b,1516864568068; _ntes_nuid=7e2e27f69781e78f2c610fa92434946b; __utma=94650624.470888446.1516864569.1516864569.1516864569.1; __utmc=94650624; __utmz=94650624.1516864569.1.1.utmcsr=baidu|utmccn=(organic)|utmcmd=organic; __utmb=94650624.8.10.1516864569' } proxies = {'http':'http://221.200.107.118','https':'http://116.2.25.251'} first_param = '{rid:"", offset:"0", total:"true", limit:"20", csrf_token:""}' second_param = "010001" third_param = "00e0b509f6259df8642dbc35662901477df22677ec152b5ff68ace615bb7b725152b3ab17a876aea8a5aa76d2e417629ec4ee341f56135fccf695280104e0312ecbda92557c93870114af6c9d05c4f7f0c3685b7a46bee255932575cce10b424d813cfe4875d3e82047b97ddef52741d546b8e289dc6935b3ece0462db0a22b8e7" forth_param = "0CoJUm6Qyw8W8jud" def get_params(i): if i == 0: first_param = '{rid:"", offset:"0", total:"true", limit:"20", csrf_token:""}' else: offset =str(i*20) first_param = '{rid:"", offset:"%s", total:"%s", limit:"20", csrf_token:""}'%(offset,'flase') iv = "0102030405060708" first_key = forth_param second_key = 16 * 'F' h_encText = AES_encrypt(first_param, first_key, iv) h_encText = AES_encrypt(h_encText, second_key, iv) return h_encText def get_encSecKey(): encSecKey = "257348aecb5e556c066de214e531faadd1c55d814f9be95fd06d6bff9f4c7a41f831f6394d5a3fd2e3881736d94a02ca919d952872e7d0a50ebfa1769a7a62d512f5f1ca21aec60bc3819a9c3ffca5eca9a0dba6d6f7249b06f5965ecfff3695b54e1c28f3f624750ed39e7de08fc8493242e26dbc4484a01c76f739e135637c" return encSecKey def AES_encrypt(text, key, iv): pad = 16 - len(text) % 16 text = text + pad * chr(pad) encryptor = AES.new(key, AES.MODE_CBC, iv) encrypt_text = encryptor.encrypt(text) encrypt_text = base64.b64encode(encrypt_text) return encrypt_text def get_json(url, params, encSecKey): data = { "params": params, "encSecKey": encSecKey } response = requests.post(url, headers=headers, data=data,proxies = proxies) return response.content def get_page(url): params = get_params(0); encSecKey = get_encSecKey(); json_text = get_json(url, params, encSecKey) json_dict = json.loads(json_text) total_comment = json_dict['total'] page=(total_comment/20)+1 print '***查询到评论共计%d条,%d页***'%(total_comment,page) return page if __name__ == "__main__": start_time = time.time() url = "http://music.163.com/weapi/v1/resource/comments/R_SO_4_32019002?csrf_token=" page = get_page(url) for i in range(page): params = get_params(i); encSecKey = get_encSecKey(); json_text = get_json(url, params, encSecKey) json_dict = json.loads(str(json_text))['comments'] for t in list(range(len(json_dict))): if t == 0: rdata=pd.DataFrame(pd.Series(data=json_dict[t])).T else: rdata=pd.concat([rdata,pd.DataFrame(pd.Series(data=json_dict[t])).T]) if i == 0: commentdata=rdata else: commentdata=pd.concat([commentdata,rdata]) print('***正在保存第%d页***'%(i+1)) time.sleep(random.uniform(0.2,0.5)) commentdata.to_excel('NetEase_Music_Spider.xls',sheet_name='sheet1') end_time = time.time() print "程序耗时%f秒." % (end_time - start_time) print '***NetEase_Music_Spider@Awesome_Tang***' 本次爬的是最近一直循环的<beautiful now--Zedd/Jon Bellion>,评论共计37429条,1872页,程序耗时1036.046966秒,接近20分钟。 Notes 各位爬的时候一定要使用代理IP,我后面准备爬周董最近的新歌<等你下课>的评论的,爬到5000多页也就是差不多10W条的时候,被封IP了,导致我们整个公司的网络都一段时间内不能访问网易云音乐的评论,包括手机连Wi-Fi... image.png Peace~

优秀的个人博客,低调大师

Python爬虫入门教程 52-100 Python3爬虫获取博客园文章定时发送到邮箱

写在前面 关于获取文章自动发送到邮箱,这类需求其实可以写好几个网站,弄完博客园,弄CSDN,弄掘金,弄其他的,网站多的是呢~哈哈 先从博客园开始,基本需求,获取python板块下面的新文章,间隔60分钟发送一次,时间太短估摸着没有多少新博客产出~ 抓取的页面就是这个 https://www.cnblogs.com/cate/python 需求整理 获取指定页面的所有文章,记录文章相关信息,并且记录最后一篇文章的时间 将文章发送到指定邮箱,更新最后一篇文章的时间 实际编码环节 查看一下需要导入的模块 模块清单 import requests import time import re import smtplib from email.mime.text import MIMEText from email.utils import formatadd

优秀的个人博客,低调大师

基于GeoTools的GIS专题图自适应边界及高宽等比例生成实践

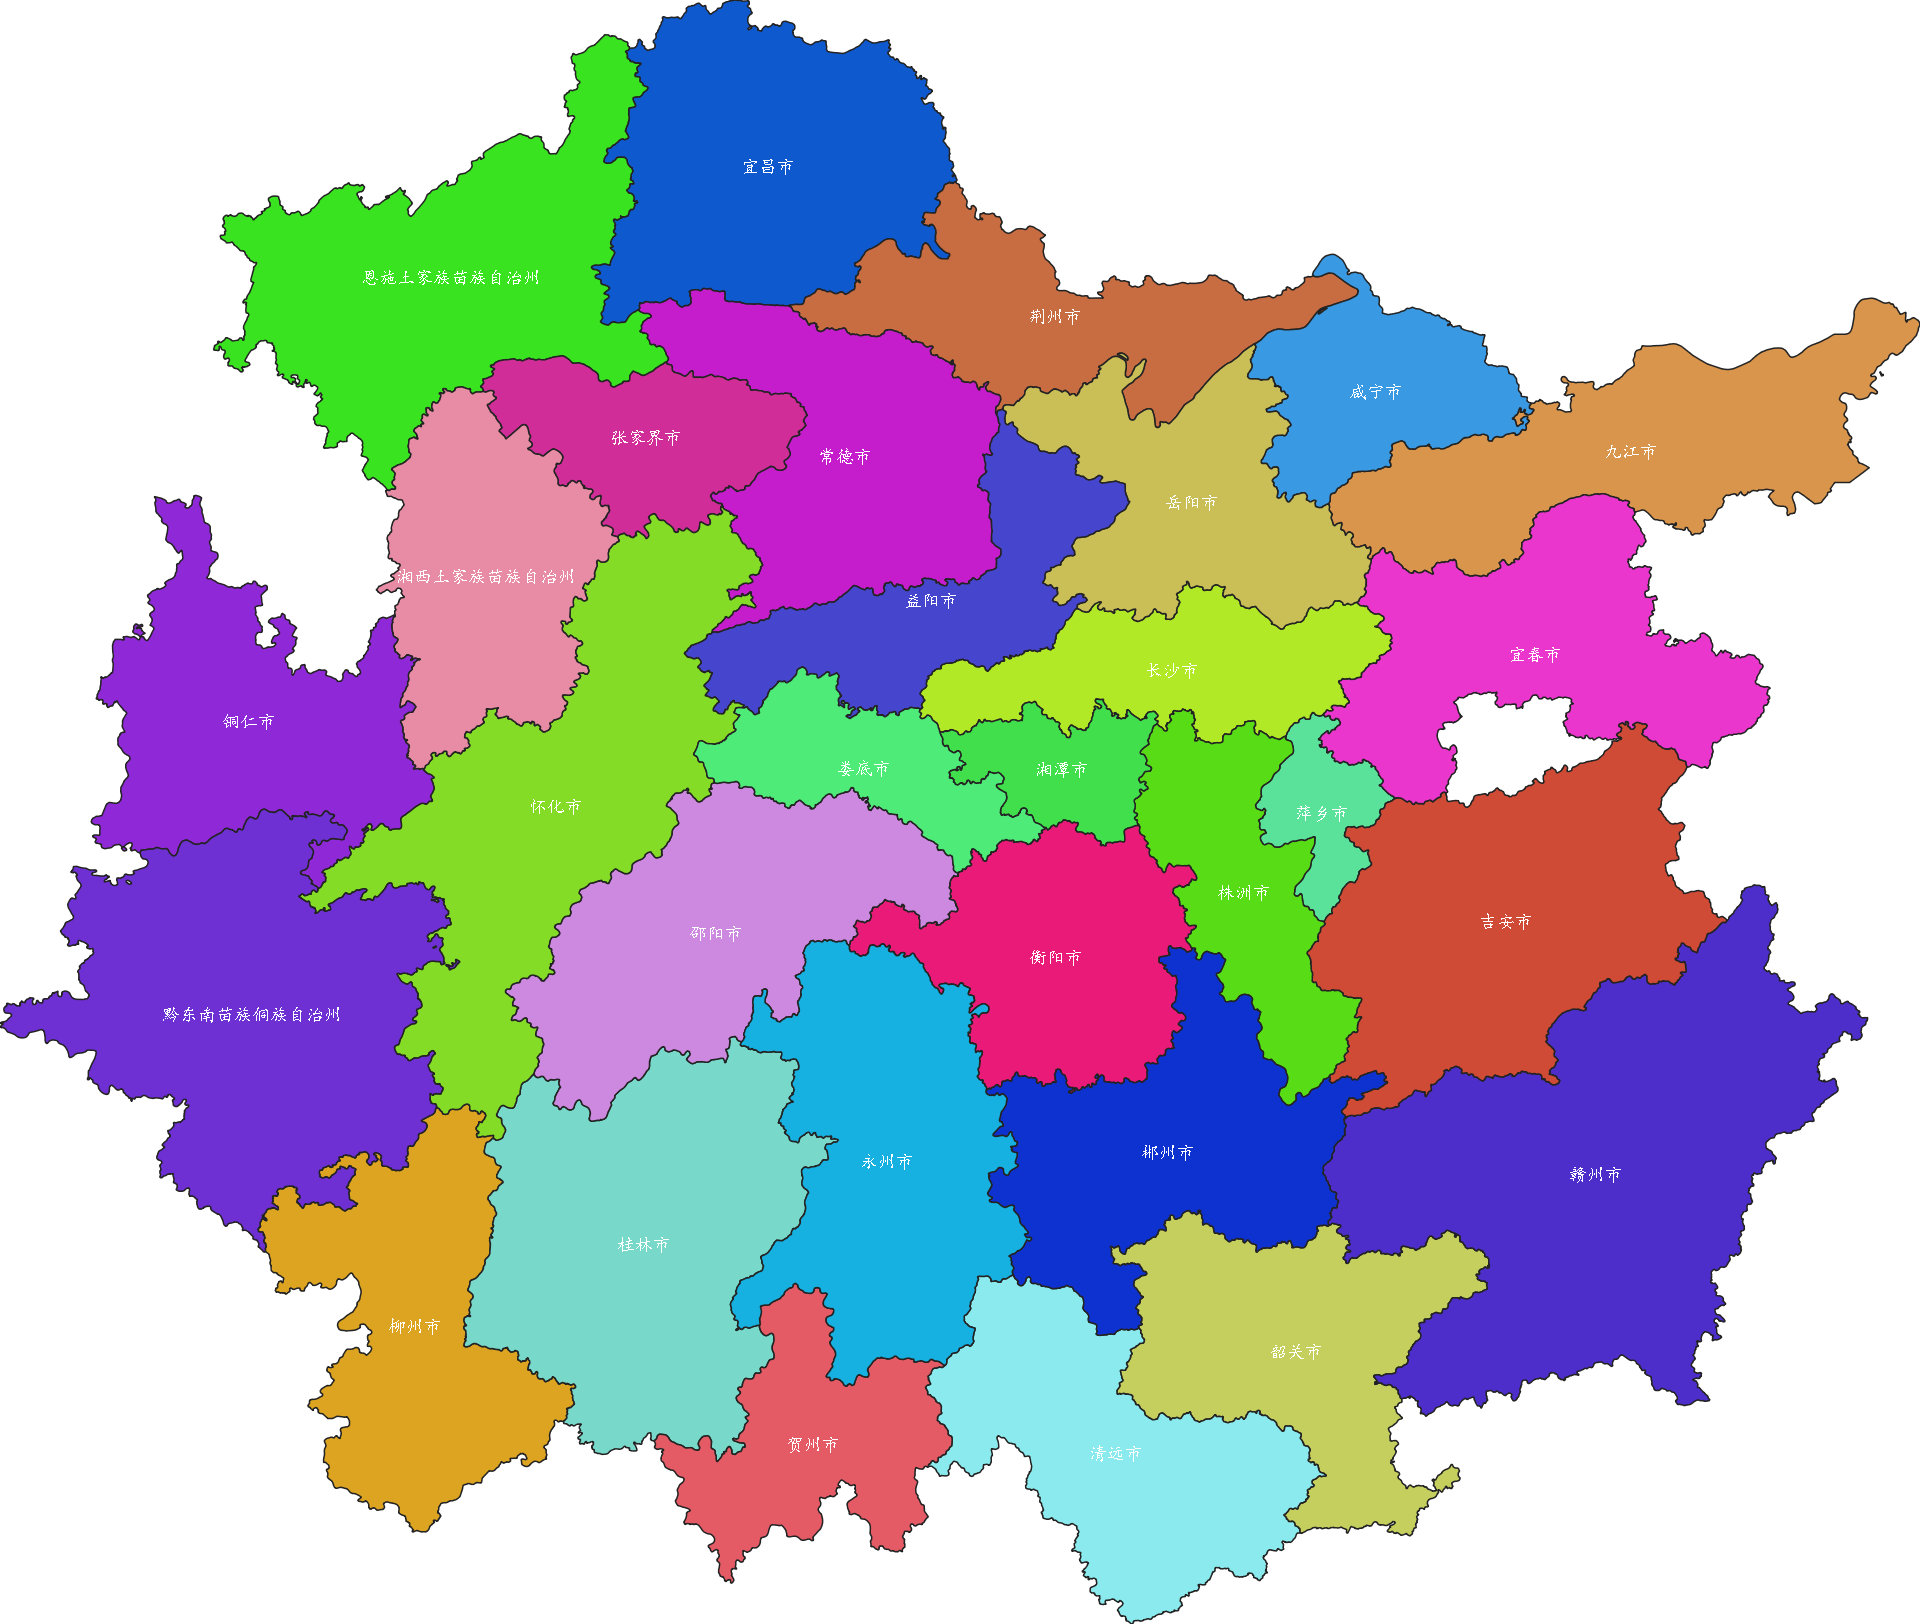
在当今数字化浪潮中,地理信息系统(GIS)的应用场景日益丰富,从城市规划到环境监测,从交通运输到资源管理,GIS 技术为各领域提供了强大的空间数据分析与可视化支持。而专题图作为 GIS 表达的重要形式,其生成质量直接影响着信息传达的准确性和直观性。以下图为例,要求绘制与湖南省相邻的其它市级行政区划的专题图:

资源下载

更多资源
Mario

Mario

马里奥是站在游戏界顶峰的超人气多面角色。马里奥靠吃蘑菇成长,特征是大鼻子、头戴帽子、身穿背带裤,还留着胡子。与他的双胞胎兄弟路易基一起,长年担任任天堂的招牌角色。

腾讯云软件源

腾讯云软件源

为解决软件依赖安装时官方源访问速度慢的问题,腾讯云为一些软件搭建了缓存服务。您可以通过使用腾讯云软件源站来提升依赖包的安装速度。为了方便用户自由搭建服务架构,目前腾讯云软件源站支持公网访问和内网访问。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

WebStorm

WebStorm

WebStorm 是jetbrains公司旗下一款JavaScript 开发工具。目前已经被广大中国JS开发者誉为“Web前端开发神器”、“最强大的HTML5编辑器”、“最智能的JavaScript IDE”等。与IntelliJ IDEA同源,继承了IntelliJ IDEA强大的JS部分的功能。

用户登录
用户注册