首页 文章 精选 留言 我的

精选列表

搜索[安全机制],共10000篇文章
优秀的个人博客,低调大师

马斯克称 Twitter 数据被极端抓取,紧急上线“限流”机制

当地时间7月1日,数以万计的用户抱怨Twitter没有发布他们的新推文,用户会收到“超出限制”的错误提示。 在一条推文中,马斯克详细介绍了修改后的使用配额。经过验证的账户每天最多可以浏览6000条推文,而未经验证的账户则最多浏览600条推文。新注册的未经验证的账户面临着更严格限制,每天最多发300条推文。 随后,马斯克又发布一条推文称,已验证的账户浏览推文数量的限制将增加到8000条,未验证的账户将增加到800条,新注册的未验证用户将增加到400条。 马斯克表示,Twitter正在努力应对“极端程度的数据抓取”和“系统操纵”。他说,这些新的限制是遏制这些紧迫问题的重要措施。他没有透露谁在抓取Twitter的数据,也没有说明这个问题持续了多长时间和详细解释系统如何被操纵。 马斯克此前曾对Twitter上的数据抓取表示担忧,并暗示他可能会对不良行为者采取行动。 另外,有人分析这次事件其实是因为Twitter和谷歌云的合同在6月30号到期了。 传言称,马斯克一直在努力将所有内容迁出,以避免支付10亿美元(据报道)的费用。合同到期后,谷歌云可能对Twitter的数据进行了速率限制。而马斯克此番限制用户访问数量,也是试图减轻损失或协商降低使用费用,并通过这种限制保持网站运行正常,直到数据迁移完成,或达成与Google Cloud的账单合同。 简单总结: - Twitter 和 Google Cloud 的合约六月底到期 - 马斯克想迁移,所以没续费 - 但迁移工作没完成…… - 七月 Google Cloud 对Twitter的数据进行了速率限制 - 其它网站嵌入的 tweet 无法显示,于是反复访问进一步堵塞 - 马斯克出台各种限流措施,并且可能觉得这是个卖会员的好机会…… 最后再转一个说法: 昨天晚上(美中时间),Twitter更新了一个版本的网页版前端,导致一个component不断反复刷新,只要你用浏览器点开一条推文,就会每秒钟给Twitter server带来近100次的request压力,整个div肉眼可见地在抖。 然后Twitter压力巨大,Elon Musk官宣自家被爬虫们DDoS攻击了, 为了对抗爬虫,全面限制访问数。 然后昨天晚上大家发现Twitter不能打开了,所有的request都被limit了。 今天早晨,这个前端的bug偷偷被修好了,那个div已经不抖了,但是全球Twitter用户来骂Elon Musk。 然后Elon Musk又在找借口,"你们应该放下手机"、"这些已经够用了",开始在推特上胡言乱语,为这个决策买单负责。 Elon Musk被手下人逐级上报,真的认为是DDoS攻击,坚决咬死不松口,后来在舆论的压力下,提升了一点点request limit。 再后来,因为整个问题在今天早晨被偷偷全部解决了,所以Twitter官方也把这个limit偷偷彻底放开了。 但是Elon Musk不懂,非程序员不懂,非前端不懂——如果你是前端,昨天晚上那一阵子没上Twitter,没把那个版本的烂前端cache到你浏览器里,你也不会懂。 为什么我懂呢?因为我昨天晚上刚好刷到Twitter,发现了这个问题,肉眼可见地看到了它的thread在抖,在刷新,看了chrome的console,发现这事儿挺可怕。 但是Twitter内部大概率不会这么上报给Elon Musk,前端惹祸,后端背锅,逐级上报,稀里糊涂做了最高决策,然后恶心了全球用户。 然后前端偷偷更新擦屁股,全球人民骂Elon Musk,推特也偷偷放开限制,这件事就算过去了。 嗯,以上就是从昨天到今天,整个Twitter乌龙事件的来龙去脉。 来源1、来源2

优秀的个人博客,低调大师

【SpringCloud技术专题】「Hystrix」(9)熔断器的原理和实现机制

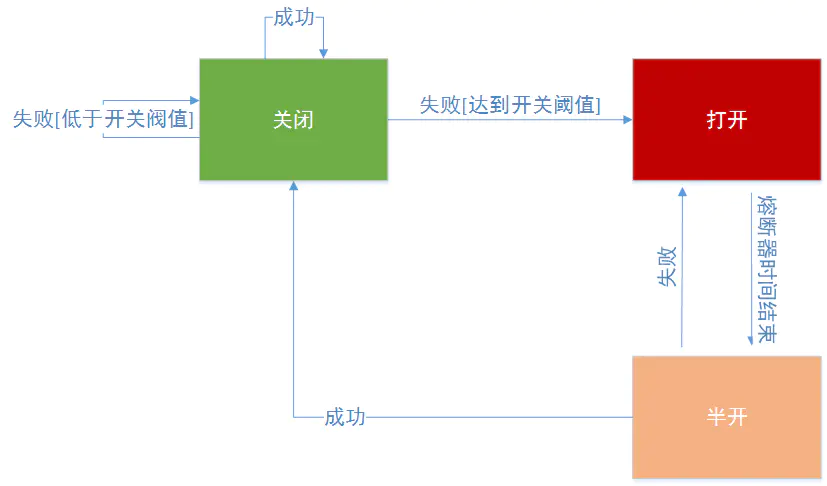
熔断器(Circuit Breaker)介绍 熔断器,现实生活中有一个很好的类比,就是家庭电路中都会安装一个保险盒,当电流过大的时候保险盒里面的保险丝会自动断掉,来保护家里的各种电器及电路。 Hystrix中的熔断器(Circuit Breaker)也是起到这样的作用,Hystrix在运行过程中会向每个commandKey对应的熔断器报告成功、失败、超时和拒绝的状态,熔断器维护计算统计的数据,根据这些统计的信息来确定熔断器是否打开。 如果打开,后续的请求都会被截断。然后会隔一段时间默认是5s,尝试半开,放入一部分流量请求进来,相当于对依赖服务进行一次健康检查,如果恢复,熔断器关闭,随后完全恢复调用。 如下图: 说明,上面说的commandKey,就是在初始化的时候设置的andCommandKey(HystrixCommandKey.Factory.asKey("testCommandKey")) 再来看下熔断器在整个Hystrix流程图中的位置,从步骤4开始,如下图: Hystrix会检查Circuit Breaker的状态。如果Circuit Breaker的状态为开启状态,Hystrix将不会执行对应指令,而是直接进入失败处理状态(图中8 Fallback)。 如果Circuit Breaker的状态为关闭状态,Hystrix会继续进行线程池、任务队列、信号量的检查(图中5) 如何使用熔断器(Circuit Breaker) 由于Hystrix是一个容错框架,因此我们在使用的时候,要达到熔断的目的只需配置一些参数就可以了。但我们要达到真正的效果,就必须要了解这些参数。Circuit Breaker一共包括如下6个参数。 circuitBreaker.enabled:是否启用熔断器,默认是TRUE。 circuitBreaker.forceOpen:熔断器强制打开,始终保持打开状态。默认值FLASE。 circuitBreaker.forceClosed:熔断器强制关闭,始终保持关闭状态。默认值FLASE。 circuitBreaker.errorThresholdPercentage:设定错误百分比,默认值50%,例如一段时间(10s)内有100个请求,其中有55个超时或者异常返回了,那么这段时间内的错误百分比是55%,大于了默认值50%,这种情况下触发熔断器-打开。 circuitBreaker.requestVolumeThreshold:默认值20。意思是至少有20个请求才进行errorThresholdPercentage错误百分比计算。比如一段时间(10s)内有19个请求全部失败了。错误百分比是100%,但熔断器不会打开,因为requestVolumeThreshold的值是20. 这个参数非常重要,熔断器是否打开首先要满足这个条件,源代码如下 // check if we are past the statisticalWindowVolumeThreshold if (health.getTotalRequests() < properties.circuitBreakerRequestVolumeThreshold().get()) { // we are not past the minimum volume threshold for the statisticalWindow so we'll return false immediately and not calculate anything return false; } if (health.getErrorPercentage() < properties.circuitBreakerErrorThresholdPercentage().get()) { return false; } circuitBreaker.sleepWindowInMilliseconds 半开试探休眠时间,默认值5000ms。当熔断器开启一段时间之后比如5000ms,会尝试放过去一部分流量进行试探,确定依赖服务是否恢复。 package myHystrix.threadpool; import com.netflix.hystrix.*; import org.junit.Test; import java.util.Random; /** * Created by wangxindong on 2017/8/15. */ public class GetOrderCircuitBreakerCommand extends HystrixCommand<String> { public GetOrderCircuitBreakerCommand(String name){ super(Setter.withGroupKey(HystrixCommandGroupKey.Factory.asKey("ThreadPoolTestGroup")) .andCommandKey(HystrixCommandKey.Factory.asKey("testCommandKey")) .andThreadPoolKey(HystrixThreadPoolKey.Factory.asKey(name)) .andCommandPropertiesDefaults( HystrixCommandProperties.Setter() .withCircuitBreakerEnabled(true)//默认是true,本例中为了展现该参数 .withCircuitBreakerForceOpen(false)//默认是false,本例中为了展现该参数 .withCircuitBreakerForceClosed(false)//默认是false,本例中为了展现该参数 .withCircuitBreakerErrorThresholdPercentage(5)//(1)错误百分比超过5% .withCircuitBreakerRequestVolumeThreshold(10)//(2)10s以内调用次数10次,同时满足(1)(2)熔断器打开 .withCircuitBreakerSleepWindowInMilliseconds(5000)//隔5s之后,熔断器会尝试半开(关闭),重新放进来请求 // .withExecutionTimeoutInMilliseconds(1000) ) .andThreadPoolPropertiesDefaults( HystrixThreadPoolProperties.Setter() .withMaxQueueSize(10) //配置队列大小 .withCoreSize(2) // 配置线程池里的线程数 ) ); } @Override protected String run() throws Exception { Random rand = new Random(); //模拟错误百分比(方式比较粗鲁但可以证明问题) if(1==rand.nextInt(2)){ // System.out.println("make exception"); throw new Exception("make exception"); } return "running: "; } @Override protected String getFallback() { // System.out.println("FAILBACK"); return "fallback: "; } public static class UnitTest{ @Test public void testCircuitBreaker() throws Exception{ for(int i=0;i<25;i++){ Thread.sleep(500); HystrixCommand<String> command = new GetOrderCircuitBreakerCommand("testCircuitBreaker"); String result = command.execute(); //本例子中从第11次,熔断器开始打开 System.out.println("call times:"+(i+1)+" result:"+result +" isCircuitBreakerOpen: "+command.isCircuitBreakerOpen()); //本例子中5s以后,熔断器尝试关闭,放开新的请求进来 } } } } 测试结果: call times:1 result:fallback: isCircuitBreakerOpen: false call times:2 result:running: isCircuitBreakerOpen: false call times:3 result:running: isCircuitBreakerOpen: false call times:4 result:fallback: isCircuitBreakerOpen: false call times:5 result:running: isCircuitBreakerOpen: false call times:6 result:fallback: isCircuitBreakerOpen: false call times:7 result:fallback: isCircuitBreakerOpen: false call times:8 result:fallback: isCircuitBreakerOpen: false call times:9 result:fallback: isCircuitBreakerOpen: false call times:10 result:fallback: isCircuitBreakerOpen: false 熔断器打开 call times:11 result:fallback: isCircuitBreakerOpen: true call times:12 result:fallback: isCircuitBreakerOpen: true call times:13 result:fallback: isCircuitBreakerOpen: true call times:14 result:fallback: isCircuitBreakerOpen: true call times:15 result:fallback: isCircuitBreakerOpen: true call times:16 result:fallback: isCircuitBreakerOpen: true call times:17 result:fallback: isCircuitBreakerOpen: true call times:18 result:fallback: isCircuitBreakerOpen: true call times:19 result:fallback: isCircuitBreakerOpen: true call times:20 result:fallback: isCircuitBreakerOpen: true 5s后熔断器关闭 call times:21 result:running: isCircuitBreakerOpen: false call times:22 result:running: isCircuitBreakerOpen: false call times:23 result:fallback: isCircuitBreakerOpen: false call times:24 result:running: isCircuitBreakerOpen: false call times:25 result:running: isCircuitBreakerOpen: false 熔断器(Circuit Breaker)源代码HystrixCircuitBreaker.java分析 Factory 是一个工厂类,提供HystrixCircuitBreaker实例 public static class Factory { //用一个ConcurrentHashMap来保存HystrixCircuitBreaker对象 private static ConcurrentHashMap<String, HystrixCircuitBreaker> circuitBreakersByCommand = new ConcurrentHashMap<String, HystrixCircuitBreaker>(); //Hystrix首先会检查ConcurrentHashMap中有没有对应的缓存的断路器,如果有的话直接返回。如果没有的话就会新创建一个HystrixCircuitBreaker实例,将其添加到缓存中并且返回 public static HystrixCircuitBreaker getInstance(HystrixCommandKey key, HystrixCommandGroupKey group, HystrixCommandProperties properties, HystrixCommandMetrics metrics) { HystrixCircuitBreaker previouslyCached = circuitBreakersByCommand.get(key.name()); if (previouslyCached != null) { return previouslyCached; } HystrixCircuitBreaker cbForCommand = circuitBreakersByCommand.putIfAbsent(key.name(), new HystrixCircuitBreakerImpl(key, group, properties, metrics)); if (cbForCommand == null) { return circuitBreakersByCommand.get(key.name()); } else { return cbForCommand; } } public static HystrixCircuitBreaker getInstance(HystrixCommandKey key) { return circuitBreakersByCommand.get(key.name()); } static void reset() { circuitBreakersByCommand.clear(); } } // HystrixCircuitBreakerImpl是HystrixCircuitBreaker的实现,allowRequest()、isOpen()、markSuccess()都会在HystrixCircuitBreakerImpl有默认的实现。 static class HystrixCircuitBreakerImpl implements HystrixCircuitBreaker { private final HystrixCommandProperties properties; private final HystrixCommandMetrics metrics; /* 变量circuitOpen来代表断路器的状态,默认是关闭 */ private AtomicBoolean circuitOpen = new AtomicBoolean(false); /* 变量circuitOpenedOrLastTestedTime记录着断路恢复计时器的初始时间,用于Open状态向Close状态的转换 */ private AtomicLong circuitOpenedOrLastTestedTime = new AtomicLong(); protected HystrixCircuitBreakerImpl(HystrixCommandKey key, HystrixCommandGroupKey commandGroup, HystrixCommandProperties properties, HystrixCommandMetrics metrics) { this.properties = properties; this.metrics = metrics; } /*用于关闭熔断器并重置统计数据*/ public void markSuccess() { if (circuitOpen.get()) { if (circuitOpen.compareAndSet(true, false)) { //win the thread race to reset metrics //Unsubscribe from the current stream to reset the health counts stream. This only affects the health counts view, //and all other metric consumers are unaffected by the reset metrics.resetStream(); } } } @Override public boolean allowRequest() { //是否设置强制开启 if (properties.circuitBreakerForceOpen().get()) { return false; } if (properties.circuitBreakerForceClosed().get()) {//是否设置强制关闭 isOpen(); // properties have asked us to ignore errors so we will ignore the results of isOpen and just allow all traffic through return true; } return !isOpen() || allowSingleTest(); } public boolean allowSingleTest() { long timeCircuitOpenedOrWasLastTested = circuitOpenedOrLastTestedTime.get(); //获取熔断恢复计时器记录的初始时间circuitOpenedOrLastTestedTime,然后判断以下两个条件是否同时满足: // 1) 熔断器的状态为开启状态(circuitOpen.get() == true) // 2) 当前时间与计时器初始时间之差大于计时器阈值circuitBreakerSleepWindowInMilliseconds(默认为 5 秒) //如果同时满足的话,表示可以从Open状态向Close状态转换。Hystrix会通过CAS操作将circuitOpenedOrLastTestedTime设为当前时间,并返回true。如果不同时满足,返回false,代表熔断器关闭或者计时器时间未到。 if (circuitOpen.get() && System.currentTimeMillis() > timeCircuitOpenedOrWasLastTested + properties.circuitBreakerSleepWindowInMilliseconds().get()) { // We push the 'circuitOpenedTime' ahead by 'sleepWindow' since we have allowed one request to try. // If it succeeds the circuit will be closed, otherwise another singleTest will be allowed at the end of the 'sleepWindow'. if (circuitOpenedOrLastTestedTime.compareAndSet(timeCircuitOpenedOrWasLastTested, System.currentTimeMillis())) { // if this returns true that means we set the time so we'll return true to allow the singleTest // if it returned false it means another thread raced us and allowed the singleTest before we did return true; } } return false; } @Override public boolean isOpen() { if (circuitOpen.get()) {//获取断路器的状态 // if we're open we immediately return true and don't bother attempting to 'close' ourself as that is left to allowSingleTest and a subsequent successful test to close return true; } // Metrics数据中获取HealthCounts对象 HealthCounts health = metrics.getHealthCounts(); // 检查对应的请求总数(totalCount)是否小于属性中的请求容量阈值circuitBreakerRequestVolumeThreshold,默认20,如果是的话表示熔断器可以保持关闭状态,返回false if (health.getTotalRequests() < properties.circuitBreakerRequestVolumeThreshold().get()) { return false; } //不满足请求总数条件,就再检查错误比率(errorPercentage)是否小于属性中的错误百分比阈值(circuitBreakerErrorThresholdPercentage,默认 50),如果是的话表示断路器可以保持关闭状态,返回 false if (health.getErrorPercentage() < properties.circuitBreakerErrorThresholdPercentage().get()) { return false; } else { // 如果超过阈值,Hystrix会判定服务的某些地方出现了问题,因此通过CAS操作将断路器设为开启状态,并记录此时的系统时间作为定时器初始时间,最后返回 true if (circuitOpen.compareAndSet(false, true)) { circuitOpenedOrLastTestedTime.set(System.currentTimeMillis()); return true; } else { return true; } } } } 总结 每个熔断器默认维护10个bucket,每秒一个bucket,每个blucket记录成功,失败,超时,拒绝的状态,默认错误超过50%且10秒内超过20个请求进行中断拦截。下图显示HystrixCommand或HystrixObservableCommand如何与HystrixCircuitBreaker及其逻辑和决策流程进行交互,包括计数器在断路器中的行为。
优秀的个人博客,低调大师

Netty面试常驻题:你知道Netty的零拷贝机制吗?

理解零拷贝 零拷贝是Netty的重要特性之一,而究竟什么是零拷贝呢?WIKI中对其有如下定义: "Zero-copy" describes computer operations in which the CPU does not perform the task of copying data from one memory area to another. 从WIKI的定义中,我们看到“零拷贝”是指计算机操作的过程中,CPU不需要为数据在内存之间的拷贝消耗资源。而它通常是指计算机在网络上发送文件时,不需要将文件内容拷贝到用户空间(User Space)而直接在内核空间(Kernel Space)中传输到网络的方式。 Non-Zero Copy方式: Zero Copy方式: 从上图中可以清楚的看到,Zero Copy的模式中,避免了数据在用户空间和内存空间之间的拷贝,从而提高了系统的整体性能。Linux中的sendfile()以及Java NIO中的FileChannel.transferTo()方法都实现了零拷贝的功能,而在Netty中也通过在FileRegion中包装了NIO的FileChannel.transferTo()方法实现了零拷贝。 而在Netty中还有另一种形式的零拷贝,即Netty允许我们将多段数据合并为一整段虚拟数据供用户使用,而过程中不需要对数据进行拷贝操作,这也是我们今天要讲的重点。我们都知道在stream-based transport(如TCP/IP)的传输过程中,数据包有可能会被重新封装在不同的数据包中,例如当你发送如下数据时: 有可能实际收到的数据如下: 因此在实际应用中,很有可能一条完整的消息被分割为多个数据包进行网络传输,而单个的数据包对你而言是没有意义的,只有当这些数据包组成一条完整的消息时你才能做出正确的处理,而Netty可以通过零拷贝的方式将这些数据包组合成一条完整的消息供你来使用。而此时,零拷贝的作用范围仅在用户空间中。 以Netty 3.8.0.Final的源代码来进行说明 ###ChannelBuffer接口 Netty为需要传输的数据制定了统一的ChannelBuffer接口。该接口的主要设计思路如下: 1.使用getByte(int index)方法来实现随机访问 2.使用双指针的方式实现顺序访问 每个Buffer都有一个读指针(readIndex)和写指针(writeIndex) 在读取数据时读指针后移,在写入数据时写指针后移 定义了统一的接口之后,就是来做各种实现了。Netty主要实现了HeapChannelBuffer,ByteBufferBackedChannelBuffer等等,下面我们就来讲讲与Zero Copy直接相关的CompositeChannelBuffer类。###CompositeChannelBuffer类 CompositeChannelBuffer类的作用是将多个ChannelBuffer组成一个虚拟的ChannelBuffer来进行操作。 为什么说是虚拟的呢,因为CompositeChannelBuffer并没有将多个ChannelBuffer真正的组合起来,而只是保存了他们的引用,这样就避免了数据的拷贝,实现了Zero Copy。下面我们来看看具体的代码实现,首先是成员变量 private int readerIndex; private int writerIndex; private ChannelBuffer[] components; private int[] indices; private int lastAccessedComponentId; 以上这里列出了几个比较重要的成员变量。其中readerIndex既读指针和writerIndex既写指针是从AbstractChannelBuffer继承而来的;然后components是一个ChannelBuffer的数组,他保存了组成这个虚拟Buffer的所有子Buffer,indices是一个int类型的数组,它保存的是各个Buffer的索引值;最后的lastAccessedComponentId是一个int值,它记录了最后一次访问时的子Buffer ID。 从这个数据结构,我们不难发现所谓的CompositeChannelBuffer实际上就是将一系列的Buffer通过数组保存起来,然后实现了ChannelBuffer 的接口,使得在上层看来,操作这些Buffer就像是操作一个单独的Buffer一样。 创建 接下来,我们再看一下CompositeChannelBuffer.setComponents方法,它会在初始化CompositeChannelBuffer时被调用。 /** * Setup this ChannelBuffer from the list */ private void setComponents(List<ChannelBuffer> newComponents) { assert !newComponents.isEmpty(); // Clear the cache. lastAccessedComponentId = 0; // Build the component array. components = new ChannelBuffer[newComponents.size()]; for (int i = 0; i < components.length; i ++) { ChannelBuffer c = newComponents.get(i); if (c.order() != order()) { throw new IllegalArgumentException( "All buffers must have the same endianness."); } assert c.readerIndex() == 0; assert c.writerIndex() == c.capacity(); components[i] = c; } // Build the component lookup table. indices = new int[components.length + 1]; indices[0] = 0; for (int i = 1; i <= components.length; i ++) { indices[i] = indices[i - 1] + components[i - 1].capacity(); } // Reset the indexes. setIndex(0, capacity()); } 通过代码可以看到该方法的功能就是将一个ChannelBuffer的List给组合起来。它首先将List中得元素放入到components数组中,然后创建indices用于数据的查找,最后使用setIndex来重置指针。这里需要注意的是setIndex(0, capacity())会将读指针设置为0,写指针设置为当前Buffer的长度,这也就是前面需要做assert c.readerIndex() == 0和assert c.writerIndex() == c.capacity()这两个判断的原因,否则很容易会造成数据重复读写的问题。 所以Netty推荐我们使用ChannelBuffers.wrappedBuffer方法来进行Buffer的合并,因为在该方法中Netty会通过slice()方法来确保构建CompositeChannelBuffer是传入的所有子Buffer都是符合要求的。 数据访问 CompositeChannelBuffer.getByte(int index)的实现如下: public byte getByte(int index) { int componentId = componentId(index); return components[componentId].getByte(index - indices[componentId]); } 从代码我们可以看到,在随机查找时会首先通过index获取这个字节所在的componentId既字节所在的子Buffer序列,然后通过index - indices[componentId]计算出它在这个子Buffer中的第几个字节,然后返回结果。 下面再来看一下componentId(int index) 的实现: private int componentId(int index) { int lastComponentId = lastAccessedComponentId; if (index >= indices[lastComponentId]) { if (index < indices[lastComponentId + 1]) { return lastComponentId; } // Search right for (int i = lastComponentId + 1; i < components.length; i ++) { if (index < indices[i + 1]) { lastAccessedComponentId = i; return i; } } } else { // Search left for (int i = lastComponentId - 1; i >= 0; i --) { if (index >= indices[i]) { lastAccessedComponentId = i; return i; } } } throw new IndexOutOfBoundsException("Invalid index: " + index + ", maximum: " + indices.length); } 从代码中我们发现,Netty以lastComponentId既上次访问的子Buffer序号为中心,向左右两边进行搜索,这样做的目的是,当我们两次随机查找的字符序列相近时(大部分情况下都是这样),可以最快的搜索到目标索引的componentId。 写在最后 欢迎大家关注我的公众号【风平浪静如码】,海量Java相关文章,学习资料都会在里面更新,整理的资料也会放在里面。 觉得写的还不错的就点个赞,加个关注呗!点关注,不迷路,持续更新!!!

优秀的个人博客,低调大师

【Java复习Ⅲ 11】spring框架:对spring的宏观理解(注入/反射机制)

2021年04月08日 spring宏观介绍 有很多的时候我们学习的只是知识的表层,我们要努力把“了解”变为“精通”。这个系列就是为了记录Java基础梳理。 希望在学习的过程中不是把知识简单的记忆住,更重要的是做到“有趣”,怎么做到呢?将代码理解为构建世界的语言,我们所在的世界的一草一木都可以用代码解释,Java是面向对象的,也是存在于我们的生活的,Java生活就是这个道理。 在以后可能会加一些拓展, 学习理科、技术最依靠的是理解、模型,不断应用,在应用中理解,记忆,才能对知识的理解更上一层。 Spring的组成 spring 2002年发布的,我们可以说“spring配置文件(xml)是spring的灵魂” spring组件 function core 核心(bean的管理) AOP Aspect Oriented Programming 动态代理(总代理销售商对下面的人一视同仁) ORM Object Relation Mapping (对象关系映射) DAO Data access Object(数据连接对象) Context 上下文,前后文(代表当前编程的环境) Web WebMVC 独立的框架(springMVC) Spring框架的几大模块之间相互耦合度很小,因此Spring框架的使用可以根据实际需要选其部分模块循序渐进的使用,而非必须统统照搬。 Spring的原理: spring框架主要依赖IOC和AOP,完成控制反转和注射,这是spring的主要作用! 【IOC】控制反转 Inversion of Control 正向:A类需要使用B类,new一个B类(Instance) 反向:A类需要只用B类,由spring注入一个B给A 【AOP】可以做很多事务的管理。(类似动态代理、面向的是各个类) 【DIC】通过DIC主要的作用是对象的使用直接向spring要,而不用我们自己创建。 Spring核心思想 控制反转Ioc//Inversion of Control和依赖注射DI/Dependency Injection 【控制反转】 什么叫控制反转呢? 套用好莱坞的一句名言就是:Don’t call me.I will call you. 。什么意思呢?就好比一个皇帝和太监 有一天皇帝想幸某个美女,于是跟太监说,今夜我要宠幸美女,皇帝往往不会告诉太监,今晚几点会回宫,会回哪张龙床,他只会告诉太监他要哪位美女。其它一切都交,由太监去安排,到了晚上皇帝回宫时,自然会有美女出现在皇帝的龙床上。这就是控制反转,而把美女送,到皇帝的寝宫里面去就是注射。太监就是是框架里面的注射控制器类BeanFactory,负责找到美女并送到龙 床上去。整个后宫可以看成是Spring框架,美女就是Spring控制下的JavaBean。 【传统的模式】 就是一个饥渴男去找小姐出台,找领班,帮助给介绍一个云云,于是领班就开始给他张罗。介绍一个合适的给他,完事后,再把小姐还给领班,下次再来。这个过程中,领班就是查询上下文Context,领班的一个职能就是给客户找到他们所要的小姐。这就是lookup()方法,领班手中的小姐名录就 是JNDI//Java Naming and Directory Interface。小姐就是EJB,饥渴男是客户端,青楼是EJB容器。 【区别】 饥渴男去找小姐出台很麻烦,不仅得找,用完后还得把小姐给还回去。而皇帝爽翻了,什么都不用管,交给太监去处理,控制权转移到太监手中去了,而不是皇帝,必要时候由太监给注射进去就可以了。看到Spring的美妙了吧,Spring还提供了与多个主流框架的支持,可以和其它开源框架集成。 配置文件 DTD XSD : Xml Schema Definition(2001年发布,写配置文件xsi里面会有) xmlns ns=namespace xsi == xml schema instance xsi:schemaLocation == 对应的实例的位置(XX 对应 XX.xsd) applicationContext.xml (一般都是这个名字作为spring的配置文件) <beans xmlns="http://www.springframework.org/schema/beans" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xmlns:context="http://www.springframework.org/schema/context" xsi:schemaLocation=" http://www.springframework.org/schema/beans http://www.springframework.org/schema/beans/spring-beans-4.1.xsd http://www.springframework.org/schema/context http://www.springframework.org/schema/context/spring-context-4.2.xsd"> <beanid="queenLiModel"class="com.hzyc.demo.model.Model"/> <beanid="queenLiDao"class="com.hzyc.demo.model.dao.Dao"/> <beanid="emperor"class="com.hzyc.demo.model.service.Service"> <constructor-argname="model"ref="queenLiModel"/> <propertyname="dao"ref="queenLiDao"/> bean>beans> 在spring中管理依赖关系 测试类: publicclassService{ //声明我要用的东西 privateDaodao; privateModelmodel; Service(Modelmodel){ this.model=model; } publicvoidserviceRun(){ model.setName("小明"); model.setCode("121"); System.out.println(model); dao.daoRun(); System.out.println("service结束……"); } //普通的getset方法: publicDaogetDao(){、publicvoidsetDao(Daodao){ publicModelgetModel(){、publicvoidsetModel(Modelmodel){}classtest{ publicstaticvoidmain(String[]args){ try{ //写完这个文件之后就已经完成注入的过程了 ApplicationContextatx=newClassPathXmlApplicationContext("applicationContext.xml"); Serviceemperor=(Service)atx.getBean("emperor"); emperor.serviceRun(); ModelqueenModel=(Model)atx.getBean("queenLiModel"); queenModel.setCode("我是queenLiModel"); System.out.println(queenModel.getCode()); }catch(Exceptione){ e.printStackTrace(); } }} 学习笔记

优秀的个人博客,低调大师

使用Chrome开发者工具研究JavaScript的垃圾回收机制

I use the following simple JavaScript code to illustrate: var JerryTestArray = []; (function(){ for( var i = 0; i < 100; i++){ JerryTestArray[i] = document.createElement("div"); } })(); Create a new empty tab in your Chrome, and first create a snapshot with empty heap status by click “Take Snapshot” button: The Snapshot1 is generated. Now switch to tab Console, paste the JavaScript code and execute it in console. And switch to Profiles tab again to make the second snapshot: Once done, select the second snapshot, choose “Comparison” and “Snapshot1” as filter: We can find out from column “New” that 100 div nodes are created as we expect. Since these nodes are not appended to document node so they are invisible to end user, so displayed as “Detached DOM”. The JerryTestArray still holds the reference to each div node so Garbage collector will not touch these nodes. In order to make Garbage collector recycle the memory occupied by these nodes, just assign another value to JerryTestArray in console: Once done, make the third snapshot and compare it with the second. Now we can find that the re-assignment to JerryTestArray will trigger the destruction of those 100 div nodes by Garbage collector: Meanwhile, the string we use in assignment could also be inspected via the combination of filters below: There is another kind of profile in Chrome development tool which can give you an overview about timeline of memory allocation: Click Start button in above screenshot, and paste the following code in console and executed: var JerryTestArray = []; (function(){ for( var i = 0; i < 98; i++){ JerryTestArray[i] = document.createElement("span"); JerryTestArray[i].className = "JerryClassName" + i; } })(); After the code is executed, paste the following code and execute: JerryTestArray[30] = "this is a long test............................end"; Now stop the profile. The profile is displayed as below. The highlighted vertical blue line indicates the timeslot when the 97 Span elements are created. Note that the number of Span elements displayed here is not 98 but 97 since Chrome development tool displays the final status of objects after “stop profile” button is clicked ( the reference to 30th Span element is replaced by String, so it is recycled by GC ). You can drag the two vertical bars to define the time range between which you would like to inspect. For example the time range below contains the timeslot when the below assignment occurs: JerryTestArray[30] = "this is a long test............................end"; With this gained knowledge now we can check the memory allocation and destruction in some real application. For example click tile “My Tasks” to enter this application, make the first snapshot and click back button within application to return to launchpad, and make the second snapshot and review the comparison result. From the result we find out lots of stuff are deleted after we return to launchpad: Hover your mouse to a given destructed object and you can review its detail: For more tips How I use Chrome development tool in my daily work, please refer to this blog Chrome Development Tool tips used in my daily work 本文来自云栖社区合作伙伴“汪子熙”,了解相关信息可以关注微信公众号"汪子熙"。

资源下载

更多资源
Nacos

Nacos

Nacos /nɑ:kəʊs/ 是 Dynamic Naming and Configuration Service 的首字母简称,一个易于构建 AI Agent 应用的动态服务发现、配置管理和AI智能体管理平台。Nacos 致力于帮助您发现、配置和管理微服务及AI智能体应用。Nacos 提供了一组简单易用的特性集,帮助您快速实现动态服务发现、服务配置、服务元数据、流量管理。Nacos 帮助您更敏捷和容易地构建、交付和管理微服务平台。

Spring

Spring

Spring框架(Spring Framework)是由Rod Johnson于2002年提出的开源Java企业级应用框架,旨在通过使用JavaBean替代传统EJB实现方式降低企业级编程开发的复杂性。该框架基于简单性、可测试性和松耦合性设计理念,提供核心容器、应用上下文、数据访问集成等模块,支持整合Hibernate、Struts等第三方框架,其适用范围不仅限于服务器端开发,绝大多数Java应用均可从中受益。

Sublime Text

Sublime Text

Sublime Text具有漂亮的用户界面和强大的功能,例如代码缩略图,Python的插件,代码段等。还可自定义键绑定,菜单和工具栏。Sublime Text 的主要功能包括:拼写检查,书签,完整的 Python API , Goto 功能,即时项目切换,多选择,多窗口等等。Sublime Text 是一个跨平台的编辑器,同时支持Windows、Linux、Mac OS X等操作系统。

WebStorm

WebStorm

WebStorm 是jetbrains公司旗下一款JavaScript 开发工具。目前已经被广大中国JS开发者誉为“Web前端开发神器”、“最强大的HTML5编辑器”、“最智能的JavaScript IDE”等。与IntelliJ IDEA同源,继承了IntelliJ IDEA强大的JS部分的功能。

用户登录
用户注册