首页 文章 精选 留言 我的

精选列表

搜索[开发工具包],共10011篇文章
优秀的个人博客,低调大师

分布式系统开发工具包 —— 基于Hessian的HTTP RPC调用技术

Hessian官网:http://hessian.caucho.com/ hessian是二进制web service协议。 Hessian介绍 创建Hessian服务包括四个步骤: 创建Java接口,用于提供公开服务 使用HessianProxyFactory创建客户端 创建服务实现类 在servlet引擎中配置服务 HelloWorld服务 public interface BasicAPI { public String hello(); } 服务实现 public class BasicService extends HessianServlet implements BasicAPI { private String _greeting = "Hello, world"; public void setGreeting(String greeting) { _greeting = greeting; } public String hello() { return _greeting; } } 客户端实现 String url = "http://hessian.caucho.com/test/test"; HessianProxyFactory factory = new HessianProxyFactory(); BasicAPI basic = (BasicAPI) factory.create(BasicAPI.class, url); System.out.println("hello(): " + basic.hello()); 部署标准web.xml <web-app> <servlet> <servlet-name>hello</servlet-name> <servlet-class>com.caucho.hessian.server.HessianServlet</servlet-class> <init-param> <param-name>home-class</param-name> <param-value>example.BasicService</param-value> </init-param> <init-param> <param-name>home-api</param-name> <param-value>example.Basic</param-value> </init-param> </servlet> <servlet-mapping> <url-pattern>/hello</url-pattern> <servlet-name>hello</servlet-name> </servlet-mapping> </web-app> Hessian序列化 Hessian类可以用来做序列化与反序列化 序列化 Object obj = ...; OutputStream os = new FileOutputStream("test.xml"); Hessian2Output out = new Hessian2Output(os); out.writeObject(obj); os.close(); 反序列化 InputStream is = new FileInputStream("test.xml"); Hessian2Input in = new Hessian2Input(is); Object obj = in.readObject(null); is.close(); 如果要序列化比基础类型或String类型更加复杂的java对象,务必确保对象实现了java.io.Serializable接口。 Hessian处理大量数据 分布式应用需要发送大量二进制数据时,使用InputStream会更加有效率,因为它避免了分配大量byte数组。方法参数中只有最后一个参数可能是InputStream,因为数据是在调用过程中读的。 下面是一个上传文件的API的例子 package example; public interface Upload { public void upload(String filename, InputStream data); } 如果返回结果是InputStream,客户端必须在finally块中调用InputStream.close()方法,因为Hessian不会关闭底层HTTP流,直到所有数据被读取并且input stream被关闭。 文件下载API: package example; public interface Download { public InputStream download(String filename, InputStream data); } 文件下载实现: InputStream is = fileProxy.download("test.xml"); try { ... // read data here } finally { is.close(); } 原文发布于:http://www.yesdata.net/2018/03/11/hessian/

优秀的个人博客,低调大师

分布式系统开发工具包 —— 基于Kryo的Java对象序列化

Kryo是用于Java语言的一个快速和高效的对象图序列化框架。Kryo项目的目的是快速、高效、方便地使用API。当需要持久化对象的时候,不论是持久化到文件、数据库还是网络,都可以使用Kryo。 目前Kryo已经到了4.0.1版本以上了。本文的介绍适用于V2.0+以上版本。 安装Kryo 一般适用maven来Kryo包。 使用官方版的Kryo的话可以引用下述配置代码 <dependency> <groupId>com.esotericsoftware</groupId> <artifactId>kryo</artifactId> <version>4.0.1</version> </dependency> 如果你已经在你的classpath下有了不同版本的asm了的话,上述依赖可能会碰到问题。这时你可以使用kyro-shaded jar包,它自身包含了它所需版本的asm,并且是位于在不同包里的。 <dependency> <groupId>com.esotericsoftware</groupId> <artifactId>kryo-shaded</artifactId> <version>4.0.1</version> </dependency> 如果你想试用最新的特性 <repository> <id>sonatype-snapshots</id> <name>sonatype snapshots repo</name> <url>https://oss.sonatype.org/content/repositories/snapshots</url> </repository> <dependency> <groupId>com.esotericsoftware</groupId> <artifactId>kryo</artifactId> <version>4.0.1-SNAPSHOT</version> </dependency> 开始使用Kryo库 import com.esotericsoftware.kryo.Kryo; import com.esotericsoftware.kryo.io.Output; import com.esotericsoftware.kryo.io.Input; // ... Kryo kryo = new Kryo(); // ... Output output = new Output(new FileOutputStream("file.bin")); SomeClass someObject = ... kryo.writeObject(output, someObject); output.close(); // ... Input input = new Input(new FileInputStream("file.bin")); SomeClass someObject = kryo.readObject(input, SomeClass.class); input.close(); Kryo类编排序列化,Output和Input类处理缓存字节和刷新到流中。 参考连接: Kryo官网 用于网络的Kryo Kryo为什么比Hessian快 原文发布于:http://www.yesdata.net/2018/03/17/kyro/

优秀的个人博客,低调大师

feilong-core 1.14.3 发布啦,让 Java 开发更简便的工具包

本次升级共有3处变更, 具体参见1.14.3 milestone 1.14.3 文档地址:http://feilong-core.mydoc.io/ 单元测试数 增加至2164个, 单元测试覆盖率 增加至91%,javadoc 比率83% [Feature]🆕 #788sort util 封装数组或者集合 固定的排序方法 com.feilong.core.util.SortUtil 新增sortListByFixedOrderArray(List<T>, T...)和sortListByFixedOrderList(List<T>, List<T>)方法 对 集合 list 按照指定的固定顺序fixedOrderItemList进行排序. 说明: 默认使用的是UnknownObjectBehavior.AFTER,不在指定固定顺序的元素将排在后面 示例: assertThat( sortListByFixedOrderList(toList("张飞", "关羽", "刘备"), toList("刘备", "张飞", "关羽")), // contains("刘备", "张飞", "关羽")); 重构: 对于以下代码: try{ Collections.sort( list, new FixedOrderComparator<>( StoPropertyConstants.PRPT_ITEM_HYPELAUNCH, StoPropertyConstants.PRPT_ITEM_MIADIDAS_VALUE_EN, StoPropertyConstants.PRPT_ITEM_PRESONALLZATION_CODE, StoPropertyConstants.PRPT_ITEM_PERSALES_CODE, StoPropertyConstants.PRPT_ITEM_VIP_CODE, StoPropertyConstants.PRPT_ITEM_COMINGSOON_CODE, StoPropertyConstants.PRPT_ITEM_DISCOUNT_CODE, StoPropertyConstants.PRPT_ITEM_NORMAL_CODE, StoPropertyConstants.PRPT_ITEM_NOSALE)); }catch (Exception e){ LOGGER.error("itemType sort error:{},itemType:{}", e, JsonUtil.format(itemType)); } 可以重构成: com.feilong.core.util.SortUtil.sortListByFixedOrderList( list, toList( StoPropertyConstants.PRPT_ITEM_HYPELAUNCH, StoPropertyConstants.PRPT_ITEM_MIADIDAS_VALUE_EN, StoPropertyConstants.PRPT_ITEM_PRESONALLZATION_CODE, StoPropertyConstants.PRPT_ITEM_PERSALES_CODE, StoPropertyConstants.PRPT_ITEM_VIP_CODE, StoPropertyConstants.PRPT_ITEM_COMINGSOON_CODE, StoPropertyConstants.PRPT_ITEM_DISCOUNT_CODE, StoPropertyConstants.PRPT_ITEM_NORMAL_CODE, StoPropertyConstants.PRPT_ITEM_NOSALE)); #789新建ComparatorUtil #791新建ContainsStringPredicate 使用场景,参考 <bean class="com.feilong.context.converter.IfStringToBeanConverter"> <property name="predicate"> <bean class="com.feilong.core.util.predicate.ContainsStringPredicate" p:searchCharSequence="TRADE_NOT_EXIST" /> </property> <property name="trueStringToBeanConverter"> <bean class="com.feilong.netpay.alipay.query.AlipayTradeNotExistStringToBeanConverter" /> </property> <property name="falseStringToBeanConverter"> <bean class="com.feilong.context.converter.XMLMapBuilderStringToBeanConverter"> <property name="beanClass" value="com.feilong.netpay.alipay.query.AlipaySingleQueryResultCommand" /> <property name="nameAndValueMapBuilder"> <bean class="com.feilong.context.converter.builder.XmlNodeNameAndValueMapBuilder" p:xpathExpression="/alipay/response/trade/*" /> </property> <property name="beanBuilder"> <bean class="com.feilong.context.converter.builder.AliasBeanBuilder" /> </property> </bean> </property> </bean> [Update] none [版本升级] none [Remove] none [Fix Bug]🐛 none [Javadoc] none [Junit Test] none

优秀的个人博客,低调大师

AI工具包

更多深度文章,请关注云计算频道:https://yq.aliyun.com/cloud 现在的人工智能可以为企业带来许多好处,并且将简单的认知能力赋予给了机器。作为计算机科学领域,人工智能正在以前所未有的速度发展。今天我将向你介绍AI的两大工具,它们正在推动着人工智能的发展。 机器学习,深度学习: 当前AI的基础技术可分为两类:机器学习和深度学习。当然,如果按照比较严谨的分类,深度学习也属于机器学习的一部分。今天,我们不细讲这些,目前人工智能使用的绝大多数技术是机器学习,它包含数据科学家最常用的算法:线性模型,k均值聚类,决策树等。虽然我们现在将它们作为AI的一部分,但它们是数据科学家长期以来都在做的事情。这里也说明了数据是人工智能最重要的一部分。 过去两年,两种AI受到了更多的关注和炒作:一种机器学习技术的细分化,神经网络,也被称为深度

优秀的个人博客,低调大师

Android 日志工具包

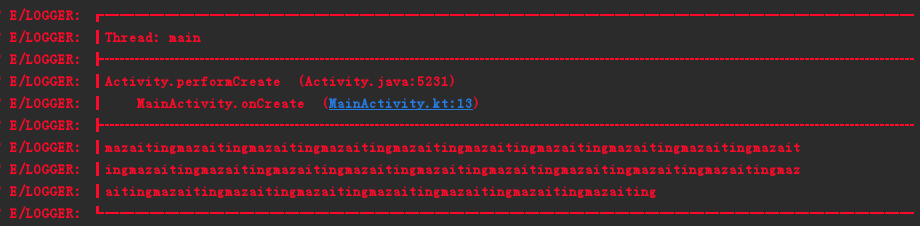
1). 实现效果图 效果图.png 2). 实现思路 绘制边框 打印线程名称 打印堆栈信息 打印消息体 3). 边框绘制 边框实际上也是以字符串的形式打印 4). 打印线程信息 Log.println(priority, mTag, HORIZONTAL_LINE + "Thread: " + Thread.currentThread().getName()); 5). 打印堆栈信息 builder.append(HORIZONTAL_LINE).append("").append(level).append(element.getClassName().substring(element.getClassName().lastIndexOf(".") + 1)) .append(".").append(element.getMethodName()).append(" ").append(" (").append(element.getFileName()) .append(":").append(element.getLineNumber()).append(")"); 6). 打印消息体 // 获取消息总长度 int tLen = msg.length(); // 获取消息长度打印长度的倍数 int multiple = tLen / LENGTH + 1; // 创建临时变量 String tmp; // 遍历倍数 for (int i = 0; i < multiple; i++) { // 获取字符内容 if (i != multiple - 1) { // 获取指定范围的数据 tmp = msg.substring(i * LENGTH, (i + 1) * LENGTH); } else { // 最后一段数据 tmp = msg.substring(i * LENGTH); } // 打印消息 Log.println(priority, mTag, HORIZONTAL_LINE + tmp); } 7). 代码下载 8). Gradle依赖 compile 'com.mazaiting:log:1.0.0'

优秀的个人博客,低调大师

简介Valgrind工具包功能

我就不班门弄斧了。不过呢,有可能有些同学可能不知道Valgrind有哪些功能,那么我就从Valgrind的官方网站处,摘几段文字吧。 Memcheck Memcheck detects memory-management problems, and is aimed primarily at C and C++ programs. When a program is run under Memcheck's supervision, all reads and writes of memory are checked, and calls to malloc/new/free/delete are intercepted. As a result, Memcheck can detect if your program: Accesses memory it shouldn't (areas not yet allocated, areas that have been freed, areas past the end of heap blocks, inaccessible areas of the stack). Uses uninitialised values in dangerous ways. Leaks memory. Does bad frees of heap blocks (double frees, mismatched frees). Passes overlapping source and destination memory blocks to memcpy() and related functions. Memcheck reports these errors as soon as they occur, giving the source line number at which it occurred, and also a stack trace of the functions called to reach that line. Memcheck tracks addressability at the byte-level, and initialisation of values at the bit-level. As a result, it can detect the use of single uninitialised bits, and does not report spurious errors on bitfield operations. Memcheck runs programs about 10--30x slower than normal. Cachegrind Cachegrind is a cache profiler. It performs detailed simulation of the I1, D1 and L2 caches in your CPU and so can accurately pinpoint the sources of cache misses in your code. It identifies the number of cache misses, memory references and instructions executed for each line of source code, with per-function, per-module and whole-program summaries. It is useful with programs written in any language. Cachegrind runs programs about 20--100x slower than normal. Callgrind Callgrind, by Josef Weidendorfer, is an extension to Cachegrind . It provides all the information that Cachegrind does, plus extra information about callgraphs. It was folded into the main Valgrind distribution in version 3.2.0. Available separately is an amazing visualisation tool, KCachegrind , which gives a much better overview of the data that Callgrind collects; it can also be used to visualise Cachegrind's output. Massif Massif is a heap profiler. It performs detailed heap profiling by taking regular snapshots of a program's heap. It produces a graph showing heap usage over time, including information about which parts of the program are responsible for the most memory allocations. The graph is supplemented by a text or HTML file that includes more information for determining where the most memory is being allocated. Massif runs programs about 20x slower than normal. Helgrind Helgrind is a thread debugger which finds data races in multithreaded programs. It looks for memory locations which are accessed by more than one (POSIX p-)thread, but for which no consistently used (pthread_mutex_) lock can be found. Such locations are indicative of missing synchronisation between threads, and could cause hard-to-find timing-dependent problems. It is useful for any program that uses pthreads. It is a somewhat experimental tool, so your feedback is especially welcome here. DRD DRD is a tool for detecting errors in multithreaded C and C++ programs. The tool works for any program that uses the POSIX threading primitives or that uses threading concepts built on top of the POSIX threading primitives. While Helgrind can detect locking order violations, for most programs DRD needs less memory to perform its analysis. 原文:http://valgrind.org/info/tools.html

资源下载

更多资源
Mario

Mario

马里奥是站在游戏界顶峰的超人气多面角色。马里奥靠吃蘑菇成长,特征是大鼻子、头戴帽子、身穿背带裤,还留着胡子。与他的双胞胎兄弟路易基一起,长年担任任天堂的招牌角色。

Nacos

Nacos

Nacos /nɑ:kəʊs/ 是 Dynamic Naming and Configuration Service 的首字母简称,一个易于构建 AI Agent 应用的动态服务发现、配置管理和AI智能体管理平台。Nacos 致力于帮助您发现、配置和管理微服务及AI智能体应用。Nacos 提供了一组简单易用的特性集,帮助您快速实现动态服务发现、服务配置、服务元数据、流量管理。Nacos 帮助您更敏捷和容易地构建、交付和管理微服务平台。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

Sublime Text

Sublime Text

Sublime Text具有漂亮的用户界面和强大的功能,例如代码缩略图,Python的插件,代码段等。还可自定义键绑定,菜单和工具栏。Sublime Text 的主要功能包括:拼写检查,书签,完整的 Python API , Goto 功能,即时项目切换,多选择,多窗口等等。Sublime Text 是一个跨平台的编辑器,同时支持Windows、Linux、Mac OS X等操作系统。

用户登录
用户注册