首页 文章 精选 留言 我的

精选列表

搜索[双向转换],共10000篇文章
优秀的个人博客,低调大师

python 将字符串转换成字典dict

版权声明:本文为博主原创文章,未经博主允许不得转载。 https://blog.csdn.net/qq_34173549/article/details/81539013 JSON到字典转化: 》》》dictinfo = json.loads(json_str) 输出dict类型 字典到JSON转化: 》》》jsoninfo = json.dumps(dict)输出str类型 比如: info = {'name' : 'jay', 'sex' : 'male', 'age': 22} jsoninfo = simplejson.dumps(info) print jsoninfo Unicode到字典的转化: 》》》 json.loads() 比如: import json str = '{"params":{"id":222,"offset":0},{"nodename":"topic"}' params = json.loads(str) print params['params']['id']

优秀的个人博客,低调大师

Android中关于dip和px以及转换的总结

我们在页面布局的时候,经常会设置容器的长度,但是到底该使用哪个作为长度的单位而懊恼。在Android中支持的描述大小区域的类型有以下几种:px(pixels)——像素:不同的设备显示效果相同,一般我们HVGA代表320x480像素,这个用的比较多。dip(device independent pixels)——设备独立像素:这个和设备硬件有关,一般我们为了支持WCGA、HVGA和QVGA推荐使用这个,不依赖于像素。等同于dp。sp(scaled pixels—best for text size)——主要用于字体显示best for textsize。由此,根据 google 的建议,TextView 的字号最好使用 sp 做单位,而且查看TextView的源码可知 Android 默认使用 sp 作为字号单位。pt(points)——磅:是一个标准的长度单位,1pt=1/72英寸,用于印刷业,非常简单易用; 在 Android 中,1pt 大概等于2.22sp以上供参考,如果 UI 能够以sp为单位提供设计是最好的,如果设计中没有sp的概念,则开发人员也可以通过适当的换算取近似值。in(inches)——英寸mm(millimeters)——毫米 过去,程序员通常以像素为单位设计计算机用户界面。例如,定义一个宽度为300像素的表单字段,列之间的间距为5个像素,图标大小为16×16像素 等。这样处理的问题在于,如果在一个每英寸点数(dpi)更高的新显示器上运行该程序,则用户界面会显得很小。在有些情况下,用户界面可能会小到难以看清内容。到底px和dip有什么区别呢? dip != px 主要是针对不同设备而言的。在Density是160的设备上,比如用AVDManager创建的默认模拟器,dip和px是一样的但是如果同样的代码,换到不同Density的设备上,比如换到一个Density是240的设备上,dip和px体现出来的大小就不一样了。px不管在什么样的设备上都是那样长,但是dip会根据设备变化;WQVGA屏density=120;QVGA屏density=120;HVGA屏density=160;WVGA屏density=240;density值表示每英寸有多少个显示点,与分辨率是两个概念。 当屏幕density=240时使用hdpi标签的资源 当屏幕density=160时使用mdpi标签的资源 当屏幕density=120时使用ldpi标签的资源。 不加任何标签的资源是各种分辨率情况下共用的。为了使用户界面能够在现在和将来的显示器类型上正常显示,建议大家始终使用sp作为文字大小的单位,将dip作为其他元素的单位。当然,也可以考虑使用矢量图形,而不是用位图。。 px和dp换算公式为: pixs =dips * (densityDpi/160). dips=(pixs*160)/densityDpi 如何获得设备的屏幕分辨率和屏幕密度? 例如分辨率为480*800,密度为240的设备,方法如下: 1 2 3 4 DisplayMetrics dm =getResources().getDisplayMetrics(); dm.densityDpi= 240 dm.widthPixels= 480 dm.heightPixels= 800 本文转自欢醉博客园博客,原文链接http://www.cnblogs.com/zhangs1986/p/3207694.html如需转载请自行联系原作者 欢醉

优秀的个人博客,低调大师

Android中 Bitmap和Drawable相互转换的方法

1、Drawable --> Bitmap [java] view plain copy Bitmapdrawable2Bitmap(Drawabledrawable){ if(drawableinstanceofBitmapDrawable){ return((BitmapDrawable)drawable).getBitmap(); }elseif(drawableinstanceofNinePatchDrawable){ Bitmapbitmap=Bitmap .createBitmap( drawable.getIntrinsicWidth(), drawable.getIntrinsicHeight(), drawable.getOpacity()!=PixelFormat.OPAQUE?Bitmap.Config.ARGB_8888 :Bitmap.Config.RGB_565); Canvascanvas=newCanvas(bitmap); drawable.setBounds(0,0,drawable.getIntrinsicWidth(), drawable.getIntrinsicHeight()); drawable.draw(canvas); returnbitmap; }else{ returnnull; } } 2、从资源中获取的Drawable --> Bitmap [java] view plain copy Resourcesres=getResources(); Bitmapbmp=BitmapFactory.decodeResource(res,R.drawable.pic); 3、Bitmap --> Drawable [java] view plain copy Drawablebitmap2Drawable(Bitmapbitmap){ returnnewBitmapDrawable(bitmap); } 4、Bitmap --> byte[] [java] view plain copy byte[]Bitmap2Bytes(Bitmapbm){ ByteArrayOutputStreambaos=newByteArrayOutputStream(); bm.compress(Bitmap.CompressFormat.PNG,100,baos); returnbaos.toByteArray(); } 5、 byte[] --> Bitmap [java] view plain copy BitmapBytes2Bimap(byte[]b){ if(b.length!=0){ returnBitmapFactory.decodeByteArray(b,0,b.length); }else{ returnnull; } } 本文转自 一点点征服 博客园博客,原文链接: http://www.cnblogs.com/ldq2016/p/7058127.html ,如需转载请自行联系原作者

优秀的个人博客,低调大师

spark集成hbase与hive数据转换与代码练习

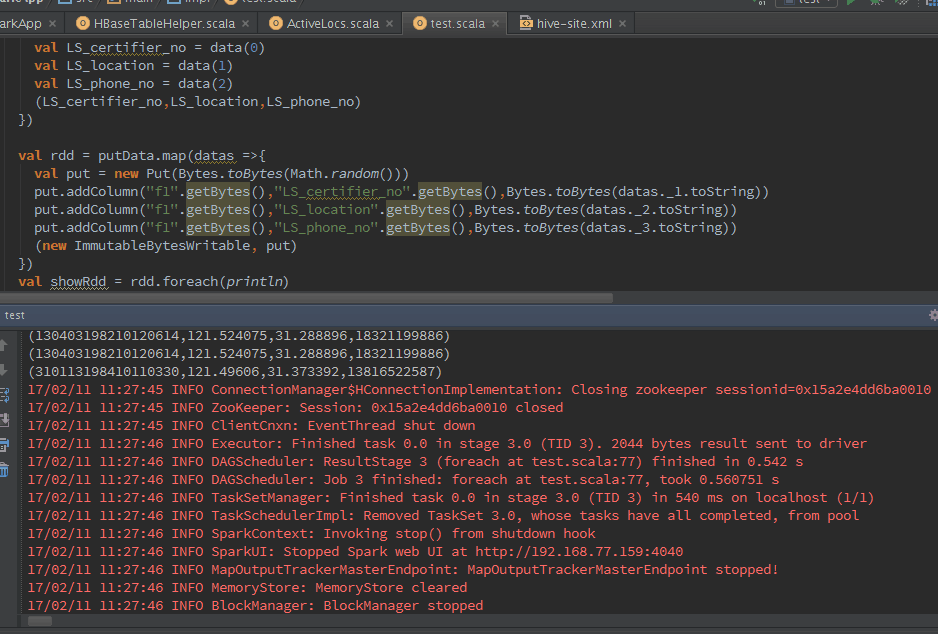
帮一个朋友写个样例,顺便练手啦~一直在做平台的各种事,但是代码后续还要精进啊。。。 1 import java.util.Date 2 3 import org.apache.hadoop.hbase.HBaseConfiguration 4 import org.apache.hadoop.hbase.client.{Put, Scan, Result} 5 import org.apache.hadoop.hbase.io.ImmutableBytesWritable 6 import org.apache.hadoop.hbase.mapred.TableOutputFormat 7 import org.apache.hadoop.hbase.mapreduce.TableInputFormat 8 import org.apache.hadoop.hbase.util.Bytes 9 import org.apache.hadoop.mapred.JobConf 10 import org.apache.log4j.{Level, Logger} 11 import org.apache.spark.rdd.RDD 12 import org.apache.spark.sql.DataFrame 13 import org.apache.spark.sql.hive.HiveContext 14 import org.apache.spark.{SparkContext, SparkConf} 15 16 /** 17 * Created by ysy on 2/10/17. 18 */ 19 object test { 20 21 case class ysyTest(LS_certifier_no: String,loc: String,LS_phone_no: String) 22 23 def main (args: Array[String]) { 24 val sparkConf = new SparkConf().setMaster("local").setAppName("ysy").set("spark.executor.memory", "1g") 25 val sc = new SparkContext(sparkConf) 26 val sqlContext = new HiveContext(sc) 27 sqlContext.sql("drop table pkq") 28 val columns = "LS_certifier_no,LS_location,LS_phone_no" 29 val hbaseRDD = dataInit(sc,"EVENT_LOG_LBS",columns).map(data =>{ 30 val id =Bytes.toString(data._2.getValue("f1".getBytes, "LS_certifier_no".getBytes)) 31 val loc = Bytes.toString(data._2.getValue("f1".getBytes, "LS_location".getBytes)) 32 val phone = Bytes.toString(data._2.getValue("f1".getBytes, "LS_phone_no".getBytes)) 33 (id,loc,phone) 34 }) 35 val showData = hbaseRDD.foreach(println) 36 val datas = hbaseRDD.filter(_._1 != null).filter(_._2 != null).filter(_._3 != null) 37 val hiveDF = initHiveTableFromHbase(sc:SparkContext,sqlContext,datas) 38 writeHiveTableToHbase(sc,hiveDF) 39 40 41 } 42 43 def initHiveTableFromHbase(sc:SparkContext,sqlContext: HiveContext,hiveRDD:RDD[(String,String,String)]) : DataFrame = { 44 val hRDD = hiveRDD.map(p => ysyTest(p._1,p._2,p._3)) 45 val hiveRDDSchema = sqlContext.createDataFrame(hiveRDD) 46 hiveRDDSchema.registerTempTable("pkq") 47 hiveRDDSchema.show(10) 48 hiveRDDSchema 49 } 50 51 def dataInit(sc : SparkContext,tableName : String,columns : String) : RDD[(ImmutableBytesWritable,Result)] = { 52 val configuration = HBaseConfiguration.create() 53 configuration.addResource("hbase-site.xml") 54 configuration.set(TableInputFormat.INPUT_TABLE,tableName ) 55 val scan = new Scan 56 val column = columns.split(",") 57 for(columnName <- column){ 58 scan.addColumn("f1".getBytes(),columnName.getBytes()) 59 } 60 val hbaseRDD = sc.newAPIHadoopRDD(configuration,classOf[TableInputFormat],classOf[org.apache.hadoop.hbase.io.ImmutableBytesWritable],classOf[org.apache.hadoop.hbase.client.Result]) 61 System.out.println(hbaseRDD.count()) 62 hbaseRDD 63 } 64 65 def writeHiveTableToHbase(sc : SparkContext,hiveDF : DataFrame) = { 66 val configuration = HBaseConfiguration.create() 67 configuration.addResource("hbase-site.xml ") 68 configuration.set(TableOutputFormat.OUTPUT_TABLE,"EVENT_LOG_LBS") 69 val jobConf = new JobConf(configuration) 70 jobConf.setOutputFormat(classOf[TableOutputFormat]) 71 72 val putData = hiveDF.map(data =>{ 73 val LS_certifier_no = data(0) 74 val LS_location = data(1) 75 val LS_phone_no = data(2) 76 (LS_certifier_no,LS_location,LS_phone_no) 77 }) 78 79 val rdd = putData.map(datas =>{ 80 val put = new Put(Bytes.toBytes(Math.random())) 81 put.addColumn("f1".getBytes(),"LS_certifier_no".getBytes(),Bytes.toBytes(datas._1.toString)) 82 put.addColumn("f1".getBytes(),"LS_location".getBytes(),Bytes.toBytes(datas._2.toString)) 83 put.addColumn("f1".getBytes(),"LS_phone_no".getBytes(),Bytes.toBytes(datas._3.toString)) 84 (new ImmutableBytesWritable, put) 85 }) 86 val showRdd = rdd.foreach(println) 87 rdd.saveAsHadoopDataset(jobConf) 88 } 89 90 }

资源下载

更多资源
Mario

Mario

马里奥是站在游戏界顶峰的超人气多面角色。马里奥靠吃蘑菇成长,特征是大鼻子、头戴帽子、身穿背带裤,还留着胡子。与他的双胞胎兄弟路易基一起,长年担任任天堂的招牌角色。

腾讯云软件源

腾讯云软件源

为解决软件依赖安装时官方源访问速度慢的问题,腾讯云为一些软件搭建了缓存服务。您可以通过使用腾讯云软件源站来提升依赖包的安装速度。为了方便用户自由搭建服务架构,目前腾讯云软件源站支持公网访问和内网访问。

Spring

Spring

Spring框架(Spring Framework)是由Rod Johnson于2002年提出的开源Java企业级应用框架,旨在通过使用JavaBean替代传统EJB实现方式降低企业级编程开发的复杂性。该框架基于简单性、可测试性和松耦合性设计理念,提供核心容器、应用上下文、数据访问集成等模块,支持整合Hibernate、Struts等第三方框架,其适用范围不仅限于服务器端开发,绝大多数Java应用均可从中受益。

WebStorm

WebStorm

WebStorm 是jetbrains公司旗下一款JavaScript 开发工具。目前已经被广大中国JS开发者誉为“Web前端开发神器”、“最强大的HTML5编辑器”、“最智能的JavaScript IDE”等。与IntelliJ IDEA同源,继承了IntelliJ IDEA强大的JS部分的功能。

用户登录
用户注册