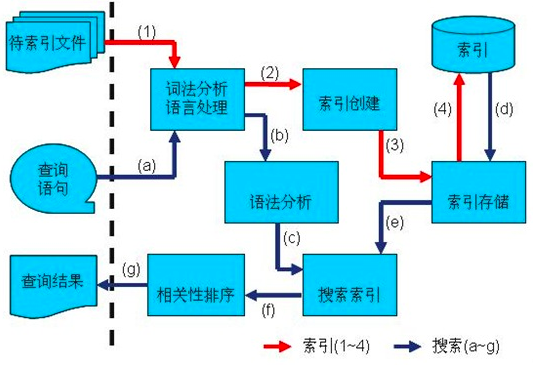
搜索引擎:MapReduce实战----倒排索引
1.倒排索引简介 倒排索引(Inverted index),也常被称为反向索引、置入档案或反向档案,是一种索引方法,被用来存储在全文搜索下某个单词在一个文档或者一组文档中的存储位置的映射。它是文档检索系统中最常用的数据结构。 有两种不同的反向索引形式: 一条记录的水平反向索引(或者反向档案索引)包含每个引用单词的文档的列表。 一个单词的水平反向索引(或者完全反向索引)又包含每个单词在一个文档中的位置。 后者的形式提供了更多的兼容性(比如短语搜索),但是需要更多的时间和空间来创建。 举例: 以英文为例,下面是要被索引的文本: T0= "it is what it is" T1= "what is it" T2= "it is a banana" 我们就能得到下面的反向文件索引: 1 2 3 4 5 "a": {2} "banana": {2} "is": {0, 1, 2} "it": {0, 1, 2} "what": {0, 1} 检索的条件"what","is"和"it"将对应这个集合:{0,1}∩{0,1,2}∩{0,1,2}={0,1}。 对相同的文字,我们得到后面这些完全反向索引,有文档数量和当前查询的单词结果组成的的成对数据。 同样,文档数量和当前查询的单词结果都从零开始。 所以,"banana": {(2, 3)}就是说 “banana”在第三个文档里 (T2),而且在第三个文档的位置是第四个单词(地址为 3)。 1 2 3 4 5 "a": {(2, 2)} "banana": {(2, 3)} "is": {(0, 1), (0, 4), (1, 1), (2, 1)} "it": {(0, 0), (0, 3), (1, 2), (2, 0)} "what": {(0, 2), (1, 0)} 如果我们执行短语搜索"what is it"我们得到这个短语的全部单词各自的结果所在文档为文档0和文档1。但是这个短语检索的连续的条件仅仅在文档1得到。 2.分析和设计 (1)Map过程 首先使用默认的TextInputFormat类对输入文件进行处理,得到文本中每行的偏移量及其内容,Map过程首先必须分析输入的<key, value>对,得到倒排索引中需要的三个信息:单词、文档URI和词频,如图所示: 存在两个问题,第一:<key, value>对只能有两个值,在不使用Hadoop自定义数据类型的情况下,需要根据情况将其中的两个值合并成一个值,作为value或key值; 第二,通过一个Reduce过程无法同时完成词频统计和生成文档列表,所以必须增加一个Combine过程完成词频统计 public static class Map extends Mapper<Object,Text,Text,Text>{ private Text keyInfo = new Text(); private Text valueInfo = new Text(); private FileSplit split; //存储所在文件的路径 public void map(Object key,Text value,Context context) throws IOException, InterruptedException{ split = (FileSplit)context.getInputSplit(); //获取当前任务分割的单词所在的文件路径 StringTokenizer itr = new StringTokenizer(value.toString()); while(itr.hasMoreTokens()){ keyInfo.set(itr.nextToken()+"+"+split.getPath().toString()); //keyvalue是由单词和URI组成的 valueInfo.set("1"); //value值设置成1 context.write(keyInfo,valueInfo); } } } (2)Combine过程 将key值相同的value值累加,得到一个单词在文档中的词频,如图 public static class Combiner extends Reducer<Text,Text,Text,Text>{ private Text info = new Text(); public void reduce(Text key,Iterable<Text>values,Context context) throws IOException, InterruptedException{ int sum = 0; for(Text value:values){ sum += Integer.parseInt(value.toString()); } // int index = key.toString().indexOf("+"); // info.set(key.toString().substring(index+1)+":"+sum); // key.set(key.toString().substring(0,index)); String record = key.toString(); String[] str = record.split("[+]"); info.set(str[1]+":"+sum); key.set(str[0]); context.write(key,info); } } (3)Reduce过程 讲过上述两个过程后,Reduce过程只需将相同key值的value值组合成倒排索引文件所需的格式即可,剩下的事情就可以直接交给MapReduce框架进行处理了 public static class Reduce extends Reducer<Text,Text,Text,Text>{ private Text result = new Text(); public void reduce(Text key,Iterable<Text>values,Context context) throws IOException, InterruptedException{ String value =new String(); for(Text value1:values){ value += value1.toString()+" ; "; } result.set(value); context.write(key,result); } } 完整代码如下: package ReverseIndex; import java.io.*; import java.util.StringTokenizer; import org.apache.hadoop.fs.Path; import org.apache.hadoop.io.*; import org.apache.hadoop.mapreduce.Job; import org.apache.hadoop.mapreduce.Mapper; import org.apache.hadoop.mapreduce.Reducer; import org.apache.hadoop.mapreduce.lib.input.FileInputFormat; import org.apache.hadoop.mapreduce.lib.input.FileSplit; import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat; public class ReverseIndex { public static class Map extends Mapper<Object,Text,Text,Text>{ private Text keyInfo = new Text(); private Text valueInfo = new Text(); private FileSplit split; //存储所在文件的路径 public void map(Object key,Text value,Context context) throws IOException, InterruptedException{ split = (FileSplit)context.getInputSplit(); //获取当前任务分割的单词所在的文件路径 StringTokenizer itr = new StringTokenizer(value.toString()); while(itr.hasMoreTokens()){ keyInfo.set(itr.nextToken()+"+"+split.getPath().toString()); //keyvalue是由单词和URI组成的 valueInfo.set("1"); //value值设置成1 context.write(keyInfo,valueInfo); } } } public static class Combiner extends Reducer<Text,Text,Text,Text>{ private Text info = new Text(); public void reduce(Text key,Iterable<Text>values,Context context) throws IOException, InterruptedException{ int sum = 0; for(Text value:values){ sum += Integer.parseInt(value.toString()); } //下面三行注释和紧接着四行功能一样,只不过实现方法不一样罢了 // int index = key.toString().indexOf("+"); // info.set(key.toString().substring(index+1)+":"+sum); // key.set(key.toString().substring(0,index)); //对传进来的key进行拆分,以+为界 String record = key.toString(); String[] str = record.split("[+]"); info.set(str[1]+":"+sum); key.set(str[0]); context.write(key,info); } } public static class Reduce extends Reducer<Text,Text,Text,Text>{ private Text result = new Text(); public void reduce(Text key,Iterable<Text>values,Context context) throws IOException, InterruptedException{ String value =new String(); for(Text value1:values){ value += value1.toString()+" ; "; } result.set(value); context.write(key,result); } } public static void main(String[] args) throws IOException, ClassNotFoundException, InterruptedException { // TODO Auto-generated method stub Job job = new Job(); job.setJarByClass(ReverseIndex.class); job.setNumReduceTasks(1); //设置reduce的任务数量为1,平常的小测试不需要开辟太多的reduce任务进程 job.setMapperClass(Map.class); job.setMapOutputKeyClass(Text.class); job.setMapOutputValueClass(Text.class); job.setCombinerClass(Combiner.class); job.setReducerClass(Reduce.class); job.setOutputKeyClass(Text.class); job.setOutputValueClass(Text.class); FileInputFormat.addInputPath(job, new Path("/thinkgamer/input")); FileOutputFormat.setOutputPath(job, new Path("/thinkgamer/output")); System.exit(job.waitForCompletion(true) ? 0 : 1); } }