首页 文章 精选 留言 我的

精选列表

搜索[小程序·即时通信 IM],共10028篇文章
优秀的个人博客,低调大师

MongoDB学习笔记(三)--权限 && 导出导入备份恢复 && fsync和锁

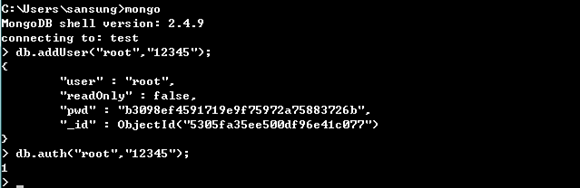
权限 绑定内网IP访问MongoDB服务 在启动的时候带上 –bind_ip 192.168.1.1 参数,可以使指定IP访问。 mongod --bind_ip 192.168.1.1 连接时必须指定IP,否则会失败。 mongo 192.168.1.1 用户 MongoDB中默认有一个空的admin数据库,在admin.system.users中保存的用户比其他数据库中设置的权限更大。在admin.system.users中没有添加任何用户的情况下,鸡屎在MongoDB启动时启用了 –auth 参数,客户端不进行任何认证依然可以连接到数据库,并且可以对数据库进行任何操作。 建立系统root用户 使用addUser()函数添加一个root用户。 建立指定权限的用户 使用addUser()函数为test库添加了一个只读权限的用户,设置只读只需要在addUser()函数中传入第3个参数值为true。 执行指定文件中的内容 text.js的内容是 var count = db.yyd.count(); printjson('count if yyd is : ' + count); 查看活动进程 db.currentOp(); 结束进程 db,killOp(opid号) serverStatus 获取运行中的MongoDB服务器统计信息。 db.runCommand({"serverStatus":1}); mongostat 便捷的查看serverStatus的结果。 导出 导入 备份 恢复 fsync和锁 fsync命令会强制服务器将所有缓冲区写入磁盘。还可以选择上锁阻止对数据库的进一步写入,直到释放锁为止。 db,runCommand({"fsync":1,"lock":1}); 上锁之后便可以不用停掉服务器,也不用牺牲备份的实施特性,只是会导致写入操作暂时被阻塞。 本文转自我爱物联网博客园博客,原文链接:http://www.cnblogs.com/yydcdut/p/3558446.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

Dock的生态开源技术(Etcd&Machine&Compose&Swarm&Mesos&Kubernetes)

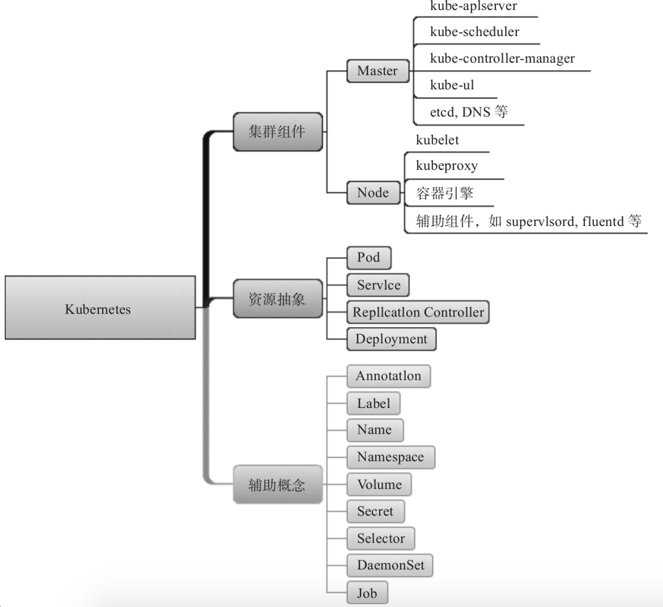
Etcd CoreOS公司开源的高可用分布式键值数据库Etcd,该项目已经被广泛应用到分布式系统的一致性实现和服务发现中,基于Go语言实现。 Etcd就是专门为集群环境设计,可以很好地实现数据一致性,提供集群节点状态管理和服务自动发现等(类似ZooKeeper)。 Etcd在进行设计的时候重点考虑了下面四个要素: 简单:支持REST风格的HTTP+JSON API; 安全:支持HTTPS方式的访问; 快速:支持并发每秒一千次的写操作; 可靠:支持分布式结构,基于Raft 通常情况下,用户使用Etcd可以在多个节点上启动多个实例,并将它们添加为一个集群。同一个集群中的Etcd实例将会自动保持彼此信息的一致性,这意味着分布在各个节点上的应用也将获取到一致的信息。 [1]Apache ZooKeeper是一套知名的分布式系统中进行同步和一致性管理的工具。 [2]doozer是一个一致性分布式数据库实现,主要面向少量数据,更多信息可以参考https://github.com/ha/doozerd。 [3]Raft是一套通过选举主节点来实现分布式系统一致性的算法,相比于大名鼎鼎的Paxos算法,它的算法过程相对容易理解,由Stanford大学的Diego Ongaro和John Ousterhout提出。更多细节可以参考https://raftconsensus.github.io。 主要操作: 数据操作,监听数据操作,目录操作,日志操作,用户操作,角色操作,认证操作,节点操作,集群操作。 Docker Machine Docker Machine是Docker官方三剑客项目之一,负责使用Docker的第一步,在多种平台上快速安装Docker环境。它支持多种平台,让用户可以在很短时间内搭建一套Docker主机集群。当要对多个Docker主机进行配置和管理时,采用Docker Machine将十分方便快捷。不仅提高了操作速度,更通过批量统一的管理减少了出错的可能。这是在大规模集群和云平台环境中所推荐的。配合Compose和Swarm,可以实现完整的Docker环境生命周期管理。 Machine项目是Docker官方的开源项目,负责实现对Docker主机本身进行管理,其代码在https://github.com/docker/machine上开源。 Machine项目主要由Go编写,用户可以在本地任意指定被Machine管理的Docker主机,并对其进行操作。Machine定位是“在本地或者云环境中创建Docker主机”。 其基本功能包括: 在指定节点上安装Docker引擎,配置其为Docker主机; 集中管理所有Docker主机。 Machine连接不同类型的节点是通过不同驱动指定的,目前已经支持了包括IBM、Amazon、Google等多家数据中心的云主机。 Docker Compose Compose项目是Docker官方的开源项目,基于Python语言实现,负责实现对Docker容器集群的快速编排。从功能上看,跟OpenStack中的Heat十分类似。其代码目前在https://github.com/docker/compose上开源。 编排(Orchestration)功能是复杂系统实现灵活可操作性的关键。特别是在Docker应用场景中,编排意味着用户可以灵活地对各种容器资源实现定义和管理。 作为Docker官方编排工具,Compose的重要性不言而喻,它可以让用户通过编写一个简单的模板文件,快速地创建和管理基于Docker容器的应用集群。 Compose定位是“定义和运行多个Docker容器的应用”,其前身是开源项目Fig,目前仍然兼容Fig格式的模板文件。我们知道使用一个Dockerfile模板文件,可以让用户很方便地定义一个单独的应用容器。然而,在日常工作中,经常会碰到需要多个容器相互配合来完成某项任务的情况。例如要实现一个Web项目,除了Web服务容器本身,往往还需要再加上后端的数据库服务容器,甚至还包括负载均衡容器等。Compose恰好满足了这样的需求。它允许用户通过一个单独的docker-compose.yml模板文件(YAML格式)来定义一组相关联的应用容器为一个项目(project)。 Compose中有两个重要的概念: 服务(service):一个应用的容器,实际上可以包括若干运行相同镜像的容器实例。 项目(project):由一组关联的应用容器组成的一个完整业务单元,在docker-compose.yml文件中定义。 Compose的默认管理对象是项目,通过子命令对项目中的一组容器进行便捷地生命周期管理。 Compose项目由Python编写,实现上调用了Docker服务提供的API来对容器进行管理。因此,只要所操作的平台支持Docker API,就可以在其上利用Compose来进行编排管理。 Docker Swarm Docker Swarm是Docker公司推出的官方容器集群平台,基于Go语言实现。 Docker Swarm是Docker官方的三剑客项目之一,提供Docker容器集群服务,是Docker官方对容器云生态进行支持的核心方案。使用它,用户可以将多个Docker主机封装为单个大型的虚拟Docker主机,快速打造一套容器云平台。 通过使用Swarm,用户可以将若干Docker主机节点组成的集群当作一个大的虚拟Docker主机使用。并且,原先基于单机的Docker应用可以无缝地迁移到Swarm上来。实现这些功能的前提是服务自动发现能力。在现代分布式系统中,服务的自动发现、注册、更新等能力将成为系统的基本保障和重要基础。在生产环境中,Swarm的管理节点和发现服务后端要采用高可用性的保护,可以采用集群模式。 作为容器集群管理器,Swarm最大的优势之一就是100%支持标准的Docker API。各种基于标准API的工具,如Compose、docker-py,各种管理软件,甚至Docker本身等都可以很容易地与Swarm进行集成。这大大方便了用户将原先基于单节点的系统移植到Swarm上。同时Swarm内置了对Docker网络插件的支持,用户可以很容易地部署跨主机的容器集群服务。 Swarm是典型的master-slave结构,通过发现服务来选举manager。manager是中心管理节点,各个node上运行agent接受manager的统一管理。在V2中,集群会自动通过Raft协议分布式选举出manager节点,无需额外的发现服务支持,避免了单点瓶颈。同时,V2中内置了基于DNS的负载均衡和对外部负载均衡机制的集成支持。 Mesos——优秀的集群资源调度平台 Mesos项目是源自UC Berkeley对集群资源进行抽象和管理的开源项目,类似于操作系统内核,用户可以使用它很容易地实现分布式应用的自动化调度。同时,Mesos自身也很好地结合了Docker等相关容器技术,基于Mesos已有的大量应用框架,可以实现用户应用的快速上线。 Mesos可以将整个数据中心的资源(包括CPU、内存、存储、网络等)进行抽象和调度,使得多个应用同时运行在集群中分享资源,并无需关心资源的物理分布情况。如果把数据中心中的集群资源看做一台服务器,那么Mesos要做的事情,其实就是今天操作系统内核的职责:“抽象资源+调度任务”。 Mesos项目主要由C++语言编写,项目官方地址为http://mesos.apache.org,代码仍在快速演化中。 Mesos拥有许多引人注目的特性,包括: 支持数万个节点的大规模场景(Apple、Twitter、eBay等公司的实践)。 支持多种应用框架,包括Marathon、Singularity、Aurora等。 支持HA(基于ZooKeeper实现)。 支持Docker、LXC等容器机制进行任务隔离。 提供了多个流行语言的API,包括Python、Java、C++等。 自带了简洁易用的WebUI,方便用户直接进行操作。 值得注意的是,Mesos自身只是一个资源抽象的平台,要使用它往往需要结合运行其上的分布式应用(在Mesos中被称作框架,framework),比如Hadoop、Spark、Marathon、Elasticsearch等大部分时候,用户只需要跟这些框架打交道即可,完全无需关心底下的资源调度情况,因为Mesos已经自动帮你实现了。这大大方便了上层应用的开发和运维。当然,用户也可以基于Mesos打造自己的分布式应用框架。 Mesos中有三个基本的组件:管理服务(master)、任务服务(slave)以及应用框架(framework)。 跟大部分分布式系统中类似,主节点(master)起到管理作用,将看到全局的信息,负责不同应用框架之间的资源调度和逻辑控制。应用框架需要注册到管理服务上才能被使用。用户和应用需要通过主节点提供的API来获取集群状态和操作集群资源。 slave负责汇报本从节点上的资源状态(空闲资源、运行状态等等)给主节点,并负责隔离本地资源来执行主节点分配的具体任务。隔离机制目前包括各种容器机制,包括LXC、Docker等。 应用框架(framework)是实际干活的,包括两个主要组件: 调度器(scheduler):注册到主节点,等待分配资源; 执行器(executor):在从节点上执行框架指定的任务(框架也可以使用Mesos自带的执行器,包括shell脚本执行器和Docker执行器)。 应用框架可以分两种:一种是对资源的需求,是会扩展的(如Hadoop、Spark等),申请后还可能调整;另一种是对资源需求大小是固定的(如MPI等),一次申请即可。 Kubernetes——生产级容器集群平台 Kubernetes是Google团队发起并维护的开源容器集群管理系统,支持如Docker等容器技术。类似Docker Swarm,使用Kubernetes,用户可以轻松搭建和管理一个私有容器云。该项目基于Go语言实现,试图为基于容器的应用部署和管理打造一套强大并且易用的管理平台。 Kubernetes拥有鲜明的技术优势: 优秀的API设计,以及简洁高效的架构设计,主要组件个数很少,彼此之间通过接口调用; 基于微服务模式的多层资源抽象模型,兼顾灵活性与可操作性,提出的Pod模型被许多平台借鉴; 可拓展性好,模块化容易替换,伸缩能力极佳,1.2.0版本单集群支持1000个节点,同时运行30000个Pods; 自动化程度高,真正实现“所得即所需”,用户通过模板声明服务后,生命周期都是自动化管理; 部署支持多种环境,包括虚拟机、裸机部署,还很好地支持常见云平台,包括AWS、GCE等; 支持丰富的运维工具,方便用户对集群进行性能测试、问题检查和状态监控; 自带控制台、客户端命令等工具,允许用户通过多种方式与kubernetes集群进行交互。 基于Kubernetes,可以很容易地实现一套PaaS,比如Openshift和Deis。Kubernetes目前在github.com/kubernetes/kubernetes进行维护。 Kubernete模型中的核心概念。这些核心概念反映了Kubernetes设计过程中对应用容器集群的认知模型。 集群组件,从架构上看,Kubernetes集群(Cluster)也采用了典型的“主-从”架构。一个集群主要由管理组件(Master)和工作节点(Node)组件构成。 Kubernetes集群的主要任务始终围绕着应用的生命周期。通过将不同资源进行不同层次的抽象,Kubernetes提供了灵活可靠的生命周期管理。 资源的核心抽象主要包括: 容器组(Pod):由位于同一节点上若干容器组成,彼此共享网络命名空间和存储卷(Volume)。Pod是Kubernetes中进行管理的最小资源单位,是最为基础的概念。跟容器类似,Pod是短暂的,随时可变的; 服务(Service):若干(往往是同类型的)Pod形成的对外提供某个功能的抽象,不随Pod改变而变化,带有唯一固定的访问路径,如IP地址或者域名。 复制控制器(Replication Controller):负责启动Pod,并维护其健康运行的状态。是用户管理Pod的句柄。 部署(Deployment):创建Pod,并可根据参数自动创建管理Pod的复制控制器,并且支持升级。1.2.0版本引入提供比复制控制器更方便的操作; 横向Pod扩展器(Horizontal Pod Autoscaler,HPA):类似云里面的自动扩展组,根据Pod的使用率(典型如CPU)自动调整一个部署里面Pod的个数,保障服务可用性; 还有一些管理资源相关的辅助概念,主要包括: 注解(Annotation):键值对,可以存放大量任意数据,一般用来添加对资源对象的详细说明,可供其他工具处理。 标签(Label):键值对,可以标记到资源对象上,用来对资源进行分类和筛选; 名字(Name):用户提供给资源的别名,同类资源不能重名; 命名空间(Namespace):这里是指资源的空间,避免不同租户的资源发生命名冲突,另外可以进行资源限额; 持久卷(PersistentVolume):类似于Docker中数据卷的概念,就是一个数据目录,Pod对其有访问权限。 秘密数据(Secret):存放敏感数据,例如用户认证的口令等; 选择器(Selector):基于标签概念的一个正则表达式,可通过标签来筛选出一组资源; Daemon集(DaemonSet):确保节点上肯定运行某个Pod,一般用来采集日志和监控节点; 任务(Job):确保给定数目的Pod正常退出(完成了任务); 入口资源(Ingress Resource):用来提供七层代理服务; 资源限额(Resource Quotas):用来限制某个命名空间下对资源的使用,开始逐渐提供多租户支持; 安全上下文(Security Context):应用到容器上的系统安全配置,包括uid、gid、capabilities、SELinux角色等; 服务账号(Service Accounts):操作资源的用户账号。

优秀的个人博客,低调大师

Choosing Between ElasticSearch, MongoDB & Hadoop

An interesting trend has been developing in the IT landscape over the past few years. Many new technologies develop and immediately latch onto the “Big Data” buzzword. And as older technologies add “Big Data” features in an attempt to keep up with the Joneses, we areseeing a blurring of the boundaries between various technologies. Say you have search engines such as ElasticSearch or Solr storing JSON documents, MongoDB storing JSON documents, or a pile of JSON documents stored in HDFS on a Hadoop cluster. Interestingly enough, you can fulfill many of the same use cases with any of these three configurations. ElasticSearch as a NoSQL database? Superficially, that doesn’t sound right, but nonethelessit is a valid scenario. Likewise, MongoDB with support for MapReduce over sharded collections can accomplish many of the same things as Hadoop. And, of course, with the many tools that you can layer on top of a Hadoop base (Hive, HBase, Pig, and the like) you can query data from your Hadoop cluster in a multitude of ways. Given that, can we now say that Hadoop, MongoDB and ElasticSearch are all exactly equivalent? Of course not. Each tool still has a niche for which it is most ideally suited, but each has enough flexibility to fulfill multiple roles. The question now becomes “What is the ideal use for each of these technologies”, and that my friends is what we will explore now. ElasticSearch has begun to spread beyond its roots as a “pure” search engine and now adds some features for analytics and visualization - but at its core,remains primarily a full-text search engine for locating documents by keyword. ElasticSearch builds on top of Lucene and supports extremely fast lookup and a rich query syntax. If you have millions (or more) of text documents and you need to locate documents by keywords located in that text, ElasticSearch fits the bill perfectly. Yes, if your documents are JSON you can treat ElasticSearch as a sort of lightweight “NoSQL database”. But ElasticSearch is not quite a “database engine” and provides less support for complex calculations and aggregation as part of a query - although the “statistics” facet does provide some ability to retrieve calculated statistical information scoped to the given query. Facets in ElasticSearch are intended mainly to support a “faceted navigation” facility. If you are looking to return a (usually small) collection of documents in response to a keyword query, and want the ability to support faceted navigation around those documents, then ElasticSearch is probably your best, first choice. If you need to perform more complex calculations, run server-side scripts against your data, and easily run MapReduce jobs on your data, then MongoDB or Hadoop enter the picture. 假设你的目的是通过指定keyword查询取得一个文档集合(一般是较小的),而且具有支持对文档基于切面的导航,elasticsearch会非常合适,可是假设你希望支持很多其它复杂的计算,在server端你的数据上执行脚本,非常easy的在你的数据上执行mapreduce成寻。那么MongoDB和Hadoop就在被考虑的范围里边了。 MongoDB is a “NoSQL” database which is designed from the ground up to be highly scalable, with automatic sharding support and a number of additional performance optimizations. MongoDB is a document oriented database which stores document in a “JSON like” format (technically BSON) with some extensions beyond plain JSON - for example, a native date type. MongoDB provides a text index type for supporting full-text search against fields which contain text, so we can see that there is overlap between what you can do with ElasticSearch and MongoDB, in terms of basic keyword search against a collection of documents. Where MongoDB goes beyond ElasticSearch is its support for features like server-side scripts in Javascript, aggregation pipelines, MapReduce support and capped collections. With MongoDB, you can use aggregation pipelines to process documents in a collection, streaming them through a sequence of pipeline operators where each operator transforms the document. Pipeline operators can generate entirely new documents or remove documents from the final output. This is a very powerful facility for filtering, processing and transforming data as it is retrieved. MongoDB also supports running map/reduce jobs over the data in a collection, using custom Javascript functions for the map and reduce phases of the operation. This allows for ultimate flexibility in performing any type of calculation or transformation to the selected data. 与ES相比,MongoDB超过es的地方是支持server端的javascript和聚合管道 以及MapReduce的支持和capped collections Another extremely powerful feature in MongoDB is known as “capped collections”. With the capped collections facility, a user can define a maximum size for a collection - after which the collection can simply be written to blindly, and it will roll-over data as necessary to maintain the specified size limit. This feature is extremely useful for capture logs and other streaming data for analysis. 另外一个很NB的特征是capped collections;通过capped collections。用户能够定义为一个collection定义最大的size,用来插入数据(仅仅能插入更新 不能删除)。依照LRU挤出数据存放新插入的数据,这个特点很适合获取log数据和流数据的存储和分析 科普一下capped collections 特点: 1.仅仅能插入,更新,不能删除doc,能够使用drop()删除整个collection 2.LRU列表。相信大家对这个应该非常了解了,oracle里面非常多地方就是用的这个规则,假设指定的集合大小满了。那么会依照LRU挤出数据存放新插入的数据,这里记得更新是不能超出collection的大小的,不能挤出空间存放更新的数据,这个也合情合理。 3.插入的记录都是依照插入的顺序排列,普通的collection在_id上是肯定有索引的,可是这里是没有的 4.能够高速的查询和插入。假设写比读的比例大。建议不要建立索引。否则写会耗费非常多额外的资源。 As you can see, while ElasticSearch and MongoDB have some overlap in possible use cases, they are not the same tool. But what about Hadoop? Isn’t Hadoop “just MapReduce” which is supported by MongoDB anyway? Is there really a use case for Hadoop where MongoDB isjust as suitable. In a word, yes. Hadoop is the grand-father of MapReduce based cluster computing frameworks. Hadoop provides probably the overall most flexible and powerful environment for processing large amounts of data, and definitely fits niches for which you would not use ElasticSearch or MongoDB. To understand why this is true, look at how Hadoop abstracts storage - via HDFS - from the associated computational facility. With data stored in HDFS, any arbitrary job can be run against that data, using either Java code written to the core MapReduce API, or arbitrary code written in native languages using Hadoop Streaming. And starting with Hadoop2 and YARN, even the core programming model is abstracted so that you aren’t limited to MapReduce. With YARN you can, for example, implement MPI on top of Hadoop and write jobs in that style. Additionally, the Hadoop ecosystem provides a staggering array of tools that build on top of HDFS and core MapReduce to query, analyze and process data. Hive provides a “SQL like” language that allows Business Analysts to query data using a syntax they are already familiar with. HBase provides a column oriented database on top of Hadoop. Pig and Sizzle provide two more alternative programming models for querying Hadoop Data. With data stored in HDFS using Hadoop, you inherit the ability to simply plugin Apache Mahout to use advanced machine learning algorithms on your data. While using RHadoopis straightforward to use the R statistical language to perform advanced statistical analyses on Hadoop data. So while Hadoop and MongoDB also have some overlapping use cases, and share some useful functionality (seamless horizontal scalability, for example) it remains the case that each tool serves a specific purpose in enterprise computing. If you simply want to locate documents by keyword and perform simple analytics, then ElasticSearch mayfit the bill. If you need to query documents that can be modeled as JSON and perform moderately more sophisticated analysis, then MongoDB becomes a compelling choice. And if you have a huge quantity of data that needs a wide variety of different types of complex processing and analysis, then Hadoop provides the broadest range of tools and the most flexibility. As always, it is important to choose the right tool(s) for the job at hand. And in the “Big Data” space the sheer number of technologies and the blurry lines can make this difficult. As we can see, there are specific scenarios which best suit each of these technologies and, more importantly,the differences do matter. Though, the best news of all isyou are notlimited to using only one of these tools. Depending on the details of your use case, it may actually make sense to build a combination platform. For example, ElasticSearch and Hadoop are known to work well together, with ElasticSearch providing rapid keyword search, and Hadoop jobs powering the more complicated analytics. In the end, it takes ample research and careful analysis to make the best choices for your computing environment. Before selecting any technology or platform, take the time to evaluate it carefully, understand what scenarios it was designed to optimize for, and what tradeoffs and sacrifices it makes. Start with a small pilot project to “kick the tires” before converting your entire enterprise to a new platform, and slowly grow into the new stack. Follow these steps and you can successfully navigate the maze of “Big Data” technologies and reap the associated benefits.\ 本文转自:http://www.osintegrators.com/opensoftwareintegrators%7CChoosing-Between-ElasticSearch-MongoDB-%2526-Hadoop 本文转自mfrbuaa博客园博客,原文链接:http://www.cnblogs.com/mfrbuaa/p/5208702.html,如需转载请自行联系原作者

优秀的个人博客,低调大师

Android Step Counter & Detector Sensor

package zhangphil.sensor; import android.content.Context; import android.hardware.Sensor; import android.hardware.SensorEvent; import android.hardware.SensorEventListener; import android.hardware.SensorManager; import android.support.v7.app.AppCompatActivity; import android.os.Bundle; import android.util.Log; public class MainActivity extends AppCompatActivity { private String TAG = "ZHANG PHIL"; private SensorManager mSensorManager; @Override protected void onCreate(Bundle savedInstanceState) { super.onCreate(savedInstanceState); startSensor(); } /** * 启动传感器。 */ private void startSensor() { mSensorManager = (SensorManager) this.getSystemService(Context.SENSOR_SERVICE); Sensor mStepCounterSensor = mSensorManager.getDefaultSensor(Sensor.TYPE_STEP_COUNTER); Sensor mStepDetectorSensor = mSensorManager.getDefaultSensor(Sensor.TYPE_STEP_DETECTOR); if (mSensorManager == null || mStepCounterSensor == null || mStepDetectorSensor == null) { throw new UnsupportedOperationException("设备不支持"); } mSensorManager.registerListener(mSensorEventListener, mStepCounterSensor, SensorManager.SENSOR_DELAY_NORMAL); mSensorManager.registerListener(mSensorEventListener, mStepDetectorSensor, SensorManager.SENSOR_DELAY_NORMAL); } private SensorEventListener mSensorEventListener = new SensorEventListener() { private float step, stepDetector; @Override public void onSensorChanged(SensorEvent sensorEvent) { /** * 计步计数传感器传回的历史累积总步数 */ if (sensorEvent.sensor.getType() == Sensor.TYPE_STEP_COUNTER) { step = sensorEvent.values[0]; Log.d(TAG, "STEP_COUNTER:" + step); } /** * 计步检测传感器检测到的步行动作是否有效? */ if (sensorEvent.sensor.getType() == Sensor.TYPE_STEP_DETECTOR) { stepDetector = sensorEvent.values[0]; Log.d(TAG, "STEP_DETECTOR:" + stepDetector); if (stepDetector == 1.0) { Log.d(TAG, "一次有效的步行"); } } } @Override public void onAccuracyChanged(Sensor sensor, int i) { } }; @Override protected void onDestroy() { super.onDestroy(); mSensorManager.unregisterListener(mSensorEventListener); } }

优秀的个人博客,低调大师

Ubuntu SVN安装&使用&命令

SVN 安装 apt-get install subversion checkout svn checkout svn://192.168.1.110/app 按提示输入相应的用户名和密码。 往版本库中添加新的文件 svn add *.c //(添加当前目录下所有的 c文件) 将改动的文件提交到版本库 svn commit -m “my commit“ test.cpp 删除文件 svn delete svn://192.168.1.100/app/php/helloworld.php -m “delete file” help帮助 svn help chechout checkout (co): Check out a working copy from a repository. usage: checkout URL[@REV]... [PATH] SVN常用命令 checkout svn checkout path(path 是服务器上的目录) //例如:svn checkout svn://192.168.1.100/app/ 添加新的文件 svn add file //例如:svn add test.php(添加test.php) 将改动的文件提交到版本库 svn commit -m “LogMessage“ [-N] [--no-unlock] PATH (如果选择了保持锁,就使用–no- unlock开关) //例如:svn commit -m “add test file for my test“ test.php 加锁/解锁 svn lock -m “LockMessage“ [--force] PATH //例如:svn lock -m “lock test file“ test.php 更新到某个版本 svn update -r m path //例如: //svn update如果后面没有目录,默认将当前目录以及子目录下的所有文件都更新到最新版本。 //svn update -r 200 test.php(将版本库中的文件test.php还原到版本200) //svn update test.php(更新,于版本库同步。如果在提交的时候提示过期的话,是因为冲突,需要先update,修改文件,然后清除svn resolved,最后再提交commit) 查看文件或者目录状态 svn status path(目录下的文件和子目录的状态,正常状态不显示) //【?:不在svn的控制中;M:内容被修改;C:发生冲突;A:预定加入到版本库;K:被锁定】 svn status -v path(显示 文件和子目录状态) //第一列保持相同,第二列显示工作版本号,第三和第四列显示最后一次修改的版本号和修改人。 //注:svn status、svn diff和 svn revert这三条命令在没有网络的情况下也可以执行的,原因是svn在本地的.svn中保留了本地版本的原始拷贝。 删除文件 svn delete path -m “delete test fle“ //例如:svn delete svn://192.168.1.100/app/php/test.php -m “delete test file” //或者直接svn delete test.php 然后再svn ci -m ‘delete test file‘,推荐使用这种 查看日志 svn log path //例如:svn log test.php 显示这个文件的所有修改记录,及其版本号的变化 查看文件详细信息 svn info path //例如:svn info test.php 比较差异 svn diff path(将修改的文件与基础版本比较) //例如:svn diff test.php svn diff -r m:n path(对版本m和版本n比较差异) //例如:svn diff -r 200:201 test.php 将两个版本之间的差异合并到当前文件 svn merge -r m:n path //例如:svn merge -r 200:205 test.php(将版本200与205之间的差异合并到当前文件,但是一般都会产生冲突,需要处理一下) 恢复本地修改 svn revert: 恢复原始未改变的工作副本文件 (恢复大部份的本地修改)。revert: //注意: 本子命令不会存取网络,并且会解除冲突的状况。但是它不会恢复被删除的目录 本文转自我爱物联网博客园博客,原文链接:http://www.cnblogs.com/yydcdut/p/4300332.html如需转载请自行联系原作者

优秀的个人博客,低调大师

Openstack API 类型 & REST 风格

目录 目录 Openstack 提供了三种操作方式 Web界面 CIL 指令行 RESTful API REST 风格 RESTFul风格的API设计 基于HTTP协议的RESTful API OpenStack中的RESTful API开发框架 Openstack 提供了三种操作方式 Web界面 也就是通过Dashboard(儀表板)来使用Openstack雲計算平台上的功能。通过Web界面使用 OpenStack Services 这种方式是通过 OpenStack Horizon Project 提供的。Horizon Project 是一个Django Web Application。Horizon Project 会通过API来和各个 OpenStack Services 进行交互,然后在 Web 界面上顯示這些 Services 的状态和交互結果。 CIL 指令行 通过以往的 keystone、nova、neutron 等指令,或者通过最新的 OpenStack 指令来操作各个 Services 的功能。社区目前希望使用統一的 OpenStack 指令來代替以往每个 Project 都有各自的 Commands 的方式,这些 Commands 是由命名为 client(EG. keystoneclient、novaclient) 的項目所實現的。這些 client 項目除了爲用户提供命令行操作界面方式之外還提供了 Python 的 SDK (其实是在SDK的基础上实现了命令行)。这些 client 项目提供的 SDK 本質是封装了這些 Openstack services 的 API 的调用。現在 Openstack 社區希望僅使用 openstackclient 作爲统一的命令行工具,然后使用各个 Services 的 client 项目所提供的 SDK 来完成相应的操作。 RESTful API 通过各个 OpenStack Project 提供的 API 来使用各 Services 的功能。API 这种方式是支撐上述兩種方式的基础,由各个 Services 自身來实现使用 API 操作 OpenStack 的方式。这些 API 具有统一的形式,均采用了基於 HTTP 协议的 Restful 风格来实现。Openstack API 服务进程在接收了客户端的HTTP Request之后,一个所谓的 路由 模块就会将URL转换成为相应的资源,并路由到合适的操作函数上去。以此来实现了从API到具体操作的映射。 REST 风格 REST(Representational State Transfer)表述性状态转换,是一种软件架构的设计风格,而不是一种标准,为软件设计提供了一组原则和约束条件,但这是原则和约束的条件也同样不具有标准性。所以也可以将REST理解为是一组没有严格标准的架构约束条件和设计原则。REST的软件设计倾向于简单轻量的方法设计和实现,以及**REST具有通过HTTP直接传输数据的特性。**REST风格的软件架构必须满足下面两点规范: URI 标识资源:首先从Restful的角度来看,互联网上的任何东西(文本/图片/视频/歌曲/Services)都是一个资源。每个资源都使用了一个特定的URI来唯一标示,访问这一个URI就是访问这一个资源,而且这个资源具有至少一种状态。 无状态原则: 再一个就是,Client 和 Server 之间互相传递的只是资源的表述,即:调用资源的URI并获取资源的不同表现形式。并且 Client 和 Server 之间的交互是由 HTTP 无状态协议来支撑的,所以资源的所有状态都只会保存在 Server 中。当 Client 应用 HTTP 协议中的 GET/POST/PUT/DELETE 操作资源时,会使得 Server 中的资源的状态发生转换,这就是所谓的“表述性状态转换”。 RESTFul风格的API设计 你的URI中应该都是名词,表示一个事物,而非动词。EG. /resources/142 是好的URI,它看起来像是一个事物 而 /resources/142/get 则不是好的URI,因为它看起来更像是一个动作,只有事物才符合资源的定义。 面向资源的体系结构 URI使用名词,不使用动词 资源地址即URI 无状态性 灵活使用单数和复数 传输资源的表现形式(Web Server 接收和返回的互联网媒体类型,JSON/XML) 对资源的操作与HTTP内置方法映射 基于HTTP协议的RESTful API 由于这种软件设计风格非常适合采用HTTP协议来实现,因此HTTP协议是目前实现RESTful API的主要方案。 OpenStack 就是基于 HTTP 协议和 JSON 来实现自己的 RESTful API(之前OpenStack还有采用XML来表示数据的,现在都已经转到JSON了)。当一个 Service 要对外提供 API 时,它就会启动一个 HTTP Web Server,用来对外提供 RESTful API。 OpenStack 的 API 都是有详细的文档记录的,可以查看所有的API文档。 OpenStack 的 API 服务都是使用 WSGI 的方式来部署的。部署WSGI,一般会使用 Web Server + Application Server + Application(框架) 的部署方式。OpenStack 官方推荐的是使用 Apache + mod_wsgi ,当然你也可以选 nginx + uWSGI 。还有些项目会提供使用 eventlet 的单进程部署方案(EG. Keystone项目的keystone-all命令)。 OpenStack中的RESTful API开发框架 OpenStack 早期的核心项目(EG. Keystone/Nova/Glance/Neutron)使用了由几个模块组合出来的一个框架: Paste + PasteDeploy + Routes + WebOb 。这些模块分别负责了应用的 WSGI 化、URL 路由和请求处理等功能。但是这种框架存在着较为复杂的弊端,所以现在 Openstack 社区的新项目已经开始使用新的 Web 框架 Pecan。 Pecan 是一个基于对象路由的框架,即灵活又简单。Pecan 主要实现了 URL 路由功能,支持 RESTful API 。Pecan 没有实现模板、session 管理、 ORM 等功能,但是这些功能可以通过其他的模块来实现。对于 OpenStack 来说,Pecan 是一个很好的选择,因为 OpenStack 项目中统一使用 sqlalchemy 来实现ORM,API的实现也不需要模板功能,安全控制则基于 Keystone 体系。使用 Pecan 来开发 REST 服务,代码量很少,代码结构也清晰。

优秀的个人博客,低调大师

hadoop(2): 安装&使用 sqoop

本文的原文连接是: http://blog.csdn.net/freewebsys/article/details/47722393 未经博主允许不得转载。 1,关于sqoop Sqoop是一个用来将Hadoop和关系型数据库中的数据相互转移的工具,可以将一个关系型数据库(例如 : MySQL ,Oracle ,Postgres等)中的数据导入到Hadoop的HDFS中,也可以将HDFS的数据导入到关系型数据库中。 官网:http://sqoop.apache.org/ 一个1.4.6 版本,一个是1.99版本(开发版还没有迁移完成,生产环境不推荐) 文档: http://sqoop.apache.org/docs/1.4.6/ 2,安装 参考之前的文章hadoop和hive用的是2.0,所以sqoop这里也用2.0,不过是alpha。直接解压缩。 配置环境变量 export JAVA_HOME=/usr/java/default export CLASS_PATH=$JAVA_HOME/lib export PATH=$JAVA_HOME/bin:$PATH export HADOOP_HOME=/data/hadoop export PATH=$HADOOP_HOME/bin:$PATH export HIVE_HOME=/data/apache-hive export PATH=$HIVE_HOME/bin:$PATH export SQOOP_HOME=/data/sqoop export PATH=$SQOOP_HOME/bin:$PATH sqoop启动的时候会检查hbase环境变量,不需要,直接注释 /data/sqoop/bin/configure-sqoop 的128 行到 147行。 128 ## Moved to be a runtime check in sqoop. 129 #if [ ! -d "${HBASE_HOME}" ]; then 130 # echo "Warning: $HBASE_HOME does not exist! HBase imports will fail." 131 # echo 'Please set $HBASE_HOME to the root of your HBase installation.' 132 #fi 133 134 ## Moved to be a runtime check in sqoop. 135 #if [ ! -d "${HCAT_HOME}" ]; then 136 # echo "Warning: $HCAT_HOME does not exist! HCatalog jobs will fail." 137 # echo 'Please set $HCAT_HOME to the root of your HCatalog installation.' 138 #fi 139 140 #if [ ! -d "${ACCUMULO_HOME}" ]; then 141 # echo "Warning: $ACCUMULO_HOME does not exist! Accumulo imports will fail." 142 # echo 'Please set $ACCUMULO_HOME to the root of your Accumulo installation.' 143 #fi 144 #if [ ! -d "${ZOOKEEPER_HOME}" ]; then 145 # echo "Warning: $ZOOKEEPER_HOME does not exist! Accumulo imports will fail." 146 # echo 'Please set $ZOOKEEPER_HOME to the root of your Zookeeper installation.' 147 #fi hadoop和hive参考之前写的博客: http://blog.csdn.net/freewebsys/article/details/47617975 sqoop命令主要就分为数据导入到hadoop,和数据从hadoop导出到 mysql。 首先创建mysql数据库blog,创建一个hadoop用户操作blog库,blog库里面创建一个msg表,插入6条记录 CREATE DATABASE blog DEFAULT CHARACTER SET utf8 COLLATE utf8_general_ci; GRANT ALL PRIVILEGES ON blog.* TO sqoop@"%" IDENTIFIED BY "sqoop"; FLUSH PRIVILEGES; ##创建msg和 msg_hive数据表: CREATE TABLE `msg_hive` ( `id` bigint(20) NOT NULL, `gid` bigint(20) DEFAULT NULL , `content` varchar(4000), `create_time` datetime DEFAULT NULL COMMENT '创建时间', PRIMARY KEY (`id`,`gid`) ) ENGINE=MyISAM DEFAULT CHARSET=utf8 PARTITION BY KEY(`gid`); CREATE TABLE `msg` ( `id` bigint(20) NOT NULL, `gid` bigint(20) DEFAULT NULL , `content` varchar(4000), `create_time` datetime DEFAULT NULL COMMENT '创建时间', PRIMARY KEY (`id`,`gid`) ) ENGINE=MyISAM DEFAULT CHARSET=utf8 PARTITION BY KEY(`gid`); #插入测试数据。 insert into `msg`(id,gid,content,create_time) values(1,1,'zhang san 11',now()); insert into `msg`(id,gid,content,create_time) values(1,2,'zhang san 22',now()); insert into `msg`(id,gid,content,create_time) values(1,3,'zhang san 33',now()); insert into `msg`(id,gid,content,create_time) values(2,1,'li si 11',now()); insert into `msg`(id,gid,content,create_time) values(2,2,'li si 22',now()); insert into `msg`(id,gid,content,create_time) values(2,3,'li si 33',now()); 3,sqoop使用,导入,导出 首先测试下数据库连接执行select。 sqoop eval --connect jdbc:mysql://127.0.0.1:3306/blog --username sqoop --password sqoop --query 'select now()' ##执行结果: ----------------------- | now() | ----------------------- | 2015-08-18 17:22:26.0 | ----------------------- 将mysql 数据导入到hive中,其实就是导入到hadoop上面,这里需要指定输出目录是hive的warehouse目录: sqoop import --direct --connect jdbc:mysql://127.0.0.1:3306/blog --username sqoop --password sqoop --table msg \ --fields-terminated-by "\001" --lines-terminated-by "\n" --delete-target-dir --null-string '\\N' --null-non-string '\\N' --target-dir /user/hive/warehouse/msg 参数一大堆,设置分隔符的,设置null的。最后指定hive的warehouse目录。 但是这样hive还不识别这个表,必须在hive中创建下。 sqoop create-hive-table --hive-table msg --connect jdbc:mysql://127.0.0.1:3306/blog --username sqoop --password sqoop --table msg 将hive 数据导入到 mysql中。 sqoop export --direct --connect jdbc:mysql://127.0.0.1:3306/blog --username sqoop --password sqoop --table msg_hive \ --fields-terminated-by "\001" --lines-terminated-by "\n" --export-dir /user/hive/warehouse/msg 同样的需要配置export-dir,配置mysql的数据表msg_hive 检查结果:(分别在hive和mysql中查看数据) hive> select * from msg; OK 1 1 zhang san 11 2015-08-17 12:11:32 1 2 zhang san 22 2015-08-17 12:11:33 1 3 zhang san 33 2015-08-17 12:11:33 2 1 li si 11 2015-08-17 12:11:33 2 2 li si 22 2015-08-17 12:11:33 2 3 li si 33 2015-08-17 12:11:33 Time taken: 0.105 seconds, Fetched: 6 row(s) mysql> select * from msg_hive; +----+-----+--------------+---------------------+ | id | gid | content | create_time | +----+-----+--------------+---------------------+ | 2 | 1 | li si 11 | 2015-08-17 12:11:33 | | 2 | 2 | li si 22 | 2015-08-17 12:11:33 | | 2 | 3 | li si 33 | 2015-08-17 12:11:33 | | 1 | 3 | zhang san 33 | 2015-08-17 12:11:33 | | 1 | 1 | zhang san 11 | 2015-08-17 12:11:32 | | 1 | 2 | zhang san 22 | 2015-08-17 12:11:33 | +----+-----+--------------+---------------------+ 6 rows in set (0.00 sec) 4,总结 本文的原文连接是: http://blog.csdn.net/freewebsys/article/details/47722393 未经博主允许不得转载。 sqoop提供了import和export功能,很方便的就可以迁移mysql和hive的数据。 业务数据需要迁移到hadoop上面进行计算,同时,将计算结果放到mysql数据库中进行统计显示。 数据可以方便的流动。 参考: http://segmentfault.com/a/1190000002532293 写的参数很详细。

优秀的个人博客,低调大师

容器服务&&AHAS Sentinel 弹性 Demo

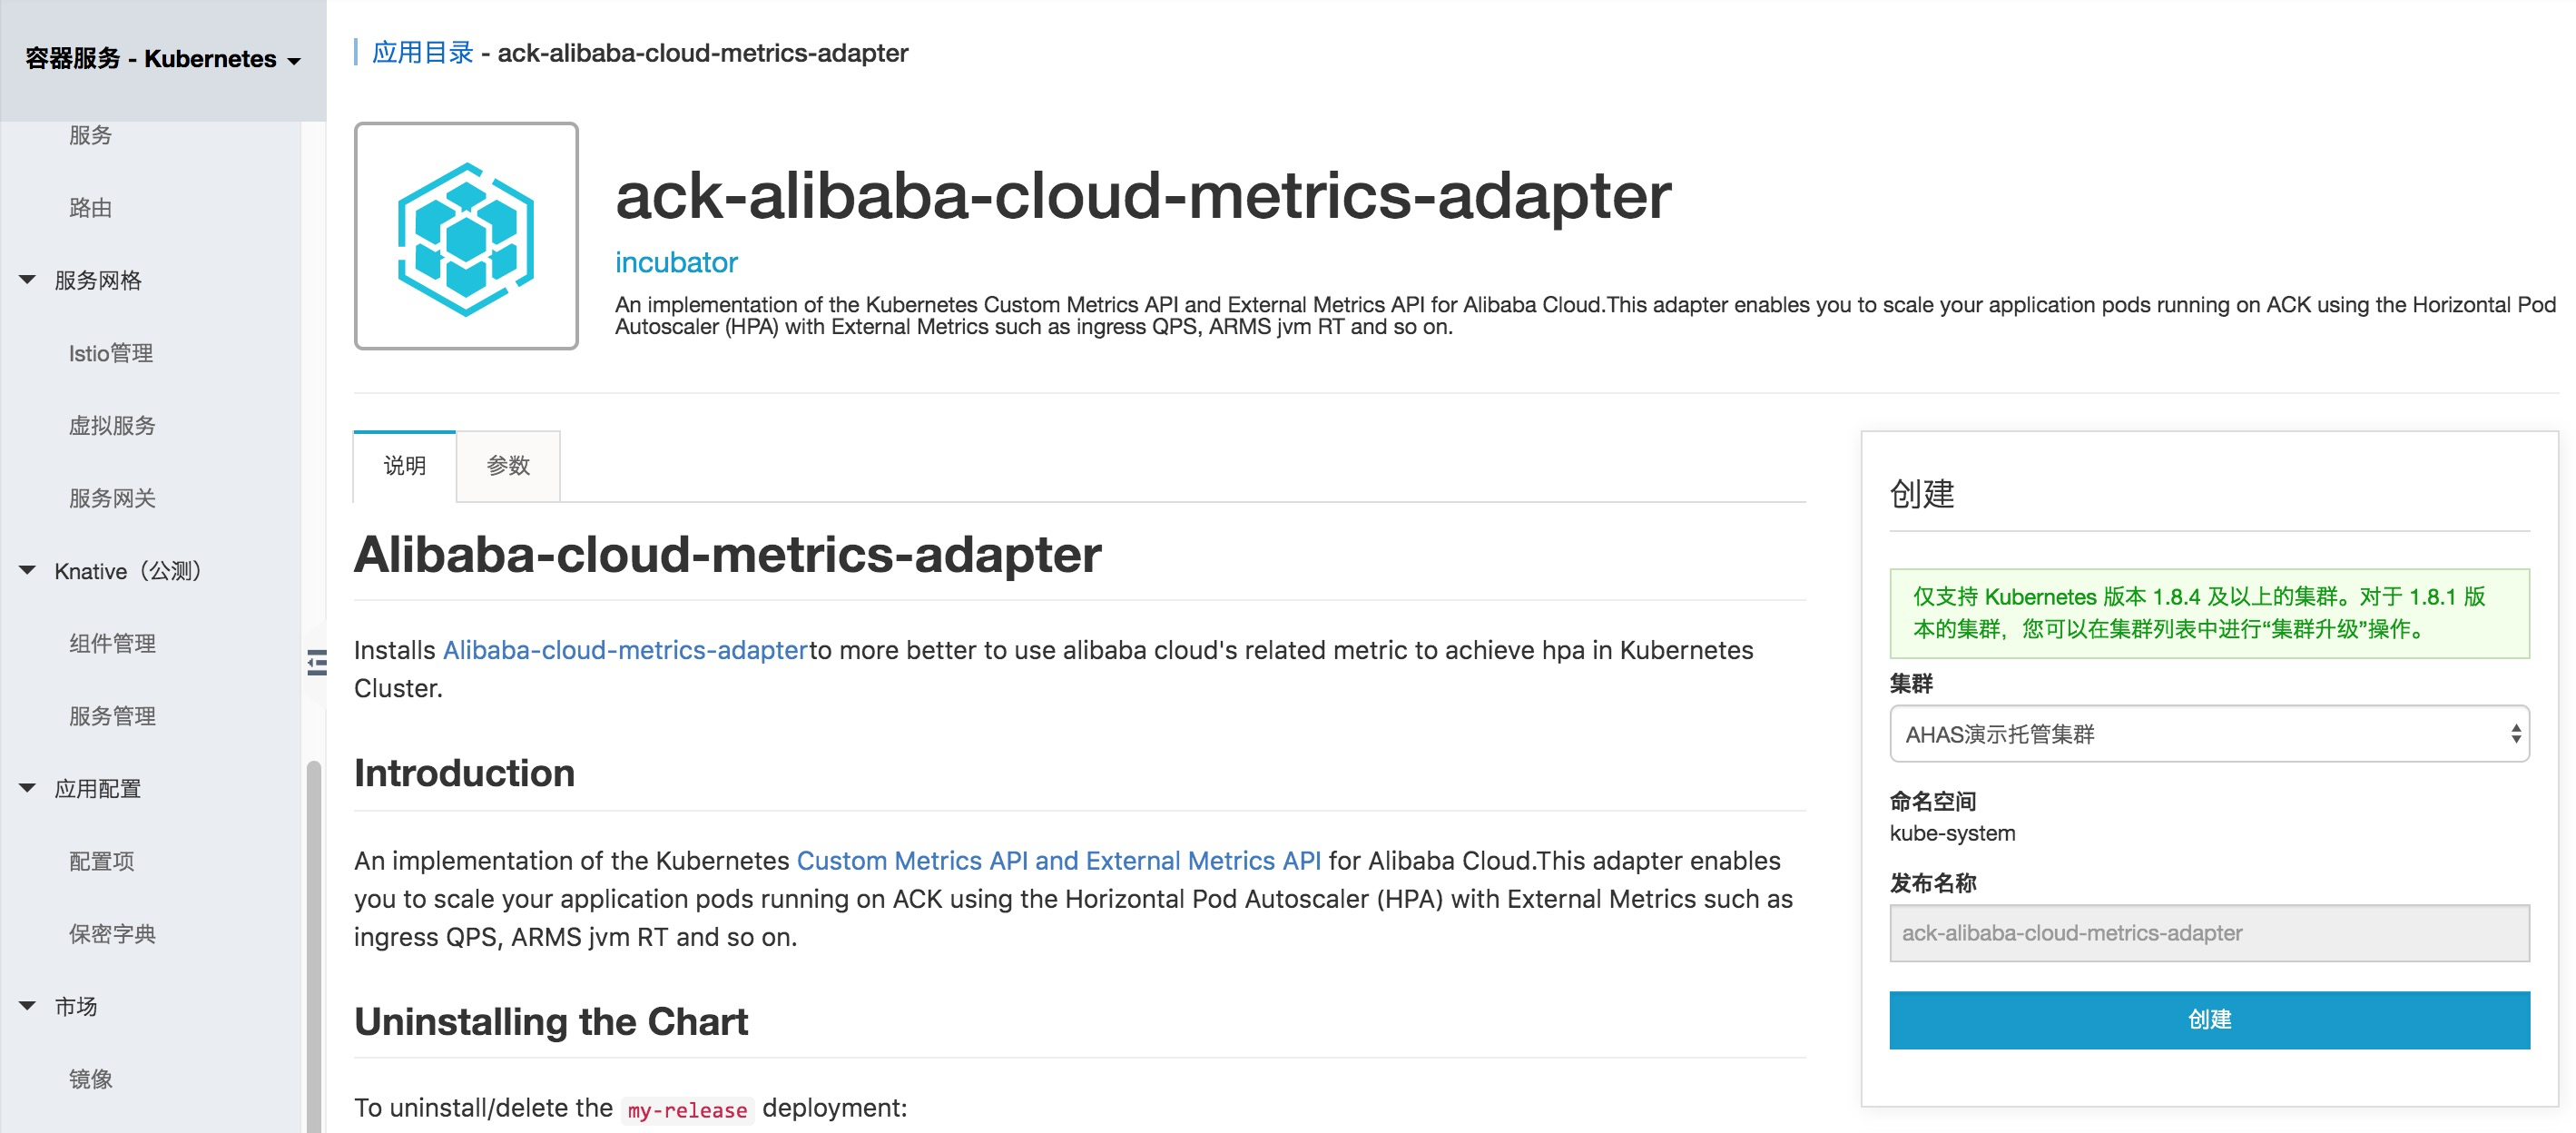
应用高可用服务 AHAS(Application High Availability Service)是一款阿里云应用高可用服务相关产品。只要容器服务中的 Java 应用接入了 AHAS 应用流控组件后,用户的应用实例就可以自动根据 AHAS Sentinel 收集的指标(如 QPS、平均响应时间等)进行弹性伸缩,使得系统可以自动根据实时的流量情况进行扩缩容,保证系统的可用性。 0. 安装 alibaba-cloud-metrics-adapter 可以直接在容器服务控制台 应用目录 中安装 alibaba-cloud-metrics-adapter。 相关 repo:https://github.com/AliyunContainerService/alibaba-cloud-metrics-adapter 1. 安装 AHAS Sen

优秀的个人博客,低调大师

Docker 上传镜像&拉取镜像

版权声明:本文为博主原创文章,未经博主允许不得转载。 https://blog.csdn.net/qq_36367789/article/details/81623850 与git相似,docker也有自己的镜像仓库,官方仓库网站是https://hub.docker.com/,其实我们平时docker pull xxx就是从该仓库得到的镜像(在不设置国内镜像加速的情况下)。它和git仓库很相似。 创建账号 DockerHub:https://hub.docker.com/ 很多人在这里就出了问题,为什么都填完了但是不能点注册按钮呢?因为该网站目前来说注册是需要翻墙的,注册成功后再关闭翻墙。 我重新上传一个项目做示范,该镜像是从hub上pull到的一个nginx镜像,我把它上传到我的公开仓库。 上传镜像 先登录docker hub账号。 docker login [root@FantJ ~]# docker login Login with your Docker ID to push and pull images from Docker Hub. If you don't have a Docker ID, head over to https://hub.docker.com to create one. Username (fantj): fantj Password: Login Succeeded [root@FantJ ~]# docker images REPOSITORY TAG IMAGE ID CREATED SIZE docker.io/openjdk 8-jre bef23b4b9cac 2 weeks ago 443 MB docker.io/nginx latest ae513a47849c 4 weeks ago 109 MB [root@FantJ ~]# docker tag docker.io/nginx fantj/nginx [root@FantJ ~]# docker images REPOSITORY TAG IMAGE ID CREATED SIZE docker.io/openjdk 8-jre bef23b4b9cac 2 weeks ago 443 MB fantj/nginx latest ae513a47849c 4 weeks ago 109 MB docker.io/nginx latest ae513a47849c 4 weeks ago 109 MB [root@FantJ ~]# docker push fantj/nginx The push refers to a repository [docker.io/fantj/nginx] 7ab428981537: Mounted from library/nginx 82b81d779f83: Mounted from library/nginx d626a8ad97a1: Mounted from library/nginx latest: digest: sha256:e4f0474a75c510f40b37b6b7dc2516241ffa8bde5a442bde3d372c9519c84d90 size: 948 [root@FantJ ~]# 流程大概是:登录->tag操作->push 注:tag 的第二个参数的前缀是你的hub账户名 拉取镜像 我先把服务器上的镜像删除掉,然后再从hub中拉取镜像。 # 删除本地fantj/nginx镜像 [root@FantJ ~]# docker images REPOSITORY TAG IMAGE ID CREATED SIZE docker.io/openjdk 8-jre bef23b4b9cac 2 weeks ago 443 MB fantj/nginx latest ae513a47849c 4 weeks ago 109 MB docker.io/nginx latest ae513a47849c 4 weeks ago 109 MB [root@FantJ ~]# docker rmi fantj/nginx Untagged: fantj/nginx:latest Untagged: fantj/nginx@sha256:e4f0474a75c510f40b37b6b7dc2516241ffa8bde5a442bde3d372c9519c84d90 [root@FantJ ~]# docker images REPOSITORY TAG IMAGE ID CREATED SIZE docker.io/openjdk 8-jre bef23b4b9cac 2 weeks ago 443 MB docker.io/nginx latest ae513a47849c 4 weeks ago 109 MB # 从hub中拉取fantj/nginx镜像 [root@FantJ ~]# docker pull fantj/nginx Using default tag: latest Trying to pull repository docker.io/fantj/nginx ... latest: Pulling from docker.io/fantj/nginx Digest: sha256:e4f0474a75c510f40b37b6b7dc2516241ffa8bde5a442bde3d372c9519c84d90 Status: Downloaded newer image for docker.io/fantj/nginx:latest [root@FantJ ~]# docker images REPOSITORY TAG IMAGE ID CREATED SIZE docker.io/openjdk 8-jre bef23b4b9cac 2 weeks ago 443 MB docker.io/fantj/nginx latest ae513a47849c 4 weeks ago 109 MB docker.io/nginx latest ae513a47849c 4 weeks ago 109 MB [root@FantJ ~]#

资源下载

更多资源
腾讯云软件源

腾讯云软件源

为解决软件依赖安装时官方源访问速度慢的问题,腾讯云为一些软件搭建了缓存服务。您可以通过使用腾讯云软件源站来提升依赖包的安装速度。为了方便用户自由搭建服务架构,目前腾讯云软件源站支持公网访问和内网访问。

Rocky Linux

Rocky Linux

Rocky Linux(中文名:洛基)是由Gregory Kurtzer于2020年12月发起的企业级Linux发行版,作为CentOS稳定版停止维护后与RHEL(Red Hat Enterprise Linux)完全兼容的开源替代方案,由社区拥有并管理,支持x86_64、aarch64等架构。其通过重新编译RHEL源代码提供长期稳定性,采用模块化包装和SELinux安全架构,默认包含GNOME桌面环境及XFS文件系统,支持十年生命周期更新。

Sublime Text

Sublime Text

Sublime Text具有漂亮的用户界面和强大的功能,例如代码缩略图,Python的插件,代码段等。还可自定义键绑定,菜单和工具栏。Sublime Text 的主要功能包括:拼写检查,书签,完整的 Python API , Goto 功能,即时项目切换,多选择,多窗口等等。Sublime Text 是一个跨平台的编辑器,同时支持Windows、Linux、Mac OS X等操作系统。

WebStorm

WebStorm

WebStorm 是jetbrains公司旗下一款JavaScript 开发工具。目前已经被广大中国JS开发者誉为“Web前端开发神器”、“最强大的HTML5编辑器”、“最智能的JavaScript IDE”等。与IntelliJ IDEA同源,继承了IntelliJ IDEA强大的JS部分的功能。

用户登录
用户注册