Hadoop MapReduce编程 API入门系列之最短路径(十五)
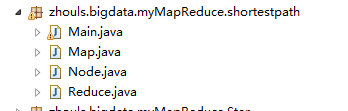
====================================== = Iteration: 1 = Input path: out/shortestpath/input.txt = Output path: out/shortestpath/1 ====================================== 2016-12-12 16:37:05,638 INFO [org.apache.hadoop.metrics.jvm.JvmMetrics] - Initializing JVM Metrics with processName=JobTracker, sessionId= 2016-12-12 16:37:06,231 WARN [org.apache.hadoop.mapreduce.JobSubmitter] - Hadoop command-line option parsing not performed. Implement the Tool interface and execute your application with ToolRunner to remedy this. 2016-12-12 16:37:06,236 WARN [org.apache.hadoop.mapreduce.JobSubmitter] - No job jar file set. User classes may not be found. See Job or Job#setJar(String). 2016-12-12 16:37:06,260 INFO [org.apache.hadoop.mapreduce.lib.input.FileInputFormat] - Total input paths to process : 1 2016-12-12 16:37:06,363 INFO [org.apache.hadoop.mapreduce.JobSubmitter] - number of splits:1 2016-12-12 16:37:06,831 INFO [org.apache.hadoop.mapreduce.JobSubmitter] - Submitting tokens for job: job_local535100118_0001 2016-12-12 16:37:07,524 INFO [org.apache.hadoop.mapreduce.Job] - The url to track the job: http://localhost:8080/ 2016-12-12 16:37:07,526 INFO [org.apache.hadoop.mapreduce.Job] - Running job: job_local535100118_0001 2016-12-12 16:37:07,534 INFO [org.apache.hadoop.mapred.LocalJobRunner] - OutputCommitter set in config null 2016-12-12 16:37:07,550 INFO [org.apache.hadoop.mapred.LocalJobRunner] - OutputCommitter is org.apache.hadoop.mapreduce.lib.output.FileOutputCommitter 2016-12-12 16:37:07,635 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Waiting for map tasks 2016-12-12 16:37:07,638 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Starting task: attempt_local535100118_0001_m_000000_0 2016-12-12 16:37:07,716 INFO [org.apache.hadoop.yarn.util.ProcfsBasedProcessTree] - ProcfsBasedProcessTree currently is supported only on Linux. 2016-12-12 16:37:07,759 INFO [org.apache.hadoop.mapred.Task] - Using ResourceCalculatorProcessTree : org.apache.hadoop.yarn.util.WindowsBasedProcessTree@27b70923 2016-12-12 16:37:07,767 INFO [org.apache.hadoop.mapred.MapTask] - Processing split: file:/D:/Code/MyEclipseJavaCode/myMapReduce/out/shortestpath/input.txt:0+149 2016-12-12 16:37:07,830 INFO [org.apache.hadoop.mapred.MapTask] - (EQUATOR) 0 kvi 26214396(104857584) 2016-12-12 16:37:07,830 INFO [org.apache.hadoop.mapred.MapTask] - mapreduce.task.io.sort.mb: 100 2016-12-12 16:37:07,830 INFO [org.apache.hadoop.mapred.MapTask] - soft limit at 83886080 2016-12-12 16:37:07,830 INFO [org.apache.hadoop.mapred.MapTask] - bufstart = 0; bufvoid = 104857600 2016-12-12 16:37:07,830 INFO [org.apache.hadoop.mapred.MapTask] - kvstart = 26214396; length = 6553600 2016-12-12 16:37:07,834 INFO [org.apache.hadoop.mapred.MapTask] - Map output collector class = org.apache.hadoop.mapred.MapTask$MapOutputBuffer input -> K[dee],V[0 null hadoop hello] output -> K[dee],V[0 hadoop hello] output -> K[hadoop],V[1 dee] output -> K[hello],V[1 dee] input -> K[hadoop],V[2147483647 null hive hello] output -> K[hadoop],V[2147483647 hive hello] input -> K[hello],V[2147483647 null dee hadoop hive joe] output -> K[hello],V[2147483647 dee hadoop hive joe] input -> K[hive],V[2147483647 null hadoop hello joe] output -> K[hive],V[2147483647 hadoop hello joe] input -> K[joe],V[2147483647 null hive hello] output -> K[joe],V[2147483647 hive hello] 2016-12-12 16:37:07,851 INFO [org.apache.hadoop.mapred.LocalJobRunner] - 2016-12-12 16:37:07,851 INFO [org.apache.hadoop.mapred.MapTask] - Starting flush of map output 2016-12-12 16:37:07,851 INFO [org.apache.hadoop.mapred.MapTask] - Spilling map output 2016-12-12 16:37:07,851 INFO [org.apache.hadoop.mapred.MapTask] - bufstart = 0; bufend = 174; bufvoid = 104857600 2016-12-12 16:37:07,852 INFO [org.apache.hadoop.mapred.MapTask] - kvstart = 26214396(104857584); kvend = 26214372(104857488); length = 25/6553600 2016-12-12 16:37:07,871 INFO [org.apache.hadoop.mapred.MapTask] - Finished spill 0 2016-12-12 16:37:07,877 INFO [org.apache.hadoop.mapred.Task] - Task:attempt_local535100118_0001_m_000000_0 is done. And is in the process of committing 2016-12-12 16:37:07,891 INFO [org.apache.hadoop.mapred.LocalJobRunner] - file:/D:/Code/MyEclipseJavaCode/myMapReduce/out/shortestpath/input.txt:0+149 2016-12-12 16:37:07,892 INFO [org.apache.hadoop.mapred.Task] - Task 'attempt_local535100118_0001_m_000000_0' done. 2016-12-12 16:37:07,892 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Finishing task: attempt_local535100118_0001_m_000000_0 2016-12-12 16:37:07,892 INFO [org.apache.hadoop.mapred.LocalJobRunner] - map task executor complete. 2016-12-12 16:37:07,896 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Waiting for reduce tasks 2016-12-12 16:37:07,896 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Starting task: attempt_local535100118_0001_r_000000_0 2016-12-12 16:37:07,910 INFO [org.apache.hadoop.yarn.util.ProcfsBasedProcessTree] - ProcfsBasedProcessTree currently is supported only on Linux. 2016-12-12 16:37:07,942 INFO [org.apache.hadoop.mapred.Task] - Using ResourceCalculatorProcessTree : org.apache.hadoop.yarn.util.WindowsBasedProcessTree@5bf7b707 2016-12-12 16:37:07,948 INFO [org.apache.hadoop.mapred.ReduceTask] - Using ShuffleConsumerPlugin: org.apache.hadoop.mapreduce.task.reduce.Shuffle@969f4cd 2016-12-12 16:37:07,972 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - MergerManager: memoryLimit=1327077760, maxSingleShuffleLimit=331769440, mergeThreshold=875871360, ioSortFactor=10, memToMemMergeOutputsThreshold=10 2016-12-12 16:37:07,975 INFO [org.apache.hadoop.mapreduce.task.reduce.EventFetcher] - attempt_local535100118_0001_r_000000_0 Thread started: EventFetcher for fetching Map Completion Events 2016-12-12 16:37:08,017 INFO [org.apache.hadoop.mapreduce.task.reduce.LocalFetcher] - localfetcher#1 about to shuffle output of map attempt_local535100118_0001_m_000000_0 decomp: 190 len: 194 to MEMORY 2016-12-12 16:37:08,023 INFO [org.apache.hadoop.mapreduce.task.reduce.InMemoryMapOutput] - Read 190 bytes from map-output for attempt_local535100118_0001_m_000000_0 2016-12-12 16:37:08,076 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - closeInMemoryFile -> map-output of size: 190, inMemoryMapOutputs.size() -> 1, commitMemory -> 0, usedMemory ->190 2016-12-12 16:37:08,078 INFO [org.apache.hadoop.mapreduce.task.reduce.EventFetcher] - EventFetcher is interrupted.. Returning 2016-12-12 16:37:08,080 INFO [org.apache.hadoop.mapred.LocalJobRunner] - 1 / 1 copied. 2016-12-12 16:37:08,081 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - finalMerge called with 1 in-memory map-outputs and 0 on-disk map-outputs 2016-12-12 16:37:08,110 INFO [org.apache.hadoop.mapred.Merger] - Merging 1 sorted segments 2016-12-12 16:37:08,111 INFO [org.apache.hadoop.mapred.Merger] - Down to the last merge-pass, with 1 segments left of total size: 184 bytes 2016-12-12 16:37:08,113 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - Merged 1 segments, 190 bytes to disk to satisfy reduce memory limit 2016-12-12 16:37:08,114 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - Merging 1 files, 194 bytes from disk 2016-12-12 16:37:08,115 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - Merging 0 segments, 0 bytes from memory into reduce 2016-12-12 16:37:08,116 INFO [org.apache.hadoop.mapred.Merger] - Merging 1 sorted segments 2016-12-12 16:37:08,117 INFO [org.apache.hadoop.mapred.Merger] - Down to the last merge-pass, with 1 segments left of total size: 184 bytes 2016-12-12 16:37:08,118 INFO [org.apache.hadoop.mapred.LocalJobRunner] - 1 / 1 copied. 2016-12-12 16:37:08,141 INFO [org.apache.hadoop.conf.Configuration.deprecation] - mapred.skip.on is deprecated. Instead, use mapreduce.job.skiprecords input -> K[dee] input -> V[0 hadoop hello] output -> K[dee],V[0 null hadoop hello] input -> K[hadoop] input -> V[2147483647 hive hello] input -> V[1 dee] output -> K[hadoop],V[1 dee hive hello] input -> K[hello] input -> V[2147483647 dee hadoop hive joe] input -> V[1 dee] output -> K[hello],V[1 dee dee hadoop hive joe] input -> K[hive] input -> V[2147483647 hadoop hello joe] output -> K[hive],V[2147483647 null hadoop hello joe] input -> K[joe] input -> V[2147483647 hive hello] output -> K[joe],V[2147483647 null hive hello] 2016-12-12 16:37:08,154 INFO [org.apache.hadoop.mapred.Task] - Task:attempt_local535100118_0001_r_000000_0 is done. And is in the process of committing 2016-12-12 16:37:08,156 INFO [org.apache.hadoop.mapred.LocalJobRunner] - 1 / 1 copied. 2016-12-12 16:37:08,156 INFO [org.apache.hadoop.mapred.Task] - Task attempt_local535100118_0001_r_000000_0 is allowed to commit now 2016-12-12 16:37:08,162 INFO [org.apache.hadoop.mapreduce.lib.output.FileOutputCommitter] - Saved output of task 'attempt_local535100118_0001_r_000000_0' to file:/D:/Code/MyEclipseJavaCode/myMapReduce/out/shortestpath/1/_temporary/0/task_local535100118_0001_r_000000 2016-12-12 16:37:08,163 INFO [org.apache.hadoop.mapred.LocalJobRunner] - reduce > reduce 2016-12-12 16:37:08,164 INFO [org.apache.hadoop.mapred.Task] - Task 'attempt_local535100118_0001_r_000000_0' done. 2016-12-12 16:37:08,164 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Finishing task: attempt_local535100118_0001_r_000000_0 2016-12-12 16:37:08,164 INFO [org.apache.hadoop.mapred.LocalJobRunner] - reduce task executor complete. 2016-12-12 16:37:08,535 INFO [org.apache.hadoop.mapreduce.Job] - Job job_local535100118_0001 running in uber mode : false 2016-12-12 16:37:08,539 INFO [org.apache.hadoop.mapreduce.Job] - map 100% reduce 100% 2016-12-12 16:37:08,544 INFO [org.apache.hadoop.mapreduce.Job] - Job job_local535100118_0001 completed successfully 2016-12-12 16:37:08,601 INFO [org.apache.hadoop.mapreduce.Job] - Counters: 33 File System Counters FILE: Number of bytes read=1340 FILE: Number of bytes written=387869 FILE: Number of read operations=0 FILE: Number of large read operations=0 FILE: Number of write operations=0 Map-Reduce Framework Map input records=5 Map output records=7 Map output bytes=174 Map output materialized bytes=194 Input split bytes=135 Combine input records=0 Combine output records=0 Reduce input groups=5 Reduce shuffle bytes=194 Reduce input records=7 Reduce output records=5 Spilled Records=14 Shuffled Maps =1 Failed Shuffles=0 Merged Map outputs=1 GC time elapsed (ms)=0 CPU time spent (ms)=0 Physical memory (bytes) snapshot=0 Virtual memory (bytes) snapshot=0 Total committed heap usage (bytes)=466616320 Shuffle Errors BAD_ID=0 CONNECTION=0 IO_ERROR=0 WRONG_LENGTH=0 WRONG_MAP=0 WRONG_REDUCE=0 File Input Format Counters Bytes Read=169 File Output Format Counters Bytes Written=161 ====================================== = Iteration: 2 = Input path: out/shortestpath/1 = Output path: out/shortestpath/2 ====================================== 2016-12-12 16:37:08,638 INFO [org.apache.hadoop.metrics.jvm.JvmMetrics] - Cannot initialize JVM Metrics with processName=JobTracker, sessionId= - already initialized 2016-12-12 16:37:08,649 WARN [org.apache.hadoop.mapreduce.JobSubmitter] - Hadoop command-line option parsing not performed. Implement the Tool interface and execute your application with ToolRunner to remedy this. 2016-12-12 16:37:08,653 WARN [org.apache.hadoop.mapreduce.JobSubmitter] - No job jar file set. User classes may not be found. See Job or Job#setJar(String). 2016-12-12 16:37:09,079 INFO [org.apache.hadoop.mapreduce.lib.input.FileInputFormat] - Total input paths to process : 1 2016-12-12 16:37:09,098 INFO [org.apache.hadoop.mapreduce.JobSubmitter] - number of splits:1 2016-12-12 16:37:09,183 INFO [org.apache.hadoop.mapreduce.JobSubmitter] - Submitting tokens for job: job_local447108750_0002 2016-12-12 16:37:09,525 INFO [org.apache.hadoop.mapreduce.Job] - The url to track the job: http://localhost:8080/ 2016-12-12 16:37:09,525 INFO [org.apache.hadoop.mapreduce.Job] - Running job: job_local447108750_0002 2016-12-12 16:37:09,527 INFO [org.apache.hadoop.mapred.LocalJobRunner] - OutputCommitter set in config null 2016-12-12 16:37:09,529 INFO [org.apache.hadoop.mapred.LocalJobRunner] - OutputCommitter is org.apache.hadoop.mapreduce.lib.output.FileOutputCommitter 2016-12-12 16:37:09,540 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Waiting for map tasks 2016-12-12 16:37:09,540 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Starting task: attempt_local447108750_0002_m_000000_0 2016-12-12 16:37:09,544 INFO [org.apache.hadoop.yarn.util.ProcfsBasedProcessTree] - ProcfsBasedProcessTree currently is supported only on Linux. 2016-12-12 16:37:09,591 INFO [org.apache.hadoop.mapred.Task] - Using ResourceCalculatorProcessTree : org.apache.hadoop.yarn.util.WindowsBasedProcessTree@25a02403 2016-12-12 16:37:09,597 INFO [org.apache.hadoop.mapred.MapTask] - Processing split: file:/D:/Code/MyEclipseJavaCode/myMapReduce/out/shortestpath/1/part-r-00000:0+149 2016-12-12 16:37:09,662 INFO [org.apache.hadoop.mapred.MapTask] - (EQUATOR) 0 kvi 26214396(104857584) 2016-12-12 16:37:09,663 INFO [org.apache.hadoop.mapred.MapTask] - mapreduce.task.io.sort.mb: 100 2016-12-12 16:37:09,663 INFO [org.apache.hadoop.mapred.MapTask] - soft limit at 83886080 2016-12-12 16:37:09,663 INFO [org.apache.hadoop.mapred.MapTask] - bufstart = 0; bufvoid = 104857600 2016-12-12 16:37:09,663 INFO [org.apache.hadoop.mapred.MapTask] - kvstart = 26214396; length = 6553600 2016-12-12 16:37:09,666 INFO [org.apache.hadoop.mapred.MapTask] - Map output collector class = org.apache.hadoop.mapred.MapTask$MapOutputBuffer input -> K[dee],V[0 null hadoop hello] output -> K[dee],V[0 null hadoop hello] output -> K[hadoop],V[1 null:dee] output -> K[hello],V[1 null:dee] input -> K[hadoop],V[1 dee hive hello] output -> K[hadoop],V[1 dee hive hello] output -> K[hive],V[2 dee:hadoop] output -> K[hello],V[2 dee:hadoop] input -> K[hello],V[1 dee dee hadoop hive joe] output -> K[hello],V[1 dee dee hadoop hive joe] output -> K[dee],V[2 dee:hello] output -> K[hadoop],V[2 dee:hello] output -> K[hive],V[2 dee:hello] output -> K[joe],V[2 dee:hello] input -> K[hive],V[2147483647 null hadoop hello joe] output -> K[hive],V[2147483647 null hadoop hello joe] input -> K[joe],V[2147483647 null hive hello] output -> K[joe],V[2147483647 null hive hello] 2016-12-12 16:37:09,675 INFO [org.apache.hadoop.mapred.LocalJobRunner] - 2016-12-12 16:37:09,675 INFO [org.apache.hadoop.mapred.MapTask] - Starting flush of map output 2016-12-12 16:37:09,675 INFO [org.apache.hadoop.mapred.MapTask] - Spilling map output 2016-12-12 16:37:09,675 INFO [org.apache.hadoop.mapred.MapTask] - bufstart = 0; bufend = 289; bufvoid = 104857600 2016-12-12 16:37:09,676 INFO [org.apache.hadoop.mapred.MapTask] - kvstart = 26214396(104857584); kvend = 26214348(104857392); length = 49/6553600 2016-12-12 16:37:09,691 INFO [org.apache.hadoop.mapred.MapTask] - Finished spill 0 2016-12-12 16:37:09,699 INFO [org.apache.hadoop.mapred.Task] - Task:attempt_local447108750_0002_m_000000_0 is done. And is in the process of committing 2016-12-12 16:37:09,704 INFO [org.apache.hadoop.mapred.LocalJobRunner] - file:/D:/Code/MyEclipseJavaCode/myMapReduce/out/shortestpath/1/part-r-00000:0+149 2016-12-12 16:37:09,705 INFO [org.apache.hadoop.mapred.Task] - Task 'attempt_local447108750_0002_m_000000_0' done. 2016-12-12 16:37:09,705 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Finishing task: attempt_local447108750_0002_m_000000_0 2016-12-12 16:37:09,705 INFO [org.apache.hadoop.mapred.LocalJobRunner] - map task executor complete. 2016-12-12 16:37:09,707 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Waiting for reduce tasks 2016-12-12 16:37:09,708 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Starting task: attempt_local447108750_0002_r_000000_0 2016-12-12 16:37:09,714 INFO [org.apache.hadoop.yarn.util.ProcfsBasedProcessTree] - ProcfsBasedProcessTree currently is supported only on Linux. 2016-12-12 16:37:09,856 INFO [org.apache.hadoop.mapred.Task] - Using ResourceCalculatorProcessTree : org.apache.hadoop.yarn.util.WindowsBasedProcessTree@3f539d4b 2016-12-12 16:37:09,857 INFO [org.apache.hadoop.mapred.ReduceTask] - Using ShuffleConsumerPlugin: org.apache.hadoop.mapreduce.task.reduce.Shuffle@a7bc768 2016-12-12 16:37:09,862 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - MergerManager: memoryLimit=1327077760, maxSingleShuffleLimit=331769440, mergeThreshold=875871360, ioSortFactor=10, memToMemMergeOutputsThreshold=10 2016-12-12 16:37:09,865 INFO [org.apache.hadoop.mapreduce.task.reduce.EventFetcher] - attempt_local447108750_0002_r_000000_0 Thread started: EventFetcher for fetching Map Completion Events 2016-12-12 16:37:09,871 INFO [org.apache.hadoop.mapreduce.task.reduce.LocalFetcher] - localfetcher#2 about to shuffle output of map attempt_local447108750_0002_m_000000_0 decomp: 317 len: 321 to MEMORY 2016-12-12 16:37:09,874 INFO [org.apache.hadoop.mapreduce.task.reduce.InMemoryMapOutput] - Read 317 bytes from map-output for attempt_local447108750_0002_m_000000_0 2016-12-12 16:37:09,876 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - closeInMemoryFile -> map-output of size: 317, inMemoryMapOutputs.size() -> 1, commitMemory -> 0, usedMemory ->317 2016-12-12 16:37:09,877 INFO [org.apache.hadoop.mapreduce.task.reduce.EventFetcher] - EventFetcher is interrupted.. Returning 2016-12-12 16:37:09,879 INFO [org.apache.hadoop.mapred.LocalJobRunner] - 1 / 1 copied. 2016-12-12 16:37:09,879 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - finalMerge called with 1 in-memory map-outputs and 0 on-disk map-outputs 2016-12-12 16:37:09,892 INFO [org.apache.hadoop.mapred.Merger] - Merging 1 sorted segments 2016-12-12 16:37:09,893 INFO [org.apache.hadoop.mapred.Merger] - Down to the last merge-pass, with 1 segments left of total size: 311 bytes 2016-12-12 16:37:09,896 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - Merged 1 segments, 317 bytes to disk to satisfy reduce memory limit 2016-12-12 16:37:09,898 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - Merging 1 files, 321 bytes from disk 2016-12-12 16:37:09,898 INFO [org.apache.hadoop.mapreduce.task.reduce.MergeManagerImpl] - Merging 0 segments, 0 bytes from memory into reduce 2016-12-12 16:37:09,898 INFO [org.apache.hadoop.mapred.Merger] - Merging 1 sorted segments 2016-12-12 16:37:09,901 INFO [org.apache.hadoop.mapred.Merger] - Down to the last merge-pass, with 1 segments left of total size: 311 bytes 2016-12-12 16:37:09,902 INFO [org.apache.hadoop.mapred.LocalJobRunner] - 1 / 1 copied. input -> K[dee] input -> V[2 dee:hello] input -> V[0 null hadoop hello] output -> K[dee],V[0 null hadoop hello] input -> K[hadoop] input -> V[1 null:dee] input -> V[1 dee hive hello] input -> V[2 dee:hello] output -> K[hadoop],V[1 null:dee hive hello] input -> K[hello] input -> V[1 dee dee hadoop hive joe] input -> V[2 dee:hadoop] input -> V[1 null:dee] output -> K[hello],V[1 dee dee hadoop hive joe] input -> K[hive] input -> V[2 dee:hadoop] input -> V[2 dee:hello] input -> V[2147483647 null hadoop hello joe] output -> K[hive],V[2 dee:hadoop hadoop hello joe] input -> K[joe] input -> V[2 dee:hello] input -> V[2147483647 null hive hello] output -> K[joe],V[2 dee:hello hive hello] 2016-12-12 16:37:09,929 INFO [org.apache.hadoop.mapred.Task] - Task:attempt_local447108750_0002_r_000000_0 is done. And is in the process of committing 2016-12-12 16:37:09,934 INFO [org.apache.hadoop.mapred.LocalJobRunner] - 1 / 1 copied. 2016-12-12 16:37:09,934 INFO [org.apache.hadoop.mapred.Task] - Task attempt_local447108750_0002_r_000000_0 is allowed to commit now 2016-12-12 16:37:09,944 INFO [org.apache.hadoop.mapreduce.lib.output.FileOutputCommitter] - Saved output of task 'attempt_local447108750_0002_r_000000_0' to file:/D:/Code/MyEclipseJavaCode/myMapReduce/out/shortestpath/2/_temporary/0/task_local447108750_0002_r_000000 2016-12-12 16:37:09,947 INFO [org.apache.hadoop.mapred.LocalJobRunner] - reduce > reduce 2016-12-12 16:37:09,948 INFO [org.apache.hadoop.mapred.Task] - Task 'attempt_local447108750_0002_r_000000_0' done. 2016-12-12 16:37:09,948 INFO [org.apache.hadoop.mapred.LocalJobRunner] - Finishing task: attempt_local447108750_0002_r_000000_0 2016-12-12 16:37:09,948 INFO [org.apache.hadoop.mapred.LocalJobRunner] - reduce task executor complete. 2016-12-12 16:37:10,526 INFO [org.apache.hadoop.mapreduce.Job] - Job job_local447108750_0002 running in uber mode : false 2016-12-12 16:37:10,526 INFO [org.apache.hadoop.mapreduce.Job] - map 100% reduce 100% 2016-12-12 16:37:10,527 INFO [org.apache.hadoop.mapreduce.Job] - Job job_local447108750_0002 completed successfully 2016-12-12 16:37:10,542 INFO [org.apache.hadoop.mapreduce.Job] - Counters: 35 File System Counters FILE: Number of bytes read=3162 FILE: Number of bytes written=776144 FILE: Number of read operations=0 FILE: Number of large read operations=0 FILE: Number of write operations=0 Map-Reduce Framework Map input records=5 Map output records=13 Map output bytes=289 Map output materialized bytes=321 Input split bytes=140 Combine input records=0 Combine output records=0 Reduce input groups=5 Reduce shuffle bytes=321 Reduce input records=13 Reduce output records=5 Spilled Records=26 Shuffled Maps =1 Failed Shuffles=0 Merged Map outputs=1 GC time elapsed (ms)=0 CPU time spent (ms)=0 Physical memory (bytes) snapshot=0 Virtual memory (bytes) snapshot=0 Total committed heap usage (bytes)=677380096 PATH dee:hello=1 Shuffle Errors BAD_ID=0 CONNECTION=0 IO_ERROR=0 WRONG_LENGTH=0 WRONG_MAP=0 WRONG_REDUCE=0 File Input Format Counters Bytes Read=169 File Output Format Counters Bytes Written=159 zhouls.bigdata.myMapReduce.shortestpath.Reduce$PathCounter TARGET_NODE_DISTANCE_COMPUTED=2 ========================================== = Shortest path found, details as follows. = = Start node: dee = End node: joe = Hops: 2 = Path: dee:hello ========================================== 代码 package zhouls.bigdata.myMapReduce.shortestpath; import org.apache.hadoop.io.Text; import org.apache.hadoop.mapreduce.Mapper; import java.io.IOException; public class Map extends Mapper<Text, Text, Text, Text> { private Text outKey = new Text(); private Text outValue = new Text(); @Override protected void map(Text key, Text value, Context context) throws IOException, InterruptedException { Node node = Node.fromMR(value.toString()); System.out.println("input -> K[" + key + "],V[" + node + "]"); // output this node's key/value pair again to preserve the information // System.out.println( " output -> K[" + key + "],V[" + value + "]"); context.write(key, value); // only output the neighbor details if we have an actual distance // from the source node // if (node.isDistanceSet()) { // our neighbors are just a hop away // // create the backpointer, which will append our own // node name to the list // String backpointer = node.constructBackpointer(key.toString()); // go through all the nodes and propagate the distance to them // for (int i = 0; i < node.getAdjacentNodeNames().length; i++) { String neighbor = node.getAdjacentNodeNames()[i]; int neighborDistance = node.getDistance() + 1; // output the neighbor with the propagated distance and backpointer // outKey.set(neighbor); Node adjacentNode = new Node() .setDistance(neighborDistance) .setBackpointer(backpointer); outValue.set(adjacentNode.toString()); System.out.println( " output -> K[" + outKey + "],V[" + outValue + "]"); context.write(outKey, outValue); } } } } package zhouls.bigdata.myMapReduce.shortestpath; import org.apache.hadoop.io.Text; import org.apache.hadoop.mapreduce.*; import java.io.IOException; public class Reduce extends Reducer<Text, Text, Text, Text> { public static enum PathCounter { TARGET_NODE_DISTANCE_COMPUTED, PATH } private Text outValue = new Text(); private String targetNode; protected void setup(Context context ) throws IOException, InterruptedException { targetNode = context.getConfiguration().get( Main.TARGET_NODE); } public void reduce(Text key, Iterable<Text> values, Context context) throws IOException, InterruptedException { int minDistance = Node.INFINITE; System.out.println("input -> K[" + key + "]"); Node shortestAdjacentNode = null; Node originalNode = null; for (Text textValue : values) { System.out.println(" input -> V[" + textValue + "]"); Node node = Node.fromMR(textValue.toString()); if(node.containsAdjacentNodes()) { // the original data // originalNode = node; } if(node.getDistance() < minDistance) { minDistance = node.getDistance(); shortestAdjacentNode = node; } } if(shortestAdjacentNode != null) { originalNode.setDistance(minDistance); originalNode.setBackpointer(shortestAdjacentNode.getBackpointer()); } outValue.set(originalNode.toString()); System.out.println( " output -> K[" + key + "],V[" + outValue + "]"); context.write(key, outValue); if (minDistance != Node.INFINITE && targetNode.equals(key.toString())) { Counter counter = context.getCounter( PathCounter.TARGET_NODE_DISTANCE_COMPUTED); counter.increment(minDistance); context.getCounter(PathCounter.PATH.toString(), shortestAdjacentNode.getBackpointer()).increment(1); } } } package zhouls.bigdata.myMapReduce.shortestpath; import org.apache.commons.lang.StringUtils; import java.io.IOException; import java.util.Arrays; public class Node { private int distance = INFINITE; private String backpointer; private String[] adjacentNodeNames; public static int INFINITE = Integer.MAX_VALUE; public static final char fieldSeparator = '\t'; public int getDistance() { return distance; } public Node setDistance(int distance) { this.distance = distance; return this; } public String getBackpointer() { return backpointer; } public Node setBackpointer(String backpointer) { this.backpointer = backpointer; return this; } public String constructBackpointer(String name) { StringBuilder backpointers = new StringBuilder(); if (StringUtils.trimToNull(getBackpointer()) != null) { backpointers.append(getBackpointer()).append(":"); } backpointers.append(name); return backpointers.toString(); } public String[] getAdjacentNodeNames() { return adjacentNodeNames; } public Node setAdjacentNodeNames(String[] adjacentNodeNames) { this.adjacentNodeNames = adjacentNodeNames; return this; } public boolean containsAdjacentNodes() { return adjacentNodeNames != null; } public boolean isDistanceSet() { return distance != INFINITE; } @Override public String toString() { StringBuilder sb = new StringBuilder(); sb.append(distance) .append(fieldSeparator) .append(backpointer); if (getAdjacentNodeNames() != null) { sb.append(fieldSeparator) .append(StringUtils .join(getAdjacentNodeNames(), fieldSeparator)); } return sb.toString(); } public static Node fromMR(String value) throws IOException { String[] parts = StringUtils.splitPreserveAllTokens( value, fieldSeparator); if (parts.length < 2) { throw new IOException( "Expected 2 or more parts but received " + parts.length); } Node node = new Node() .setDistance(Integer.valueOf(parts[0])) .setBackpointer(StringUtils.trimToNull(parts[1])); if (parts.length > 2) { node.setAdjacentNodeNames(Arrays.copyOfRange(parts, 2, parts.length)); } return node; } } package zhouls.bigdata.myMapReduce.shortestpath; import org.apache.commons.io.*; import org.apache.commons.lang.*; import org.apache.hadoop.conf.Configuration; import org.apache.hadoop.fs.FileSystem; import org.apache.hadoop.fs.*; import org.apache.hadoop.io.Text; import org.apache.hadoop.mapreduce.*; import org.apache.hadoop.mapreduce.lib.input.*; import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat; import java.io.*; import java.util.Iterator; public final class Main { public static final String TARGET_NODE = "shortestpath.targetnode"; public static void main(String... args) throws Exception { String startNode = "dee"; String targetNode = "joe"; // String inputFile = "hdfs://HadoopMaster:9000/shortestpath/shortestpath.txt"; // String outputDir = "hdfs://HadoopMaster:9000/out/shortestpath"; String inputFile = "./data/shortestpath/shortestpath.txt"; String outputDir = "./out/shortestpath"; iterate(startNode, targetNode, inputFile, outputDir); } public static Configuration conf = new Configuration(); static{ // conf.set("fs.defaultFS", "hdfs://HadoopMaster:9000"); // conf.set("yarn.resourcemanager.hostname", "HadoopMaster"); } public static void iterate(String startNode, String targetNode, String input, String output) throws Exception { Path outputPath = new Path(output); outputPath.getFileSystem(conf).delete(outputPath, true); outputPath.getFileSystem(conf).mkdirs(outputPath); Path inputPath = new Path(outputPath, "input.txt"); createInputFile(new Path(input), inputPath, startNode); int iter = 1; while (true) { Path jobOutputPath = new Path(outputPath, String.valueOf(iter)); System.out.println("======================================"); System.out.println("= Iteration: " + iter); System.out.println("= Input path: " + inputPath); System.out.println("= Output path: " + jobOutputPath); System.out.println("======================================"); if(findShortestPath(inputPath, jobOutputPath, startNode, targetNode)) { break; } inputPath = jobOutputPath; iter++; } } public static void createInputFile(Path file, Path targetFile, String startNode) throws IOException { FileSystem fs = file.getFileSystem(conf); OutputStream os = fs.create(targetFile); LineIterator iter = org.apache.commons.io.IOUtils .lineIterator(fs.open(file), "UTF8"); while (iter.hasNext()) { String line = iter.nextLine(); String[] parts = StringUtils.split(line); int distance = Node.INFINITE; if (startNode.equals(parts[0])) { distance = 0; } IOUtils.write(parts[0] + '\t' + String.valueOf(distance) + "\t\t", os); IOUtils.write(StringUtils.join(parts, '\t', 1, parts.length), os); IOUtils.write("\n", os); } os.close(); } public static boolean findShortestPath(Path inputPath, Path outputPath, String startNode, String targetNode) throws Exception { conf.set(TARGET_NODE, targetNode); Job job = new Job(conf); job.setJarByClass(Main.class); job.setMapperClass(Map.class); job.setReducerClass(Reduce.class); job.setInputFormatClass(KeyValueTextInputFormat.class); job.setMapOutputKeyClass(Text.class); job.setMapOutputValueClass(Text.class); FileInputFormat.setInputPaths(job, inputPath); FileOutputFormat.setOutputPath(job, outputPath); if (!job.waitForCompletion(true)) { throw new Exception("Job failed"); } Counter counter = job.getCounters() .findCounter(Reduce.PathCounter.TARGET_NODE_DISTANCE_COMPUTED); if(counter != null && counter.getValue() > 0) { CounterGroup group = job.getCounters().getGroup(Reduce.PathCounter.PATH.toString()); Iterator<Counter> iter = group.iterator(); iter.hasNext(); String path = iter.next().getName(); System.out.println("=========================================="); System.out.println("= Shortest path found, details as follows."); System.out.println("= "); System.out.println("= Start node: " + startNode); System.out.println("= End node: " + targetNode); System.out.println("= Hops: " + counter.getValue()); System.out.println("= Path: " + path); System.out.println("=========================================="); return true; } return false; } // public static String getNeighbor(String str){ // return str.split(",")[0]; // } // public static int getNeighborDis(String str){ // return Integer.parseInt(str.split(",")[1]); // } } 本文转自大数据躺过的坑博客园博客,原文链接:http://www.cnblogs.com/zlslch/p/6165087.html,如需转载请自行联系原作者
)
)